tikv/pd needs an edition variable before it will build, and CI builds report version None
Placement driver for TiKV. Single node with default ports You can run pd-server directly on your local machine.
At a glance
- What is it?
- The placement driver that schedules TiKV, with an embedded etcd and three binaries from a single make. The README is short and the build system is where the information is: a required edition variable, a set of tags that silently change what you compile, a container that fetches a JSON processor from a fixed URL, and dependencies pinned to commits that have never been released.
- Who is it for?
- pd is a good choice if you are running TiKV, because it is the component that decides where regions live, and a poor choice if you are evaluating it as a standalone database, because a single placement driver stores nothing and serves no queries. Three things to check first.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 1 day ago.
- What is it written in?
- Mainly Go, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
Star history
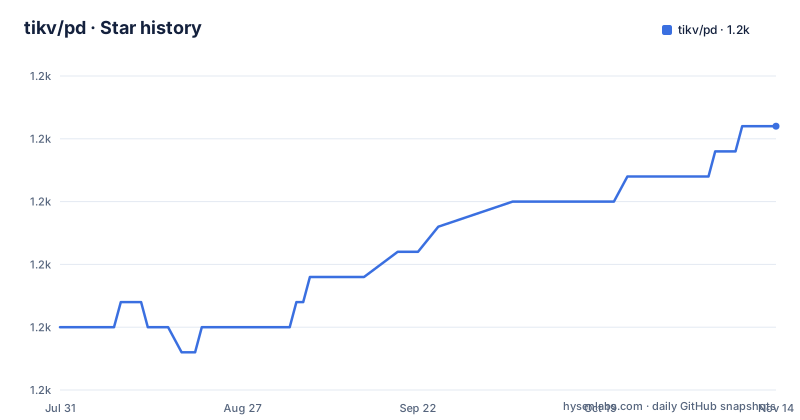
- tikv/pd1,163 ★ · +8
| Repository | 2026-07-31 | 2026-11-14 |
|---|---|---|
| tikv/pd | 1.2k | 1.2k |
8 Stars in the last 106 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
A placement driver on its own is not a database
PD is short for placement driver, and its job is stated in one line: it manages and schedules TiKV clusters. Fault tolerance comes from embedding etcd.
That framing matters for anyone arriving from the database world, because the README is explicit about the dependency direction. PD is a component of the TiKV project and needs to run with TiKV to work. A cluster can additionally include TiDB to provide SQL services. So the deployment examples in the file are a development convenience, not a production topology: the single node section says you can run the server directly on your local machine, and the cluster section sends you to the TiUP deployment guide or the Kubernetes documentation for anything real.
The single node path is genuinely simple, and the flags are the interesting part. The name identifies the member, the data directory holds state, the client URL is where callers reach it, the peer URL is where other placement drivers talk to each other, and the log file is where it writes. Those last two are the ones to understand: client traffic and peer traffic are separate listeners on separate ports, and the rest of the system is configured by which address you put in each.
The file also notes that if you want to connect from outside, you can let the driver listen on the host IP rather than only on loopback. That single sentence is the difference between a development default and an exposed service.
The local run binds the host IP, the container binds everything and advertises the host IP
The two invocations in the file look similar and behave differently in one way that matters.
Running directly on the machine, the client and peer URLs are both set to the host address you exported, and there are no advertise flags at all. The process binds and advertises the same address, because there is nothing between it and the network it is on.
Running in the container, the bind address becomes all interfaces on both ports, and two new flags appear: an advertise client URL and an advertise peer URL, both set to the host address. The container listens on everything inside its network namespace while telling the rest of the world to reach it at the host address, and the port mappings publish both ports.
# Set HOST_IP to the address you want to listen on
export HOST_IP="192.168.199.105"

pd-server --name="pd" \
          --data-dir="pd" \
          --client-urls="http://${HOST_IP}:2379" \
          --peer-urls="http://${HOST_IP}:2380" \
--log-file=pd.log# Set HOST_IP to the address you want to listen on
export HOST_IP="192.168.199.105"
docker run -d -p 2379:2379 -p 2380:2380 --name pd pingcap/pd \
--name="pd" \
--data-dir="pd" \
--client-urls="http://0.0.0.0:2379" \
--advertise-client-urls="http://${HOST_IP}:2379" \
--peer-urls="http://0.0.0.0:2380" \
--advertise-peer-urls="http://${HOST_IP}:2380" \
--log-file=pd.logThe two ports are the same in both cases: one for clients, one for peers, and they are the pair the image exposes.
The members API answers with a wildcard CORS origin
The file shows the members endpoint being called two ways, and the second one prints the response headers before the body.
Those headers are the finding. The response carries an allowed origin of any site, an allowed headers list that includes the authorization header, and an allowed methods list covering post, get, options, put and delete.
Put that next to the two things the file already tells you to do. It says you can let the driver listen on the host IP if you want to connect from outside, and the container example publishes the client port on all interfaces. So in that configuration, any web page a browser on that network visits can send cross-origin requests to the placement driver and read the response, and the response says the authorization header is allowed through.
The members endpoint itself is a read that returns the cluster identifier, the member name, its identifier, peer and client URLs, deploy path, binary version and git hash. Nothing in that is a secret, which is the fair caveat. But the same origin policy covers every path on that port, and the placement API is not only a read: it schedules, and scheduling is a write.
The go module file shows where that comes from. A cross-origin middleware for the web framework and a gzip handler and a profiling handler sit in the dependency list, so permissive CORS is a deliberate framework choice rather than an accident of the example.
If you need this reachable from a browser, put something in front of it that sets its own policy.
Both sample responses stop mid-JSON, and the identifiers are not real ones
Both example outputs are cut off, and neither cut is where a reader would stop reading.
The plain client example ends after the first member's peer URL, with the array left open. The alternative client prints the headers, then the same cluster identifier and the same member, and stops in the middle of a key name partway through the deploy path field. The trailing blank line in both cases is where the rest of the object should be.
So the shape of the response has to be inferred rather than read. From what is there, a members response carries a header object with a cluster identifier, a members array whose entries have a name, a member identifier, peer URLs, client URLs, deploy path, binary version and git hash, and a leader object repeating the same fields for the current leader.
The sample values are worth reading as illustrative rather than captured. The member identifier is a twenty digit number that sits beyond the range of a signed sixty four bit integer, which no real member identifier would. The git hash is a well formed forty character hash. The binary version shown is a point release older than any of the current release tags.
None of that makes the documentation wrong about the interface. It does mean the sample was edited by hand, so treat the field list as accurate and the values as placeholders.
The build refuses to start without an edition, and turns the version into None under CI
The build instructions in the file are two steps: install Go 1.26 or later, then run make, which produces three binaries in a bin directory. The server, the control tool, and a recovery tool.
The make file is where the detail lives, and it starts with a guard. The default target is the build, but before anything runs there is a check that an edition variable is set to either the community value or the enterprise value, and if it is anything else the build stops with a message telling you to set it. The default is the community edition. So the one thing the two step instruction does not mention is the one thing the build insists on.
Past the guard, a set of variables each add a build tag, and three of them also turn CGO on. A flag that disables the dashboard adds a tag to build without it and leaves CGO off; a race detector flag adds the race flag and turns CGO on; a next generation flag adds a tag, also builds without the dashboard, and changes the tag used for tests; a failpoint flag, a plugin flag, a FIPS flag that also selects a boring crypto experiment, and a swagger flag each add their own tag. None of them print what they changed.
The version handling is the sharpest line. The release version comes from asking git to describe the checked out tree with tags, including whether it is dirty. And when a CI environment variable is set, that value is replaced with the literal string None.
So a build produced by continuous integration reports itself as version None, and the build timestamp, git hash, branch and edition are all injected into the binary at link time. If you are reading a version string from a running node, that is where the gap comes from.
The image fetches a JSON processor from a fixed URL and runs on an older Alpine than it builds on
The container build is in two stages. The builder is a Go image on Alpine with a native toolchain added: make, git, bash, curl, a C and C++ compiler, and the gold linker. The dependency manifests are copied before the source, so a source change does not re-download modules.
Then two details worth reading.
The control tool needs a JSON processor, and instead of using a package manager the build downloads a prebuilt binary from a fixed release URL and marks it executable. That is a network fetch of an executable during a build, pinned to one version, with no checksum step alongside it.
The build also carries a comment naming a specific incompatibility between a SQLite library and a recent Alpine, with a link to the upstream issue, and works around it by setting a large file compiler flag for the whole make. Whether that flag is still needed depends on which Alpine the builder is on, and the workaround is applied unconditionally rather than conditionally.
The runtime stage is a different, older Alpine than the builder. It copies in the three binaries and the JSON processor, adds curl, exposes the two ports and sets the server as the entry point.
The build skew between the two stages is the thing to note: the code is compiled on a recent userland and shipped on an older one. That is a deliberate way to reduce the surface of the shipped image, and it is also the kind of choice where a native library compiled against one C library and run against another is where surprises live.
Several dependencies are commits that were never released
The module file is worth a look even if you never build the project, because it describes what a reproducible build actually needs.
The declared language version is 1.26.8, a patch-level floor, while the installation instruction says Go 1.26 or later. The container builds on a matching 1.26 tag. So the toolchain requirement is stated three times in three slightly different ways, and only the module file pins a patch.
Then the dependency list. Several entries are pseudo versions, which is what the tooling records when a commit was taken without a tag: a timestamp and a short hash instead of a version number. The protobuf definitions, the logging library, the error library, the failure injection library, a netstat helper, a queue helper and a metering SDK are all in that form. One module, a system utility package, is listed with no version at all.
So the build of a released binary of this project depends on unreleased commits of internal modules. That is normal inside one organisation and unusual for an outside builder, because those commits are not addressable from a public tag.
There is also a commented out replacement directive with a two step procedure written around it: uncomment it to point at a private fork while preparing a coordinated change across two repositories, and comment it out again after the change is merged upstream. The comment is left in the file, so anyone running the module tidy the way it suggests will not trip over it.
Two release lines are being maintained at once
The published releases do not follow a single line. There is a 7.5.8 tag dated 17 September 2026, and an 8.5.8 tag dated 27 August 2026, and an 8.5.7 tag dated 9 July 2026.
So the newest release by date is on the older major line, published three weeks after the newest release on the newer one. That is what a maintenance branch looks like when a product is still supported across a major version, and it means version numbers in the wild will include both a 7.x and an 8.x for the same component.
The default branch received a push on 24 September 2026, a week after the newest tag, and the archive flag is off.
The rest of the repository is the standard apparatus of a project of this size: a changelog, a third party notices file, an owners file and an owners aliases file, a golangci configuration, a coverage configuration and a separate coverage service configuration, a static analysis configuration, an error code registry, a directory of sample configurations, and separate top level directories for the client, the commands, the metrics, a plugin loader, scripts, vendored third party code and tools. There is a workspace file for one editor and two agent instruction files, which tells you something about the current state of the tooling habits of the maintainers.
For an adopter, the practical question is which line your TiKV version expects, and the file answers that question only by pointing at the deployment guides.
Editorial conclusion
pd is a good choice if you are running TiKV, because it is the component that decides where regions live, and a poor choice if you are evaluating it as a standalone database, because a single placement driver stores nothing and serves no queries. Three things to check first. Build with the edition variable set deliberately, since the build stops without it and the edition is compiled into the binary. Read the build tags, because the dashboard flag turns CGO on and off underneath you. And if you run the HTTP API on a shared network, look at the CORS headers it returns before you do, because the file's own sample response shows a wildcard origin with the authorization header allowed.
Frequently asked questions
What does PD do in a TiKV deployment?
PD is the placement driver, and it manages and schedules TiKV clusters, with fault tolerance provided by an embedded etcd. It needs to run with TiKV to do anything useful, and a cluster may also include TiDB for SQL. On its own it stores no data and serves no queries.
How do I build pd-server from source?
Install Go 1.26 or later and run make, which is equivalent to make build and produces pd-server, pd-ctl and pd-recover in the bin directory. The build also requires an edition environment variable set to either the community or the enterprise value, or it stops with an error.
Which ports does tikv/pd use?
Two, for two different purposes: 2379 for client URLs, where callers reach the placement driver, and 2380 for peer URLs, where placement drivers talk to each other. Both are declared as exposed ports in the container image and both are published in the single node container example.
Does the tikv/pd HTTP API allow cross-origin requests?
The sample response in the file shows an allowed origin of any site, an allowed headers list including the authorization header, and an allowed methods list covering post, get, options, put and delete. The module file also lists a cross-origin middleware for the web framework, so this is a deliberate framework choice rather than an accident.
What version does a CI build of tikv/pd report?
The literal string None. The build normally derives the release version from git describe including the dirty flag, and replaces it with None when the continuous integration environment variable is set. Build timestamp, git hash, branch and edition are injected into the binary at link time.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/tikv-pd)Star history chart for your README
[](https://hysenlabs.com/projects/tikv-pd)Was this useful?