pg-aiguide: one MCP endpoint, five different config shapes
MCP server and Claude plugin for Postgres skills and documentation. Helps AI coding tools generate better PostgreSQL code.
At a glance
- What is it?
- timescale/pg-aiguide packages PostgreSQL documentation as agent skills plus a hosted search endpoint, with install recipes for a dozen clients. The interesting parts are the config dialects the endpoint needs and the evaluation the project uses to justify itself.
- Who is it for?
- pg-aiguide is worth a try if your agent writes Postgres and you have stopped reviewing its schemas by hand, because the skills are opinionated and version-aware rather than generic advice, and the MCP endpoint covers three manuals rather than one. Three things to know before you rely on it.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 2 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
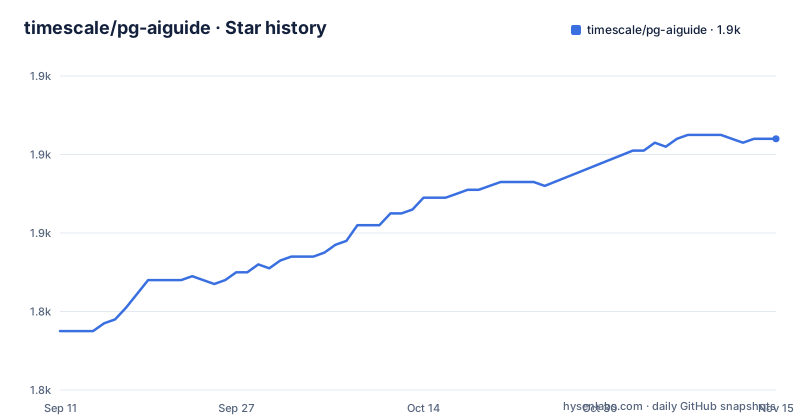
- timescale/pg-aiguide1,884 ★ · +49
| Repository | 2026-09-11 | 2026-11-15 |
|---|---|---|
| timescale/pg-aiguide | 1.8k | 1.9k |
49 Stars in the last 65 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
One endpoint, five config dialects
A single hosted URL is what every client has to be pointed at, and the spelling of that pointer changes with the client. Cursor wants a mcpServers block carrying only a url. VS Code wants the same shape plus a type of http:
code --add-mcp '{"name":"pg-aiguide","type":"http","url":"https://mcp.tigerdata.com/docs"}'Gemini CLI takes the transport as a flag, codex takes the URL as a flag instead, and OpenCode wants a third spelling, a type of remote, inside an object that also carries a schema reference:
{
  "$schema": "https://opencode.ai/config.json",
  "mcp": {
    "pg-aiguide": {
      "type": "remote",
      "url": "https://mcp.tigerdata.com/docs"
    }
  }
}
So url alone, type http, type remote and two flag forms all address the same server, and a sixth and seventh recipe exist for VS Code Insiders. One more oddity: the URL path is docs, which reads like documentation and is in fact the server endpoint.
Three install routes, and only one of them is local
The project can be consumed three ways and they overlap. As agent skills, installed by name, either one at a time or interactively:
npx skills add timescale/pg-aiguide --skill postgreswith a second named skill for investigating an existing database, and the text claims compatibility with Claude Code, Cursor, codex, Gemini CLI, VS Code and forty or more other agents by way of a separate skills directory. As a hosted MCP server for any agent that speaks the protocol. Or as a Claude Code plugin, added as a marketplace and then installed by its short name:
claude plugin marketplace add timescale/pg-aiguide
claude plugin install pg@aiguide
What that plugin actually is, the text says plainly: the skills directory in this repository plus the public endpoint hosted by TigerData. There is no bundled database and no bundled index, so the plugin is two references rather than a local corpus.
The evaluation is one prompt, answered twice, graded by the author
The demonstration is a transcript of a single prompt to Claude Code: describe the schema you would create for an e-commerce website, twice, first with the MCP server disabled and then enabled, write each to its own file in the working directory, then compare the two and say which is better with qualitative and quantitative reasons, using only standard Postgres. The summarized result is four times more constraints, fifty-five percent more indexes including partial and expression indexes, patterns recommended for a particular major version, modern features such as identity columns generated always and a not-distinct null constraint, and cleaner naming and documentation. The reader is left to weigh the method: one prompt, one domain, one model producing both schemas and then judging them, and the project drawing its own conclusion from the comparison. Two details date the transcript: the prompt calls the server the tiger MCP server rather than pg-aiguide, and the results cite version 17 patterns while the development database runs version 18.
Changing the embedding model means re-scraping everything
The environment sample states the constraints that actually bind. Embedding dimensions are fixed at 1536 to match the database schema and cannot be changed without modifying that schema. The model name is optional and defaults to a small OpenAI embedding model, but the comments are emphatic about the consequence of changing it: all data in the database must use the same embedding model, mixing embeddings from different models produces meaningless search results, and if you change the model you must re-scrape all documentation. So the search index is a build artefact with an unusually long half-life, and the model choice is effectively a decision you make once. A custom OpenAI-compatible endpoint is supported for a local runtime or a third-party service, which is the only lever here that does not require a rebuild. The sample also ships a literal placeholder credential and a schema named docs.
The npm package ships dist/, the container ships source
Two packaging paths with different contents. The manifest publishes one file array containing dist, with a bin entry pointing at the built index, so the tarball is compiled output only. The container takes the other route: a Bun base image at a pinned patch level, a production install from the lock file, then copies the TypeScript sources, the skills directory and the migrations directory in, and starts by running the source directly with the http argument. The skills and migrations therefore travel in the image but not, as listed, in the npm tarball, which is presumably why a prepare step runs a staging script after the build. The build itself is a TypeScript compile followed by a chmod over the emitted scripts, and the runtime stack is pinned hard: the OpenAI provider, the AI library and an internal MCP boilerplate are all exact versions while everything else takes a range. The manifest also declares a name that does not match the repository, an organisation scope for a project hosted under a different one.
The check script runs lint with a write flag
The verification entry point is a single script, and it is not read-only. It installs dependencies, typechecks, runs the linter with the write flag, validates the skills directory, then runs the tests reporting only failures. So a contributor who runs the documented check gets a formatter and linter that edits their working tree before any test runs, and the exit code covers a mix of what was found and what was silently repaired. Alongside it sit a separate skills validator with its own script, a protocol inspector launched through the package runner, two smoke scripts for the packed npm artifact and its migrations, and a prepare step. A migration tool is both a dependency and a script name, and a migrations directory sits at the root. For a repository whose product is documentation, the amount of machinery aimed at validating that documentation is the notable part.
A tree with two extensionless entries that shadow script names
The repository root holds four manifest-like files and several directories that decide what the project is: a skills directory, a rules directory, an ingest directory for scraping, a scripts directory, an assets directory, a migrations directory, plugin manifests for Claude Code and Cursor, an MCP configuration file, and separate documentation files for the API, the Claude instructions and the development guide. Two entries at the root have no file extension at all, named bun and check. The check script invokes the first by path, as a wrapper for running the package scripts, which is why the second name appears twice in the listing. Also worth noting: the repository's recorded primary language is Python while the manifest, the compiler settings, the lock file and the container image are all TypeScript on Bun, so the language detection is picking up something other than the shipped build.
Editorial conclusion
pg-aiguide is worth a try if your agent writes Postgres and you have stopped reviewing its schemas by hand, because the skills are opinionated and version-aware rather than generic advice, and the MCP endpoint covers three manuals rather than one. Three things to know before you rely on it. The search side is hosted, so your queries go to somebody else's endpoint, and self-hosting means running the container plus a Postgres plus an embedding pipeline. Switching embedding models invalidates the entire index and requires re-scraping. And the evidence offered is one prompt answered twice by one model that then graded its own output, so treat the constraint and index counts as a demonstration rather than a measurement.
Frequently asked questions
How do I install the pg-aiguide skills for my coding agent?
Run npx skills add timescale/pg-aiguide --skill postgres for the main best-practice skill, or --skill schema-exploration for investigating an existing database, or run the command with no skill flag to pick interactively. The text claims support for Claude Code, Cursor, codex, Gemini CLI, VS Code and forty or more other agents.
Is the pg-aiguide MCP server hosted or self-hosted?
Both, in the sense that the documented path is hosted: the endpoint lives at mcp.tigerdata.com/docs and the Claude Code plugin is described as this repository's skills plus that public endpoint. The repository also carries a Dockerfile and a compose file, so the server can be run yourself, with its own database and embedding pipeline.
What happens if I change the embedding model in pg-aiguide?
You have to re-scrape all the documentation. The environment sample states that all data must use the same embedding model, that mixing embeddings from different models produces meaningless search results, and that embedding dimensions are fixed at 1536 to match a database schema that would also have to change.
Which configuration shapes does the pg-aiguide endpoint need?
It depends on the client. Cursor takes a mcpServers entry with a url alone, VS Code takes the same plus a type of http, Gemini CLI takes the transport as the -t http flag, codex takes the URL with --url, and OpenCode takes a type of remote entry inside an object carrying a $schema reference.
Does the pg-aiguide npm package include the skills?
Not by the file list. The manifest publishes a single dist directory with a bin entry pointing at the built index, while the Dockerfile copies the TypeScript sources, the skills directory and the migrations directory into the image and runs the source directly. A prepare step runs a staging script after the build.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/timescale-pg-aiguide)Star history chart for your README
[](https://hysenlabs.com/projects/timescale-pg-aiguide)Was this useful?