pg_textsearch: negative scores, a server restart, and a Windows step copied from another project
PostgreSQL extension for BM25 relevance-ranked full-text search. Postgres OSS licensed.
At a glance
- What is it?
- A BM25 ranked full-text search extension for recent PostgreSQL versions, licensed under the PostgreSQL licence. Its ranking operator returns negative scores on purpose, it has to be preloaded before the server starts, and its Windows build instructions change directory into a different project's name.
- Who is it for?
- Take pg_textsearch if you want relevance ranking inside PostgreSQL rather than a separate search service, and if your database is on version 17 or 18 and on Linux or Mac. Check three things first.
- Can I use it commercially?
- Yes. PostgreSQL is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository received new commits within the last day.
- What is it written in?
- Mainly C, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
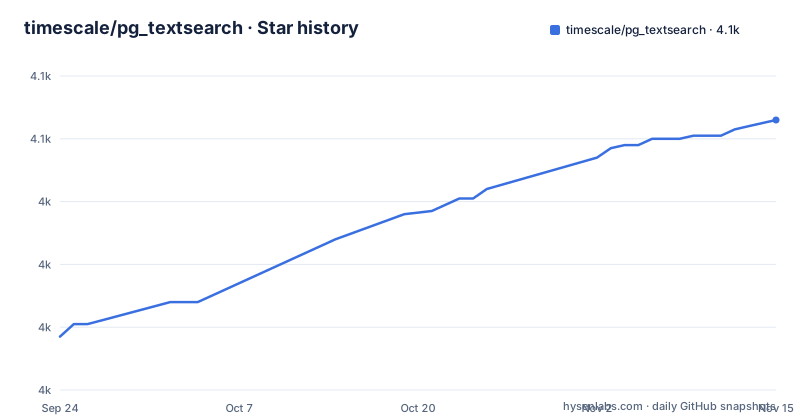
- timescale/pg_textsearch4,066 ★ · +69
| Repository | 2026-09-24 | 2026-11-15 |
|---|---|---|
| timescale/pg_textsearch | 4k | 4.1k |
69 Stars in the last 52 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The ranking operator returns negative scores on purpose
The query syntax is one operator in an ordering clause, and the first thing to understand about it is that its output is negative. Scoring a column against a query text yields negative BM25 scores for ascending index scans, so a lower score ranks first. That is a deliberate choice rather than an accident: it lets the operator slot into the existing ascending order by relevance machinery instead of requiring a descending scan path, which is what makes a `LIMIT` cheap. The operator can also score rows outside an index scan, which is called standalone scoring and still uses corpus statistics taken from the selected BM25 index. The index is detected from the column, and a query can name it explicitly when detection is not what you want. So the same operator serves two roles: a ranked index scan for top-k, and a standalone scorer for rows a different part of the plan selected.
It is a preloaded library, not just an extension
Installation has a step that catches people out, and it is the reason the extension behaves like part of the server rather than a plug-in. You add the library to the preloaded libraries list in the server configuration file and restart the server, then enable the extension in each database where you want it. Everything else is ordinary: a table with a text column, an index built with the BM25 access method, and an ordering query. The preloaded step is why there is also a configuration entry for a background compaction schedule, since the library has to be resident for that work to happen at all. The practical consequence for deployment is that adding this extension to an existing cluster is a configuration change and a restart, not a migration, so it belongs in the same change window as a version upgrade rather than in a feature release.
Boolean filtering is separate from ranking, and the two do not fuse
Boolean filtering uses the database's own operator and query syntax to narrow candidates, and the page is careful about how the two interact. The full-text query syntax supports conjunction, disjunction, negation, phrase operators, prefix matching, and weight restrictions, and phrase and weight checks may be rechecked against the table row after the index returns candidates. There is a configuration requirement that trips people up: the default text search configuration used to parse the column value must match the one the index was built with, or the plan can be wrong. And there is a caching hazard, because if that setting changes after a prepared statement has switched to a generic plan, the cached plan is rejected and you have to deallocate and prepare again, with the note that a newly planned query can pick the correct sequential fallback. On top of that, combining Boolean filtering with ranking is supported but is not yet optimized as one index scan: the filter is evaluated, scores are calculated for the matching rows, and then they are sorted.
Four index options, two of which are tuning knobs
The index options are few and two are the ones you will actually change. The text search configuration is required, and it selects the stemming and tokenisation rules. The `k1` parameter defaults to 1.2 and controls term frequency saturation over a range from 0.1 to 10, which is the standard knob for how quickly repeated terms stop mattering. The `b` parameter defaults to 0.75 and controls length normalisation over a range from 0 to 1, which is how much a long document is penalised relative to a short one. The fourth is not a tuning knob at all but a compaction strategy with three values, inline, background, and manual, describing when spill-time compaction happens, and it has a companion option holding an optional cron schedule captured when the index enters background mode. So the extension distinguishes tuning the ranking from tuning the index's own maintenance, which is a design decision that matters if your corpus is large enough to spill.
Expression, partial, and multi-column indexes are all first-class
The index forms are where this extension earns its place next to the built-in text search, because the useful cases are the ones the built-in access method does not cover. An expression index works on a JSONB field extraction, on a text transformation such as lowercasing a column, on a concatenation of two columns for a title-and-body search, and on an array expression. Two rules apply to all of them: the expression must evaluate to a text-like type or an array of those, and it must use only immutable functions, and the query has to repeat the same expression in its ordering clause rather than referring to the column. Partial indexes add a `WHERE` clause so only a subset of rows is indexed, which is the case where a BM25 corpus statistic is wrong: if you index only one category of documents, the term statistics describe that category. So partial indexing changes the ranking corpus, not just the row count, and that is the detail to think about before using one.
Pre-filtering and post-filtering behave differently under a limit
There are two distinct plan shapes and the page explains both because they have opposite performance characteristics. Pre-filtering is the good case: another index, on a category column for instance, narrows the rows before scoring begins, so standalone scoring only sees candidates. Post-filtering is the other case, where a condition on the scored column itself, such as a minimum content length, cannot be evaluated until after scoring. When the planner chooses the ordered BM25 scan, those extra conditions become post-filters applied after scoring, and the extension compensates by growing its internal scoring batch until the limit is filled or the matches are exhausted. That is a sensible behaviour, since a post-filter that discards most candidates would otherwise return short pages, but it means the cost of a query with a selective post-filter is not obvious from the query text. The page also tells you how to check which plan you are getting, and notes that the planner may prefer standalone scoring with a sequential scan on a small table, with a way to test the index plan deliberately by turning sequential scans off for the session.
The Windows build steps name another project's directory
The build instructions are short for Linux and Mac, where cloning and running make is the whole procedure, and separate for Windows, which needs a working Microsoft compiler environment with both the compiler and the build tool on the path. The Windows steps are where a copy-and-paste error survives in a repository that otherwise looks carefully maintained: after cloning the repository the instructions change into a directory named for a different project's vector search extension, not this one. Everything after that is fine, including pointing the root variable at a PostgreSQL installation directory and building and installing with the Windows make file, so the sequence works if you substitute the correct directory. For comparison, the Linux and Mac path is four lines, and the shared preloaded-library step is one configuration line plus a restart:
shared_preload_libraries = 'pg_textsearch' # add to existing list if neededIt is worth mentioning because a reader following the page literally will fail in a way that looks like a missing clone rather than a typo in a path, and the page is otherwise detailed enough that people tend to follow it exactly.
Editorial conclusion
Take pg_textsearch if you want relevance ranking inside PostgreSQL rather than a separate search service, and if your database is on version 17 or 18 and on Linux or Mac. Check three things first. The extension has to be added to the preloaded library list and the server restarted before it can be enabled, so it is not a drop-in extension the way a type or a function would be. Boolean filtering combined with ranking is not yet a single index scan, so a filter matching many rows will not perform the way the ranked scan alone does. And the Windows build steps contain a directory name from a different project, so follow the Mac and Linux sequence rather than that page if you are building there.
Frequently asked questions
what is pg_textsearch
It is a PostgreSQL extension for relevance-ranked full-text search using BM25. You build an index with the BM25 access method on a text column and rank results in the ordering clause with an operator, with configurable k1 and b parameters and support for expression, partial, and partitioned indexes.
Which PostgreSQL versions does pg_textsearch support?
PostgreSQL 17 and 18 are supported. PostgreSQL 19 is supported on a best-effort basis while it is in beta: its continuous integration is allowed to fail and prebuilt binaries are not published for it yet.
How do I install pg_textsearch?
Prebuilt binaries for Linux on amd64 and arm64 are on the releases page. To build from source, clone the repository and run make then make install, which may need elevated permissions, and on Windows use the Windows make file with a working Microsoft compiler environment on the path.
Do I need to restart PostgreSQL after installing pg_textsearch?
Yes. The library has to be added to the preloaded libraries list in the server configuration file and the server restarted before the extension can be enabled in a database, so it is a configuration change rather than a drop-in extension.
How do I control BM25 ranking in pg_textsearch?
Two index options. k1 defaults to 1.2 over a range of 0.1 to 10 and controls term frequency saturation, while b defaults to 0.75 over a range of 0 to 1 and controls length normalisation. The text search configuration is also required and selects the tokenisation and stemming rules.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/timescale-pg-textsearch)Star history chart for your README
[](https://hysenlabs.com/projects/timescale-pg-textsearch)Was this useful?