ai-powered-search: the book's code, and the compose file that runs all of it
The codebase for the book "AI-Powered Search" (Manning Publications, 2025) and associated "AI-Powered Search: Modern Retrieval for Humans & Agents" Maven course
At a glance
- What is it?
- Everything ships as Jupyter notebooks inside containers, so a clone and a compose up is the whole setup. The port map exposes Spark, Solr or OpenSearch, and a search webserver, and the tree is organised by topic rather than by chapter.
- Who is it for?
- This suits a developer who has bought or is evaluating the book and wants the examples running rather than transcribed, and who is comfortable with Docker and PySpark. It is a poor fit if you want a search library to drop into a project, since the code is organised as teaching material with a webserver attached, and a poor fit if you need to know exactly what data you are allowed to use, because the datasets carry their own licences that the repository says may change.
- Can I use it commercially?
- Not without permission. GitHub finds no licence file in the repository, and without a licence all rights are reserved by default: you may read the code but not reuse it. Check the README, or ask the authors, before using it.
- Is it still maintained?
- Yes. The repository last received commits 5 days ago.
- What is it written in?
- Mainly Jupyter Notebook, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
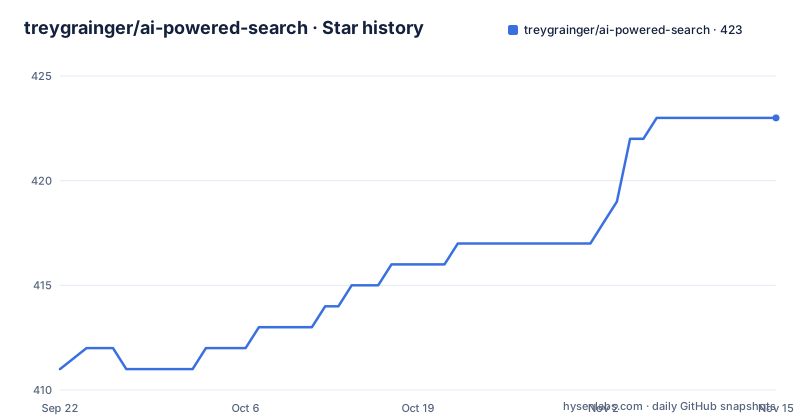
Star history
- treygrainger/ai-powered-search423 ★ · +12
| Repository | 2026-09-22 | 2026-11-15 |
|---|---|---|
| treygrainger/ai-powered-search | 411 | 423 |
12 Stars in the last 54 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Two commands and a browser, and the first build is the slow part
The setup is deliberately reduced to the point where there is nothing to configure. If the source is not already local:
git clone https://github.com/treygrainger/ai-powered-search.gitThen:
cd ai-powered-search
docker compose up
That is the whole procedure, and the documentation flags the one real cost: building the images may take a while, especially the first time. There is no virtual environment to create, no dependency resolver to satisfy, and no model to download before you can start, because the container image is the dependency specification.
Once the containers are up, you open `http://localhost:8888` and get the Jupyter interface, and the entry point is a welcome notebook in the chapters directory that presents a table of contents for the live code examples from across the book. That structure is worth noting: the code is not organised to be read linearly as a program, it is a set of notebooks you navigate, and the welcome notebook is the index.
The book itself carries a longer version of this in Appendix A, which the repository points to for full step by step instructions. The compose route is the quick path, and the appendix is the one to read if you need to understand what the containers are doing rather than just start them.
The port map is the architecture, and it runs more than one search engine
The compose file publishes six ports from the notebooks service, and each one names a piece of the stack. Port 7077 is the Spark master. Port 8082 maps to container port 8080 and is the Spark master UI, with a comment that 8082 is less likely to conflict with something already on the host. Port 8081 is the Spark worker UI, and 4041 is the Spark UI. Port 8888 is the Jupyter notebook interface. Port 2345 is the search webserver, which is a part of the project rather than part of Spark.
Two environment variables wire the notebook container to the rest: `AIPS_SOLR_HOST` points at a hostname called `aips-solr`, and `AIPS_ZK_HOST` points at ZooKeeper on port 2181. So ZooKeeper is in the picture even though the first port list does not mention it, which is the standard arrangement for a Solr deployment.
The search engines are separate services with their own build contexts. Solr builds from `engines/solr/build/`, is exposed on 8983, and declares a dependency on both ZooKeeper and the notebooks service. OpenSearch is the other one: an `opensearch` service building from `engines/opensearch/build/`, with a single-node discovery type, a one gigabyte heap, the security plugin disabled, and an empty initial admin password, plus unlimited memlock and a high file descriptor limit. The security settings are commented as deliberate for a local lab.
Both services carry profiles of `all` and an empty string, which is how the same file serves a default run and a run that includes the optional engines. The compose file is the clearest single artefact in the repository for understanding what a notebook is talking to.
The tree is organised by technique, not by chapter order
The top level tells you how the material is sliced. There is a `semantic_search/` directory, an `ltr/` directory for learning to rank, an `engines/` directory holding the search engine builds and the documentation about abstractions, and a `webserver/` directory matching the service on port 2345. Alongside those are `chapters/` for the notebooks themselves, `aips/` for the project's own library code, `data/` for datasets, `build/` for the notebook container image, and `course/` for the associated course material.
That last one matters for scope. The repository description says it is the codebase for the book and for an associated Manning course titled AI-Powered Search: Modern Retrieval for Humans and Agents, so the repository covers more than the printed chapters. Someone coming only for the book gets material laid out for a course as well.
The technique list in the documentation gives a better sense of coverage than the directory names alone. It covers semantic search with dense vector embeddings from foundation models, retrieval augmented generation, question answering and summarisation that combine search with language models, fine tuning transformer models, personalised search built from user signals and vector embeddings, collecting behavioural signals and boosting models with them, semantic knowledge graphs for domain specific learning, machine learned ranking, click models used to automate that ranking, and generative and hybrid search.
Two implementation choices are stated once and matter for everything else. All examples are in Python, and PySpark is used heavily for data processing. The default engine is Apache Solr, but most examples are abstracted away from the specific engine, with the abstractions and custom integration notes in the engine documentation.
The dataset licence paragraph is the one to read before you run anything
The code is Apache License 2.0 unless otherwise specified, and the repository is careful to say what that does not cover. Executing the code may pull additional dependencies under other licences, so you are told to inspect them before using them in your own project. That is the ordinary warning, and then it gets more specific.
Datasets are called out separately. They may be derived from AI models, or from web crawls of data subject to fair use under the copyright laws of the country of publication, which the repository identifies as the USA. The datasets are published as-is for the sole purpose of demonstrating the concepts in the book, and both the datasets and their associated licences may change over time.
Three things follow that matter for anyone doing more than reading. The data is demonstration data, not a corpus you should build on. The licence position rests on a specific jurisdictional reading of fair use, so it does not transfer to another country unchanged. And the licences may change, so a pipeline that depends on a dataset from this repository is depending on something with no stability commitment behind it.
There is also a single supported route for the other kind of dependency. If you work for a search engine or vector database company and want your engine supported, the README asks you to reach out to the first author at a searchkernel.com address. That is the mechanism for expanding the engine coverage, and it is a person rather than a pull request.
Support lives in the publisher's forum, not in the repository
Help for the book material goes through Manning. The documentation states that a purchase of the book includes online access to the publisher's LiveBook forum, and that this is where you can comment and ask questions about any part of the book. The repository handles the rest: pull requests, GitHub issues, and comments on the project repository are all invited.
The split is worth understanding before you file anything. A question about why an example produces a particular result is a book question and belongs in the forum, where the authors and other readers are. A bug in the code, a broken notebook, or an engine integration request belongs in the repository. Filing a book question as an issue tends to get a slower answer because the maintainers are not the only audience for it.
The repository itself is not versioned. It publishes no GitHub releases, and the last push is dated 2026-09-21. The implication for a reader is that the code tracks whatever the book currently needs, and if you are working through an older printed edition there is no tag to check out that matches it. That is a reasonable arrangement for a book codebase and an awkward one for a course that needs a pinned environment, which is probably why the Docker images are built rather than published with a version tag.
The project is also explicit that it is not a general purpose search library. The documentation says specific technologies are used to demonstrate concepts while most techniques are applicable to many modern search engines and vector databases, and that swappable implementations are expected to become available for the popular options.
Editorial conclusion
This suits a developer who has bought or is evaluating the book and wants the examples running rather than transcribed, and who is comfortable with Docker and PySpark. It is a poor fit if you want a search library to drop into a project, since the code is organised as teaching material with a webserver attached, and a poor fit if you need to know exactly what data you are allowed to use, because the datasets carry their own licences that the repository says may change. Before you run it, check three things: that you have enough free memory, since the compose file ships Spark and at least one search node at once; which engine profile you want, because Solr and OpenSearch are both defined and the default profile is not the only one; and what the dataset licences permit for your use, since the repository is explicit that they are published as-is for demonstration. The last push was 2026-09-21 and the project publishes no GitHub releases.
Frequently asked questions
How do I run the ai-powered-search code examples?
Clone the repository, change into the directory, and run docker compose up. Installing Docker is the only prerequisite, since the code ships as Jupyter notebooks inside containers. Once the build finishes, open http://localhost:8888 and start from the welcome notebook in chapters/.
Which search engine do the ai-powered-search examples use?
Apache Solr is the default, and most examples are abstracted away from the specific engine. The compose file also defines an OpenSearch service alongside Solr, and the engine documentation in engines/README.md covers the abstractions and custom integrations.
What license applies to the data used by ai-powered-search?
The code is Apache 2.0 unless otherwise specified, but datasets carry their own licences. The repository says some are derived from AI models and some from web crawls of data subject to fair use under United States copyright law, are published as-is for demonstrating the book's concepts, and may change over time.
Where should I ask questions about the ai-powered-search book?
Buying the book includes access to the publisher's LiveBook forum, which is where questions about any part of the book are asked. Pull requests, GitHub issues, and comments are for the code itself. The repository also has no GitHub releases, so there is no tag to match an older printed edition.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/treygrainger-ai-powered-search)Star history chart for your README
[](https://hysenlabs.com/projects/treygrainger-ai-powered-search)Was this useful?