TypeDB: a typed schema where every record is an entity, relation or attribute
TypeDB: Built for systems, not records
At a glance
- What is it?
- TypeDB replaces tables and ad hoc labels with a type hierarchy over three roots, queried through TypeQL. The trade is deliberate: the database enforces the shape of your data, and in exchange you cannot query data you have not typed.
- Who is it for?
- TypeDB suits a team that wants one schema to carry entities, relations and attributes, with inheritance and interfaces enforced by the database rather than by code review, and that will commit to TypeQL instead of SQL or Cypher. A team that needs a documented upgrade path should confirm one in the TypeDB documentation first.
- Can I use it commercially?
- Yes, with conditions. MPL-2.0 is a weak copyleft licence: you can use it inside commercial and closed-source software, but if you distribute changes to its own files, you must publish those changes under the same licence.
- Is it still maintained?
- Yes. The repository last received commits 2 days ago.
- What is it written in?
- Mainly Rust, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
Star history
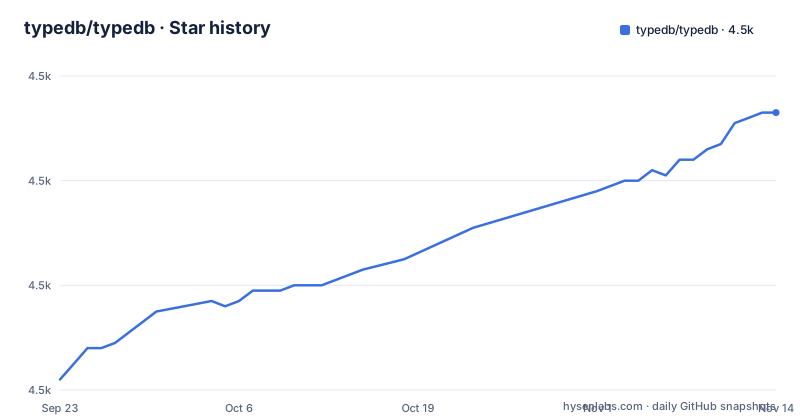
- typedb/typedb4,513 ★ · +51
| Repository | 2026-09-23 | 2026-11-14 |
|---|---|---|
| typedb/typedb | 4.5k | 4.5k |
51 Stars in the last 52 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Every user-defined type subtypes entity, relation or attribute
TypeDB's schema is a type hierarchy, not a list of tables. User-defined types subtype one of three roots, and the root decides what a type is allowed to do. Entities are independent objects. Relations depend on role interfaces, played by entities or by other relations. Attributes carry a value and can be owned by an entity or a relation. Inheritance and interfaces combine freely on top of that, which is where the project claims object model parity with typed object languages.
The example schema declares a value type first, then subtypes it: `email` and `employee-id` both take `sub id`, so `id` becomes their shared base.
define

attribute full-name, value string;
attribute id, value string;
attribute email, sub id;
attribute employee-id, sub id;
The annotations on the next block do the real work. `owns email @unique` makes the email a uniqueness constraint rather than a plain property, and `owns employee-id @key` folds it into the entity's key.
entity user,
    owns full-name,
    owns email @unique,
    plays mentorship:trainee;
entity employee,
    owns employee-id @key,
    plays mentorship:mentor;

relation mentorship,
    relates mentor,
    relates trainee;
That design moves cost onto whoever writes the query. Every table, join and constraint has to be expressed as a type, and a modelling mistake turns into a query that cannot be written at all.
TypeQL can bind the type itself to a variable
TypeQL's syntax is fully variablizable, which means a type name can sit in a variable position instead of a fixed slot. The README runs the same three-line pattern three times to show what that buys.
match $user isa user,
    has full-name $name,
    has email $email;
# This returns all users of any type
Because `isa user` names the supertype, anything subtyping `user` comes back, `employee` included. Narrowing the same pattern to `isa employee` and adding `has employee-id $id` restricts the result to employees, with no change to the shape of the answer.
The third form binds the type itself:
match $user-type sub user;
$user isa $user-type,
    has full-name $name,
    has email $email;
# This returns all users and their type
Read that as two steps: fetch every subtype of `user`, then match each one, and the concrete type comes back as part of the answer. That matters when the caller has to branch on what it just retrieved. Patterns compose instead of executing in a fixed order, which is the practical difference from an imperative query against a store that makes no promises about shape.
Queries as functions, new in TypeDB 3.0
Functions arrived in TypeDB 3.0, and the README calls them a cornerstone of the query model, describing them as modularizable subqueries you can re-use and invoke whenever you want. The gain over copying patterns between queries is straightforward: a pattern that names a variable gets a name, and callers pass their own values in.
The repository layout supports this in a small but concrete way. The top level carries `function/` as its own crate directory next to `compiler/`, `query/`, `executor/`, `ir/` and `answer/`, so the query path is split across crates rather than folded into one. The server's Cargo.toml lists `function` among its dev-dependencies alongside `query` and `executor`.
What the README withholds is a function body. It links out to the TypeQL Functions documentation rather than showing a declaration inline, so the exact syntax has to be read on typedb.com. For anyone copying a first example, that is a genuine gap: the feature is announced with a version number and no runnable snippet.
Running CE: a release archive or one of four Bazel targets
Two routes exist, and the README is explicit that you do not need the second one. The short route is the GitHub Releases page, which carries prebuilt archives, with the walkthrough at typedb.com/docs/home/install/ce. The long route compiles from source and needs Bazel via Bazelisk.
One target covers the common case:
$ bazel build //:assemble-typedb-allThe README describes that as building the TypeDB server with the TypeDB Console included. For a per-architecture archive instead, the README lists targets such as:
$ bazel build //:assemble-all-mac-x86_64-zip
$ bazel build //:assemble-all-mac-arm64-zip
$ bazel build //:assemble-all-linux-x86_64-targz
$ bazel build //:assemble-all-linux-arm64-targz
For other platforms, check the full README and the installation documentation.
A Rust workspace that is also a Bazel workspace
Both build systems sit at the top level side by side: `BUILD`, `MODULE.bazel`, `MODULE.bazel.lock`, `WORKSPACE.bazel`, `deployment.bzl`, `.bazelversion`, `.bazelrc` and a `.cargo/` directory, then `Cargo.toml`, `Cargo.lock` and `main.rs`. The Rust package is the server binary:
[package]
	name = "typedb_server_bin"
	edition = "2024"
	version = "0.0.0"
A header above that block says the file is generated by the TypeDB Cargo sync tool and must not be modified, which is why the version reads `0.0.0`. The release number is stamped elsewhere: the tree holds a top-level `VERSION` file, and the most recent published tags are 3.14.1 on 2026-10-22, 3.14.0-rc1 on 2026-10-17 and 3.14.0-rc0 on 2026-10-15.
Runtime dependencies stay short: `tokio`, `server`, `database`, `tracing`, `resource`, `clap`, `logger`, `fail_point`, `sentry`.
Cloud, Enterprise and the MPL-2.0 community build
TypeDB ships in three editions, and only one of them is this repository. Cloud is a multi-cloud database as a service. Enterprise is that same thing deployed in your own environment, and the README carries a sales address for it. Community Edition is the open-source build under MPL-2.0, with the `LICENSE` file at the top level.
The distinction is a procurement question rather than a code question. Taking CE means you run the server and own the upgrade; the README's own route is download or build, then start it yourself. Moving to Cloud hands that schedule to someone else. The README sends all edition comparisons to a Deploy page on the vendor's site, so the trade-off is documented outside the repository rather than in it.
MPL-2.0 is file-level copyleft, and that is a question for a lawyer rather than a blog post. The narrower engineering check is simpler: the licence identifier and the `LICENSE` file are both in the tree, so you can read exactly what you are agreeing to before you build anything.
Where a property graph stops and TypeQL starts
The nearest neighbour is a property-graph database such as Neo4j, and the difference comes down to where the shape of the data is declared. Neo4j stores labelled nodes and typed relationships, constraining what it accepts through indexes and constraints, and you write Cypher against whatever graph happens to sit there. TypeDB takes that freedom away.
That is the whole trade in one sentence: TypeDB moves modelling into the schema and returns type errors at the database boundary, in exchange for less room to improvise at query time. Exploratory work over a graph whose shape you do not control yet is where the type system becomes friction. When the shape is the asset and you want the constraint enforced by the database instead of by review, the same friction is the reason to switch.
Clients sit on top of this. The README names language drivers as part of the ecosystem.
Five answers the README never gives you
Some questions to settle in the TypeDB documentation before committing: how an existing database moves between server versions, what to do when a schema change breaks a running query, and how backup, restore and rollback work, which for a system holding your source of truth is the first question to ask.
The repository also holds a `docker/` directory at the top level.
Finally the ecosystem. TypeDB Studio is named as the graphical interface, and the README mentions language drivers as part of the ecosystem. The schema you write in TypeQL reaches the server through one of those drivers, so check its compatibility with your server version.
Editorial conclusion
TypeDB suits a team that wants one schema to carry entities, relations and attributes, with inheritance and interfaces enforced by the database rather than by code review, and that will commit to TypeQL instead of SQL or Cypher. A team that needs a documented upgrade path should confirm one in the TypeDB documentation first. The last push to the default branch was on 2026-10-29 and release 3.14.1 shipped on 2026-10-22, so the release cadence is real. Before building, check the target list: //:assemble-typedb-all covers the server plus console, and the archive targets shown in the README cover macOS and Linux on x86_64 and arm64.
Frequently asked questions
What is TypeDB?
TypeDB is a database written in Rust that models data as entities, relations and attributes under a type system with inheritance and interfaces. Queries go through TypeQL, a declarative, functional and strongly typed language, and the open-source build is the Community Edition under MPL-2.0.
TypeDB vs which other databases?
TypeDB's own framing is that its data model unifies the strengths of relational, document and graph databases. Against a property-graph database such as Neo4j, the split is about where shape is declared: Neo4j constrains with indexes and constraints, TypeDB with a type hierarchy you write.
How do I install TypeDB Community Edition?
The README points to the GitHub Releases page for a prebuilt archive and to typedb.com/docs/home/install/ce for the walkthrough. Building from source needs Bazel via Bazelisk, and `bazel build //:assemble-typedb-all` produces the server with the TypeDB Console included.
Does TypeDB document a backup or version migration path?
The README's getting-started and installation sections cover downloading a release or building from source, and link out to typedb.com for concepts and installation; check the TypeDB documentation for backup, restore and migration.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/typedb-typedb)Star history chart for your README
[](https://hysenlabs.com/projects/typedb-typedb)Was this useful?