chromem-go's newest tag is two years old, and it only does exhaustive search
Embeddable vector database for Go with Chroma-like interface and zero third-party dependencies. In-memory with optional persistence.
At a glance
- What is it?
- An embeddable vector database for Go that has no third-party dependencies at all, which the module manifest proves, and which therefore implements ten embedding providers and its document filters by hand. The interface is a deliberate subset of a Python one, the similarity search is brute force only, and the last published tag predates the last push by about two years.
- Who is it for?
- This is a good fit for a Go service that needs retrieval over a modest corpus and does not want a second thing to operate. The zero-dependency claim is real and checkable in the module manifest, the storage model is the SQLite analogy taken seriously, and the code is flat and readable.
- Can I use it commercially?
- Yes, with conditions. MPL-2.0 is a weak copyleft licence: you can use it inside commercial and closed-source software, but if you distribute changes to its own files, you must publish those changes under the same licence.
- Is it still maintained?
- Yes. The repository last received commits 69 days ago.
- What is it written in?
- Mainly Go, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 13, 2026, and from our analysis. They are not legal advice.
Star history
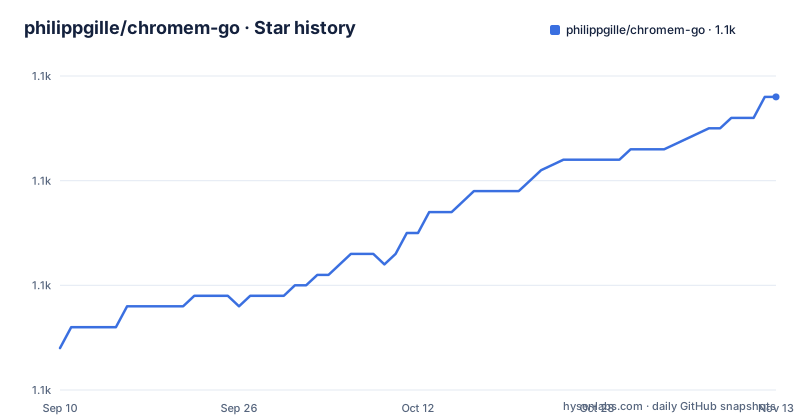
- philippgille/chromem-go1,078 ★ · +24
| Repository | 2026-09-10 | 2026-11-13 |
|---|---|---|
| philippgille/chromem-go | 1.1k | 1.1k |
24 Stars in the last 64 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
It is not a Chroma client, and the README says so explicitly
The name invites the wrong assumption, so the project removes it in the second paragraph.
It is not a library to connect to Chroma, and it is not a reimplementation of Chroma in Go. It is a database on its own.
What it took from Chroma was an interface shape. The README quotes the Python library's core API directly from that project's README at a pinned tag, showing an in-memory client, a create-collection call and an add call with documents and metadata. The Go equivalent is presented beside it, and the one structural difference is named in a comment: the constructor is called a database rather than a client because there is no client and server separation, the database is embedded in your process.
That is the whole pitch, stated with the SQLite comparison the project itself makes. Instead of running a vector database alongside your service, you import a package and the vectors live in your binary's address space.
The stated scope is narrow and stated up front: not scale, not a feature count, but simplicity and performance for the common cases. The intended use cases are listed as retrieval augmented generation and question answering, text and code search, recommendations, classification and clustering.
Zero dependencies means ten embedding providers written by hand
The zero-dependency claim is the one thing in this repository you can verify in five seconds, because the module manifest contains no requirements at all:
module github.com/philippgille/chromem-go

go 1.21
No require block, no indirect block. The only version constraint is the language version.
That has a direct consequence for the feature list. Seven hosted embedding providers are supported, three local ones, plus a bring-your-own interface, and none of them can be implemented with a vendor SDK. Every integration is a hand-written HTTP call against that provider's API surface using the standard library.
The hosted list is OpenAI as the default, Azure OpenAI, Vertex AI, Cohere, Mistral, Jina and mixedbread. The local list is Ollama, a project presenting an Ollama-compatible API under a different name, and LocalAI. Bring your own means implementing one function type.
You can also bypass the whole question by passing embeddings you already have when adding documents, which is the sane path if you have a separate embedding service.
The trade is real either way. Zero dependencies means no supply chain and no version conflicts, and it also means nobody is maintaining those provider integrations but this project, so an API change lands as a bug report.
The interface example claims parity while omitting update and delete
The Go example in the README is short, and it is worth reading closely because of what it does with return values:
package main

import "github.com/philippgille/chromem-go"

func main() {
    // Set up chromem-go in-memory, for easy prototyping. Can add persistence easily!
    // We call it DB instead of client because there's no client-server separation. The DB is embedded.
    db := chromem.NewDB()

    // Create collection. GetCollection, GetOrCreateCollection, DeleteCollection also available!
    collection, _ := db.CreateCollection("all-my-documents", nil, nil)
The error returned by creating a collection is assigned to the blank identifier. In a README whose purpose is to teach an interface, that is the line a reader copies, and it teaches discarding the only error the example produces.
The comment below it is the other thing worth noticing. The Python original's comment for the same step says adding documents can also update and delete. The Go comment says update and delete will be added in the future, and mentions a concurrent variant of the add call instead.
So the two comments are not describing the same API. The project is upfront about this elsewhere: it started with four core methods, added more over time, and deliberately does not intend to cover the whole Chroma surface, preferring Go-idiomatic alternatives.
That is a reasonable position. It is just not the parity the side-by-side layout implies at a glance.
Exhaustive search, and a benchmark that scales linearly because of it
There is exactly one similarity search implementation, and the features list names it three ways to make sure nobody is confused: exhaustive nearest neighbor search using cosine similarity, also known as exact search, brute-force search, or a flat index.
The performance claim is a single sentence. On a mid-range 2020 Intel laptop processor, a thousand documents can be queried in 0.3 milliseconds and a hundred thousand in 40, with very few and small memory allocations.
Two observations. First, the scaling between those two points is linear, which is exactly what an exhaustive scan does, so the number is not going to improve by tuning. Second, the hardware description is a class of machine rather than a part: no processor model, no memory, no vector dimension, no number of queries averaged, no Go version. A reader cannot reproduce the figure from what is given.
That said, the framing is honest about where this stops working. The project says its focus is not scale at the level of millions of documents, and a linear scan at 40 milliseconds for a hundred thousand is a sensible trade for a service that will realistically index one wiki or one set of documents.
It also means every query touches every vector, so the memory claim about few and small allocations is doing real work in that configuration.
Two years of commits past the last tag, on a package that warns about breaking changes
The release history is three tags, and the most recent one is old. The newest published version is 0.7.0 from September 2024, preceded by 0.6.0 in April 2024 and 0.5.0 in March 2024. The most recent push to the main branch is dated 2026-09-06.
So the tree carries roughly two years of changes that no release has captured, which means there is no artifact to pin if you want a versioned dependency, only a commit hash or the branch head.
The README warns about this directly, calling the project beta and under heavy construction, and saying breaking changes may arrive in releases before 1.0. It points at a changelog for the record of what changed.
The language floor is Go 1.21, which is old by current standards and is a deliberate choice for a library rather than an application: raising it would break every consumer still on an older toolchain.
Nothing here is a warning sign by itself. A library that has been stable for two years of unreleased work is a common and healthy pattern. The practical consequence is narrower: dependency tooling will show you a two-year-old version number against a repository that looks much newer, and you have to decide which of those two you actually depend on.
The vector arithmetic has no test file, and neither do three providers
The repository is flat: every Go file sits at the module root, so the package import path is the module path and there is no internal directory anywhere.
That makes the test coverage easy to read off the file list. There are test files for collections, the database, documents, persistence and queries, plus a shared fixtures file, and test files for two of the embedding providers, the Ollama one and the OpenAI one.
There is no test file for the vector arithmetic. For a database whose entire value proposition is cosine similarity between vectors, the file that implements it is the one file in the root with no tests beside it.
There is also no test file for the Vertex integration, none for the Cohere integration, and none for the compatibility layer that presumably routes the remaining providers. And there is no separate file for Mistral, Jina or mixedbread at all, so those must share one of the existing modules.
So of ten listed embedding providers, two have dedicated tests, and the maths everything else depends on has none. None of that means the library is wrong. It does mean the project is asking you to trust the core computation more than the integrations, which is the opposite of what most such projects do.
A go.sum in a module with no dependencies
One small thing in the root deserves a sentence.
There is a go.sum file in a module whose manifest declares no requirements. A checksum file exists to lock transitive dependencies, so a module with nothing to lock normally has no checksum file. Its presence means either that it was generated at a point when the project did depend on something, or that it is carried by tooling defaults.
It is harmless either way, and it is the kind of leftover that survives a dependency removal. It also underlines the point about how this project is maintained: one person, keeping a real library flat and dependency-free, with the residue accumulating at the edges.
The examples directory is the better part of the root, and it is where the library's intended uses are actually demonstrated. There are five of them: a minimal one, a retrieval augmented generation example that pulls from Wikipedia through a local model, a semantic search example over an academic preprint archive through OpenAI, an export and import pair that round-trips through object storage, and a WebAssembly one that matches the experimental browser binding listed in the features.
Five examples covering five different deployment shapes is a better argument for the library's reach than any of the prose around them.
Editorial conclusion
This is a good fit for a Go service that needs retrieval over a modest corpus and does not want a second thing to operate. The zero-dependency claim is real and checkable in the module manifest, the storage model is the SQLite analogy taken seriously, and the code is flat and readable. It is not a fit for a large corpus, because the only search implementation is exhaustive, and 100,000 documents in 40 milliseconds is a linear scan rather than an index. Two things to check before committing. The maintenance shape, which is two years of unreleased commits on a 0.x package whose own README warns that breaking changes can arrive before 1.0, so pin a commit rather than a version. And the test coverage map, where the vector arithmetic and three of the embedding providers have no test files, so if cosine similarity is what you are trusting this for, verify it yourself.
Frequently asked questions
What is philippgille/chromem-go?
It is an embeddable vector database for Go that runs inside your process rather than as a separate service, which the project compares to using SQLite instead of a client-server database. The README is explicit that it is neither a client for Chroma nor a Go reimplementation of it; the inspiration was the interface shape, and it is a database in its own right.
Does chromem-go have any third-party dependencies?
None. The module manifest contains no requirements block at all, only a module path and a Go 1.21 language version. The consequence is that every embedding provider integration is written directly against the standard library rather than through a vendor SDK.
Which embedding providers does chromem-go support?
Seven hosted ones, with OpenAI as the default, plus Azure OpenAI, Vertex AI, Cohere, Mistral, Jina and mixedbread. Three local ones: Ollama, a project exposing an Ollama-compatible API under another name, and LocalAI. You can also implement the embedding function type yourself, or pass in embeddings you already have when adding documents.
How fast is chromem-go, and at what scale?
The README claims a thousand documents can be queried in 0.3 milliseconds and a hundred thousand in 40, on a mid-range 2020 Intel laptop processor, with few and small memory allocations. No processor model, vector dimension, query count or language version is given, and the search is exhaustive rather than an approximate index, so the scaling between those two points is linear.
Is chromem-go ready to depend on?
The repository is marked beta and under heavy construction, with breaking changes possible before 1.0. The newest published release is 0.7.0 from September 2024 while the branch has been pushed to as recently as 2026-09-06, so there is no release matching the current tree and you would pin a commit. The similarity search is the only search implementation and the file implementing it has no test file.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/philippgille-chromem-go)Star history chart for your README
[](https://hysenlabs.com/projects/philippgille-chromem-go)Was this useful?