causalml: ten Cython modules, two exact pins, and a formatter in the runtime dependency list
Uplift modeling and causal inference with machine learning algorithms
At a glance
- What is it?
- Uber's uplift modeling package estimates conditional average treatment effects from experimental or observational data. Its packaging tells a sharper story than its feature list: a compiled tree layer split across three parallel implementations, two dependencies pinned to exact versions while everything else floats, and a build recipe whose coverage target never enables the tracing its own comment describes.
- Who is it for?
- causalml earns its place when a team has experimental or observational data, needs heterogeneous treatment effects rather than an average lift, and can absorb a compiled install: ten Cython modules, two exact dependency pins and a Python floor of 3.11 make it heavier than a pure-Python estimator.
- Can I use it commercially?
- Check first. The repository uses a licence we do not classify automatically, so read its LICENSE file before any commercial use.
- Is it still maintained?
- Yes. The repository last received commits 33 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 13, 2026, and from our analysis. They are not legal advice.
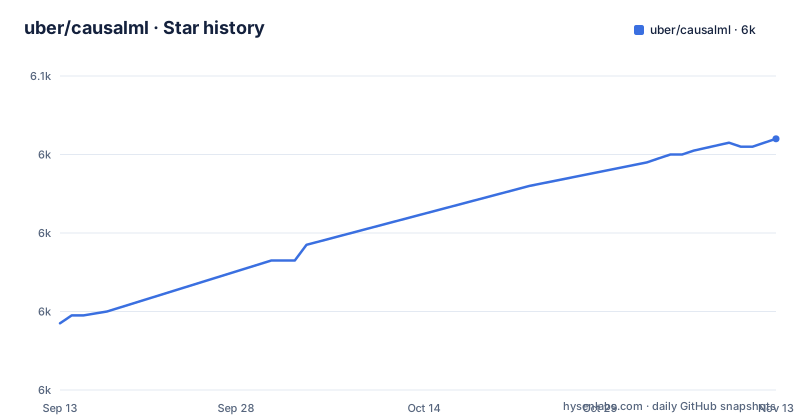
Star history
- uber/causalml6,044 ★ · +47
| Repository | 2026-09-13 | 2026-11-13 |
|---|---|---|
| uber/causalml | 6k | 6k |
47 Stars in the last 61 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
black sits in the runtime dependency list next to numpy and scipy
The dependencies array in pyproject.toml ends with packaging, graphviz and black>=26.1.0. Black is the source formatter, and it is the only entry in that list that does not compute anything: everything around it is numpy>=1.25.2, scipy>=1.16.0, pandas>=0.24.1, scikit-learn>=1.6.0, statsmodels>=0.14.5, xgboost, lightgbm, shap, seaborn, matplotlib, pydot>=3.0.0, tqdm, dill, forestci and pathos. Everything genuinely optional is handled carefully further down in [project.optional-dependencies], which defines a polars extra, a test extra, tf, torch, jax and docs. So the file organizes optional work deliberately and then places the code formatter in the mandatory set, with a version floor higher than any other entry in the array. The Makefile never invokes black either. Its setup_local target installs pre-commit and runs pre-commit install, so the formatting gate is expected to arrive through the pre-commit config in .pre-commit-config.yaml rather than through the tool now declared as a hard requirement on every user.
Two dependencies are pinned to exact versions while everything else floats
forestci==0.6 and pathos==0.2.9 are the only two entries in the dependency array written with == instead of >=. Every other line moves within a range. The effect of an exact pin is that a bug fix or a security release in that package cannot reach an installed causalml without a new causalml release, and a second package in the same environment that needs a different forestci turns into an unsolvable resolution rather than a warning. The two pinned lines sit at opposite ends of the file's own history of care: pathos is in the 0.2 series while scipy in the same array is at 1.16.0 and scikit-learn at 1.6.0. requires-python is set to >=3.11, so the interpreter floor is current even where the dependency floors are not. The test extra inherits the same style, adding pytest>=4.6, pytest-cov>=4.0 and causalml[polars], which means the coverage run described below needs an optional group installed before it can measure anything.
The coverage target never sets the environment variable the compiled layer needs
setup.py enables annotation unconditionally with Cython.Compiler.Options.annotate = True, and its comment explains that line tracing is deliberately opt-in through the CYTHON_TRACE environment variable, so that coverage builds keep instrumentation while release wheels stay uninstrumented and fast. The Makefile never mentions CYTHON_TRACE. The two relevant targets read:
.PHONY: install
install: build_ext
	pip install .

.PHONY: test
test: build_ext
	pytest -vs --cov causalml/
	python setup.py clean --all
build_ext runs python setup.py build_ext --force --inplace with nothing exported ahead of it, so under make test the compiled half of the package gets built without the tracing hooks the comment relies on. Those compiled units are the tree estimators under causalml/inference/tree/, which is the directory a coverage run over causalml/ is meant to measure. The install target inherits the same chain, since install depends on build_ext and build_ext depends on clean, and clean deletes build, dist, eggs, causalml.egg-info and every .so, .c and .html file under causalml/. Every install therefore starts by removing the build products and recompiling all ten Cython modules from scratch.
Ten Cython modules split across three parallel tree implementations
cython_modules in setup.py lists ten compiled units, and they divide into three families rather than one. causalml.inference.tree._tree contributes six: _tree, _criterion, _splitter, _utils, _group_criterion and _group_builder. causalml.inference.tree.causal contributes two, _criterion and _builder. causalml.inference.tree._uplift contributes two, also _criterion and _builder. The naming makes the relationship plain. A plain decision tree is the base, and the causal and uplift variants each replace the criterion that scores a split and the builder that constructs one, which is why those two families need only two modules each where the base needs six. That structure is the reason a source install compiles anything at all. setup.py tries to import Cython.Build and numpy, and on ImportError falls back to dist.Distribution().fetch_build_eggs, a setuptools-era helper that downloads build requirements at build time rather than declaring them, so the first build of a fresh environment reaches out for the compiler tooling it needs.
The README hands installation to a documentation link
The Installation section of the README says that installation instructions are available at https://causalml.readthedocs.io/en/stable/installation.html and stops there. Quickstart points at quickstart.html the same way, and Example Notebooks points at examples.html. No pip command, no conda command and no version pin appear in that section. The one installation path visible in the repository is the Makefile, where install depends on build_ext and runs pip install ., which compiles the ten Cython modules first and needs a working C toolchain before it installs anything. A reader who wants the Python floor, the extras or the build prerequisites will not find them in its Installation section. pyproject.toml is where requires-python = ">=3.11" lives, alongside the optional groups and the comment explaining why the docs group carries only the Sphinx toolchain. The documentation list above the installation section does point at an FAQ page described as answering common installation and usage questions, so the README treats installation as a topic the hosted docs own.
The docs extra omits pandoc, which is not a Python package
The docs extra lists sphinx>=8.2,<10, pydata-sphinx-theme>=0.20.0, sphinxcontrib-bibtex and nbsphinx, and the comment beside it gives the reasoning: the Sphinx toolchain only, everything the docs import including numpy, scikit-learn and matplotlib already arrives through the package's own dependencies, and the neural backends are mocked in docs/conf.py rather than installed. The same comment then notes that nbsphinx also needs the pandoc binary, which is not a Python package. That makes docs the one optional group pip cannot satisfy on its own, so a clean machine running pip install causalml[docs] ends up with a Sphinx stack and no renderer for the notebooks the example pages are built from. The neural backend extras are stated with different care from each other. tf names tensorflow>=2.4.0, torch names bare torch and pyro-ppl with no floor at all, and jax spells out a four-package set: jax>=0.4.1, flax>=0.11.0, optax>=0.1.4 and orbax-checkpoint>=0.10.0.
The benchmark loaders verify their downloads and ship the ground truth
The loaders cover the standard causal inference benchmarks, naming LaLonde, IHDP and Twins, with SHA256-verified downloads, and they ship the ground-truth metrics those datasets make computable: PEHE, ATE error and policy risk. Provenance and terms for each dataset are pointed at a separate datasets page instead of being stated in the README, so the downloads are checksum-verified while the question of what the data may be used for is one hop away. The leaderboard notebook is described as regenerating every published number end to end, which is a heavier commitment than a results table, and the three metrics cover different questions: PEHE and ATE error score an effect estimate against known truth, while policy risk scores the targeting decision that estimate implies. Two documentation pages frame how to use that output, one described as an end-to-end walkthrough training one estimator per family and showing how to decide which one to believe, and one described as a decision path and capability matrix over the estimators.
Seven months between v0.15.5 and v0.16.0, with pyproject sitting on 0.17.0
Three releases are recent enough to compare: v0.16.0 on 2026-02-06, v0.17.0 on 2026-07-04 and v0.18.0 on 2026-10-12. The first gap is five months and the second just over three, so the cadence is uneven rather than absent. pyproject.toml declares version = "0.18.0", which matches the newest tag instead of drifting ahead of it, and the repository is not archived, with the last push to master on 2026-10-12. Version changes are tracked in a changelog held at docs/changelog.rst. The README also carries a disclaimer that the project is stable and being incubated for long-term support, while noting it may contain new experimental code for which APIs are subject to change. That disclaimer pairs awkwardly with the compiled layout, because the tree estimators under causalml/inference/tree/ are the part of the package a caller cannot easily patch between releases, so an API that shifts there is a rebuild rather than an edit.
Editorial conclusion
causalml earns its place when a team has experimental or observational data, needs heterogeneous treatment effects rather than an average lift, and can absorb a compiled install: ten Cython modules, two exact dependency pins and a Python floor of 3.11 make it heavier than a pure-Python estimator. Before trusting a targeting decision, check the three things this repository actually gives you the means to check: the SHA256-verified loaders for LaLonde, IHDP and Twins, the PEHE, ATE error and policy risk values they let you compute, and the leaderboard notebook that regenerates the published numbers end to end. A team that only needs an average treatment effect is paying for machinery it will not use, and the disclaimer about experimental code with subject-to-change APIs applies to whichever estimator you pin today.
Frequently asked questions
What does causalml estimate, and what does it need as input?
It estimates the Conditional Average Treatment Effect, meaning the causal impact of an intervention T on an outcome Y for users with observed features X, from experimental or observational data and without strong assumptions on model form. The README names campaign targeting optimization and personalized engagement as the use cases.
What does uber/causalml require before pip will install it?
Python 3.11 or newer, per requires-python = ">=3.11" in pyproject.toml, and a working C toolchain for the ten Cython modules that setup.py compiles, including the ones under causalml.inference/tree/_tree, causalml/inference/tree/causal and causalml/inference/tree/_uplift. The README's Installation section contains no pip command and points at the hosted installation page instead.
Which license is causalml under?
The README states the Apache 2.0 License and points at the LICENSE file in the tree root, and the pyproject.toml classifier reads License :: OSI Approved :: Apache Software License. The repository's license field reads NOASSERTION, so GitHub does not identify the licence there even though both package-level sources say Apache.
Does causalml bundle the benchmark datasets?
It ships loaders for LaLonde, IHDP and Twins with SHA256-verified downloads, together with the ground-truth metrics they enable: PEHE, ATE error and policy risk. Provenance and terms for each dataset are described on a separate datasets page rather than in the README.
Which extra do I install for a neural backend in causalml?
There are three: tf names tensorflow>=2.4.0, torch names torch and pyro-ppl without a floor, and jax names jax>=0.4.1, flax>=0.11.0, optax>=0.1.4 and orbax-checkpoint>=0.10.0. A separate polars extra, a test extra and a docs extra complete the set, and the docs comment notes that the neural backends are mocked in docs/conf.py rather than installed for the documentation build.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/uber-causalml)Star history chart for your README
[](https://hysenlabs.com/projects/uber-causalml)Was this useful?