ICU: two implementations, two release streams, and four quality reports for one of them
The home of the ICU project source code.
At a glance
- What is it?
- The ICU repository holds the C and C++ implementation, the Java implementation, a tools directory and vendored dependencies, and it is the home of a project stewarded by the Unicode Consortium. Its front page names no build tool, points its bug tracker at a hosted issue system rather than the repository host, and links a static analysis and coverage report only for the Java side.
- Who is it for?
- Adequate fit: anyone who needs mature internationalisation support and reads the per-language readme rather than the top-level page, which is the only documentation this repository offers at the root. It fits badly for a team that wants one build path or one quality signal, because there are at least three build configurations in the tree and the reported analysis and coverage belong to the Java implementation alone.
- Can I use it commercially?
- Check first. The repository uses a licence we do not classify automatically, so read its LICENSE file before any commercial use.
- Is it still maintained?
- Yes. The repository last received commits 2 days ago.
- What is it written in?
- Mainly C++, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 13, 2026, and from our analysis. They are not legal advice.
Star history
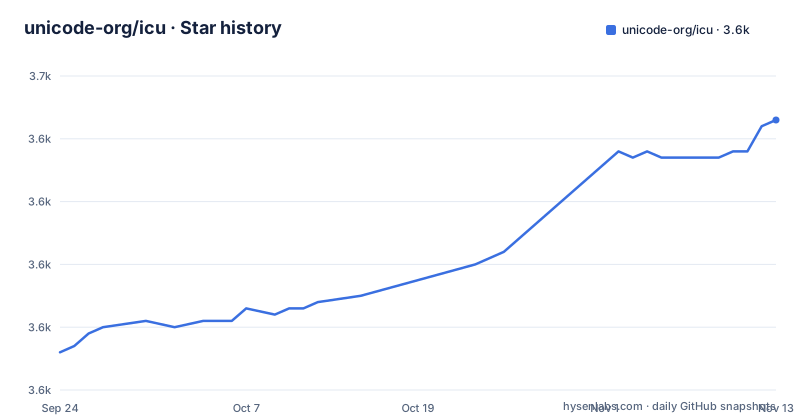
- unicode-org/icu3,643 ★ · +37
| Repository | 2026-09-24 | 2026-11-13 |
|---|---|---|
| unicode-org/icu | 3.6k | 3.6k |
37 Stars in the last 50 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Four link destinations, and the bug tracker is not on the repository host
The front page is a title, a sentence about stewardship, and four plain lines. The first is the source address, which is the repository itself. The second is labelled bugs, and the address is not a repository issues page: it is a project board on a hosted issue system, under a project path for ICU. So bug reports for a repository hosted on one forge are tracked on another product.
The other two are documentation. An API documentation site and a user guide, both served from a project pages address, both on the same host as the quality reports further down the page.
That is the whole navigation of the file. There is no build section, no getting started, no contribution summary beyond a paragraph at the bottom, and no link to either of the two implementations except the subdirectory list further down. A reader who lands here is given four URLs and has to work out from the rest of the page which one answers their question.
Two release streams publish into one repository
The release record contains two different tag families, and they are not interleaved versions of one thing.
One family looks like a product version with a release candidate suffix: a tag for the 79 release candidate, published 2026-09-25 and titled as the 79 RC. The other family is a three-part path made of a product name, an ISO date, and a major line: one published 2026-08-31 and one published 2026-07-01, both naming the same 79 line.
So a second implementation with its own release cadence shares this repository's releases list, and its tags carry the build date inside the tag name. That is a reasonable way to publish nightly or dated snapshots, and it has one practical consequence: sorting the release list by date interleaves two different products, and there is nothing on the tag to say which implementation a given snapshot is meant to be consumed as.
Every quality report on the page is for the Java implementation
The build status table has six rows. Two are the implementation builds, one for the C and C++ side and one for Java, both GitHub Actions runs filtered to the main branch. The third is a Valgrind job, which is a C and C++ memory-checking workflow. The fourth is an exhaustive test workflow, a fifth is a fuzzing row, and the sixth is a supply-chain scorecard.
The quality reports section below it has four items, and all four are Java. A static analysis report from a Java analyser, a Java code coverage report, an API comparison report for the Java library, and a link to the full set of reports in various formats.
So the C and C++ side gets a build, a memory checker and an exhaustive test run, and no static analysis or coverage figure anywhere on this page. That is a documentation asymmetry rather than a testing asymmetry, since a Valgrind workflow and an exhaustive test workflow are considerably more than nothing, but a reader comparing the two implementations from this page alone would conclude the C side is the less measured one.
Two build-status rows are third-party services queried with a filter
Four of the six build rows are badges pointing at this repository's own workflows, with the branch in the query string so the badge follows the main line rather than the default.
The other two are different in kind. The fuzzing row does not point at a workflow at all. It points at an external fuzzing service's issue tracker, with a query that filters for open issues, a specific component identifier, and a search term matching this project. Which means the fuzzing signal on this page is a count of open bugs somebody else found and has not yet fixed, read live from another site.
The supply-chain scorecard row is a link to a viewer for a project whose identifier is a repository URI. Also external, also live.
So a reader scanning the build table gets four internal signals and two external ones, with no indication on the page of which is which beyond the domain in the link.
The page names no build tool, and the tree carries three configurations
The top level holds twenty entries and no build script. There is no makefile, no shell build entry point, and no root build definition file of any kind.
What is there instead is a set of tool configurations. Two files configure a build system and one of them is a version-pinning file for a launcher that reads the other; a third file, at the root, uses the older workspace filename rather than the newer module filename that the same tool prefers. Then there is a Maven project file with its own tool directory beside it, a static analyser configuration that matches the Java report linked on the page, and a skip list.
So the tree implies at least two distinct build systems, one for each implementation, with the C and C++ side carrying a launcher-pinned setup and the Java side carrying Maven. The front page mentions none of it, and instead routes the reader to a separate readme inside each of the two implementation directories. That is a defensible choice for a repository this old and this federated, but it means the top-level page tells you nothing about how either implementation is built.
The license field reports nothing determined, and the page names the terms
The recorded license for this repository is NOASSERTION, which is a statement that no license was determined rather than the name of one.
The front page says something more specific, in its closing section. The contents of the repository are governed by the Unicode Terms of Use and are released under a license file at the root. That address is the Unicode Consortium's own copyright page, and the same paragraph notes that a contributor licence agreement is required to contribute, pointing at the contributing file or at opening a pull request.
The tree backs the page up. There is a license file at the root, and beside it a file named for keys, which is where release signing keys would live. There is also a separate security policy file, which the page never links.
So three of the four signals a reader would use to check the terms agree with each other, and the fourth, the machine-readable field, is blank. For a project whose whole purpose is a data standard, that is a gap worth closing rather than an interesting detail.
Four top-level directories, two of which are the products
The subdirectory list on the front page has four entries. Two are the implementations: one for C and C++, one for Java, and each links to its own readme inside its own directory rather than to documentation on the site. The other two are a tools directory and a directory described as vendor dependencies.
That vendor directory is the one worth a second look in a project of this age. Vendored third-party code committed into the tree is how a build stays reproducible without a package manager, and it is also how a project of this size accumulates a large surface of code it does not own. The page gives no indication of what is in it, how it is updated, or whether there is a process for it.
The remaining root entries are governance and tooling: a security policy, a contributing file, a documentation directory, the license file and the keys file, the readme itself, and the build configurations covered earlier. Twenty entries in total, of which two are the actual products and one is a black box.
Editorial conclusion
Adequate fit: anyone who needs mature internationalisation support and reads the per-language readme rather than the top-level page, which is the only documentation this repository offers at the root. It fits badly for a team that wants one build path or one quality signal, because there are at least three build configurations in the tree and the reported analysis and coverage belong to the Java implementation alone. Four things are worth checking first. The front page contains no build command and names no build tool. The bug tracker is a hosted issue system, not the repository host. The releases are two separate tag families in one repository, one dated per date for a second product line. And the recorded license field reports that nothing was determined, while the page names the Unicode Terms of Use and points at a license file. Nothing above was built, compiled or run.
Frequently asked questions
What is Unicode ICU?
The International Components for Unicode, a project stewarded by the Unicode Consortium. The repository is the home of its source code and holds a C and C++ implementation, a Java implementation, a tools directory and vendored dependencies. Its page links an API documentation site and a user guide.
What is ICU4?
The name is used for the implementations inside this repository. The front page lists two subdirectories, one for C and C++ and one for Java, and each links to its own readme. The page also links a separate API documentation site and a user guide hosted on project pages.
What is ICU in programming?
A set of libraries for handling text and internationalisation across languages. In this repository the implementations are the C and C++ one and the Java one, published with two separate release tag families, one versioned per release and one carrying a build date. The recorded language for the repository is C++.
How can I use Unicode characters in C++?
The repository's C and C++ implementation lives in the icu4c directory, and the front page links that directory to its own readme. The top-level page carries no build command; its build status table points at a workflow for the C implementation, a Valgrind job and an exhaustive test job, all filtered to the main branch.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/unicode-org-icu)Star history chart for your README
[](https://hysenlabs.com/projects/unicode-org-icu)Was this useful?