oneDAL's 3-18x Spark claim is measured against DAAL 2020 and Spark 2.4.4
oneAPI Data Analytics Library (oneDAL)
At a glance
- What is it?
- An Apache-licensed C++ and SYCL library of accelerated machine learning kernels for tabular data, now governed by a foundation but still installed under Intel's package names. Both performance claims in the readme date from the previous decade.
- Who is it for?
- oneDAL is the right thing to reach for if you are doing tabular machine learning on Intel hardware and want hand-tuned kernels rather than a Python library, and the scikit-learn extension is the lowest-friction way in. Two things to check before you commit.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 1 day ago.
- What is it written in?
- Mainly C++, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
Star history
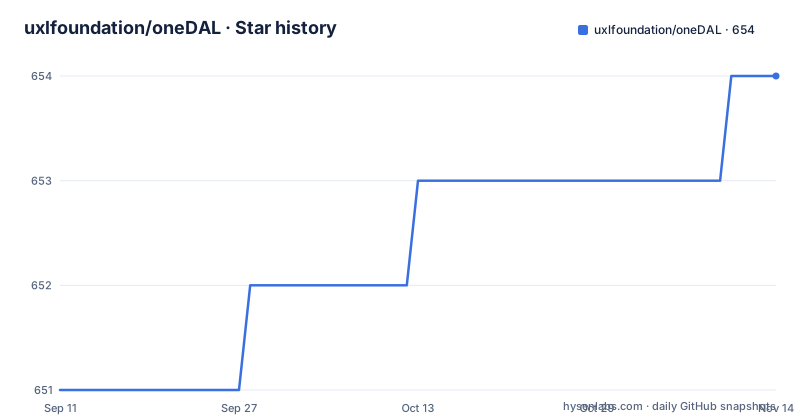
- uxlfoundation/oneDAL654 ★ · +3
| Repository | 2026-09-11 | 2026-11-14 |
|---|---|---|
| uxlfoundation/oneDAL | 651 | 654 |
3 Stars in the last 64 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The 3-18x figure compares against Spark 2.4.4 and a 2020 build of its own predecessor
The readme contains exactly one headline performance claim, for Spark MLlib acceleration: a 3-18x increase over the default Apache Spark MLlib.
The footnote underneath gives the measurement conditions, and they matter more than the range.
The comparison baseline is Intel DAAL 2020 Gold. That is the predecessor library, not a current oneDAL, and a 2020 build of it. The Spark version is 2.4.4. The cluster is seven large AWS instances, the precision is double, and the executor configuration is twelve executors with eight cores, nineteen gigabytes of memory each and eight CPUs per task, on an EMR image from 2022.
So the claim is oneDAL's Spark integration measured against a four-year-old Spark and against a 2020 build of the library it replaced, on hardware rented from a cloud provider.
None of that makes the number wrong. It makes it a statement about a specific comparison rather than about oneDAL against today's Spark, and Spark has had four major releases since.
The integration itself is real: it happens through a separate accelerator project, and the readme links to it rather than claiming the work as its own.
The scaling section is an empty table with a 2019 footnote
The readme has a scaling section promising results for strong and weak scaling, and it is empty.
What renders is a caption row with two column headings, one for a strong scaling result and one for weak scaling results, and beneath it a single empty row. No numbers, no chart, no image.
The footnote is more specific than the section it describes. The precision is single. The hardware is a two-socket machine with sixteen cores per socket running at 2.3 GHz. The software is a 2019.3 build of the predecessor library, with a 3.0.0 release of a Python MPI binding and a 3.6.8 Python distribution. And the details are said to be in an arXiv article whose identifier begins with 1909, which places it in 2019.
So the second performance claim in this readme is also measured against the previous generation of the library, five to seven years ago, and points at a paper from 2019.
The pattern across both sections is consistent: the scaling evidence is a placeholder awaiting a rerun, and the footnotes were written when the project was still Intel's data analytics acceleration library.
Distributed support itself is real, and there is an MPI sample in the tree. What is missing is current evidence for it.
Three binary channels, two named for the old library, one Linux-only
Installation offers three binary routes and a source route.
The first is the vendor's own stand-alone download. The second is a conda package from the conda-forge channel, and the package is called `dal-devel`. The third is a NuGet package called `inteldal.devel.linux-x64`.
Both of the non-vendor names are worth pausing on. The conda package uses the acronym for the old library name, not the current one, and the NuGet package carries the vendor prefix in its name and the word for a development build in it.
The NuGet name also ends in `linux-x64`. That is the only architecture and operating system it serves, so a .NET developer on Windows or on an Apple machine has no binary from that channel and is sent to the source instructions.
The source route is the cleanest of the four: clone the repository, or download a specific version from the releases page, and follow the instructions in the install document. The readme also tells you to check a system requirements page first, which is the right order for a library with a CPU-feature and accelerator matrix this size.
A conda package called for a library that no longer exists under that name is not a bug. It is the cost of a rename nobody wanted to break for existing users.
Three interface generations and four build systems in one repository
The examples section lists three C++ interface styles, which is three generations of the same library.
There is the current interface with SYCL support, the current interface without it, and the older interface family, which the readme links to under its own name. Elsewhere the readme points at a page comparing the current and legacy interfaces, so both are documented rather than deprecated-and-forgotten.
The build side is wider still. There is a makefile, plus two files that look like generated or maintained variants of it. There is a CMake directory. There is a Bazel build, with a build file, a module definition, a configuration file and a pinned Bazel version. And there is a conda recipe, which is the packaging definition the conda-forge channel builds from.
Four build systems for one library is a real maintenance cost, and it is not accidental: each serves a different consumer. Make and CMake serve the source-build instructions, Bazel serves the in-tree and monorepo use cases, and the conda recipe serves the channel.
What that buys is that the same source can be consumed four ways without anyone maintaining a fork. What it costs is that a change has to be reflected four times, and the repository root now holds thirty-two entries to do it.
Examples are duplicated along the same axis, with parallel directories for the legacy interface, the current one and the CMake path, and a separate agent instruction file inside the examples tree.
Calendar versions that ship months late, and nothing released since June
The version scheme is calendar-based, and the release dates do not match the version names.
Three releases are visible. A version numbered for November 2025 was published in March 2026. A version numbered for 2026.0 was published in May. A version numbered 2026.1 was published in June.
So the year-and-month in the name describes the development window rather than the publication date, and a release named for one month arrives two to four months later.
That is a workable scheme for a library with a two-release-a-year cadence and a long support tail. It is also confusing at a glance, because a version string of 2025.11.0 looks older than 2026.0.0 and is in fact newer.
The last release is 2026.1.0 from 2026-06-10. The last push to the default branch is later today.
So there have been commits on the branch for four months without a tagged release, on a project whose distribution channels are binary packages rather than source archives. Anyone installing from a channel is four months behind anyone building from the branch, and there is no nightly or edge channel named to bridge that.
For a library with an accelerator and a CPU-feature matrix, that gap is where compatibility problems live.
The build badge points at a project named DAAL and the maintainer contact is Intel's
Governance has moved. The project is part of a foundation, has a foundation-run artificial intelligence special interest group, foundation working groups, foundation mailing lists, and a contribution guide that covers both the code and the specification it implements.
Two things in the readme have not moved with it.
The first is the continuous-integration badge, which points at an Azure Pipelines build definition under a project path that uses the old library acronym. So the pipeline that builds the foundation's project lives under the previous name, and a reader following the badge arrives at a URL that does not match the repository it came from.
The second is the private maintainer contact, which is a mailbox at the vendor's domain. Alongside it the readme offers GitHub Discussions and a vendor-hosted community forum.
None of that is wrong. A foundation-owned project with vendor-maintained pipelines and vendor-employed maintainers is a normal and legitimate arrangement, and pointing support questions at the people who do the work is better than pointing them at a mailing list nobody reads.
It is worth knowing, though, when you are deciding where a question will get answered in two years.
The repository does have a security policy and a maintainers file, and the readme's own security section is truncated mid-sentence in the copy you get.
CPU acceleration is SIMD and cache blocking, GPU acceleration is SYCL and oneMKL
The mechanism section is two sentences and it is the most useful technical content in the readme.
On the CPU, acceleration comes from leveraging single-instruction, multiple-data instructions and from exploiting the cache structures of modern hardware. That is the standard description of a hand-tuned kernel library, and it is the honest one: the speedup is instruction selection plus blocking, not parallelism.
On the GPU, acceleration comes through the SYCL framework and a separate math kernel library. So the GPU path is not oneDAL's own; it is oneDAL generating portable code that a compiler lowers for the device, with the linear algebra delegated.
That division has a practical consequence. The GPU path's portability is bounded by what SYCL implementations exist and by what the math library supports on the device, while the CPU path depends on the instruction sets the compiler targets and on how well the blocking matches the cache hierarchy.
The library targets tabular data specifically, with linear regression, clustering and random forests named as examples, and it covers three execution shapes: CPU, GPU and multi-node distributed.
There are two ways to use it. The Python route is an extension that makes existing scikit-learn code call oneDAL without you changing the code. The C++ route is the library itself, with or without SYCL.
The readme opens with a disabled 2014 Intel copyright header
The first sixteen lines of the readme are an HTML comment.
Inside it is a conventional permissive-licence header: a copyright line naming Intel and dated 2014, the standard statement that the software is provided under the Apache licence version two, a warranty disclaimer, and a closing comment marker. The whole block is wrapped so that it does not render.
That is a small cosmetic thing, and it points at something larger. The project was Intel's data analytics acceleration library, was donated to a foundation, and was renamed. The header stayed.
The same pattern shows in the package names, in the pipeline path, in the maintainer mailbox, and in the two performance footnotes. This is a project that has changed institutional home four times over in name and ownership while keeping every internal identifier.
That is a defensible migration strategy. Renaming a conda package or a build pipeline breaks every existing user and every downstream mirror, and keeping the old name costs nothing but confusion.
It does mean that nothing in the readme tells you when the performance numbers or the package identifiers were last brought in line with the current project.
One more small inconsistency: the repository's recorded homepage uses plain HTTP, while every documentation link in the readme uses HTTPS.
Editorial conclusion
oneDAL is the right thing to reach for if you are doing tabular machine learning on Intel hardware and want hand-tuned kernels rather than a Python library, and the scikit-learn extension is the lowest-friction way in. Two things to check before you commit. Read the performance footnotes rather than the headline, since both numbers in the readme were measured against Intel's own predecessor builds rather than against a current baseline. And plan your packaging route deliberately, because the binary channels are named for the old library and one of the three is Linux-only.
Frequently asked questions
How do I install oneDAL?
Three binary routes and one source route. The vendor stand-alone download, a conda package from conda-forge named dal-devel, a NuGet package named inteldal.devel.linux-x64 which serves Linux on x64 only, or a clone of this repository with the instructions in the install document. The readme tells you to check the system requirements page first.
How do I use oneDAL from Python?
Through the extension for scikit-learn, which makes existing scikit-learn code call oneDAL behind the scenes without rewriting it. The C++ alternative is to use the library's own interfaces, either with SYCL support or without it, and the readme documents a comparison against the older interface family.
How much faster is oneDAL than default Spark MLlib?
The readme claims a 3-18x increase, measured against Apache Spark 2.4.4 and a 2020 build of the predecessor Intel library, on seven large AWS instances with double precision and a twelve-executor configuration. The scaling section it also promises has an empty table, with a footnote citing a 2019 build.
Does oneDAL run on GPUs?
Yes, through the SYCL framework with a separate math kernel library, alongside CPU acceleration through single-instruction, multiple-data instructions and cache blocking. The library targets tabular workloads across CPUs, GPUs and multi-node distributed setups.
Which oneDAL versions are released?
The visible releases use calendar versions: one named for November 2025 published in March 2026, 2026.0 in May and 2026.1 in June 2026. The default branch has been pushed since the last release, and no nightly or edge channel is named to cover the gap.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/uxlfoundation-onedal)Star history chart for your README
[](https://hysenlabs.com/projects/uxlfoundation-onedal)Was this useful?