valkey-search: a vector and secondary index module for Valkey
valkey-search is a C++ module which extends valkey with vector search and secondary indexing capabilities. It enables users to index and query data stored in Valkey using complex queries with filters while maintaining high performance and scalability.
At a glance
- What is it?
- valkey-search is a C++ Valkey module that adds vector search, numeric, tag and full-text indexing to Valkey, with the command surface borrowed from the search command family so existing clients keep working. What is interesting in the design is the query planner, which picks between pre-filtering and filtering during the similarity search rather than leaving you to choose, and the skip-index-on-load option that trades startup time for index consistency.
- Who is it for?
- valkey-search fits a team that already runs Valkey and wants semantic or hybrid search in the same datastore rather than bolting on a separate index, and the command names being the familiar search family means the client-side change is smaller than adopting a new system. It is not a general-purpose search engine replacement, since the supported surface is six commands and the module has to be loaded into the server process.
- Can I use it commercially?
- Yes. BSD-3-Clause is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository received new commits within the last day.
- What is it written in?
- Mainly C++, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 13, 2026, and from our analysis. They are not legal advice.
Star history
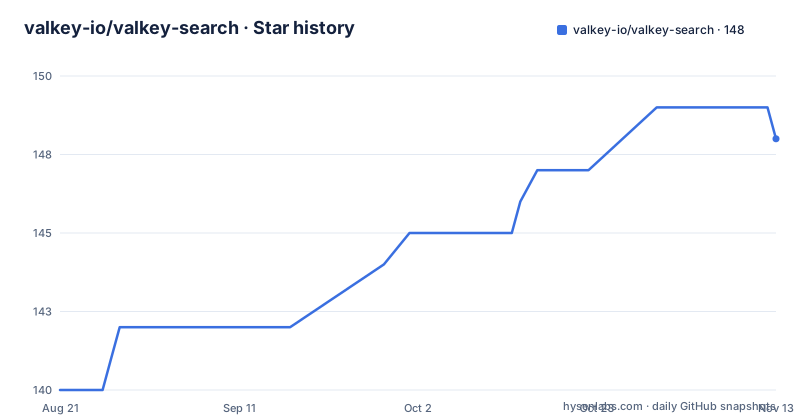
- valkey-io/valkey-search148 ★ · +8
| Repository | 2026-08-21 | 2026-11-13 |
|---|---|---|
| valkey-io/valkey-search | 140 | 148 |
8 Stars in the last 84 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Six commands, named the way clients already expect
The supported command list is short enough to be worth quoting in full, and the naming is the first thing to notice. There are commands to create an index, drop one, inspect one, list them, run a search, and run an aggregate. Those are the same names used by the search command family elsewhere in the ecosystem, which is a deliberate compatibility choice: a client that already speaks that protocol can talk to a Valkey server with this module loaded without learning a new API. The module is BSD-3-Clause licensed and distributed as a loadable shared object rather than a fork, so the server you already run stays the server you already run. The command reference for the full set of options lives on the project site rather than in the repository, with a separate quick start document in the repository holding worked examples. If you are porting an existing search integration, the work is in the data model rather than in the transport.
Two data types to index, and two ways to search vectors
The indexing surface is deliberately narrow. You can index data held in the Valkey hash type or in the JSON type, and those two paths are documented separately in the repository because the field addressing differs. On the query side, vector search comes in two forms and the distinction matters for correctness rather than speed. Approximate nearest neighbour search uses an HNSW index, which is the fast path and the reason billions of vectors are described as tractable. Exact matching uses K-nearest neighbours, which is what you want when a result set must be complete rather than nearly complete, at the cost of scanning rather than traversing a graph. The module also covers non-vector workloads explicitly, with numeric, tag and full-text indexes, so a workload that outgrew key lookups but does not need embeddings can stay in the same module.
The planner picks pre-filtering or inline filtering for you
Hybrid queries are where a vector search engine earns its keep, and the two obvious strategies trade off against each other in opposite directions. Pre-filtering applies your filters first and then runs an exact similarity search over what survives, which is efficient when the filtered set is small and expensive when it is large. Post-filtering runs the similarity search and filters afterwards, which works when the filter-qualified set is large and can return empty or short results otherwise. The module does not ask you to pick. It uses a hybrid approach with a query planner that selects the most efficient execution path between pre-filtering and inline filtering, where inline means the filter is applied during the similarity search itself rather than before or after it. That third option is the one you would otherwise have to implement, and having a planner choose it means the same query can be a good idea at one cardinality and a bad idea at another without a code change.
Query scaling has a documented cost: replica lag
Scaling is described in two axes rather than one, and the second axis comes with an explicit trade. The module supports both standalone and cluster modes, and in both of them query processing and ingestion scale linearly with CPU cores, so a bigger machine buys throughput without architectural change. Cluster mode is what you reach for when storage is the constraint, since it gives horizontal scaling of the keyspace. Query scaling is separate, and the way to get it is to send reads to replicas. The condition attached is that replica lag must be acceptable for your workload, which is the real constraint: a read from a lagging replica can return a result that does not yet reflect a write you just made, so this is acceptable for a recommendation feed and not acceptable for a lookup that must be read-your-writes consistent. That single sentence is the whole scaling story, and it is worth reading before choosing a topology.
skip-rdb-load trades startup time for index integrity
There is one operational flag that deserves its own decision, because it changes what happens on every restart. The index schema is loaded from the RDB snapshot, but the indexes themselves are not: they are created empty and refilled by the backfill process. The two stated benefits are index consistency, meaning you can recover from a corrupted or inconsistent vector index rather than serving bad nearest neighbours, and reclaiming deleted memory, since an index holding many deleted vectors frees that memory when it is rebuilt during startup. The cost is startup time proportional to the data, and it is not fully symmetric: vector indexes are rebuilt through backfill while the non-vector tag and numeric indexes keep working immediately, so a search that depends only on those is available sooner. The flag is described as non-modifiable and supplied to the module at load time, so it is a start-up choice rather than something you can toggle at runtime.
Building needs a modern compiler, and the docs say how to get one
The build is CMake with a wrapper script, which is the convenient path, and the prerequisites are where people lose time. Building requires GCC 12 or newer, or Clang 16 or newer, and on a distribution with an older default compiler the documentation gives the exact remedy: install the versioned packages and then point the system at them with update-alternatives, so the newer compiler wins.
sudo apt install -y gcc-12 g++-12
sudo update-alternatives --install /usr/bin/g++ g++ /usr/bin/g++-12 1000
sudo update-alternatives --install /usr/bin/gcc gcc /usr/bin/gcc-12 1000
The toolchain list for Debian and Ubuntu includes the build essentials, CMake, Ninja, the GoogleTest development package, OpenSSL and systemd development headers, plus the language server and the formatter and tidy tools. The Red Hat family list mirrors it with the package names changed. Three script invocations cover the work, and the help flag is the one to try first:
./build.sh --help
./build.sh
./build.sh --run-tests
Integration tests are a separate step with their own dependency set, including a Python virtual environment package and locale data, and they fetch a signing key from a package repository, so they need network access the unit tests do not.
Loading it means a module flag, and JSON means a second one
Running the module is a server start-up flag rather than a configuration block. The server is started with a load-module option pointing at the built shared object, and if you want to index the JSON data type you load the JSON module in the same invocation with a second load-module flag. Threading is set for you by default: the module matches its worker count to the number of CPU cores on the host. That default is sensible and it is overridable, with separate flags for the reader and writer thread counts if you need to pin them, which matters when the host is shared or when you are benchmarking and want the numbers to be stable across machines. The performance characteristics described in the repository come from three specific choices rather than a general claim: a threading model that allows lock-free execution in the read path, a design intended to use the CPU cache efficiently, and SIMD instructions for vector processing. Vectors are held in memory, which is the assumption underneath all three.
Editorial conclusion
valkey-search fits a team that already runs Valkey and wants semantic or hybrid search in the same datastore rather than bolting on a separate index, and the command names being the familiar search family means the client-side change is smaller than adopting a new system. It is not a general-purpose search engine replacement, since the supported surface is six commands and the module has to be loaded into the server process. Three things to check before building on it. The compiler floor is real: GCC 12 or Clang 16 or newer, which on an older distribution means upgrading the toolchain with update-alternatives before the build will work. Loading it needs the JSON module as well if you want to index JSON. And decide about startup behaviour up front, because the skip-index-on-load flag exists precisely for indexes you would rather rebuild than trust. Licence is BSD-3-Clause, the last push was on 2026-09-28, and the release tags show 1.0 through 1.2 lines still moving.
Frequently asked questions
What is valkey-search and how is it distributed?
It is a BSD-3-Clause C++ module that extends Valkey with vector search and secondary indexing, distributed as a loadable shared object rather than a fork. You start the server with a load-module option pointing at the built module file.
Which commands does valkey-search support?
Six: the commands to create an index, drop an index, inspect an index, list indexes, run a search, and run an aggregate. The names match the search command family elsewhere, so an existing client can talk to a server with the module loaded.
How does valkey-search handle hybrid vector and filter queries?
It uses a query planner that selects between pre-filtering, which filters first and then runs an exact similarity search, and inline filtering, which applies filters during the similarity search. Post-filtering is described as the third approach and can return empty or short results when the filter-qualified set is large.
What does the skip-rdb-load flag do in valkey-search?
The index schema is loaded from the RDB snapshot but the indexes are not: they are created empty and refilled by the backfill process. It lets you recover from a corrupted or inconsistent vector index and frees memory held by deleted vectors, at the cost of startup time. The flag is passed at module load and is not modifiable.
What do I need to build valkey-search?
GCC 12 or newer, or Clang 16 or newer, plus CMake, Ninja, GoogleTest development files, OpenSSL and systemd headers. The build uses a wrapper script: run ./build.sh to build, ./build.sh --help for available arguments, and ./build.sh --run-tests for the unit tests. Integration tests use a separate flag and their own dependencies.
How does valkey-search scale across cores and clusters?
Query processing and ingestion scale linearly with CPU cores in both standalone and cluster modes, and cluster mode gives horizontal scaling of the keyspace for large storage needs. Horizontal query scaling comes from directing reads to replicas, which is only suitable if replica lag is acceptable for your workload.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/valkey-io-valkey-search)Star history chart for your README
[](https://hysenlabs.com/projects/valkey-io-valkey-search)Was this useful?