microgpt-c has 4192 parameters and a Makefile that guesses your architecture
The most atomic way to train and inference a GPT in pure, dependency-free C
At a glance
- What is it?
- microgpt-c is a character-level transformer with forward pass, backprop, Adam and sampling in a single C file that links nothing but libm. The interesting engineering is in the twenty lines of build logic, where the Windows branch hardcodes the architecture and the ARM branch is decided by the wrong condition.
- Who is it for?
- microgpt-c earns its place as a readable reference and as a smoke test for a new machine, not as a model to build on. Four thousand parameters will not do your work, and the corpus it ships is a list of names.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 90 days ago.
- What is it written in?
- Mainly C, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
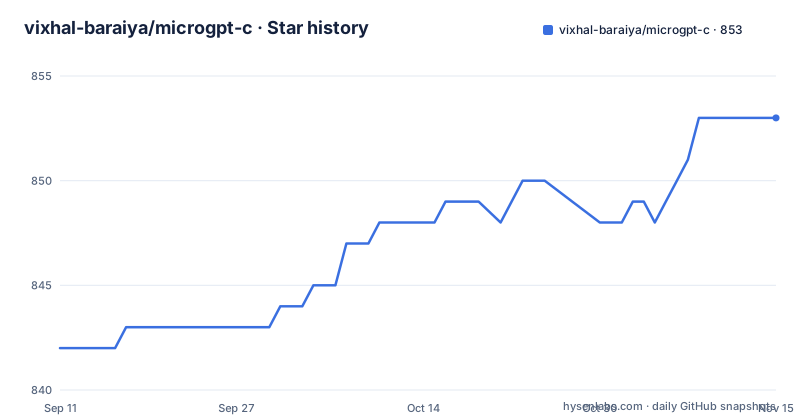
Star history
- vixhal-baraiya/microgpt-c853 ★ · +11
| Repository | 2026-09-11 | 2026-11-15 |
|---|---|---|
| vixhal-baraiya/microgpt-c | 842 | 853 |
11 Stars in the last 65 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The Windows branch hardcodes the architecture
The Makefile decides its instruction set flags in a dozen lines, and the Windows path is the one to read first:
ifeq ($(OS),Windows_NT)
  UNAME_M := x86_64
Instead of asking anything, the Windows branch declares the machine to be x86_64. That value then feeds the flag choice, so a Windows machine on ARM would be compiled with -march=native -mavx2 -mfma, flags for a different processor. Everywhere else the architecture comes from uname -m, and the filter decides the branch:
ifeq ($(filter arm64 aarch64,$(UNAME_M)),)
  ARCHFLAGS ?= -march=native -mavx2 -mfma
else
  ARCHFLAGS ?= -march=native
The comment above it explains why the flags have to come from the command line at all: clang ignores an in-file pragma GCC target, so the intrinsics will not build without them being passed explicitly.
make run always trains on data/names.txt
There are three targets and one of them does everything. Building is a single compile of a single source file against libm, with CFLAGS defaulting to -O3 plus the architecture flags, -ffast-math and -Wall. The run target depends on the binary and then executes it against a fixed data path:
DATA    := data/names.txt
run: $(BIN)
	./$(BIN) $(DATA)
So make run is not parameterized, and the documented way to use your own text is to skip make and call the binary yourself, with a corpus of one item per line:
./microgpt data/names.txtThe clean target is small in the same way, removing the binary plus object files and .dSYM bundles. The .dSYM part is macOS-specific, which is fine, but a Windows build leaves a microgpt.exe that clean does not name, so repeated builds on MSYS2 accumulate a file the target does not know about.
4192 parameters, and a trigram baseline with five times more
The evaluation paragraph is the part to quote when someone asks whether the model memorises. The model has 4192 parameters. Trained on 20000 of the 32033 names, it scores 2.2054 nats per character on those and 2.2039 on the 12033 it never saw. The claim attached to those two nearly identical numbers is that it generalises rather than memorises, and that it beats an interpolated trigram baseline carrying nearly five times as many parameters.
Five times 4192 is 20960, which is within a rounding error of the 20000 training examples. A trigram table with roughly one entry per character of the training set is a memorisation baseline of exactly the size you would expect, which is what makes the comparison meaningful rather than flattering: the small transformer matches a table that got to keep the whole training set as parameters.
Scoring in nats per character is also the right unit to quote, because it is comparable across corpora and across model sizes without rescaling.
Two forward passes, one of them single-token
Training and inference do not share a code path, and the reason is activations. gpt_forward stores what backpropagation needs, which is fine when the cost is amortized over a training step. gpt_forward_infer is a specialised single-token path that skips that bookkeeping, and the claim made for it is that its logits match the training path to within fp32 rounding. docs/PERFORMANCE.md covers how the fast path works and what limits it.
Two forward functions in a 4192 parameter model is a strange place to spend complexity, and the reason is the benchmark at the end of the README: the printed throughput line reports how many tokens per second the host achieved, so the inference path is the thing being measured. Read the equivalence claim as a statement about this program, not as a numerical property of floating point: it says two functions in one binary agree, and it does not say anything about how either compares to another implementation.
-ffast-math is on in the same build that claims fp32 agreement
The flag list is the quiet part of the build:
CFLAGS  ?= -O3 $(ARCHFLAGS) -ffast-math -Wall
LDLIBS  := -lm
-ffast-math tells the compiler it may skip the IEEE rules around infinities, NaN handling and reassociation. For a training loop it buys speed and nobody argues with it. For a claim of the form these two functions agree to within fp32 rounding, it is worth knowing that the agreement was measured inside a build compiled under relaxed floating point semantics, so reproducing the number on a strict build may not give the same digits.
The comparison is also internal. Nothing in the README compares against another implementation, so the interesting question for a reader who wants to port this is whether the fast path still agrees once the compiler is not allowed to reassociate the arithmetic. That is a question for your own build, not something the project states.
The printed loss bounces while the running average falls
The sample output in the README is worth reading as a curve rather than as proof of progress:
step 5000 / 20000 | loss 2.6036  (avg 2.2940)
step 10000 / 20000 | loss 1.9639  (avg 2.2564)
step 15000 / 20000 | loss 2.7007  (avg 2.2151)
step 20000 / 20000 | loss 2.3463  (avg 2.2201)
The instantaneous loss goes down, up above its starting value, and down again, which in a character-level model on single-token batches is expected rather than alarming. The average is the number to watch, and it falls monotonically from 2.2940 to 2.2201, which is consistent with the 2.2054 and 2.2039 figures quoted for the training and held-out sets.
The same block then prints ten generated names, which is the actual point of the exercise: a character model that has seen 20000 names will produce plausible spellings like kayley, shayan and amari, and the samples are as much a test of the sampling code as of the model.
Two machines on the benchmark table, one source file, no releases
The performance table has two rows. An Apple M5 Pro on the NEON path reports 10,168,430 tokens per second, and an AMD Ryzen 5 5600H on AVX2 reports 6,927,775. The sample run output prints its own line in the same units, naming the compiler and the path it took, c fp32+NEON, followed by the same M5 Pro figure.
Two machines is a demonstration that the code takes both the ARM and the x86 path, and one number per path, rather than a comparison you can generalise from. There is no CPU with AVX-512, no single-core versus all-core distinction stated, no batch size, and no indication of whether the figure counts a forward pass alone or the full sampling loop.
The repository itself is three directories and a build file: src/ for the single C file, data/ for the corpus, docs/ for the performance notes, plus the Makefile, LICENSE and README. MIT licensed, not archived, last pushed 2026-08-17, with 844 stars, 112 forks and 2 open issues, and no GitHub releases at all, so there is no tagged version to install.
Editorial conclusion
microgpt-c earns its place as a readable reference and as a smoke test for a new machine, not as a model to build on. Four thousand parameters will not do your work, and the corpus it ships is a list of names. What it does give you is a training loop you can read end to end in one file, a loss figure in nats per character so you can compare it against your own experiments, and a benchmark path that prints a throughput number for the host you built it on. Two things to check before you trust it on another machine. The build logic decides NEON versus AVX2 from the architecture string and hardcodes x86_64 under Windows, so an ARM Windows host gets flags for a CPU it may not have. And the build enables -ffast-math, which is worth remembering when you read the claim that the two forward passes agree to within fp32 rounding.
Frequently asked questions
What does microgpt-c depend on?
Nothing beyond libc and libm. The transformer lives in src/microgpt.c and the Makefile links with LDLIBS set to -lm, building a single microgpt binary.
How do I train microgpt-c on my own text?
Pass the binary a corpus file with one item per line, for example ./microgpt data/names.txt. The make run target always passes data/names.txt, so any other corpus means calling the binary directly.
Which platforms does microgpt-c build on?
macOS, Linux and Windows under MSYS2, on ARM64 with NEON and x86-64 with AVX2, with the Makefile choosing the flags for the host. Under Windows it does not ask the system, and sets the architecture to x86_64.
How large is the model in microgpt-c?
4192 parameters. Trained on 20000 of 32033 names it scores 2.2054 nats per character on those and 2.2039 on the 12033 it never saw, ahead of an interpolated trigram with nearly five times as many parameters.
Why does microgpt-c have two forward functions?
gpt_forward stores activations for backpropagation, while gpt_forward_infer is a specialised single-token path whose logits match to within fp32 rounding. docs/PERFORMANCE.md explains how that path works and what limits it.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/vixhal-baraiya-microgpt-c)Star history chart for your README
[](https://hysenlabs.com/projects/vixhal-baraiya-microgpt-c)Was this useful?