The repo ships a requirements file it tells you not to install
A talking LLM that runs on your own computer without needing the internet.
At a glance
- What is it?
- A local voice assistant in three parts, speech recognition, a language model backend and a speech synthesizer, with the synthesizer swapped from one open model to another in May 2025 and the old version kept on a dated branch. The install docs are careful about a generated lock file, and the two install paths disagree with each other on which sentence tokenizer to download.
- Who is it for?
- This is a readable reference implementation of a voice loop rather than a product, and the three stages are cleanly separated in the code, which makes it a good thing to read before writing your own. Two things to settle first.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Activity is slowing. The repository last received commits 7 months ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
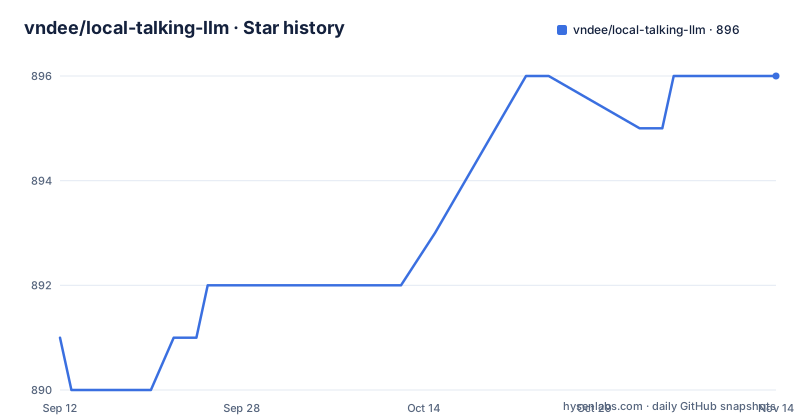
Star history
- vndee/local-talking-llm896 ★ · +5
| Repository | 2026-09-12 | 2026-11-14 |
|---|---|---|
| vndee/local-talking-llm | 891 | 896 |
5 Stars in the last 63 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The repository ships a requirements file it tells you not to install
The installation section opens with a warning against using pip with the requirements file, and explains why: the file was generated by freezing a resolved environment, so its pinned versions may not install across different systems. The recommended alternative is a lock-aware installer, with a shell command to install the tool itself, a clone, a sync, and activation of the environment that sync created:
# Install uv if you haven't already
curl -LsSf https://astral.sh/uv/install.sh | sh
# or on macOS: brew install uv
# or on Windows: powershell -ExecutionPolicy ByPass -c "irm https://astral.sh/uv/install.ps1 | iex"

# Clone the repository
git clone https://github.com/vndee/local-talking-llm.git
cd local-talking-llm

# Install dependencies using uv (recommended)
uv sync
So the file is committed for reference and for the older path, not for use. The prose elsewhere still tells you there is a detailed dependency list at a link, which has no address behind it. The two article addresses are also not the same address: the repository homepage field points at one domain and the readme credits the original write-up on a different one.
The two install paths download different sentence tokenizers
The recommended path ends with a one-line command that downloads one named NLTK tokenizer package. The alternative pip path ends with a nearly identical command that downloads a differently named one. They are not the same resource under two spellings, and the tokenizer is used for splitting responses into sentences, so a path that silently gets the wrong one is a path that behaves differently. Neither section says which the code needs or what happens if the download is skipped, which means the difference is invisible until segmentation looks wrong. Everything else in the two blocks matches, down to the comment offering the Windows activation variant, so the tokenizer name is the single divergence in an otherwise parallel pair of instructions.
The manifest description is still the template placeholder
The project metadata names the package and pins a version, and then the description field contains the scaffolding text that a package initialiser writes when it cannot think of one. That string is what a package index shows, what a search result shows, and what any tool reading the manifest reports as the summary. The repository description field elsewhere is real and accurate, so the two disagree and the wrong one is the machine-readable one. There is also no build-system table in the manifest, so the editable install recommended in the pip path relies on the tool's default backend rather than a declared one, which is a quiet difference between the two paths that the documentation does not mention.
A fine-tuning library ships as a runtime dependency with no fine-tuning docs
The declared dependencies include a parameter-efficient fine-tuning library, at a version floor, and the page never mentions fine-tuning anywhere. Nothing in the architecture, the usage flags or the configuration section adapts a model. That is odd, because the speech model it uses is described as a half-billion parameter model, which is exactly the size people fine-tune, and a fine-tuning library sitting in runtime dependencies means every install pulls in adapters, accelerate and their transitive weight for a capability the documentation does not offer. The same list also contains a packaging library, which is build tooling in a runtime set. Neither is harmful, and both are the sort of thing that tells you the project was set up for an experiment the write-up skipped.
The prose names audio libraries the manifest does not install
The dependency walkthrough lists a set of libraries with a one-line reason each, and among them three for audio: a recorder and playback library, another audio interface library, and a speech recognition library. Only one of the three appears in the manifest. The other two are nowhere in the declared dependencies, so following the prose and following the manifest give you different environments, and the prose is the part a newcomer reads first. The same passage defers the full list to a link, and the words after that link have no address attached, so the authoritative list is neither that sentence nor the prose but the manifest itself.
One of the two documented backends needs the internet
The repository description promises a talking model that runs on your own computer without needing the internet, and the architecture section makes the language model backend pluggable between a local runtime and a hosted provider. The hosted option is set up with an API key in an environment variable, and the page states plainly that no local runtime installation is needed in that case, with the language model in the cloud while transcription and synthesis stay local. That is a useful option for people without a GPU, and it is also the option that breaks the offline promise. The page frames the choice as quality versus hardware, not as offline versus online. Even on the fully local path the first run needs weights that are not in the repository, since the transcription and speech models are pulled by the libraries that load them. Voice cloning is documented as needing a ten to thirty second sample passed on the command line, and the synthesis side also exposes an exaggeration value, a weight value and a flag to save generated samples.
The lint target only works after the recommended path
The build file has two targets. One is a scaffold target that prints the current user, time, working directory, shell and terminal with colour escapes, which is what a project initialiser generates and nobody edits. The other is the real one, and it activates a specific environment directory by name before running the pre-commit hooks over every file. The name it activates is the one the recommended install creates. The alternative install creates a different directory with a different name. So the single useful make target works only on the path the documentation recommends, and on the other path it fails at the activation step rather than at the hook, which is a confusing first error for someone who followed the instructions. The model selector example is worth a second look too, since the one given is a code completion model demonstrated on a chat loop, which suggests the flag is passed straight through to the runtime.
The May 2025 synthesizer swap is preserved on a dated branch
The header of the page carries an update note rather than a changelog. It records that in May 2025 the speech synthesizer was replaced with a different open model, that the new one brings voice cloning, emotion control, a half-billion parameter size with faster inference, and built-in neural watermarking. The implementation it replaced is kept on a branch named for that date, which is a tidy way to hold the history and the only place in the repository where an older code path is still reachable. It also means the page is a write-up with a revision date rather than a maintained manual, and the funding link above it is part of that framing. The project publishes no GitHub releases, and the last commit on the default branch is dated 2026-04-04.
Editorial conclusion
This is a readable reference implementation of a voice loop rather than a product, and the three stages are cleanly separated in the code, which makes it a good thing to read before writing your own. Two things to settle first. The offline premise is conditional: one of the two documented backends is a hosted API, and the other two stages pull models on first use, so a genuinely disconnected run needs preparation. And the project tells you to ignore its own requirements file, which is honest, but it means the dependency set you actually get comes from the manifest rather than from anything pinned. Treat the manifest as the source of truth and the documentation as a guide written alongside it.
Frequently asked questions
How do I install local-talking-llm?
The page recommends a lock-aware installer: install it, clone the repository, run the sync command, and activate the environment it creates. An alternative path uses a standard virtual environment and an editable install from the manifest, with the page warning that the committed requirements file should not be used.
Does local-talking-llm work without an internet connection?
It can, with a local model backend, but not with all of them. One documented backend is a hosted provider configured with an API key, where the language model runs in the cloud while transcription and synthesis stay on the machine.
What does local-talking-llm use for speech recognition and speech output?
Speech recognition uses Whisper, and synthesis uses a half-billion parameter open model from a speech company, with voice cloning and emotion control. The implementation was switched to that synthesizer in May 2025, with the earlier one preserved on a dated branch.
How does voice cloning work in local-talking-llm?
You record a ten to thirty second sample of the voice and pass its path to the application with the voice flag. The same command line also takes an exaggeration value and a weight value for emotion, a model selector, and a flag to save the generated samples.
Can I fine-tune the models local-talking-llm uses?
The documentation does not say, and it never mentions fine-tuning. A parameter-efficient fine-tuning library is nonetheless declared as a runtime dependency, along with a packaging library, so the environment supports more than the write-up describes.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/vndee-local-talking-llm)Star history chart for your README
[](https://hysenlabs.com/projects/vndee-local-talking-llm)Was this useful?