LLMInternSkill, where the install command points at another repository
LLMInternSkill: LLM internship resume and job-search Codex Skill for resume polish, JD tailoring, evidence guard, interview grilling, and Project Scout.
At a glance
- What is it?
- LLMInternSkill is a Codex Skill for internship and job-seeking resumes that grades every line against available evidence and refuses to upgrade a claim it cannot support. The design is unusually disciplined and the worked examples are specific enough to check. The install instructions, however, clone a repository that is not this one, which is the first thing to fix before anything else.
- Who is it for?
- Use this skill if your problem is that a resume reads as thin rather than as false, because its whole contribution is deciding which lines survive contact with your materials folder. Check four things first.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 103 days ago.
- What is it written in?
- Mainly Markdown, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
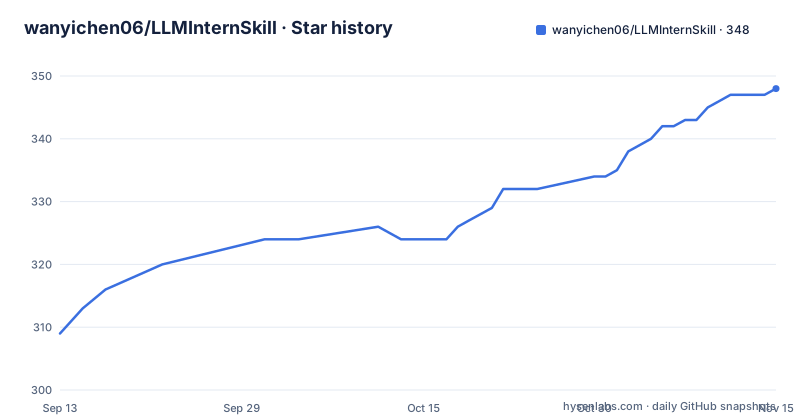
- wanyichen06/LLMInternSkill348 ★ · +39
| Repository | 2026-09-13 | 2026-11-15 |
|---|---|---|
| wanyichen06/LLMInternSkill | 309 | 348 |
39 Stars in the last 63 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The install command clones a different repository
The third quick-start method is the one that installs the skill, and it does not point at this repository.
mkdir -p ~/.codex/skills
git clone https://github.com/couragec/llm-intern-skill.git ~/.codex/skills/llm-intern-skill
The repository you are reading is under a different owner and has a different name. The clone URL names another account and a hyphenated name, and the destination directory uses that same other name.
The star history link near the bottom of the page points at the same other repository, which suggests the page was written when the project lived there and the two links were never updated. That is a small thing to spot and a large thing to get wrong: following the instructions gives you a copy whose contents you have not read, at a path that does not match the project name you think you installed.
The other two quick-start methods do not have this problem, because neither one installs anything. One pastes a resume and a job description into a conversation. The other names a materials folder in a working directory. So the project is fully usable without ever touching the install path, which is the practical mitigation.
Five states for every claim and eleven numbered outputs
The vocabulary of the skill is small and it is the whole point.
Every claim is placed in one of five states: it can be written, it can be written with caution, it can be written after evidence is added, it cannot be written, or it cannot be judged. That is a finer partition than a pass and fail, and the middle state is where the interesting work happens.
The full pipeline takes a raw resume, a materials folder, and a target job description and runs through eleven stages: resume polish, job description matching, a truth boundary, an evidence contract, a targeted resume, interview drilling, answer cards, an evidence upgrade plan, project scouting, and a LaTeX draft.
The full mode writes eleven numbered files into an output directory, one per stage, from a job description analysis through a materials audit and a truth boundary to a final pack. Naming them rather than merging them means you can read the audit before the resume, which is the order that makes the rest trustworthy.
The lighter resume-polish mode produces six things instead: a verdict, a before and after, a line-by-line diagnosis, the polished section, an optional English version, and a list of evidence upgrades.
The flagship example answers with a risky fit
The demonstration case picks a deliberately hard job description and shows the skill refusing to claim a match.
The example is a research internship on a large language model team's search, ranking, and document understanding team. The input materials are explicitly weak to middling. The chain that follows is a strong job description plus thin materials, arriving at not asserting a strong fit, finding the evidence that can be written, downgrading the dangerous expressions, producing a conservative submittable resume, generating the questions an interviewer would ask, and finishing with an evidence plan at one day, three days, and one week.
Three files are published so you can read the whole chain rather than the summary: the target job description, the candidate materials, and the final output pack, plus a rendered resume PDF.
The verdict line is the part worth quoting. It reads as a risky fit, with the reason given as having retrieval work and a small search demo but lacking ranking metrics, strong algorithm internship evidence, and document understanding experiments. The fastest upgrade named is concrete: turn the small search demo into a comparison of three retrieval strategies with two named ranking metrics and a bad-case analysis.
A tool that can return an unfavourable verdict and still hand you a resume is more useful than one that always says yes.
A project recommendation carries seven fields and one rule
When the materials are too thin, the skill's advice is to build something, and the shape of that advice is prescribed.
The suggested project types are named: a small language model built from scratch in the style of a known minimal project, an evaluation project for retrieval and citation accuracy, a search and reranking baseline, an agent tool-calling workflow, and an inference, serving, or quantisation project.
Every recommendation has to carry seven fields. Why it fits. Why not, including the risk. The minimum path to getting it running. What to modify. What evidence to collect. The claim you can safely make on a resume once it is done. And the questions an interviewer would ask about it.
The last two are what separate this from a list of links. A project recommendation that ends at a clone command has not produced evidence, and the skill says so in a boundary statement: learning an open-source project cannot be packaged directly as work experience. Only after genuinely reproducing it, understanding it, modifying it, and recording evidence can it be written up as a personal project.
That boundary is the ethical core of the project, and it is stated in the same place as the feature list rather than buried.
The default template keeps its fonts out of the repository
The LaTeX export uses a third-party resume template, and the setup notes are specific about what was kept and what was not.
The default is the Chinese-language version of a well-known elegant resume template, vendored under a templates directory with a name that includes the template's author and a Chinese locale tag.
Both the Overleaf listing and the upstream repository are credited, and two instructions follow. The upstream attribution and licence are retained. And the large CJK fonts are kept locally but not committed to the repository.
That last decision has a cost and the project accepts it deliberately. A clone of this repository will not compile the exported template without you supplying the fonts first, which makes the export path less reproducible than it looks. The alternative, committing multi-megabyte font files, is the kind of thing that quietly breaks forks and inflates every clone.
The technical details are otherwise minimal and correct: the Chinese entry point is a single named file, and the compilation route is a specific engine rather than a generic one, which is what a CJK document with custom fonts needs.
Two reference directories and an evals folder the page never mentions
The repository layout contains three things the documentation does not explain.
At the top level there is a skill definition file, an agents directory, a documentation directory, a templates directory, and two directories whose names both mean references. One is called references and the other is called skill-references.
Two directories with the same meaning and different names is either a deliberate split between material for the person using the skill and material for the skill itself, or a rename that was applied to one and not the other. Nothing in the visible documentation says which.
The third unexplained directory is the one that matters most for assessing the project. An evals directory implies a way of scoring the skill's own output, and the page never mentions it. For a tool whose entire value proposition is that it grades things, an internal harness that grades the grader would be the most reassuring artefact in the repository, and it is the one a reader has to go and find.
The examples directory, by contrast, is thoroughly documented: eleven named cases covering before-and-after polish, a downgrade of prompt-only work, two project scouting cases, a weak-metrics adapter experiment, a post-training case, the flagship seed example, and the template demo.
The default readme is Chinese and eleven roles are checked
Two smaller details are worth recording because both affect how you read the project.
The language convention is inverted from what most repositories do. The default readme is the Chinese one and the English version carries a suffix, which is why the navigation bar offers the unsuffixed file and marks the other as current.
The second is the role checklist, which is the most reusable thing in the documentation and the part a user outside China would benefit from most. Eleven directions are listed, each with the specific things the skill checks for that discipline.
Retrieval and knowledge base work is checked for chunking, retrieval, reranking, citation, evaluation, refusal behaviour, and permissions. Agent and tool use is checked for schema design, argument validation, tracing, retries, state, and human review. Reinforcement learning is checked for trajectories, environment, reward and verifier design, two named policy optimisation methods, and task success rate. Post-training is checked for supervised and preference methods, reward models, preference data, and evaluation. Pretraining is checked for the data pipeline, tokenisation, training configuration, loss, distribution, and contamination checks. Search and ranking is checked for query-document pairs, recall, coarse ranking, reranking, two named ranking metrics, and document quality.
Those are the questions an interviewer actually asks in those roles, written down as a checklist. The lists are short, which means a reader can tell which items on their own resume the skill would probe.
Editorial conclusion
Use this skill if your problem is that a resume reads as thin rather than as false, because its whole contribution is deciding which lines survive contact with your materials folder. Check four things first. Where you actually install it from, since the documented clone command names a different repository than the one you are reading. Whether your target role is one of the eleven it has a checklist for, since the checks are per discipline and generic ones would be weaker. Whether you are willing to hand over a materials folder including code, notes, papers, and logs, since the audit step is what makes the rest work. And whether you can compile the exported template yourself, since its fonts are deliberately not in the repository.
Frequently asked questions
What does LLMInternSkill do with a resume?
It polishes wording, grades every claim against your materials, downgrades anything the evidence does not support, tailors a version to a target job description, generates interviewer-style follow-up questions with dangerous, adequate, and strong answers, and produces an evidence upgrade plan and a LaTeX resume draft.
How do I install LLMInternSkill as a Codex Skill?
The README's third method clones a repository under a different account and name into a skills directory under your home Codex folder, then restarts Codex. Note that the clone command in the documentation does not point at the repository hosting this page, so check the URL before running it.
What is the materials folder LLMInternSkill expects?
A directory containing the target job description as a text file, the resume, and subfolders for projects, code, notes, papers, awards, and anything else. The audit step reads those folders, which is what allows claims to be graded against real evidence rather than against the resume's own wording.
Can LLMInternSkill turn an open-source project into resume experience?
Not directly. The stated boundary is that studying an open-source project cannot be packaged as work experience. Only after genuinely reproducing it, understanding it, modifying it, and recording evidence can it be written up as a personal project or open-source practice.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/wanyichen06-llminternskill)Star history chart for your README
[](https://hysenlabs.com/projects/wanyichen06-llminternskill)Was this useful?