Browsertrix Crawler runs a real browser in one container, and its image bakes in a VNC password you can read in the Dockerfile
Run a high-fidelity browser-based web archiving crawler in a single Docker container.
At a glance
- What is it?
- Browsertrix Crawler drives one or more Brave windows through Puppeteer and captures everything over the Chrome DevTools Protocol, packaged as a single Docker container. The crawl logic is the interesting part; the deployment defaults are the part to read twice, because the image exports three ports, sets a VNC password as a build-time environment variable, and the bundled Compose file adds NET_ADMIN and SYS_ADMIN.
- Who is it for?
- Browsertrix Crawler is the right tool when you need archival-grade capture that a plain HTTP fetcher cannot give you, because it drives a real browser and writes WARC and WACZ through a mature dependency stack. It is a poor fit to expose as-is, because the VNC password is a literal in the image and the bundled Compose file asks for two Linux capabilities.
- Can I use it commercially?
- Yes, with strict conditions. AGPL-3.0 is a network copyleft licence: if people use a modified version over a network, for example as a hosted service, you must offer them its source code under the same licence.
- Is it still maintained?
- Yes. The repository received new commits within the last day.
- What is it written in?
- Mainly TypeScript, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 13, 2026, and from our analysis. They are not legal advice.
Star history
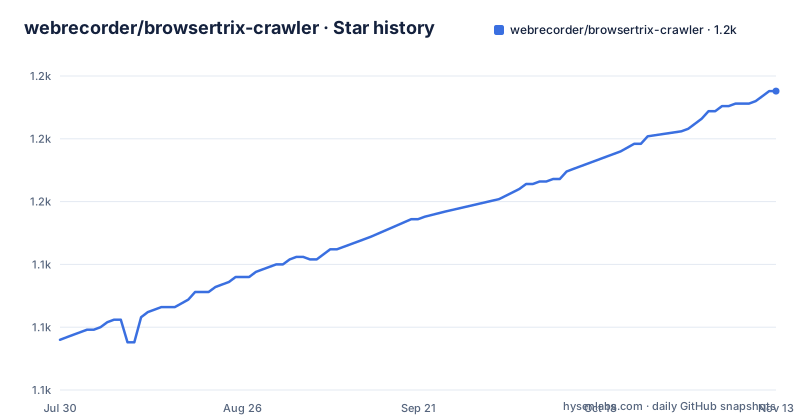
- webrecorder/browsertrix-crawler1,194 ★ · +99
| Repository | 2026-07-30 | 2026-11-13 |
|---|---|---|
| webrecorder/browsertrix-crawler | 1.1k | 1.2k |
99 Stars in the last 106 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The image exports 6080 and sets a VNC password to a literal
Three ports are exposed in the Dockerfile: 9222, 9223, and 6080. The first two are the DevTools endpoints the crawler needs. The third is a VNC viewer, which matches `@novnc/novnc` sitting in the runtime dependencies at a pinned 1.7.0, and it is guarded by a single environment variable:
VNC_PASS=vncpassw0rd!That is the default value in the image, not a placeholder the build replaces, so anyone who starts the container and publishes 6080 is serving a live desktop session behind a password that is written in a public Dockerfile. One detail worth knowing about the same block: the variable is called `BROWSER_BIN=google-chrome` even though the browser in this project is Brave, which is the kind of inherited naming that matters if you ever go looking for the binary by that name. The container also sets a fixed window geometry of 1360x1020x16, points OpenSSL at `/app/openssl.conf`, and sets `DETACHED_CHILD_PROC=1`.
The other two variables in that block are the ones you would change first. `BROWSER_VERSION` and `GEOMETRY` are build and runtime inputs, and the geometry value is what determines the screenshot size of everything you archive.
The bundled Compose file asks for two Linux capabilities
The whole compose file is seventeen lines, and the middle of it is the part to think about:
    cap_add:
      - NET_ADMIN
      - SYS_ADMIN

    shm_size: 1gb
NET_ADMIN and SYS_ADMIN are broad container capabilities, granted so a browser sandbox and network interception have the room they expect, and they are the reason a crawl container is not something to run on a shared host without thinking. The one gigabyte of shared memory is the other operational fact: a headless Chrome that has not been given a large `/dev/shm` tends to fall over on anything but a trivial page, and the classic fix is exactly this line. Storage is a single bind mount, `./crawls:/crawls`, so your captures land on the host with no volume driver involved. The service declares both an image and a build context, and the image reference is `${REGISTRY}webrecorder/browsertrix-crawler:latest`, so the registry prefix has to be set in the environment even for a local build.
The browser version is a base image, not a dependency
Nothing in the JavaScript dependency list downloads a browser. The crawler depends on `puppeteer-core`, which drives a browser you already have rather than bundling one, and the browser comes from the image instead. Two build arguments arrange that:
ARG BROWSER_VERSION=1.96.60
ARG BROWSER_IMAGE_BASE=webrecorder/browsertrix-browser-base:brave-${BROWSER_VERSION}
So the pinned browser is Brave at 1.96.60, delivered through a separate base image, and upgrading the browser means publishing a new base image and changing the default, not bumping a package. That is a deliberate division: the crawler and the browser are versioned on separate schedules. The same header carries the size-versus-build-time trade. `MINIMIZE_IMAGE_SIZE=0` is the default, and setting it to 1 shrinks the image at the cost of a longer build; when it is left at 0 the dependency install and the TypeScript compile happen in earlier layers so that a source change does not invalidate them. An `ARG REBUILD` exists purely to force those layers to rebuild when you want them to.
The build pulls a third-party hosts file from a mutable URL
One build step exists to bake an ad blocklist into the image, and it is worth reading because it makes the build depend on somebody else's repository:
    curl -vs -o ad-hosts.txt https://raw.githubusercontent.com/StevenBlack/hosts/master/hosts && \
    cat ad-hosts.txt | grep '^0.0.0.0 '| awk '{ print $2; }' | grep -v '0.0.0.0' | jq --raw-input --slurp 'split("\n")' > /app/ad-hosts.json
It fetches the hosts file from a `master` branch, keeps the lines that block with `0.0.0.0`, drops the literal wildcard address, and uses `jq` to turn the remainder into a JSON array at `/app/ad-hosts.json`. Two consequences follow. The image is not reproducible, because the content of that file changes without any change here. And the build breaks outright if that URL or its format ever changes, since the step is not tolerant of a failed download. Nothing in the repository lists the resulting file size or the source date, so you cannot tell from the tag which blocklist a given image contains.
A TypeScript project with one Python dependency and yarn as its only runner
The Python surface is a single line:
wacz>=0.5.0Everything else is JavaScript, and there are about thirty runtime dependencies: the AWS SDK client and lib-storage for S3 upload, `@puppeteer/replay`, `@webrecorder/wabac` and `warcio` for the archive format, `browsertrix-behaviors` for the behaviour scripts, `sharp` for image work, `sax` for XML, `robots-parser`, `pixelmatch` with `pngjs`, `ioredis`, `p-queue`, `undici`, `fetch-socks` for SOCKS proxies, `js-levenshtein`, `iso-639-1`, `normalize-url`, `css-selector-parser`, `client-zip`, `uuid`, `ws`, and `yargs`. The package is `"type": "module"` and the project is a yarn workspace with a committed `yarn.lock`; every documented command goes through yarn. Tests run under Jest and need the flag to work at all:
"test": "yarn node --experimental-vm-modules $(yarn bin jest --bail 1)"One oddity: `husky` is in the runtime dependency list rather than the development one, wired in by a `prepare` script that runs `husky install`, so the git-hook installer ships to anyone who installs the package.
A dependency entry is named tsc, which is not the compiler
The runtime dependency list includes an entry called `tsc` at `^2.0.4`. That name belongs to a package on the public registry and is not the TypeScript compiler, and it sits in the same list as `puppeteer-core`, `sharp`, and `warcio`, none of which are ambiguous. It also collides with the script the same file defines, `"tsc": "tsc"`, which is the one the Dockerfile calls during the image build. The actual compiler arrives as a development dependency, so a production install of this package pulls a package called tsc and gets no compiler at all, which is fine and probably intentional, but it is the kind of line that costs an afternoon when you are reading a dependency audit. The same file also pins `@novnc/novnc` to an exact 1.7.0 while everything around it uses a caret range, so the VNC client is the one component that will not move on its own.
The README credits three organisations and the docs live off the repository
The project describes its own lineage in a paragraph rather than a changelog. Initial support for the 0.x version came from Kiwix, the initial functionality was developed to support the zimit project in a collaboration between Webrecorder and Kiwix, and this codebase was then split off from Zimit into a core component of Webrecorder. Additional support, including development of the 0.4.x version, came from Portico. That history explains the version line in the title, Browsertrix Crawler 1.x, and the release names still carrying the Browsertrix Crawler prefix. For anything beyond that paragraph, the documentation is hosted rather than in the tree: the crawler docs live at crawler.docs.browsertrix.com, and building them locally is described on a docs page inside the repository. The tree itself is mostly machinery: `.eslintrc.cjs` alongside `.prettierignore`, a `jest.config.js` with a `test-setup.js`, a `docker-entrypoint.sh`, a `config/` directory, an `html/` directory for the replay side, CHANGES.md, and both LICENSE and NOTICE for the AGPL terms. The last commit landed on 2026-09-22, with v1.15.0 following on 2026-10-02 after two 1.15.0 betas.
Editorial conclusion
Browsertrix Crawler is the right tool when you need archival-grade capture that a plain HTTP fetcher cannot give you, because it drives a real browser and writes WARC and WACZ through a mature dependency stack. It is a poor fit to expose as-is, because the VNC password is a literal in the image and the bundled Compose file asks for two Linux capabilities. Before deploying, override the VNC password and keep port 6080 off anything but loopback, decide whether your host can grant those capabilities at all, and if you need a different browser version, publish the matching base image rather than expecting a dependency bump to move it.
Frequently asked questions
What is Browsertrix Crawler and how does it capture pages?
It is a standalone browser-based high-fidelity crawling system designed to run in a single Docker container. It uses Puppeteer to control one or more Brave Browser windows in parallel, and captures the data through the Chrome DevTools Protocol inside the browser rather than by fetching HTML over HTTP, which is what lets it archive interactive and script-driven pages.
Does the Browsertrix Crawler Docker image expose a remote desktop?
It exposes three ports, 9222, 9223, and 6080, and the third is a noVNC viewer, which is why `@novnc/novnc` is a runtime dependency. The VNC password is set as an environment variable whose default value is written in the Dockerfile, so it must be overridden and 6080 should not be published on a public interface.
What capabilities does the bundled docker-compose.yml request?
It adds NET_ADMIN and SYS_ADMIN, sets `shm_size: 1gb`, mounts `./crawls` at `/crawls`, and declares both an image and a local build context. The image reference is `${REGISTRY}webrecorder/browsertrix-crawler:latest`, so the registry prefix must be set in the environment.
Which browser does Browsertrix Crawler use, and how do I change the version?
It uses Brave, at version 1.96.60 by default, delivered through a separate base image referenced by the build arguments `BROWSER_VERSION` and `BROWSER_IMAGE_BASE`. The JavaScript dependency list contains `puppeteer-core` rather than a full Puppeteer download, so no browser is fetched by npm and upgrading means publishing a new base image.
How do you run the Browsertrix Crawler tests?
With `yarn test`, which is `yarn node --experimental-vm-modules $(yarn bin jest --bail 1)`. The package is `"type": "module"`, so Jest needs the vm-modules flag to load the sources. The other scripts are `tsc` for the compiler, `format` and `format:fix` for prettier over `src/` and `tests/*.ts`, `lint` and `lint:fix` for eslint over the same paths, and `prepare` for `husky install`.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/webrecorder-browsertrix-crawler)Star history chart for your README
[](https://hysenlabs.com/projects/webrecorder-browsertrix-crawler)Was this useful?