MarkItDown: A Python converter that turns office files into LLM-ready Markdown
Convert files and office documents to Markdown with Python.
At a glance
- What is it?
- Microsoft's MarkItDown converts PDFs, Office documents, images, audio, and more into Markdown for LLM pipelines. This review covers its architecture, installation, plugins, and the trade-offs of using it for high-fidelity conversions.
- Who is it for?
- Adopt MarkItDown if your goal is to feed documents into LLM pipelines and you can tolerate imperfect layout fidelity. Avoid it if you need pixel-perfect or high-fidelity conversions for human readers.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 7 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 13, 2026, and from our analysis. They are not legal advice.
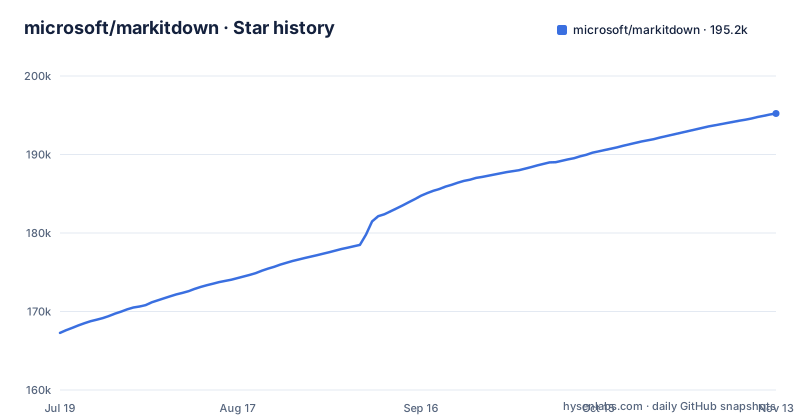
Star history
- microsoft/markitdown195,227 ★ · +27,948
| Repository | 2026-07-19 | 2026-11-13 |
|---|---|---|
| microsoft/markitdown | 167.3k | 195.2k |
27,948 Stars in the last 117 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
What MarkItDown solves and who should care
MarkItDown is a Python utility that converts a wide range of file formats into Markdown, with the explicit goal of feeding text to LLMs and text analysis pipelines. The README positions it as comparable to textract, but with a focus on preserving document structure like headings, lists, tables, and links. The primary audience is engineers building retrieval-augmented generation, summarization, or other LLM workflows that need to ingest PDFs, Office files, images, audio, and more. The project is not aimed at human-facing document conversion; the README states that output is 'often reasonably presentable' but 'meant to be consumed by text analysis tools.' If you need a clean, visually faithful Markdown rendering for a human to read, this tool may disappoint.
The conversion mechanism: format-specific converters and a unified API
MarkItDown works by dispatching each input file to a specific converter based on its type. The README lists support for PDF, PowerPoint, Word, Excel, images (EXIF metadata and OCR), audio (EXIF metadata and speech transcription), HTML, text-based formats (CSV, JSON, XML), ZIP files, YouTube URLs, and EPubs. The core API is simple: create a MarkItDown instance and call convert on a file path or stream. The README shows an example with an OpenAI client for the OCR plugin, but the base library can work without an LLM. The design is modular: each format has its own converter, and optional dependencies activate them. This means you can install only the converters you need, keeping the dependency footprint small. The plugin system extends this further, allowing third-party converters to be added without modifying the core.
Installation and first run: real commands from the README
MarkItDown requires Python 3.10 through 3.14. The README recommends a virtual environment. The standard installation is `pip install 'markitdown[all]'`, which pulls in every optional dependency. For more control, you can install subsets like `pip install 'markitdown[pdf, docx, pptx]'`. The command-line interface is straightforward: `markitdown path-to-file.pdf > document.md` writes to stdout, or `markitdown path-to-file.pdf -o document.md` writes to a file. You can also pipe content: `cat path-to-file.pdf | markitdown`. The README also shows how to install from source with `git clone` and `pip install -e 'packages/markitdown[all]'`. For Python users, the library API is just as simple: `from markitdown import MarkItDown; md = MarkItDown(); result = md.convert('file.pdf'); print(result.markdown)`.
Plugins: optional OCR and LLM-based image understanding
Plugins are disabled by default. To list installed plugins, run `markitdown --list-plugins`. To enable them, pass `--use-plugins` on the command line or `enable_plugins=True` in the Python API. The README highlights the `markitdown-ocr` plugin, which adds OCR to PDF, DOCX, PPTX, and XLSX converters by extracting text from embedded images using an LLM Vision model. It uses the same `llm_client` and `llm_model` pattern as the built-in image description. If no `llm_client` is provided, the plugin loads but silently skips OCR, falling back to the built-in converter. This is a notable design choice: OCR is not a deterministic local operation but goes through an LLM Vision call via an OpenAI-compatible client, which has cost and latency implications. The plugin approach keeps the core library lean, but it means you need to wire in an external LLM to get OCR, which may not suit offline or privacy-sensitive workflows.
Azure Content Understanding: a cloud extension for higher fidelity
For higher-quality conversion, MarkItDown offers an integration with Azure Content Understanding. Install it with `pip install 'markitdown[az-content-understanding]'`. This extension provides structured field extraction (serialized as YAML front matter), multi-modal support for documents, images, audio, and video, and configurable analyzers. The README explicitly says Content Understanding is the only option for video and the higher-quality cloud option for audio. It also enables domain-specific field extraction, such as invoice amounts or contract clauses, which neither built-in converters nor Document Intelligence expose. This is a significant trade-off: you trade local processing for a cloud dependency, and you pay for the service. The README positions it as the way to go when you need structured output or scanned PDF handling, but it is not part of the default install.
Limitations and wrong-tool cases
The most obvious limitation is fidelity. The README is candid: output is meant for text analysis, not human consumption. Complex tables, scanned PDFs, and intricate layouts may lose structure. Built-in converters give images EXIF metadata and OCR, and audio only basic transcription. For video, there is no built-in support at all; you must use Azure Content Understanding. Another limitation is the security note: MarkItDown performs I/O with the privileges of the current process, like `open()` or `requests.get()`. In untrusted environments, this is a risk. The README advises sanitizing inputs and calling the narrowest convert function, such as `convert_stream()` or `convert_local()`. Also, the plugin system is disabled by default, so users who expect OCR out of the box will be surprised.
Alternatives: textract and cloud document intelligence
The README names textract as the closest comparable tool. textract is a Python library that extracts text from many file types, but it focuses on raw text extraction rather than preserving Markdown structure. MarkItDown's advantage is that it outputs structured Markdown with headings, lists, and tables, which is more useful for LLMs that natively understand Markdown. A different alternative is Azure Document Intelligence, which MarkItDown also integrates with via the `[az-doc-intel]` optional dependency. Content Understanding, as described above, is a higher-level cloud service that does produce structured Markdown-like output with YAML front matter. The choice between local MarkItDown and a cloud service depends on whether you need offline processing, cost control, or the highest possible extraction quality.
Maintenance, licensing, and upgrade considerations
The project is under the MIT license, which is permissive for both commercial and personal use. The repository is actively maintained, with recent releases in 2026 (v0.1.9, v0.1.8, v0.1.8b2). The version numbers are still below 1.0, so API changes are possible. You should pin your dependency and test upgrades. The optional dependencies mean that upgrading the core package may not upgrade the format-specific converters unless you reinstall with the same extras. The OCR plugin is a separate package (`markitdown-ocr`), so you need to manage that independently. Keep an eye on the release notes when new releases appear.
Editorial conclusion
Adopt MarkItDown if your goal is to feed documents into LLM pipelines and you can tolerate imperfect layout fidelity. Avoid it if you need pixel-perfect or high-fidelity conversions for human readers. Before adopting, verify that your target formats are covered by the built-in converters or an available plugin, and test the output on a representative sample of your documents. Also review the security note about running conversions on untrusted inputs, and decide whether you need the Azure Content Understanding extension for higher-quality extraction.
Frequently asked questions
What is MarkItDown used for?
It is a lightweight Python utility that converts files to Markdown for use with LLMs and related text analysis pipelines, preserving structure such as headings, lists, tables and links. It handles PDF, PowerPoint, Word, Excel, images, audio, HTML, CSV, JSON, XML, ZIP files, YouTube URLs and EPub, and the documentation says the output may not be the best option for high fidelity conversion for human consumption.
how to install markitdown
Python 3.10 through 3.14 is required and a virtual environment is recommended. Install the whole thing with `pip install 'markitdown[all]'`, or a subset such as `pip install 'markitdown[pdf, docx, pptx]'`, and use uv pip install rather than pip install when you created the environment with uv.
how to use markitdown in python
Import MarkItDown from the markitdown package, pass any llm_client and llm_model you want for image descriptions, then call convert() and read result.markdown. In untrusted environments the documentation asks for the narrowest convert_* function, naming convert_stream() and convert_local().
how to use markitdown
From a shell, redirect the output with `markitdown path-to-file.pdf > document.md`, pass `-o` to write the file directly, or pipe content in with `cat path-to-file.pdf | markitdown`. Third-party plugins are disabled by default and are turned on per run with the --use-plugins flag after checking what is present with --list-plugins.
Is MarkItDown free?
The code is published under the MIT license. Two optional extras, az-doc-intel and az-content-understanding, integrate with Microsoft Azure services instead of running locally, and the content understanding extra is the only option for video and for structured field extraction.
Official sources
Where this project is recommended
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/microsoft-markitdown)
[](https://hysenlabs.com/projects/microsoft-markitdown)Star history chart for your README
[](https://hysenlabs.com/projects/microsoft-markitdown)Was this useful?