tick: Python 3 statistical learning where the optimization core is the library and the examples are the documentation
Module for statistical learning, with a particular emphasis on time-dependent modelling
At a glance
- What is it?
- tick is a Python 3 module from the Datascience initiative at Ecole Polytechnique, built around an optimization core of model classes, solvers and proximal operators, with point process inference on top. It installs C++ extensions through scikit-build-core, needs Python 3.11 or newer according to its manifest, and ships twenty-five examples named for the modelling questions they answer.
- Who is it for?
- tick earns a place on a time-series or point-process problem where you need regularized fitting rather than a prediction API, and the deployment history argues for it harder than the feature list does, since the same Hawkes code is credited with pharmacovigilance weak-signal detection on French health records, order book work in finance and information-spread analysis on 2017 election tweets. The costs of choosing it are concrete.
- Can I use it commercially?
- Yes. BSD-3-Clause is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 5 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
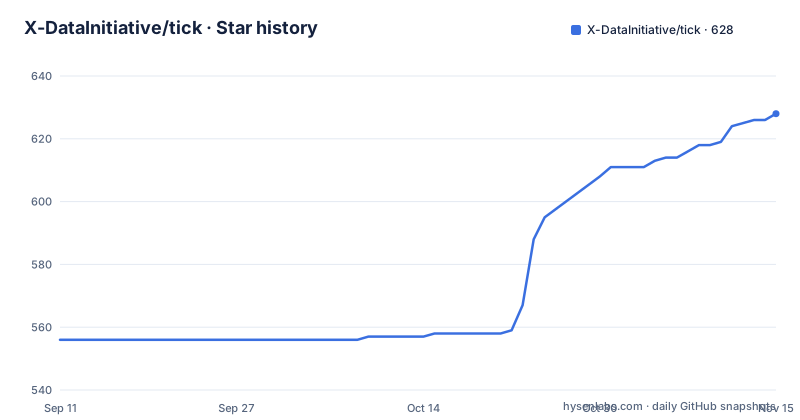
- X-DataInitiative/tick628 ★ · +72
| Repository | 2026-09-11 | 2026-11-15 |
|---|---|---|
| X-DataInitiative/tick | 556 | 628 |
72 Stars in the last 65 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The README says Python 3.5 and the manifest says 3.11
Start with the contradiction, because it decides whether your install works. The setup section says tick currently works on Linux and macOS, that Windows is experimental, and that it requires Python 3.5 or newer. The packaging metadata in the same repository says requires-python is greater than or equal to 3.11, and the classifiers enumerate Python 3.11, 3.12, 3.13 and 3.14 only. The wheel configuration builds exactly those four interpreter versions, and it skips musllinux targets, 32-bit Windows and 32-bit manylinux, which leaves macOS, 64-bit Windows and 64-bit Linux as the shipped platforms. So the prose is describing an era when the project supported a much older interpreter, while the build system has moved on by six minor versions. Two things follow. Trust the manifest, not the setup paragraph, when you decide whether tick will install. And notice that Windows being called experimental does not mean it is unbuilt, because a Windows classifier and a Windows wheel target both exist; experimental describes how much testing it has had, not whether a wheel exists. The same gap shows in the dependency pins, which we come back to below.
pip install tick compiles C++ extensions, so the wait is expected
The install command is short, which is misleading. tick is available through pip as a single package, and the documentation warns that installation may take a few minutes to build and link C++ extensions, with the option of adding tick to PYTHONPATH afterwards if the import does not resolve. That build step is not incidental; it is the reason several directories exist in the repository. The build system requires scikit-build-core, pybind11 and numpy, and the backend is scikit_build_core.build, which means a CMakeLists.txt sits at the top level and the sources are split into lib/, python/ and tick/, with tools/ and sh/ alongside them. If you install from source rather than from a wheel you also need the INSTALL document, which the README points at rather than restating. For most people the practical consequence is that tick belongs in an environment where compiling is acceptable, or on a platform where the wheel set covers your interpreter, and it does not belong in a locked-down image where pip cannot build. The verification step is an import, which is the cheapest possible check and worth running before you write any code against it.
The optimization core is the library, not the Hawkes front end
The most useful way to read tick is as two libraries stacked. The core is an optimization module providing model computational classes, solvers and proximal operators for regularization. Everything else sits on that: generalized linear models, and the point process machinery that gets the attention because it is the distinctive part. What the README says a user can do with the inference and simulation tools runs to three lines. Linear, logistic or Poisson regression, which is the part that overlaps with scikit-learn and is why one of the examples is named for a direct comparison. Simulation of point Hawkes processes with standard or exotic kernels. And inference of Hawkes models under a range of assumptions about the kernels, including exponential kernels or sums of exponential kernels, a linear combination of basis kernels, and sparse interactions. That last list is the real content, because each assumption is a different estimator with different bias and variance, and picking the wrong one is the usual way people get a bad fit out of a Hawkes model. The examples directory carries a file for each of those variants, which makes the assumption list testable rather than abstract.
Twenty-five examples, and the filenames are the API map
The examples directory holds twenty-five scripts and a README, and the filenames are the closest thing tick has to an API map. For Hawkes inference there are scripts for expectation maximisation, for a linear combination of basis kernels, for Gaussian kernels, for a four-component version, for cumulants matching, for the conditional law, for the estimated intensity, for a time-varying function simulation, for a varying baseline with a matching simulation script, and one wired to finance data. For the generalized linear models there is logistic regression on the adult dataset, a direct comparison against scikit-learn, Poisson regression, inhomogeneous Poisson, robust linear regression, two-dimensional linear regression, a convergence plot, and simulation scripts for a linear model and for Cox regression. Three of the filenames are about the optimization core rather than a model: a proximal example, a low-precision learner, and a convergence plot for the stochastic convex solver in its asynchronous variant. If your question is whether tick does what you need, the fastest answer is to find the script that matches your estimator and read it, because each one is small enough to be a worked reference for the corresponding call sequence.
requirements.txt carries no floors and pyproject.toml carries eight
There are two dependency declarations in the repository and they disagree about strictness. The manifest lists seven runtime dependencies with lower bounds: numpy at 2.0 or newer, scipy at 1.13, pandas at 2.2, dill at 0.3.8, scikit-learn at 1.5, packaging at 24.0 and matplotlib at 3.8. The standalone requirements file lists the same set of runtime packages with no version constraints at all, and adds numpydoc to the list, which is a documentation tool rather than something the library imports at runtime. That split matters in two directions. If you install with pip and let the resolver work from the manifest, you get the intended floors. If something in your build pins from requirements.txt instead, you lose the numpy 2 boundary, which for a project that compiles C++ extensions is exactly the kind of constraint you do not want to discover at build time. The optional groups are where the manifest is more careful still: a docs group pulling numpydoc, sphinx at 8.0 or newer, a bootstrap theme and statsmodels at 0.14, and a dev group with pytest, psutil, build, twine and ruff. Install the group you need rather than the union of both files.
Classified as alpha, with three patch releases inside three weeks
The project's own metadata is unusually candid about its maturity. The classifier reads Development Status 3 - Alpha, and the intended audience is declared as science and research alongside developers, with programming language covering both C++ and Python. The release history is three tags in quick succession: v0.8.0.0 published 2026-04-18, v0.8.0.1 two days later on 2026-04-20, and v0.8.0.2 on 2026-05-04, which is also the version in the manifest. So the 0.8 line is being patched rather than rewritten, and each patch release shipped inside three weeks. Against that, 86 open issues on 556 stars and 120 forks is a high issue count, which is what an alpha classification with an academic user base tends to produce. The last push is dated 2026-06-15. One more piece of history is visible in the file names: the readme badges still point at Travis and AppVeyor, and the tree contains a .travis.yml.off, so the continuous integration of that era has been switched off, and the tree keeps a .github/ directory alongside it. None of this makes the library unusable; it tells you to expect the conventions of research code rather than of a product.
Three industrial deployments argue for it harder than any benchmark
The strongest case for tick is a list of three named deployments, and none of them is a benchmark table. The first is a joint project with the French national social security body, working on a health-care database describing the medical care provided to most French citizens, where tick is used to detect weak signals in pharmacovigilance and quantify the impact of drug exposure on the occurrence of adverse events. Weak signals is the phrase that matters, because that is a problem of finding small but consistent effects in noisy event data, which is a point process question rather than a classification question. The second is high-frequency order book modelling in finance, aimed at understanding interactions between different event types, or between different assets, using the full time resolution of the original data. The third is the propagation of information in social media, using a dataset collected during the 2017 French presidential election campaign on Twitter to recover, for each topic, the network across which information spread inside the political sphere. Read together, they say the library has been used where self-exciting event structure is the model rather than a convenience, and there is a finance-data example script in the repository to back the second claim.
The docs build from doc/ with make html and an extra you install first
Documentation is generated, hosted and buildable locally, and the local build has one prerequisite the README names. The documentation is built with Sphinx and can be compiled by running make html from inside the doc directory, which requires Sphinx to be installed first. The hosted documentation and the example gallery live at the x-datainitiative.github.io address, and the paper behind the library is on arXiv at 1707.03003, with a BibTeX entry supplied and a request that you cite it if you use tick in a scientific publication. To build the docs yourself you want the docs optional group rather than the base install, because it carries numpydoc, sphinx at 8.0 or newer, a bootstrap theme and statsmodels at 0.14, and the last of those is there for the tutorials rather than for the library itself. The repository also keeps CONTRIBUTORS.md and CONTRIBUTING.md, and there is an ISSUES.md alongside INSTALL.md at the top level. A development channel exists on Gitter, and the project's own guidance for bug reports is to be as precise as possible in the description so contributors can act on it efficiently.
Editorial conclusion
tick earns a place on a time-series or point-process problem where you need regularized fitting rather than a prediction API, and the deployment history argues for it harder than the feature list does, since the same Hawkes code is credited with pharmacovigilance weak-signal detection on French health records, order book work in finance and information-spread analysis on 2017 election tweets. The costs of choosing it are concrete. The build compiles and links C++ extensions, so an install takes minutes rather than seconds and a locked-down wheel-less environment will not get past it. The written requirements and the packaging metadata disagree about the Python floor, which means you have to trust the manifest rather than the prose. And the project classifies itself as alpha with 86 open issues, which is normal for research code and not what you want under a deadline. Before you commit, check three things: that a C++ toolchain is available where you install, that the Python version you have is one the wheels cover, and that the example closest to your problem actually runs, since the gallery filenames are the fastest way to judge fit.
Frequently asked questions
How do I install the tick library?
tick is available from pip with a single pip install tick command, and installation may take a few minutes because it builds and links C++ extensions through scikit-build-core and pybind11. If the import does not resolve afterwards, the documented fallback is adding tick to your PYTHONPATH, and the cheapest verification is importing tick in Python 3.
Which Python versions does tick support?
The setup section of the README says Python 3.5 or newer, but the packaging metadata is the authority: requires-python is 3.11 or newer, the classifiers list Python 3.11 through 3.14, and the wheel configuration builds cp311 through cp314. Trust the manifest rather than the prose when you check compatibility.
Does tick work on Windows?
The README calls Windows experimental, which describes the amount of testing rather than the availability of a build. The classifiers include Microsoft Windows, and the wheel configuration skips only musllinux targets, 32-bit Windows and 32-bit manylinux, so 64-bit Windows is a shipped target.
What kinds of models does tick fit?
Linear, logistic and Poisson regression, simulation of point Hawkes processes with standard or exotic kernels, and inference of Hawkes models under several kernel assumptions: exponential kernels or sums of exponential kernels, a linear combination of basis kernels, and sparse interactions. Underneath all of it sits a generic optimization toolbox with model classes, solvers and proximal operators.
Is tick suitable for production work?
The project classifies itself as Development Status 3 - Alpha, with 86 open issues on 556 stars. The release record shows three patch tags in the 0.8 line, v0.8.0.0 on 2026-04-18, v0.8.0.1 on 2026-04-20 and v0.8.0.2 on 2026-05-04, and the last push is dated 2026-06-15.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/x-datainitiative-tick)Star history chart for your README
[](https://hysenlabs.com/projects/x-datainitiative-tick)Was this useful?