Xberg: one Rust core, opt-in features, and a generated README
Polyglot document intelligence with a Rust core: extract text, metadata, images, tables, and structured data from 106 formats across 140 file extensions, plus code intelligence for 371 languages. Fifteen bindings, with CLI, REST API, and MCP server.
At a glance
- What is it?
- Xberg is a document intelligence engine with a Rust core, fifteen language bindings, a CLI, a REST API and an MCP server. The interesting decisions sit in the Cargo features, the benchmark harness that pins its competitors, and a README the project generates itself.
- Who is it for?
- Xberg fits a team that wants one engine for format detection, OCR, tables and extraction instead of a stitched pipeline, and that is comfortable turning Cargo features on for what it needs. It does not fit a team that expects every feature in a from-source build, since a from-source build enables only the features you select.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository received new commits within the last day.
- What is it written in?
- Mainly Rust, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
Star history
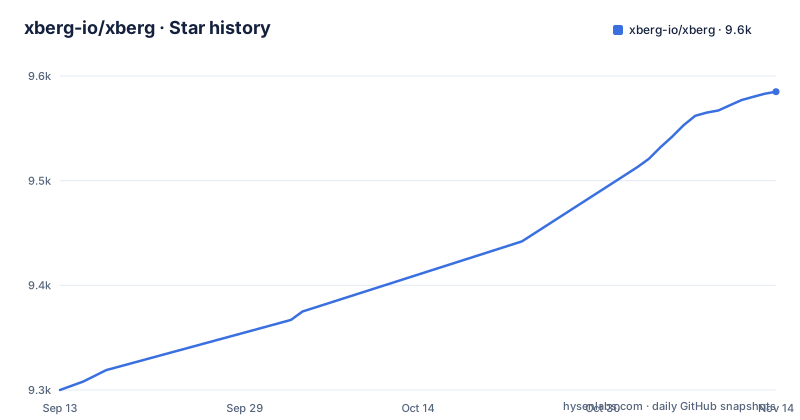
- xberg-io/xberg9,585 ★ · +285
| Repository | 2026-09-13 | 2026-11-14 |
|---|---|---|
| xberg-io/xberg | 9.3k | 9.6k |
285 Stars in the last 62 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Cargo features decide whether your input is readable at all
The capability table is honest about its gates. URL fetching and crawling sit behind `url-ingestion`, speech-to-text from MP3, M4A, WAV, WebM and MP4 sits behind `transcription`, cross-encoder reranking behind `reranker`, and the layout models behind layout and ORT. Prebuilt language packages and the Docker image bundle the common set. A build from source enables only what you select.
That sentence is the one to read twice. If you add the crate and immediately point it at an `http(s)` URL or an audio file, the capability you wanted is not a configuration mistake, it is a feature you did not compile. The OCR backends (Tesseract, PaddleOCR, Candle or VLM) come with fallback chains, confidence scores and language auto-detection.
cargo add xbergExpect the artifact you get from a source build to be narrower than the table describes.
The workspace builds two crates by default and needs Rust 1.92
The Cargo workspace lists nineteen members, from the core `crates/xberg` through binding crates such as `xberg-py`, `xberg-node`, `xberg-wasm`, `xberg-jni`, `xberg-ffi` and `xberg-paddle-ocr`, plus a benchmark harness. Only two of them are default members:
default-members = ["crates/xberg", "crates/xberg-cli"]The elixir and ruby native paths are excluded from the workspace entirely, which tells you those bindings build through their own package managers rather than through `cargo build` at the root.
The toolchain floor is the harder constraint:
[workspace.package]
version = "1.4.0"
edition = "2024"
rust-version = "1.99"
A contributor on an older pinned toolchain gets nothing from the root build. The root `pyproject.toml` is a private development project that names `maturin` as its build backend; Python users install the published package with `pip install xberg`.
Recursive archive extraction runs against three caps
Archives are traversed recursively, so a `.zip`, `.tar`, `.gz` or `.7z` inside another archive is unpacked rather than listed. That is what makes document-in-document corpora work with one call, and unpacking archives from an outside source is the step that needs the guards below.
The guards are named in the capability table: a zip-bomb limit, a compression-ratio limit, and a nesting-depth limit. The capability table does not give their values, so check the docs before sizing a nightly job; a corpus of legitimately nested deliverables could hit the depth cap.
The rest of the pipeline has the controls you would expect. Per-file timeouts, parallel batch, and content-hash caching mean a re-run over an unchanged corpus skips work, which is the difference between a scheduled job you keep and one you stop trusting.
Fifteen bindings, one install command each
Installation is one command per ecosystem, and the bindings cover Rust, Python, Node.js, Go, Java, C#, Ruby, PHP, Elixir, Dart, Swift, Zig, WASM, Kotlin and C FFI.
pip install xbergnpm install @xberg-io/xbergThe same family of packages exists on crates.io, Maven Central for `io.xberg/xberg` and `io.xberg/xberg-android`, NuGet as `XbergIo.Xberg`, Packagist as `xberg-io/xberg`, RubyGems, Hex and pub.dev, with a separate `@xberg-io/xberg-wasm` package for the browser path.
Where the work happens is a choice rather than an install detail. The engine runs as a library, as a CLI with 14 commands, as a REST API:
xberg serveor as an MCP server for an agent to call. Docker and Helm charts cover the server shapes, and a Kubernetes guide sits under the docs site. CPU is the default and no GPU is required.
The README is generated, so editing it by hand loses the change
The first lines of README.md are a warning and two commands:
<!-- To regenerate: alef readme -->
<!-- To verify freshness: alef verify -->
The file header says it is auto-generated and must not be edited. The repository carries the configuration for that generator alongside the rest of the tooling: `alef.toml`, `.alef-generation.toml`, `.alef-ownership.toml`, `.ai-rulez/` and `.agents/`. Documentation changes therefore go through alef, and `alef verify` is the freshness check a contributor runs rather than re-reading prose.
The generated text can also drift from what the code declares. The README headline counts 107 formats and 141 file extensions, while the repository description on GitHub counts 106 formats across 140 extensions. Both numbers are current in the repository, and a reader comparing them against a release announcement should ask which one they are reading before quoting either.
The Docling comparison is held together by an exact version pin
The benchmark harness lives in `pyproject.toml` as dependency groups, including one for Docling:
bench-docling = ["docling-jobkit==3.5.0", "easyocr>=1.7.2"]The comment above the Docling pin explains why 3.5.0 is described as a floor rather than a preference. Docling changed its default `pdf_backend` to `THREADED_DOCLING_PARSE`, jobkit 3.2.0's converter manager only matched `DOCLING_PARSE` and `PYPDFIUM2`, and every batch document raised `RuntimeError("Unexpected PDF backend type ...")`. The benchmark scored Docling 0 out of 14 and failed the run's minimum success rate.
Two things follow for anyone reading the comparison on the benchmarks page. The figures describe pinned versions, not current releases of the alternatives. And if that error reappears after a Docling upgrade, the comment tells you to compare jobkit's handled `PdfBackend` variants against the default Docling resolves to before suspecting the adapter. The relationship also runs the other way: Docling DocTags is one of Xberg's six output formats, so Xberg can emit into Docling's interchange format.
One benchmark cohort is excluded on aarch64
Platform coverage is a separate question from versions.
The repository keeps a `PLATFORM_SUPPORT.md` for its platform matrix.
For a reader choosing between this engine and one of the baselines, the useful question is not which number is higher. It is which cohorts each project actually runs on your hardware, because a missing wheel produces no row in the results at all.
unsafe_code is denied and third-party licences are tracked separately
The workspace lint configuration denies `unsafe_code` outright, and denies `print_stdout` and `print_stderr` in favour of `tracing` diagnostics on stderr, with the CLI opting back in locally where data output is the point. That is a deliberate choice for a native library that others link into their processes, and it means the core cannot quietly write into your host program's stdout.
Licensing is where a reader should slow down. The crate is MIT, but the engine pulls in OCR and machine learning stacks, Tesseract, PaddleOCR, Candle, ONNX, Whisper and layout models, each under its own terms. The repository ships `ATTRIBUTIONS.md`, `THIRD_PARTY_LICENSES.md` and a `deny.toml` for cargo-deny. The MIT label covers Xberg's own code and says nothing about the dependencies a build drags in, so check those files for the feature set you intend to compile before shipping a binary to a customer.
Editorial conclusion
Xberg fits a team that wants one engine for format detection, OCR, tables and extraction instead of a stitched pipeline, and that is comfortable turning Cargo features on for what it needs. It does not fit a team that expects every feature in a from-source build, since a from-source build enables only the features you select. Check three things before adopting: that `cargo add xberg` gives you the `url-ingestion` and `transcription` features your input actually needs, that your Rust toolchain is 1.99 or newer, and that the benchmark comparison you are quoting names the Docling version the harness requires rather than its latest release.
Frequently asked questions
Does Xberg handle URLs and audio out of the box?
Not in a from-source build. URL fetching and crawling require the `url-ingestion` Cargo feature and speech-to-text from MP3, M4A, WAV, WebM and MP4 requires `transcription`. Prebuilt language packages and the Docker image bundle the common set, while a build from source enables only what you select.
Which languages can I call Xberg from?
Fifteen bindings are published, covering Rust, Python, Node.js, Go, Java, C#, Ruby, PHP, Elixir, Dart, Swift, Zig, WASM, Kotlin and C FFI. Packages exist on crates.io, PyPI, npm, Maven Central, NuGet, Packagist, RubyGems, Hex and pub.dev.
How does Xberg compare with Docling?
The benchmark harness in pyproject.toml sets docling-jobkit 3.5.0 as a floor and adds EasyOCR, and the comment there records that jobkit 3.2.0 could not handle Docling's default PDF backend, which scored Docling 0 out of 14 and failed the run's minimum success rate. Xberg can also emit Docling DocTags as one of its six output formats.
What does Xberg need to extract text from a document?
Xberg runs on CPU by default and does not require a GPU, and it can be used as a library, a CLI with 14 commands, a REST API started with `xberg serve`, an MCP server, Docker or Helm. Batching is parallel, with per-file timeouts and content-hash caching.
What is the relationship between Xberg and Kreuzberg?
The README states that Xberg is the next iteration of Kreuzberg: the same document-intelligence engine, rebuilt and rebranded under a fresh v1 line. Kreuzberg v4 remains a separate LTS line at kreuzberg-dev/kreuzberg-v4-lts.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/xberg-io-xberg)Star history chart for your README
[](https://hysenlabs.com/projects/xberg-io-xberg)Was this useful?