WeClone turns a Telegram export into a LoRA twin, then binds it to Telegram, Discord or Slack
🚀 One-stop solution for creating your AI twin from chat history 💡 Fine-tune LLMs with your chat logs to capture your unique style, then bind to a chatbot to bring your digital self to life.
At a glance
- What is it?
- WeClone reads a Telegram Desktop JSON export, strips PII with Microsoft Presidio, fine-tunes Qwen2.5-VL with LoRA through LLaMA Factory, and serves the result as a chat bot. One importer exists, and the 7B model it defaults to is the one the project itself calls average.
- Who is it for?
- WeClone fits one narrow job well: turning a Telegram export into a bot that answers in your own register, with `settings.jsonc`, the Presidio pass and the deployment tables making that path concrete. Skip it if your chat history is mostly voice notes and links, or if you need macOS, since the main dependency group installs no torch there.
- Can I use it commercially?
- Yes, with strict conditions. AGPL-3.0 is a network copyleft licence: if people use a modified version over a network, for example as a hosted service, you must offer them its source code under the same licence.
- Is it still maintained?
- Yes. The repository last received commits 6 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
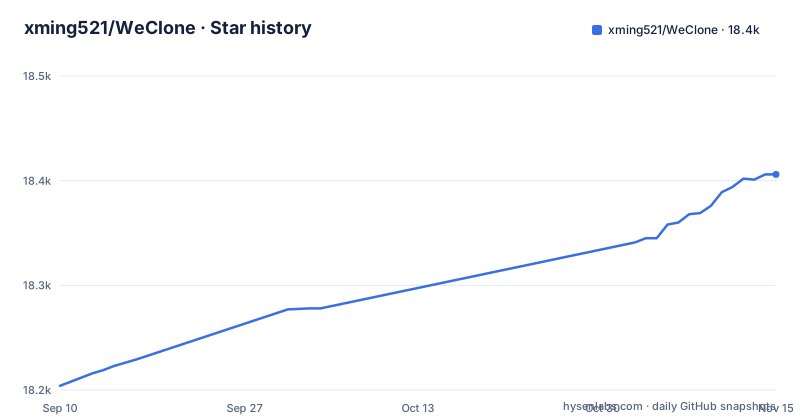
Star history
- xming521/WeClone18,406 ★ · +202
| Repository | 2026-09-10 | 2026-11-15 |
|---|---|---|
| xming521/WeClone | 18.2k | 18.4k |
202 Stars in the last 66 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
One chat partner per folder, and a my_id that has to be yours
Training starts from files Telegram Desktop already knows how to write. Open the chat, use the top right corner menu, choose Export chat history, set message types to Photos and format to JSON, and every export arrives as a `ChatExport_*` folder that belongs in `./dataset/telegram`, one folder per contact, gathered together in the same place. The repository root lists `weclone/`, `dataset/`, `ds_config.json`, `examples/`, `tests/` and a `WC-exp` entry.
Three configuration keys decide how those folders are read: `platform`, `include_type` and `language`. For Telegram you also set `telegram_args.my_id` to your own account ID, and the pipeline uses it to work out which half of every exchange is yours before anything is turned into a training example.
Group chats are marked as not recommended, and the reason is arithmetic rather than taste. A fine-tune imitates one speaker. Three people inside one export leave the model with no consistent voice to copy, so the export is the wrong shape for the job even when the parser reads it without complaint.
The uv venv, the settings.jsonc copy, and the CUDA check that prints a boolean
Setup is three commands once CUDA 12.6 or newer is in place. Clone the repository, create a 3.12 environment with uv, then install the main dependency group in editable mode:
git clone https://github.com/xming521/WeClone.git && cd WeClone
uv venv .venv --python=3.12
source .venv/bin/activate # windows .venv\Scripts\activate
uv pip install --group main -e .
Training and inference settings live in one file instead of a dotfile scattered around the tree, and you get it by copying a template. Later edits to `language`, `platform`, `include_type` or `telegram_args.my_id` all happen in `settings.jsonc`. A second template, `examples/mllm.template.jsonc`, sits beside the Telegram one for multimodal work.
Model weights are a separate step, and the suggested route is git lfs rather than a package index:
git lfs install
git clone https://huggingface.co/Qwen/Qwen2.5-VL-7B-Instruct models/Qwen2.5-VL-7B-Instruct
Torch is installed for Linux and Windows only, which makes the check the README offers a formality on a Mac rather than a test:
python -c "import torch; print('CUDA Available:', torch.cuda.is_available());"`uv pip install flash-attn --no-build-isolation` is the optional accelerator for training and inference.
16GB buys you a 7B LoRA, and the project rates that 7B as average
The default recipe is Qwen2.5-VL-7B-Instruct with LoRA for the SFT stage, and the memory table is where a plan meets a wall. Freeze, LoRA, GaLore, APOLLO and BAdam at 16-bit ask 16GB for a 7B model. QLoRA drops that to 10GB at 8-bit, 6GB at 4-bit and 4GB at 2-bit. A full pure_bf16 fine-tune asks 60GB, and the 32-bit row asks 120GB. Scale the same methods up and you get 32GB for 14B, 64GB for 30B and 160GB for 70B.
Alongside the table, a note calls the 7B result average, says models with 14B or more parameters tend to do better, and states that the project is still in a rapid iteration phase where current performance does not represent final results. So the configuration that fits a 16GB card is the one the project rates lowest, and the gap between a 16GB card and a 32GB card is the gap between the affordable run and the recommended one.
The same note puts the ceiling on the whole exercise: fine-tuning quality depends on the size, quantity and quality of the chat data, which means a thin export produces a thin twin no matter which card you own.
Presidio strips card numbers and IP addresses, and no step strips display names
Cleaning leans on Microsoft Presidio, and the default pass removes phone numbers, email addresses, credit card numbers, IP addresses, geographic location names, international bank account numbers, cryptocurrency wallet addresses, age information and generic ID numbers. Read that list closely. It enumerates formats, not people.
Presidio handles the shapes above, and a nickname is not one of them. The README adds that Presidio cannot guarantee 100% identification, which is why `settings.jsonc` provides a `blocked_words` list: words or phrases you add there are filtered, and by default the whole sentence containing them is removed. Names you want kept out of training data have to go on that list yourself. The `enable_thinking` switch, added in config version 0.3.02 to control offline cleaning, changes how hard the cleaning model thinks, not what the filter matches.
Because a Telegram export is plain JSON in a folder, the practical step is to open `./dataset/telegram` and look at it before the pipeline does, rather than after.
No voice, no video, no links and no quotes survive a Telegram export
The support table is blunt about what Telegram import cannot carry. Text and images come through. Voice, video, shared links, quoted messages and files are all marked unsupported, while animated stickers are converted to emoji rather than preserved as stickers. Forwarded messages and locations do survive. If your history with a person is mostly voice notes and links, that part of your personality never reaches the model, and the resulting twin will answer in a register you never used with that person.
The other three import targets are a thinner story still. WhatsApp, Discord and Slack carry a work-in-progress marker on every column of that table, text included. One import path exists, and the project is clear about it.
Audio work is not folded in either. `pyproject.toml` defines a `sparktts` dependency group with soundfile and soxr, separate from `main`, and the install command above pulls `main` only.
Four deployment targets, one import target
Deployment is broader than ingestion, which is the one place the two platform tables diverge in your favour. Telegram bots are supported, as are Discord and Slack. Personal WeChat accounts are supported too, on the strength of a dependency on openclaw-weixin rather than a first-party integration, so the WeChat path inherits whatever that project handles. WhatsApp deployment remains marked as work in progress.
A twin fed by a single Telegram export can therefore answer in four places. That is a real convenience if you move between clients, and it is also a reason to think about where the output lands. The model that learned your messages is now reachable from a group chat, and neither table says anything about access control, rate limits, or who is allowed to talk to the bot.
torch 2.7.1+cu126 skips macOS, and requires-python stops at 3.12
Every install is a negotiation with tight pins. `requires-python` is `>=3.12,<3.13`, so a 3.13 or 3.11 interpreter is refused outright rather than warned about. `torch` is pinned to 2.7.1+cu126 with `torchvision` 0.22.1+cu126, `transformers` to 4.53.2, `pydantic` to 2.10.6, `openai` to 1.87.0 and `llamafactory` to 0.9.4. `vllm` 0.10.0 and `triton` 3.3.1 carry a Linux-only marker, while torch and torchvision carry a Linux-or-Windows marker.
Combined with the CUDA 12.6 requirement, that puts a macOS user outside the training path entirely and confines the inference server to Linux. Windows is the awkward case: the install line carries a `.venv\Scripts\activate` comment for it, yet the README says the Windows environment has not been rigorously tested and points at WSL as the runtime instead. A Windows reader is told to install natively and run under a Linux subsystem in the same breath.
Version 0.4.0 in pyproject, newest release tag v0.3.03
The version numbers do not line up. `pyproject.toml` declares `version = "0.4.01"` and `[tool.weclone]` sets `config_version = "0.4.01"`, while the newest release tag is v0.3.03, published on 2026-01-04, after v0.3.02 on 2025-08-17 and v0.3.01 on 2025-07-17. Installing from git therefore hands you 0.4.01 code that no release note describes, and the release history stops nearly ten months before the last push on 2026-11-02.
The config changelog inside `pyproject.toml` tracks structure changes separately, with entries for 0.3.00 on 2025-06-30, 0.3.02 on 2025-08-15 and 0.3.03 on 2025-11-01. It also disagrees with the update list in the README, which dates Telegram ingestion to 25/07/10 while the changelog dates TG chat log support to 2025-06-30. Since the number is meant to be incremented whenever the config structure or an important default changes, an old `settings.jsonc` is the first file to check when a key seems to be ignored.
If you already hold clean instruction data, weigh LLaMA Factory instead. It is the toolkit WeClone delegates training to, pinned here at 0.9.4, and it performs the same supervised fine-tuning without the export, the Presidio pass or the bot binding. WeClone is the part that turns chat history into a dataset, which is also the part you drop when you already have one. The repository ships under AGPL-3.0, and putting a bot on Telegram, Discord, Slack or WeChat puts a networked service in front of that choice, so read the license text against your own deployment before exposing a twin.
Editorial conclusion
WeClone fits one narrow job well: turning a Telegram export into a bot that answers in your own register, with `settings.jsonc`, the Presidio pass and the deployment tables making that path concrete. Skip it if your chat history is mostly voice notes and links, or if you need macOS, since the main dependency group installs no torch there. Before anything else, export one contact, read the Presidio entity list against what that chat actually contains, and confirm `telegram_args.my_id` is set, because every later stage inherits those two decisions.
Frequently asked questions
What model and fine-tuning method does WeClone use by default?
Qwen2.5-VL-7B-Instruct with LoRA for the SFT stage, downloaded into `models/Qwen2.5-VL-7B-Instruct`. Other models and methods supported by LLaMA Factory can be used instead.
How much VRAM does WeClone need for a 7B model?
16GB for Freeze, LoRA, GaLore, APOLLO or BAdam at 16-bit, 10GB for QLoRA at 8-bit, 6GB at 4-bit, 4GB at 2-bit, and 60GB for a full pure_bf16 fine-tune. The README calls the 7B result average and says 14B or more tends to do better.
Which chat platforms can WeClone import from and deploy to?
Import covers Telegram, with text and images but no voice, video, links, quoted messages or files, while WhatsApp, Discord and Slack are all marked as work in progress. Deployment supports Telegram, Discord, Slack and personal WeChat accounts through openclaw-weixin.
Does WeClone run on Windows or macOS?
The README says the Windows environment has not been rigorously tested and suggests WSL as the runtime, even though the install line carries a Windows activation comment. macOS gets no torch from the main group, and the CUDA check is marked as not needed for Mac.
What version of WeClone is current?
`pyproject.toml` declares version 0.4.01 and `config_version` 0.4.01, while the newest release tag is v0.3.03, published on 2026-01-04. Installing from git gives you code that no release note describes.
What license does WeClone use?
AGPL-3.0. Deployment to Telegram, Discord, Slack or WeChat puts a networked service in front of that license, so the license text is worth reading against your own deployment before you publish a twin.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/xming521-weclone)Star history chart for your README
[](https://hysenlabs.com/projects/xming521-weclone)Was this useful?