FoJin treats a Buddhist citation as two claims that can be checked
Buddhist Digital Text Platform — 10,500+ texts, 613 sources, trilingual cross-canon, AI Q&A (RAG), knowledge graph, full-text search
At a glance
- What is it?
- A Python platform aggregating Buddhist texts from hundreds of sources, with RAG answers that cite juan and volume, a public endpoint that verifies whether a quotation exists, and deployment defaults that treat an unset environment as production.
- Who is it for?
- FoJin suits researchers, students and developers who need one searchable front door to many Buddhist corpora and who want citations a machine can re-check, which is what /api/verify/quote and the fojin-mcp server are for. It is heavy to run, needing Postgres with pgvector plus Elasticsearch plus Redis, and the corpus arrives empty unless you import texts yourself.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository received new commits within the last day.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
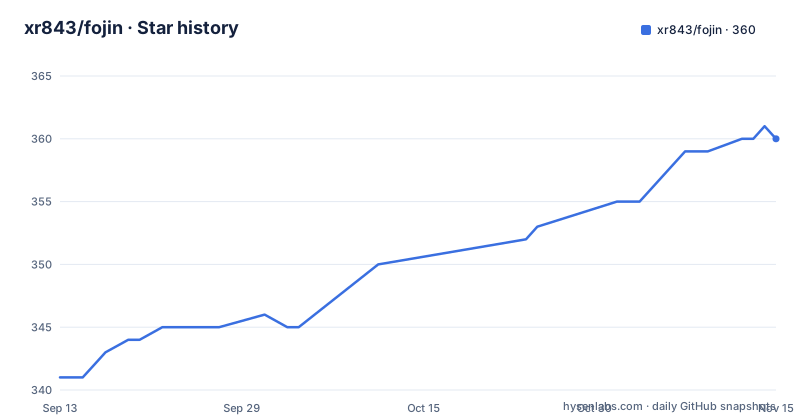
- xr843/fojin360 ★ · +19
| Repository | 2026-09-13 | 2026-11-15 |
|---|---|---|
| xr843/fojin | 341 | 360 |
19 Stars in the last 63 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
612 sources aggregated, and an empty corpus on first boot
FoJin pulls Buddhist texts out of separate databases and puts them behind one interface. The corpus is described as 10,500+ texts and 19,000+ volumes of full content in Classical Chinese, Pali, Tibetan and Sanskrit, drawn from sources including CBETA, SuttaCentral and 84000, with 39 dictionaries holding 747K entries and a knowledge graph of 110K+ entities. Scale figures move between sections of the documentation, by the way: the repository description counts 613 sources where the body says 612, and the reading row says 8,900+ texts where the rest says 10,500+.
What you get on first boot is not that corpus. After the schema and source metadata exist, the platform still has no text content, and the quick start hands off to an import step from public datasets.
git clone https://github.com/xr843/fojin.git
cd fojin
cp .env.example .env        # edit POSTGRES_PASSWORD before starting
docker compose up -d         # database migrations run automatically
The frontend answers on `http://localhost:3000` and the API documentation on `http://localhost:8000/docs`. Plan for a first run that is structurally healthy and semantically empty.
XiaoJin cites a juan, and a trust state travels with the answer
The assistant is called XiaoJin, and it answers by retrieval rather than recall: 670K+ embedded passages, optional cross-encoder reranking, and root-sutra recall to pull the containing text back when a fragment matches. Citations render as 【《sutra》juan N】 and open the exact passage, and a citation drawer places Chinese, Pali and Tibetan parallels side by side.
Underneath sits an explicit trust mechanism, which is the part worth judging. Answers pass a deterministic citation whitelist, a verbatim-quote downgrade when the wording cannot be matched, and a per-answer trust state. The documented figure is that roughly 98% of citing answers are served trustworthy at temperature 0, which is a statement about the citing subset at one setting rather than about the whole system.
For multi-step research there is a separate `/research` path that plans across corpus, dictionaries and the knowledge graph before synthesising an answer behind the same guards. Master Persona Mode adds 15 historical masters, each with retrieval scoped to their own tradition's scriptures, so the voice changes and the corpus narrows at the same time.
/api/verify/quote splits one citation into two questions
The most interesting endpoint takes a sentence and a citation and answers separately whether the quotation is real and whether the citation points at the right place. That distinction matters more than it first appears: a paraphrase can be genuine while the volume reference is wrong, and a system that returns a single confidence score hides that.
The response classifies the match as exact, near miss or absent, attaches a character-level diff, and returns the correct juan when the citation lands on the wrong one. It is not restricted to FoJin's own output. Any sentence can be checked, which turns it into a general tool for the trade: give it a quotation from a paper, a book or a forum post and see whether the canon supports it.
A companion route, `/api/commentary/passage`, returns what historical commentators wrote about one passage, anchored to juan and line. Together they cover the two things a citation is supposed to prove, existence and location, which is a smaller and more honest claim than a model's overall confidence.
Cross-canon pairs are verified chunks, not published translations
Alignment across canons is the feature with the most engineering behind it: 4,000+ chunk-level alignments, each LLM-verified, across Chinese, Pali and Tibetan. Named coverage includes the Heart Sutra, Vimalakīrti, the Lotus Sutra paired as 法华 against Toh 113 in 259 pairs, an 8,000-verse Prajñāpāramitā 小品般若 against Toh 11 in 127 pairs, Satipaṭṭhāna and the full Āgama to Nikāya corpus across MN, DN, SN and AN, and the Dhammapada.
What that means in practice is narrower than the word parallel suggests. These are chunks the pipeline decided correspond, checked by a model, not new translations and not alignments a scholar signed off on. The Heart Sutra pair and the 259-pair Lotus set are the ones to look at first if parallel reading is your reason to adopt this, because they are the concrete cases behind the 4,000+ figure.
Similarity search outside alignment runs on 670K+ embedding vectors in pgvector with HNSW, so finding texts that read alike is a separate mechanism from finding their counterparts across languages.
Passages carry URNs, and an MCP server hands them to an assistant
Every passage has a stable, resolvable identifier in the form `fojin:cbeta/T0001.1`, which is what makes the corpus callable from outside the web app. The `fojin-mcp` package on PyPI publishes eight read-only, URN-addressable tools, and a hosted instance runs at `mcp.fojin.ai` with no install and no key, so an assistant can query cited passages without credentials.
The local route is a single command:
uvx fojin-mcpRead-only is the design constraint to notice. A tool that can resolve a URN to text is safe to point an agent at; one that can write back into a corpus of religious texts is a different product with a different risk profile. The project chooses the first, and that choice is why the hosted endpoint can run anonymously.
This is also the honest alternative to the source databases themselves. CBETA, SuttaCentral, BDRC, SAT, 84000 and GRETIL each have their own interface, language and data format, and reading the primary source directly still gives you the better text. What FoJin adds is one query across all of them, alignment between canons, and an identifier your own code can hold onto.
The compose file carries its own outage history in comments
docker-compose.yml is unusually candid about what has gone wrong. Postgres runs the `pgvector/pgvector:pg15` image with `mem_limit: 4g`, and the comment above it records 155 cgroup OOM kills in the dmesg buffer, all of them task=postgres, each one a full crash-recovery cycle dropping every connection. A comment about raising the limit to 3g sits next to a value of 4g, so the prose and the setting have drifted apart.
The second block explains `shm_size: 256m`. Postgres puts parallel-worker shared memory in /dev/shm, Docker's default there is 64MB, and a parallel VACUUM on a table around 800MB fails with a shared memory resize error. Elasticsearch is built from a local Dockerfile rather than pulled, capped at 1536m of memory and 1.5 CPUs with single-node discovery. Both database ports bind to `127.0.0.1` rather than all interfaces.
One operational warning matters more than the tuning. Changing Postgres settings needs an explicit `docker compose up -d postgres`, because the path-aware `deploy.sh` does not recreate the database on a compose-only change. Miss that and a configuration edit appears to have done nothing.
Secrets fail closed, databases do not, and the tags run backwards
The example environment file is where the security posture shows. `FOJIN_ENV` is commented out, and unset means production, where startup fails without strong secrets; local development requires setting it to development to relax validation. `JWT_SECRET_KEY` and `API_KEY_ENCRYPTION_KEY`, which encrypts bring-your-own-key credentials independently of the JWT secret, are both required in production, and in development the encryption key is regenerated on every boot so stored ciphertexts do not survive a restart by design. Session length is explicit at `JWT_EXPIRE_MINUTES=43200` under an absolute cap of 90 days.
By contrast `ES_PASSWORD` and `REDIS_PASSWORD` ship empty, and the comments say empty means no authentication, described as the old behaviour. So the defaults are inconsistent in a way an operator has to notice: application secrets fail closed, datastore credentials fail open. `FRONTEND_BIND` defaults to `127.0.0.1`, with a warning that Docker bypasses ufw and exposes the port directly if you set it to `0.0.0.0`.
Licensing is Apache-2.0, with LICENSE and NOTICE both present, which matters for a corpus assembled from other projects' texts. On versioning, the release list runs v3.4.0 on 2026-03-13, v4.0.0 on 2026-03-19, then v1.0.0 labelled Initial Release on 2026-03-23, so tag order and semantic version order disagree. The last push was on 2026-09-24.
Editorial conclusion
FoJin suits researchers, students and developers who need one searchable front door to many Buddhist corpora and who want citations a machine can re-check, which is what /api/verify/quote and the fojin-mcp server are for. It is heavy to run, needing Postgres with pgvector plus Elasticsearch plus Redis, and the corpus arrives empty unless you import texts yourself. Check three things before committing: whether your questions survive retrieval over 670K passages, whether an unset FOJIN_ENV blocking your first boot is acceptable, and whether empty Elasticsearch and Redis passwords are acceptable on your network.
Frequently asked questions
What is FoJin and what does it index?
A Python platform that aggregates Buddhist texts from 612 sources into one searchable site, described as 10,500+ texts and 19,000+ volumes in Classical Chinese, Pali, Tibetan and Sanskrit, with 39 dictionaries and a 110K+ entity knowledge graph. After the first startup the database holds the schema and source metadata but no text, so content has to be imported.
How do I run FoJin locally?
Clone the repository, copy `.env.example` to `.env`, set `POSTGRES_PASSWORD`, then `docker compose up -d`, which runs the database migrations automatically. The frontend serves on port 3000 and the API documentation on port 8000.
Can FoJin check whether a quotation is genuine?
The `/api/verify/quote` endpoint takes a sentence and a citation and answers two separate questions, whether the quote is real and whether the citation is right, returning exact, near miss or absent with a character-level diff and the correct juan. It works for any sentence, not only FoJin's own answers.
How do AI assistants reach FoJin's passages?
Through the `fojin-mcp` package, which publishes eight read-only URN-addressable tools, run locally with `uvx fojin-mcp` or through the hosted endpoint at `mcp.fojin.ai` with no key required. Every passage carries a stable identifier of the form `fojin:cbeta/T0001.1`.
What does FoJin need to run besides the application code?
Postgres on the pgvector pg15 image capped at 4g with 256m of shared memory, a locally built Elasticsearch capped at 1536m and 1.5 CPUs, and Redis, plus an OpenAI-compatible LLM endpoint. Both database ports bind to 127.0.0.1 only.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/xr843-fojin)Star history chart for your README
[](https://hysenlabs.com/projects/xr843-fojin)Was this useful?