DocuTranslate's docker command publishes a port its own entrypoint never binds
Document (novel, thesis, subtitle) translation tool, supporting PDF, Word, Excel, JSON, EPUB, SRT and more.
At a glance
- What is it?
- DocuTranslate is a Python translation tool that wraps whatever AI platform you supply and handles pdf, docx, xlsx, epub, srt, json and more, with a web UI, a REST API and an MCP server. The feature list is wide and the format coverage is genuinely good. The operational surface is where the friction is: a container entrypoint that leaves the service on loopback, two documented ports for one MCP endpoint, a concurrency default that differs between the service table and the env example, and 21 dependencies with no upper bounds.
- Who is it for?
- DocuTranslate earns its place if you need subtitle, ebook, spreadsheet or paper translation driven by an AI endpoint you already pay for, and you want a self-hosted web UI rather than a hosted service. Five things to check before you rely on it.
- Can I use it commercially?
- Yes, with conditions. MPL-2.0 is a weak copyleft licence: you can use it inside commercial and closed-source software, but if you distribute changes to its own files, you must publish those changes under the same licence.
- Is it still maintained?
- Yes. The repository last received commits 13 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
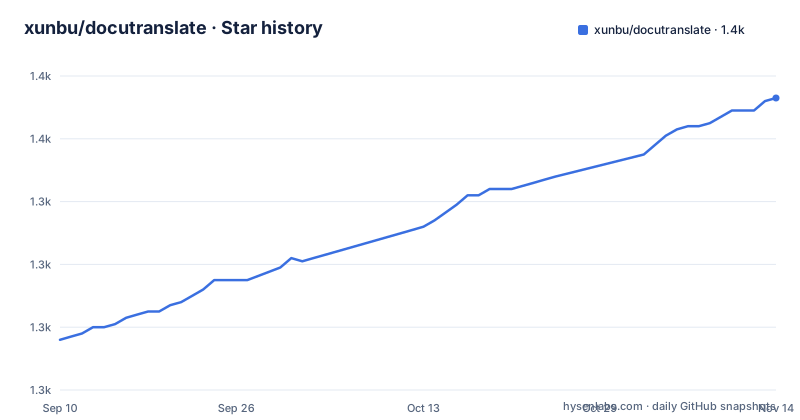
Star history
- xunbu/docutranslate1,373 ★ · +77
| Repository | 2026-09-10 | 2026-11-14 |
|---|---|---|
| xunbu/docutranslate | 1.3k | 1.4k |
77 Stars in the last 65 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
PDF is the headline format and the one format the README warns you off
The first feature bullet lists the formats: pdf, docx, xlsx, md, txt, json, epub, srt and ass. PDF is at the front of that list, which is how most people will read the tool.
Then there is a warning block near the top:
> When translating `pdf`, it is first converted to markdown. This will lose the original layout. Users with strict layout requirements should take note.
So the flagship input goes through markdown and comes back without its page structure. What survives is the content, and for academic papers the content is the point: PDF table, formula and code recognition uses mineru, online or locally deployed, specifically to handle the tables, formulas and code that appear in papers.
The other format caveat is quieter and sits inside a bullet. Word and Excel format preservation covers docx and xlsx, and the same line says the tool currently does not support doc or xls. That is the legacy binary pair, so a directory full of .doc and .xls files is out of scope.
Subtitles are the case the format list fits best: srt and ass through the srt and pysubs2 packages, with no layout to lose.
The image entrypoint starts the service without the flag that changes its bind address
The service flags come in pairs. Plain `docutranslate -i` starts the GUI with default local access, and `docutranslate -i --host 0.0.0.0` is the flag for allowing access from other devices on the LAN. That is the only difference between a loopback service and one other machines can reach.
The container entrypoint is `docutranslate -i --with-mcp`, with no host flag. The documented run command is `docker run -d -p 8010:8010 xunbu/docutranslate:latest`, and the image sets `DOCUTRANSLATE_PORT=8010` and declares `EXPOSE 8010`.
So the image publishes a port while its entrypoint leaves the service on its default local bind. Whether the published port actually reaches the UI depends on which of those two behaviours wins, and that is worth confirming on your own host before you build anything on top of the image.
The second container detail is quieter. The Dockerfile creates `/app/output` as a mount point with `RUN mkdir -p /app/output` and never declares a VOLUME for it. Translations written there live inside the container, so removing it discards them.
The rest of the runtime is lean: python:3.11-slim, and three apt packages, pandoc, ca-certificates and curl, with curl serving the healthcheck against `/service/meta` every thirty seconds.
Two environment variables exist so that .env can override what a user typed
`.env.example` is commented in Chinese and it is where the precedence rules live, because the settings it describes are not otherwise documented anywhere visible.
`DOCUTRANSLATE_WEB_SKIP_VALIDATION` skips the front end's empty-value checks. When it is true, the web interface stops validating, falls back to the backend `.env` defaults, and shows a hint icon on the page.
`DOCUTRANSLATE_ENV_FORRCE_OVERRIDE` is the sharper one. The two documented behaviours are asymmetric. When true, any field set in `.env` forces that value and the front end parameter is ignored. When false, which is the stated default, `.env` is consulted only where the front end sent nothing.
That is a normal precedence design, and a user who sets the override to true will find their UI selections quietly disregarded. Nothing in the service flags or the environment variable table mentions either flag, so the behaviour is discoverable only by reading the example file.
The same file is where the provider list lives. `DOCUTRANSLATE_PROVIDER` accepts `default, google, minimax, ollama, aliyuncs, volces, siliconflow, bigmodel, deepseek, openrouter, mimo, litellm`, twelve named providers, where the README says only that most AI platforms are supported.
Concurrency is 10 in one document and 30 in the other, and streaming has no total timeout
The same setting is documented twice with different values. The service environment variable table says `DOCUTRANSLATE_CONCURRENT` defaults to 10. The example env file says `DOCUTRANSLATE_CONCURRENT=30`.
Neither is wrong on its own. What matters is which one a fresh install picks up, and the file a user copies is the example file.
The timeout settings are where the more interesting behaviour is. Streaming is on by default, and `DOCUTRANSLATE_STREAM_IDLE_TIMEOUT` defaults to 300 seconds with the rule spelled out: the timer resets on every chunk received, and in streaming mode there is no total wall-clock ceiling. A stream that keeps trickling data can therefore run indefinitely, and the only thing that stops it is the idle timer.
Non-streaming is the opposite. `DOCUTRANSLATE_NON_STREAM_TIMEOUT` is a hard total per request or per chunk, defaulting to 1200 seconds, and the older `DOCUTRANSLATE_TIMEOUT` survives purely as a compatibility default for it. Two names, one behaviour, one of them deprecated in a comment.
Also worth knowing before tuning: chunk size defaults to 4000, temperature to 0.7, top-p to 0.9, and thinking mode takes default, enable or disable.
One MCP SSE endpoint, two documented ports, and a flag list that stops mid-word
DocuTranslate can run as an MCP server in two ways. `--mcp` starts it in stdio mode and `--mcp --transport sse` starts it in SSE mode, and `-i --with-mcp` runs the GUI with an MCP SSE endpoint sharing the same queue and port.
The SSE URL is then given twice with different ports:
- `http://127.0.0.1:8010/mcp/sse` when started with `--with-mcp` - `http://127.0.0.1:8000/mcp/sse` when started with `--mcp`
8010 is the GUI's default port and 8000 is the MCP server's, which the SSE configuration example confirms with `--mcp-port 8000`. A third number appears in the flag list, `docutranslate -i -p 8081`. So the same endpoint has two valid ports depending on launch mode, and copying the wrong one produces a connection failure with nothing to indicate which mode you are in.
The flag list itself ends on an unfinished line, `docutranslate --mcp --tr`. Whatever that flag is, it is cut off in the documentation as written.
For the zero-install route, the `uvx` configuration runs the server straight from the package with `DOCUTRANSLATE_API_KEY`, base URL and model ID supplied in the environment block.
Twenty-one dependencies, every one with a floor and no ceiling
The runtime list runs from `fastapi[standard]>=0.115.12` through `jsonpath-ng`, `openpyxl`, `xlsx2html`, `json-repair`, `mammoth`, `srt`, `lxml`, `python-docx`, `beautifulsoup4`, `markdown`, `pymdown-extensions`, `pysubs2`, `httpx`, `python-pptx`, `pypdf`, `regex`, `charset-normalizer`, `html2text`, `python-dotenv` and `msoffcrypto-tool`. Every constraint is a `>=`.
Nothing has an upper bound, so a fresh install resolves each of those to whatever the newest release happens to be. For a tool that depends on document parsing libraries across six formats, that is the dependency ceiling most likely to produce a surprise.
Two smaller inconsistencies sit in the same file. The `mcp` extra declares `python-dotenv>=1.0.0` while the base dependency already requires `python-dotenv>=1.2.1`, so the extra's constraint is weaker than the one it wraps. And the three packages in the `docling` extra, `opencv-python`, `docling` and `hf-xet`, appear again verbatim in the dev dependency group, so a development install pulls them through two separate mechanisms.
The pytest configuration is worth a glance too. `addopts` carries `-v --cov=docutranslate --cov-report=term --cov-report=html:htmlcov`, so coverage runs and writes an `htmlcov/` directory on every test invocation rather than on request.
There is also a Chinese-language comment left on the `setuptools` build requirement, and a commented-out `packages` line directly above the discovery settings that replaced it.
The PyPI one-liner is Chinese, the README is in four languages, and the target defaults to Chinese
The manifest's `description` field is `文件翻译工具`. That is the single line PyPI search, aggregators and every link preview show first, and it is Chinese only.
Against that, the repository carries four READMEs: Chinese, English, Japanese and Vietnamese. So the project has translated its long documentation four ways and left its one-line store description monolingual.
`DOCUTRANSLATE_TO_LANG` also defaults to Chinese, which is a sensible default for the project's home audience and a surprising one for someone who arrived through the English README or the Japanese one.
The community channels follow the same shape. Support points at two QQ group numbers, which is a China-only channel, in the same README that offers four language versions.
Version history has the same split. GitHub releases carry tags through v1.7.9 from 2026-09-04, with v1.7.8 in July and v1.7.7 in June, and the root of the tree also holds a Chinese-named plain text file, `更新日志.txt`, as a second changelog. Two release records, one of them not machine-readable by anything.
The portable packages take the same shape. Four PyInstaller spec files sit at the root, `full.spec`, `lite.spec`, `lite_mac.spec` and `lite_mac_x86_64.spec`, alongside `.icns`, `.ico` and `.png` icons, while a single README line calls them Windows and Mac portable packages under 40MB without naming the four variants.
The PDF engine is named once in prose and declared as a different extra in the manifest
The README names one parsing engine. PDF table, formula and code recognition uses mineru, online or locally deployed, and the environment variable table carries `DOCUTRANSLATE_MINERU_TOKEN` and a `DOCUTRANSLATE_CONVERT_ENGINE` setting whose example value in the uvx block is `mineru`.
The manifest declares a second one. The `docling` extra pulls `opencv-python`, `docling>=2.40.0` and `hf-xet`, which are not PDF parsing libraries by name and read as the local-deployment alternative to the hosted path.
So across three files there are two engines named, a selector variable, and no single place that says which one runs when or what the trade-off is. No section a reader is pointed to names the docling extra at all.
The container settles the question by omission. The Docker build runs:
uv sync --frozen --extra mcpso the image installs the MCP extra and no PDF engine extra, while still being the path offered for a quick start.
For the SDK the split is explicit in the examples: a plain text file needs no PDF parsing engine, and a PDF needs either a mineru token or a local deployment.
Editorial conclusion
DocuTranslate earns its place if you need subtitle, ebook, spreadsheet or paper translation driven by an AI endpoint you already pay for, and you want a self-hosted web UI rather than a hosted service. Five things to check before you rely on it. PDFs lose their layout because they go through markdown first, so they are not the right tool for a layout-sensitive document. If you deploy the container, verify the port is reachable, because the entrypoint starts the service without the host flag the bind address depends on, and nothing under /app/output is declared as a volume. If you run it for multiple people on a LAN, decide whether .env should be able to override what users typed in the UI, because a documented flag makes that possible. Pin your dependency versions yourself, since nothing in the manifest has a ceiling. And note that the changelog is a Chinese-named text file beside the release tags.
Frequently asked questions
How do I install DocuTranslate?
Four paths are given. `pip install docutranslate`, or `pip install docutranslate[mcp]` for the MCP extension, then run `docutranslate -i`. With uv, `uv init`, `uv add docutranslate`, then `uv run --no-dev docutranslate -i`. From git, clone the repository and run `uv sync --no-dev`, which means the git path also needs uv. Or `docker run -d -p 8010:8010 xunbu/docutranslate:latest`. Python 3.11 or newer is required.
Does DocuTranslate preserve the layout of a PDF?
No. PDFs are first converted to markdown, and the warning is stated plainly: the original layout is lost, and users with strict layout requirements are told to take note. What it does handle from papers is content: table, formula and code recognition through mineru, used online or locally deployed.
Which environment variables does DocuTranslate require?
Three are marked required: `DOCUTRANSLATE_API_KEY`, `DOCUTRANSLATE_BASE_URL` and `DOCUTRANSLATE_MODEL_ID`. `DOCUTRANSLATE_TO_LANG` defaults to Chinese and `DOCUTRANSLATE_CONCURRENT` to 10 in the service table, though the `.env.example` file shows a concurrency value of 30. `DOCUTRANSLATE_CONVERT_ENGINE` and `DOCUTRANSLATE_MINERU_TOKEN` are optional and relate to PDF parsing.
Can I run DocuTranslate as an MCP server?
Yes. `docutranslate --mcp` starts it in stdio mode, and `docutranslate --mcp --transport sse --mcp-host 127.0.0.1 --mcp-port 8000` starts it in SSE mode, with the client pointed at `http://127.0.0.1:8000/mcp/sse`. Adding `-i --with-mcp` to the GUI command serves the same endpoint on the GUI port instead, `http://127.0.0.1:8010/mcp/sse`. A uvx configuration runs it without installing anything.
What does the DocuTranslate Docker image include?
It is built from `python:3.11-slim` in two stages, with uv creating the environment and `uv sync --frozen --extra mcp` populating it, so only the MCP extra is installed and no PDF engine extra. The runtime adds pandoc, ca-certificates and curl, sets `DOCUTRANSLATE_PORT=8010`, exposes 8010, healthchecks `/service/meta` every thirty seconds, and starts with the entrypoint `docutranslate -i --with-mcp`.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/xunbu-docutranslate)Star history chart for your README
[](https://hysenlabs.com/projects/xunbu-docutranslate)Was this useful?