LLMstudio is a monorepo that runs a proxy and a tracker as two services
Framework to bring LLM applications to production
At a glance
- What is it?
- TensorOpsAI/LLMstudio packages prompt engineering work as four installable Python libraries under libs/, started through one CLI with proxy and tracker flags that expose separate Swagger ports. The metadata disagrees with the repository licence, and the type casting feature is still marked as coming soon.
- Who is it for?
- Fit for a team that wants one interface in front of several model providers plus a record of what was sent, and for the LangChain or LangGraph side projects that the example notebooks already assume. A poor fit if you expected one process or one port, because the proxy and the tracker are separate services with separate Swagger endpoints on 0.0.0.0, and the prompt playground has no documented start command in the README.
- Can I use it commercially?
- Yes, with conditions. MPL-2.0 is a weak copyleft licence: you can use it inside commercial and closed-source software, but if you distribute changes to its own files, you must publish those changes under the same licence.
- Is it still maintained?
- Yes. The repository last received commits 108 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 13, 2026, and from our analysis. They are not legal advice.
Star history
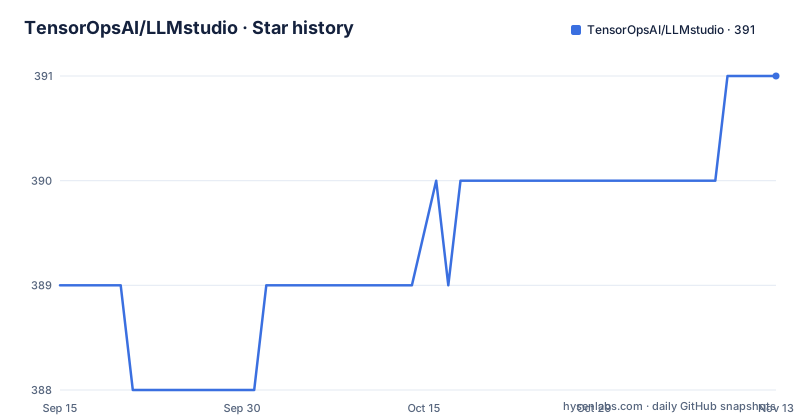
- TensorOpsAI/LLMstudio391 ★ · +2
| Repository | 2026-09-15 | 2026-11-13 |
|---|---|---|
| TensorOpsAI/LLMstudio | 389 | 391 |
2 Stars in the last 59 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Two flags, two Swagger ports, both on 0.0.0.0
The whole runtime is one command with two flags:
llmstudio server --proxy --trackerEach flag turns on its own service with its own OpenAPI browser, and they do not share a port. With `--proxy` the Swagger page is at `http://0.0.0.0:50001/docs` on the default proxy port, and with `--tracker` it is at `http://0.0.0.0:50002/docs` on the default tracker port. Those are default ports, so a configuration file elsewhere has to be the thing that moves them.
Worth noticing before you run this on a shared machine: the addresses in the documentation are all-interface addresses, not `127.0.0.1`. A Swagger endpoint reachable on every interface is a local convenience that becomes an exposure the moment the port is forwarded, so treat binding as something to set deliberately rather than inherit.
The feature list behind those two services is what the project is selling: proxy access to models from OpenAI, Anthropic and Google, custom or local open source models through Ollama, a prompt playground, a Python SDK, monitoring and logging, LangChain integration, batch calls, and routing with fallback for availability. Type casting is on the same list and is marked as coming soon, so it is a promise rather than a feature today.
Extras decide whether you get the proxy and the tracker
Two pip commands, and the difference between them is which parts arrive:
pip install 'llmstudio[proxy,tracker]'pip install llmstudioThe first is the full version with the proxy and tracker extras, the second is the lightweight core. Since those extras are the same components the `--proxy` and `--tracker` flags start, a core only install is the case where the flags will have nothing to run, so the choice has to be made before the first start rather than after a failed one.
The installation section also suggests creating and activating a new environment with conda first. That is advice rather than a requirement, and it matters because the supported interpreter range in the project metadata is Python 3.10 up to but not including 3.15.
Keys go in a .env in the directory you launch from
Configuration is a single file, and the rule is positional rather than a documented search path:
OPENAI_API_KEY="sk-api_key"
ANTHROPIC_API_KEY="sk-api_key"
VERTEXAI_KEY="sk-api-key"
The README is specific that the `.env` file is created at the same path you will run LLMstudio from, which means the working directory is part of the configuration. Move your shell somewhere else and the keys are not where the process last found them. The repository carries a `.env.template` at the top level, which is the shape to copy from, and `.gitignore` is present so the real file is not meant to be committed.
Three variables cover the hosted providers the feature list names, and nothing here covers a self hosted endpoint: for local or custom models the route described is Ollama rather than a base URL setting. So a deployment that mixes a local model with two hosted ones needs at least one of the three keys, and the README does not say what happens when only one is present.
package-mode is off, so the root project is not distributed
The project file is named `llmstudio-monorepo`, sits at version 1.0.0 and carries `package-mode = false`. That flag is the important line: the root is a workspace, not something that gets built and uploaded. The distributable pieces are the four libraries under `libs/`, and the development dependency group points at four local paths in develop mode:
llmstudio = { path = "libs/llmstudio/", develop = true }
llmstudio-core = { path = "libs/core/", develop = true }
llmstudio-tracker = { path = "libs/tracker/", develop = true }
llmstudio-proxy = { path = "libs/proxy/", develop = true }
The single console script the workspace declares is `llmstudio = "llmstudio.cli:main"`, which is the command the quickstart uses. The build backend is poetry-core, the only non development dependency constraint is the Python range, and the keywords list covers ml, ai, llm, llmops, openai, langchain and chatgpt, which tells you which integrations the author expected this to be used from.
The licence file says MPL-2.0, the project file says MIT
Two claims about licensing sit side by side. The repository licence is MPL-2.0, and the metadata in the project file declares `license = "MIT"`. For a package you install from a registry that gap is not academic: which terms apply depends on the file you actually receive and redistribute, and the two are not the same licence.
There is a second mismatch of the same kind. The repository homepage is tensorops.ai, while the project file points at llmstudio.ai and the documentation field at docs.llmstudio.ai, and the README quickstart tells you to check out the docs page. So the project's own metadata advertises a domain the repository does not list as its home, and the person reading the source has to guess which one is canonical.
The author of the project file is named as Cláudio Lemos with a tensorops.ai address, and the bug tracker points at the issues page of the repository.
Tests cover core and the main library, not the two services
Three Makefile targets is the entire developer entry point:
format:
	pre-commit run --all-files

unit-tests:
	pytest libs/core/tests/unit_tests

integration-tests:
	pytest libs/llmstudio/tests/integration_tests
The gap is where you would expect it. Unit tests live in `libs/core`, integration tests live in `libs/llmstudio`, and neither target mentions `libs/proxy` or `libs/tracker`, which are the two components you start as services on ports 50001 and 50002. Formatting is enforced through a pre-commit config rather than a Makefile-only step, so `make format` is the hook running all files.
Two other files at the root hint at what the services persist. `alembic.ini` is the migration tool configuration, which is how schema changes are managed for whatever the tracker stores, and `MANIFEST.in` controls what ends up in a source distribution. There is also a `deploy/` directory and a `docs/` directory, plus a `poetry.lock` for reproducible resolution.
The examples skip number five and the docs are marked coming soon
The `examples/` directory is the most complete documentation in the project. It holds notebooks for an introduction to the base, core, proxy and tracker versions of the library, an introduction with the proxy, one with tracking, an LLM comparison notebook, LangChain integration, a BigQuery integration, a Google Cloud guide and a LangGraph tutorial. Alongside them sit plain Python entry points: `core.py`, `sdk.py`, `llm_proxy.py`, `langchain_integration.py`, a `_config.yaml` and a README of its own.
Two things about that list are worth a second look. The numbering jumps from 04 to 06, so there is no fifth notebook in the tree, which suggests a file was removed or renumbered rather than never written. And the documentation bullet in the README is annotated as coming soon, while the quickstart points at docs.llmstudio.ai through a link whose target is the relative `docs` path, so following it lands in this repository's docs directory rather than on the hosted site.
Contributing goes through a CONTRIBUTING.md file and a Discord invite, and a training link points at an LLM Studio workshop page on the tensorops.ai site.
Editorial conclusion
Fit for a team that wants one interface in front of several model providers plus a record of what was sent, and for the LangChain or LangGraph side projects that the example notebooks already assume. A poor fit if you expected one process or one port, because the proxy and the tracker are separate services with separate Swagger endpoints on 0.0.0.0, and the prompt playground has no documented start command in the README. Before installing, decide whether you need the full extras or the core only, sort out the licence question by reading the LICENSE file rather than the pyproject, and bind those two ports to loopback if the machine is not yours alone.
Frequently asked questions
What does TensorOpsAI/LLMstudio do?
It is a Python framework for taking LLM applications to production, framed as prompt engineering at your fingertips. It lists proxy access to models from OpenAI, Anthropic and Google, custom or local models through Ollama, a prompt playground, a Python SDK, monitoring and logging, LangChain integration, batch calls, and smart routing with fallback. Type casting is on the list but marked as coming soon.
How do I install and start LLMstudio?
Run pip install 'llmstudio[proxy,tracker]' for the full version or pip install llmstudio for the lightweight core, preferably in a new conda environment. Put OPENAI_API_KEY, ANTHROPIC_API_KEY or VERTEXAI_KEY into a .env file at the path you will run from, then start it with llmstudio server --proxy --tracker.
Where are the LLMstudio Swagger pages?
The proxy service serves its OpenAPI page at http://0.0.0.0:50001/docs on its default port, and the tracker serves its own at http://0.0.0.0:50002/docs. Both addresses are all-interface rather than loopback, so binding them is worth deciding before running on a shared machine.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/tensoropsai-llmstudio)Star history chart for your README
[](https://hysenlabs.com/projects/tensoropsai-llmstudio)Was this useful?