video-subtitle-remover: five Windows builds and five inpaint modes
An AI-based tool for removing hard-coded subtitles and text-like watermarks from images or videos, producing lossless-resolution output without needing any third-party API; runs entirely locally.
At a glance
- What is it?
- VSR erases subtitles burned into video frames by inpainting the masked region, and it ships as five differently targeted Windows archives plus three Docker tags. The choice you make in the first minute, coordinates versus whole-frame sweep and sttn versus lama, decides whether the output is usable.
- Who is it for?
- Adopt video-subtitle-remover when the subtitles are burned into the pixels and you have a card that matches one of the five Windows archives, or a Mac where CPU detection is acceptable. Skip it when the subtitle is a soft track you could switch off, when you need to strip watermarks from hundreds of pictures from a script, or when you need a batch input the option list does not offer.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 137 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
Star history
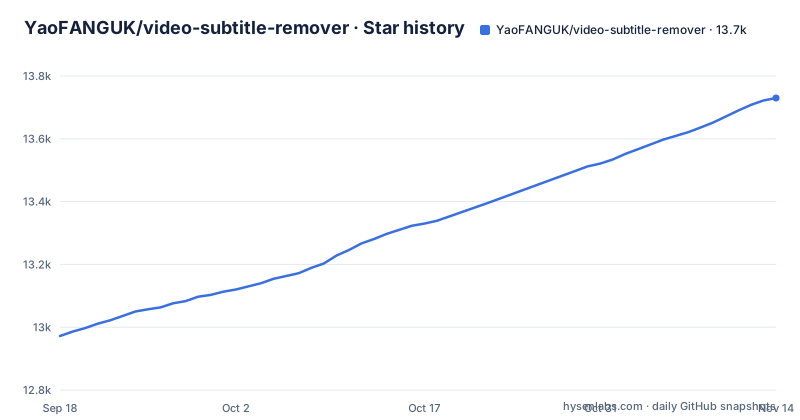
- YaoFANGUK/video-subtitle-remover13,730 ★ · +758
| Repository | 2026-09-18 | 2026-11-14 |
|---|---|---|
| YaoFANGUK/video-subtitle-remover | 13k | 13.7k |
758 Stars in the last 57 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The CLI wants four coordinates or it sweeps the whole frame
Two of the documented options decide how much of the picture gets touched. Give the tool `--subtitle-area-coords YMIN YMAX XMIN XMAX` and it restricts work to that band, which is what you want for a video carrying a permanent channel logo while dialogue sits elsewhere in the frame. The flag can be repeated for several areas in one invocation. Leave it out and the tool scans the entire video for text and inpaints every region it finds, which is also how you clear a station ident or a scrolling ticker. The rest of the option list is thin: `-i INPUT` names the video, `-o OUTPUT` names the result, and `--inpaint-mode` takes five values with `sttn-auto` as the default. Nothing in that list takes a folder of clips, a frame range or a resolution override, so a batch of files means a shell loop rather than one command.
Five inpaint modes, and the default is a guess about your footage
The five values split along two different lines. The two sttn entries are variants of STTN, while `lama`, `propainter` and `opencv` fill the masked region by other means. The project's own notes say what each one buys: sttn works better on live-action footage, runs fast, and can skip subtitle detection. lama gives the best result on still images and on animated video, runs at middling speed, and cannot skip detection. propainter is the answer for motion that is very violent, and it consumes a large amount of video memory. Starting on `sttn-auto` hands that decision to the default for the first export of your session. Animated source deserves an explicit `lama` before you queue an hour of processing onto it.
Windows archives are cut by compute capability, and only one covers old cards
Each release ships five Windows archives, and the deciding column is compute capability rather than the driver you happen to have installed. `vsr-windows-cpu.7z` and `vsr-windows-directml.7z` both run Python 3.12 with Paddle 3.0.0, the first anywhere and the second on non-Nvidia Windows cards. The three Nvidia archives split by CUDA version, and their supported ranges do not overlap the way a driver version would. The CUDA 11.8 package covers compute capability 3.5 to 8.9, the CUDA 12.6 package covers 5.0 to 8.9, and the CUDA 12.8 package covers 5.0 to 9.0 and above. Read that as a hard boundary rather than a preference: a card below capability 5.0 has only the CUDA 11.8 package among the Nvidia builds, because no other CUDA package reaches below 5.0. NVIDIA publishes a compute capability list per GPU model, which is the reference to use before you pick a download.
STTN_SKIP_DETECTION trades missed subtitles for damaged frames
The speed lever is a file you edit by hand, not a flag on the command line. Two settings in `backend/config.py` decide whether the sttn path runs the detector on every frame:
MODE = InpaintMode.STTN  # 设置为STTN算法
STTN_SKIP_DETECTION = True # 跳过字幕检测,跳过后可能会导致要去除的字幕遗漏或者误伤不需要去除字幕的视频帧
The comment on the second line states the whole contract: skipping detection can leave the subtitles you wanted removed still sitting in the output, and it can also inpaint frames that never carried a subtitle. That is a two-sided risk, not a free optimisation. It only makes sense once you have watched the source and know the text sits in a fixed band for the length of the clip. On a film where the subtitle position changes, or on footage where a face drifts through the lower third, the same setting that makes the pass faster is the one that returns a smeared face or a surviving subtitle.
Docker tags are cut per Nvidia generation and the AMD example stops mid-command
The container route is three published tags, one for each Nvidia generation, invoked identically:
# Nvidia 10 20 30系显卡
docker run -it --name vsr --gpus all eritpchy/video-subtitle-remover:1.4.0-cuda11.8 python backend/main.py -i test/test.mp4 -o test/test_no_sub.mp4
# Nvidia 40系显卡
docker run -it --name vsr --gpus all eritpchy/video-subtitle-remover:1.4.0-cuda12.6 python backend/main.py -i test/test.mp4 -o test/test_no_sub.mp4
# Nvidia 50系显卡
docker run -it --name vsr --gpus all eritpchy/video-subtitle-remover:1.4.0-cuda12.8 python backend/main.py -i test/test.mp4 -o test/test_no_sub.mp4
The fourth example, labelled for AMD and Intel hardware, breaks off after the image name is cut to `eritpchy/video-subti`, with no tag and no arguments, and it already carries `--gpus all` on that line. Treat the AMD and Intel invocation as undocumented rather than reconstructing it. Since every working example passes `--gpus all`, the container path assumes an Nvidia container runtime, and non-Nvidia machines are left to the source install below.
A Mac or a GPU-less box installs Paddle from the CPU index, then runs gui.py
On macOS and on machines with no GPU, the pinned install is the CPU one, and the entry point matches the other platforms:
python -m venv videoEnv
source videoEnv/bin/activate
pip install paddlepaddle==3.0.0 -i https://www.paddlepaddle.org.cn/packages/stable/cpu/
pip install torch==2.7.0 torchvision==0.22.0
pip install -r requirements.txt
Two caveats sit on that path. On an Intel Mac the guidance is to stay on CPU, because forcing the GPU there only makes it slower. On Apple Silicon the PP-OCRv4-Server detection model is described as having accuracy that is not ideal, with other models advised instead. Since a wrong detection region feeds straight into the inpainter, that Mac caveat is the one most likely to hand you a visibly broken frame. The same block notes it was based on Python 3.13 while the stated requirement is 3.12 or newer. Once the environment is up, `python gui.py` opens the interface and `python ./backend/main.py` runs the backend directly.
Soft subtitle tracks and image batches have no documented command line path
Two of the advertised capabilities exist only on one side of the interface. The image watermark remover handles a multi-select batch of pictures, while the command line documents an input video path and nothing else, so there is no documented way to run a folder of PNGs through the watermark pass from a script. A job that is a catalogue of product shots means driving the GUI, one batch at a time. The scope of the pixel work is equally narrow. This removes subtitles burned into the frame, and the project points at a separate repository, video-subtitle-extractor (VSE), for extracting the original video's subtitles. The tool targets hard subtitles burned into the frame.
Pinned wheels, one support group still open, last push 2026-06-30
Dependencies are pinned hard: `opencv-python==4.11.0.86`, `numpy==2.2.5`, `av==17.0.0`, `paddleocr==3.4.0`, `filesplit==3.0.2`, `scikit-image==0.25.2`, `pyside6-fluent-widgets==1.7.7` and `tqdm==4.67.1`. Torch and torchvision are deliberately kept out of that file and installed per platform, and the onnxruntime entries for linux, win32 and darwin sit commented out under a warning against upgrading, citing Windows 10 and 11 compatibility problems and pointing at `hardware_acclerator.py` for the check. Any upgrade to Python or Torch is therefore a full environment rebuild, not a version bump. Release spacing has been uneven, with 1.1.0 in December 2023, 1.1.1 in April 2025 and 1.4.0 on 2026-04-09, and the last push dated 2026-06-30 on a repository that is not archived. Support runs through QQ groups, and three of the four numbers listed are marked full, leaving 295894827. The licence is Apache-2.0, so shipping a modified build carries the usual notice and licence-file obligations.
Editorial conclusion
Adopt video-subtitle-remover when the subtitles are burned into the pixels and you have a card that matches one of the five Windows archives, or a Mac where CPU detection is acceptable. Skip it when the subtitle is a soft track you could switch off, when you need to strip watermarks from hundreds of pictures from a script, or when you need a batch input the option list does not offer. Verify your own output before committing: run one short clip through `python ./backend/main.py` and compare frame rate, resolution and audio against the source.
Frequently asked questions
What is video-subtitle-remover (VSR) on GitHub?
It is the Python repository YaoFANGUK/video-subtitle-remover, licensed under Apache-2.0, with a Qt interface at gui.py and a command line through backend/main.py. The most recent release is 1.4.0.
Where do I download video-subtitle-remover (VSR)?
Prebuilt Windows archives are attached to the repository's releases page: vsr-windows-cpu.7z, vsr-windows-directml.7z and three Nvidia packages for CUDA 11.8, 12.6 and 12.8. Docker images under eritpchy/video-subtitle-remover are published as separate tags per Nvidia generation.
Is video-subtitle-remover (VSR) free?
It is free software under the Apache-2.0 licence. No third-party API key is needed because the processing runs locally.
What does video-subtitle-remover (VSR) actually remove?
It inpaints away hard-coded subtitles burned into the frame, generating output at the original resolution, and it can also remove text watermarks from a batch of images. Where you pass subtitle coordinates it restricts work to that band, and where you pass none it searches the whole video for text.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/yaofanguk-video-subtitle-remover)Star history chart for your README
[](https://hysenlabs.com/projects/yaofanguk-video-subtitle-remover)Was this useful?