yfedoseev/pdf_oxide: the repository record says Apache-2.0 and everything else says MIT or Apache-2.0, and the newest release is titled with 144 defects found in its own audit
The fastest PDF library for Python and Rust. Text extraction, image extraction, markdown conversion, PDF creation & editing. 0.8ms mean, 5× faster than industry leaders, 100% pass rate on 3,830 PDFs. MIT/Apache-2.0.
At a glance
- What is it?
- A Rust PDF toolkit with bindings for 19 languages, a CLI and a model-context-protocol server, claiming 0.8ms mean text extraction across a 3,830-file corpus and a 100 percent pass rate. The pass rate is 100 percent of the files the project excluded, the fastest row in the Rust comparison does not extract text, one row reports a p99 lower than its mean, and the pass criterion is that nothing crashed. The licence is stated five different ways and the narrowest of them is the machine-readable one.
- Who is it for?
- This is a fast library with unusually complete release notes and an unusually complete audit, and both of those make it much easier to trust than the marketing line is. Four things to check before you build on it.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 5 days ago.
- What is it written in?
- Mainly Rust, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
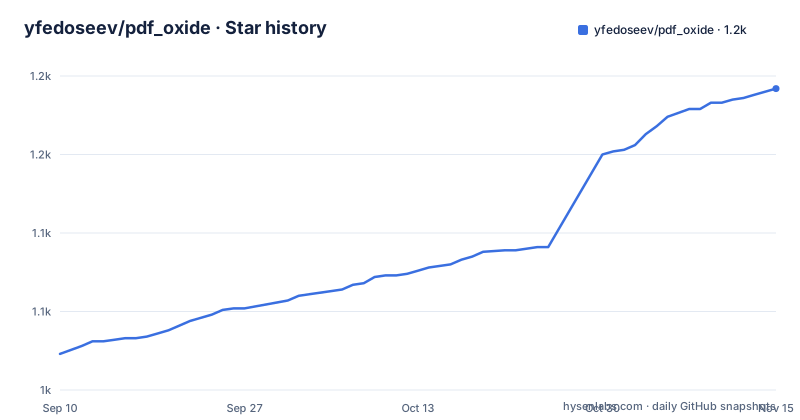
- yfedoseev/pdf_oxide1,192 ★ · +169
| Repository | 2026-09-10 | 2026-11-15 |
|---|---|---|
| yfedoseev/pdf_oxide | 1k | 1.2k |
169 Stars in the last 66 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The licence is stated five ways and the repository record is the narrowest
Pick a licence question in this project and you get a different answer depending on where you look. The repository metadata says Apache-2.0. The repository's own one-line description says MIT over Apache-2.0. The readme's opening paragraph says it is MIT licensed. The feature table in the same readme says MIT over Apache-2.0. The Python packaging manifest declares the dual expression properly and lists a classifier for each of the two licences. The root directory carries both licence files and a notice file, which is the correct layout for the dual grant. So five of the six statements agree that both licences are offered, and the sixth, which is the one a package index, a licence scanner and an automated compliance check will read, says one. Nothing in the repository reconciles them. The readme is internally inconsistent on its own as well, since the intro picks one licence and the table below it names both. The consequence is not theoretical. A licence scanner reading the repository record concludes the project is Apache-2.0 alone, which carries a notice obligation and a patent grant and offers no alternative. A scanner reading the files in the root concludes both are on offer. An organisation with a policy that permits one grant and not the other gets different answers from different tools, and the narrower answer is the one a hosting platform shows a user.
The newest release is titled with 144 defects found in its own output
Read the release titles rather than the feature list. The tag at version 0.3.78 is named for a correctness audit and states 144 defects across rendering, text, reading order, files and colour. That is a library whose job includes rendering pages, recovering text, deciding reading order and producing markdown, reporting 144 places where its own output is wrong. The Python packaging manifest separately classifies the project as version 4 Beta, which is the classification for a package that is not yet considered stable. Those two facts sit in the same repository as the fastest-library claim, and neither is hidden. What they add up to is a project that has measured its own error rate and published it, which is more than most libraries in this space do, and a project that is telling you not to treat it as finished. The earlier release titles are the same register. Version 0.3.76 fixes edits that could be lost on save, a specific image filter that misread compressed data, table-cell ownership at boundary cases, and a search path that scaled with the number of searches times a full extraction. The title before that describes the other kind of bug, and it is the one to worry about. The text, markdown and plain-text conversion functions were silently dropping content the source file had tagged as a structural artifact, which is how running headers, footers and section identifiers are marked in a tagged document. Doing that silently, with no way to opt back in, means every document with a running footer quietly lost it and the user could not tell. A lost footer is a nuisance. The same failure class in a table or a reference list is not.
One Rust row reports a p99 below its mean, and the fastest row extracts no text
The Rust comparison table has four other libraries and two things in it do not survive a second look. The first is a row for a library whose mean is 13.5 milliseconds and whose p99 is 11 milliseconds, which is not a distribution that can exist. Either the columns are transposed for that row or one of the numbers is wrong, and either way the table cannot be used to make a tail-latency claim about it. The second is the fastest row in the whole table, at 0.3ms mean, which belongs to a library listed as having no built-in text extraction. That row is in a comparison whose column heading is text extraction, so the table's own fastest result is a library that does not do the thing being compared. Set it aside and the ordering among the libraries that do extract text is coherent, with the library under review first. The Python table is cleaner and its four headline multipliers are exact ratios of the mean column, so the claims are arithmetically consistent with the numbers beside them. The tail column is where the picture is least flattering to the marketing. The 9ms figure compares against 28ms, 42ms, 82ms, 97ms, 124ms, 189ms, 280ms and 378ms, and because the headline multipliers are ratios of means, the gap narrows in the tail: the slow library with a 108.8ms mean has a 378ms p99, which is a hundred-and-thirty-six times the mean ratio and forty-two times the tail one. Nothing in the tables reports throughput under concurrency, and the stated single-thread condition means it is nowhere in the document.
The 100 percent total is 100 percent of the files the project excluded
The corpus table lists three suites: a PDF/A compliance corpus of 2,907 files at 100 percent, a browser project's test corpus of 897 files at 99.2 percent, and an edge-case suite of 26 files at 100 percent. The three add up to the 3,830 in every headline. The total row then reads 100 percent, which the row above it contradicts, because 99.2 percent of 897 is roughly seven failures. The readme does explain it: the seven non-passing files are intentionally broken fixtures, with a missing file header, fuzz-corrupted catalogues and invalid cross-reference streams, so the total is 100 percent of the valid files. That is a defensible way to compute it and the explanation is in the document. The problem is that the explanation is in the readme and the unqualified number is in two places it is not, the repository description and the feature table. A reader who sees only the description has been told 100 percent on 3,830 real-world files and has not been told that seven were set aside. There is also a difference in what the three suites are for, which the table states and the headline does not. A compliance corpus is documents validated against a specification, so it is a corpus of well-formed files. A browser project's test corpus is closer to what people actually open, which is why it is the one suite sitting below a clean rate. An edge-case suite of twenty-six files is not a statistical sample of anything. So the headline is dominated by the suite with the least variety in it, and the suite that most resembles real usage is the one carrying the seven exclusions.
The pass criterion is that nothing crashed, and parity is not accuracy
Read the reliability line closely: a 100 percent pass rate, zero panics and zero timeouts. All three of those are liveness properties. A pass means the library returned without crashing and without exceeding the sixty-second per-file timeout, so the metric rewards not falling over and says nothing about whether the answer is right. That is a meaningful thing to measure and a much weaker thing than the number sounds. The 144 defects give the rest of the reliability claim its scale. Broken down across five named areas and attached to a dated release rather than lumped into a total, an audit of that size is the most useful number in the repository for anyone deciding how much of their own validation they still have to write. The text-quality claim is stated the same way: 99.5 percent parity against two named competitors across the corpus, plus a claim of extracting from seven to ten times more hard files than it misses. Parity is similarity to PyMuPDF and a browser library, so half a percent of the corpus diverges from both of them, and the readme does not say in which direction. Where a document is scanned the library agrees with nobody because it does not do optical recognition, which the benchmark conditions do disclose.
The C header that all nineteen bindings depend on drifted for twenty-six versions
Every language binding is built over a stable C interface, and that single decision is what makes twenty languages possible. The interface header is generated from the Rust source by a tool whose configuration and rule sit in the root. The Makefile carries the story of how that went wrong, in a comment above the regeneration target: the committed header had silently drifted to version 0.3.24, missing every symbol added in 0.3.50 and 0.3.51, because nothing regenerated it. The fix is a second target that regenerates the header to a temporary path, diffs it against the committed copy, and fails the build with a message telling you which command to run. So the architecture that makes nineteen languages cheap also produced a bug that would have shipped a wrong interface to every C and C++ consumer for twenty-six releases. It is worth noting that the failure was silent, which is the specific kind of problem a diff in continuous integration is designed to catch. The same drift class appears repeatedly in the release history. In 0.3.76 the edits and text overlays applied to a loaded page did not survive a save and left dangling content-stream references behind; a compressed image filter was decoding its data as raw stencil rows; a table cell could be attributed to the wrong column at a single-cell or boundary case; and repeating a search on one document re-extracted the whole file each time. Four defects in one patch, three of them silent. A project willing to put that in a release title is a project you can plan around.
The coverage target measures a module that the package does not contain
The Python Makefile is short and has one line that cannot work. The coverage target runs the test runner with a coverage source flag pointing at a module named for a PDF library with an internal separator, and the name is not the package anywhere else. The packaging manifest gives the distribution a joined name with no separator, the install command uses the hyphenated form, and the import line in the quick start uses the joined form. The install line is the shortest statement of that same naming:
pip install pdf_oxideThe Makefile header comment refers to it as the PDF library bindings. So the coverage flag names a module that the distribution does not ship, which means the coverage report measures an empty target and reports nothing about the code it is meant to measure. The same file has two more small mismatches. A target that builds wheels for all Python versions lists five interpreters starting at 3.8, while the manifest requires 3.9 or newer and classifies support up to 3.14, so the build target covers a version the project does not support and stops two short of the version it does. Five more targets in that file are defined without being declared, among them the two coverage variants, the all-versions wheel build, and both header targets. None of them creates a file with its own name, so the omission has not bitten yet, but the declared list names ten targets while roughly half of what the file actually defines are absent from it.
The model-context-protocol configuration points at a launcher the install line does not provide
The four lines that set up the model-context-protocol server contradict each other. The install line is a Homebrew command for the project's own tap, with a trailing note that it includes the server binary. The configuration block immediately below it, the one you paste into a client, does not name that binary at all. It names a command called crgx and passes it a crate-style specifier with an at-sign version tag. So the documented path is: install the binary one way, then configure your client to fetch and run it through a completely different launcher that the install line never mentioned. A reader who follows both blocks literally ends up with a configuration that depends on a tool they do not have. The rest of the packaging surface is more careful. The root carries a dependency-advisory configuration, a vulnerability-scanner configuration, a coverage configuration, a linter configuration and a formatter configuration, and the workspace manifest goes to the trouble of listing exactly which optional dependencies a dead-code detector will wrongly flag. The language count is where this kind of sprawl shows. The readme says twenty languages, a core plus nineteen bindings, and the tree holds a directory per binding plus workspace members for the command-line tool, the protocol server and the Java interface layer. Eleven bindings arrived in a single earlier release, each with its own continuous-integration workflow and its own coverage tests. Those tests are what turned up the lag described in one release title, where a search-index capability added to the core in one version reached the other nineteen bindings only in the next.
Editorial conclusion
This is a fast library with unusually complete release notes and an unusually complete audit, and both of those make it much easier to trust than the marketing line is. Four things to check before you build on it. The licence is the first thing to resolve, because the repository record says Apache-2.0 while the licence files, the packaging manifest, the description and the readme all say the permissive pair, and the narrower statement is the one tooling reads. The second is what the pass rate means: it is a liveness test, so nothing panicked and nothing timed out, and the text-quality claim is agreement with two competitors rather than agreement with the truth. An audit found 144 defects in rendering, text, reading order, file handling and colour, which is the number to size your own testing against. The third is feature coverage: digital signatures, machine-learning table detection, optical recognition and press-grade colour management are all optional features off by default, and the benchmark ran on the default set with no recognition. The fourth is the stable C interface that all 19 bindings depend on, which shipped a stale header for more than twenty versions before a drift check was added to catch it. For extraction at scale on documents you control, this is a serious piece of work with a candid changelog. For any decision where wrong output is worse than no output, budget your own validation.
Frequently asked questions
Which licence is pdf_oxide under?
The repository metadata says Apache-2.0. The repository description, the readme's feature table and the Python packaging manifest all say MIT or Apache-2.0, the readme's opening paragraph says MIT licensed, and the root carries both licence files plus a notice file. Nothing in the repository reconciles the metadata with the other five statements.
How does pdf_oxide compare to PyMuPDF and pypdf?
The benchmark table gives 0.8ms mean and 9ms p99 for pdf_oxide against 4.6ms and 28ms for PyMuPDF and 12.1ms and 97ms for pypdf, which are ratios of about five and fifteen times on the mean. The stated conditions are 3,830 files from three public suites, single-threaded, a sixty-second per-file timeout, no warm-up, and text extraction libraries only with no optical recognition.
What does the pdf_oxide pass rate actually measure?
A liveness criterion. The feature table describes the 100 percent pass rate alongside zero panics and zero timeouts, so a pass means the library returned without crashing and without timing out. The seven non-passing files across the corpus are described as intentionally broken fixtures, and the text-quality figure of 99.5 percent is parity against two named competitors rather than accuracy against ground truth.
Does pdf_oxide do OCR, digital signatures and colour management?
All three are optional features that are off by default. The workspace manifest lists a signature stack, a machine-learning and table-detection set including an optical-recognition runtime and a third-party renderer, and a press-grade colour backend among the dependencies a dead-code detector will report as unused because no default feature activates them. The benchmark ran with no optical recognition.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/yfedoseev-pdf-oxide)Star history chart for your README
[](https://hysenlabs.com/projects/yfedoseev-pdf-oxide)Was this useful?