Chinese-LLaMA-Alpaca-3 ships three recipes under one name, and v3 loses long text
Chinese LLaMA-Alpaca 3: the third-generation Chinese Llama-3 LLMs, developed from Meta Llama 3.
At a glance
- What is it?
- The third project in a Chinese adaptation series, open-sourcing 8B base and instruct models plus its training scripts and datasets. The most useful thing on the page is a comparison table that quietly contradicts its own recommendation: the version it tells you to prefer gives up about six points on long-context benchmarks.
- Who is it for?
- This is a well documented model release whose main virtue is that it shows its work: the scripts, the datasets and the per-version benchmark table are all public, and the vocabulary decision comes with the measurement behind it. Two things to weigh before you pick a checkpoint.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Activity is slowing. The repository last received commits 6 months ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
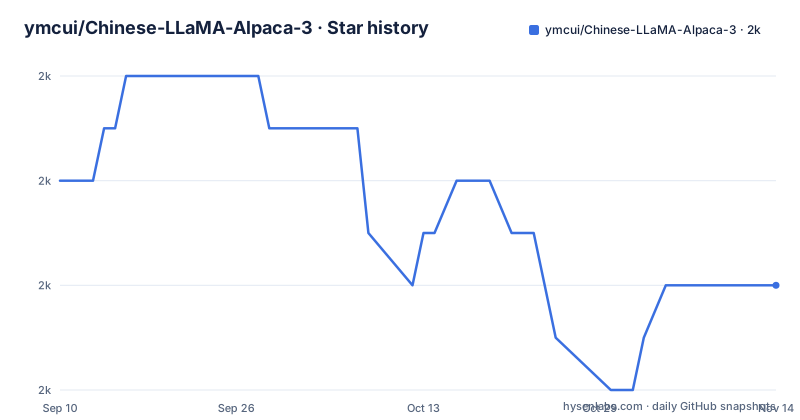
Star history
- ymcui/Chinese-LLaMA-Alpaca-31,978 ★ · -2
| Repository | 2026-09-10 | 2026-11-14 |
|---|---|---|
| ymcui/Chinese-LLaMA-Alpaca-3 | 2k | 2k |
-2 Stars in the last 65 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The recommended checkpoint is the weaker one for long documents
The comparison table carries four numbers per version, and the recommendation contradicts one of them.
On Chinese ability, sourced from a validation split of a Chinese benchmark, the third version leads. On English ability, from a public leaderboard average, it leads by a hair over the second. On an arena win rate and rating, it leads substantially.
On long-text ability, from a long-context benchmark average, it does not. The second version scores in the mid forties, the third in the low forties. That is a gap of roughly six points on the one axis where the earlier version is the better choice.
The guidance above the table says to prefer the third version unless you have a specific preference. So a reader who wants long-document understanding and follows that instruction gets the worse checkpoint, with the table showing it and no note explaining the trade.
The footnote under the table also stamps the arena results with the date they were collected and says they are for reference only, which is the right caveat and applies more broadly than the arena column.
Version three is a merge, not a training run
Read the three training-method cells together and it becomes clear these are three different recipes under one product name.
The first version did two stages: continued pretraining on a large Chinese corpus, then fine-tuning on five million instruction items.
The second version skipped the pretraining stage entirely and fine-tuned directly on the same five million items, starting from the upstream instruct checkpoint.
The third version is described as merging the first, second and an upstream instruct model together, followed by a light fine-tune on a small amount of instruction data, given as roughly five thousand items.
So the version with the best headline numbers is also the cheapest to produce. It is an ensemble of the two earlier checkpoints plus a thousandth of the instruction data, refined briefly.
That is a completely legitimate technique and it is common practice. It is worth knowing because the three checkpoints are not three points on one training curve, and anyone reproducing them needs a different recipe for each.
They measured the vocabulary question and chose not to extend it
The most interesting engineering decision on the page is a refusal, and it comes with its evidence.
The upstream model substantially expanded its own vocabulary, roughly quadrupling it, and switched to a byte-pair encoding scheme. For a Chinese adaptation, the obvious move is to extend that vocabulary again with Chinese tokens, which is what the previous project in this series did.
This project did not. The reasoning given is that preliminary experiments found the upstream vocabulary's encoding efficiency for Chinese to be comparable to their own expanded vocabulary from the previous generation, at around ninety five percent of it, measured as encoding efficiency on Wikipedia data. Combined with what they learned adapting a mixture-of-experts model for Chinese, they chose to keep the original vocabulary untouched.
A footnote cites a paper on rethinking language adaptation, with a case study on a Chinese mixture model. So the decision is traceable to external work rather than asserted.
The cost is that Chinese text still tokenises less efficiently than it could, roughly five percent worse than a vocabulary built for it. For a fixed context that is a small and quantified tax.
The base model got 120GB of Chinese; the instruct models mostly did not
The base and instruct halves of this project have surprisingly different ancestries, and the comparison table is where you find it.
The base model is a causal language model continued-pretrained from the upstream base checkpoint on roughly one hundred and twenty gigabytes of unlabelled general Chinese corpus, using a low-rank adaptation alongside full training of the embedding and output layers.
The first instruct model descends from this project's own Chinese base model, so the Chinese pretraining is in its ancestry.
The second does not. It is fine-tuned directly on the upstream instruct checkpoint using five million labelled instruction items, with no continued pretraining stage at all.
The third is a merge as described, drawing on both instruct models and the upstream instruct model.
So the two checkpoints the page recommends you download, the base for continuation and the third instruct for chat, share the upstream base but not the hundred and twenty gigabytes. If your use case is Chinese text generation from scratch, the base model is where that work lives.
The instruct template changed, so migrating means rewriting prompts
One entry in the technical notes is a migration warning rather than a feature.
The instruct version uses a brand new instruction template that is not compatible with the chat format of the previous generation, and the page says to follow the official template when using it. The comparison table records the same fact from the other side: the base model needs no input template, the instruct model does.
So anyone with an existing pipeline cannot swap the weights and keep the prompts. Prompt formatting has to change too, and a subtle formatting mistake produces bad output rather than an error.
Two other technical notes are inherited rather than original, and both are worth recording because they constrain what you can do. Context length went from four thousand in the previous generation to eight thousand natively, with the page noting that positional interpolation, an alternative scaling method and another named scaling method are available if you need more. And the grouped-query attention mechanism was carried over from the larger previous-generation variants for efficiency.
Both are inherited from the upstream model rather than contributed here.
The project's public arc is six weeks and then silence
The news section is dated and it tells you exactly how long the project was active in public.
It launched on the nineteenth of April 2024. Base and first instruct models followed eleven days later. Training scripts were added seven days after that, the second instruct version the day after, and the third version about three weeks after that. So the entire sequence of public releases took forty one days.
Then nothing. The newest release is dated 2024-05-30, and the most recent push to the repository is dated 2026-04-19. The repository is not archived.
So there is roughly a year and a half of commits with no release, on a project whose public face is entirely its checkpoints and its benchmark table. The distinction matters if you are deciding whether to build on these weights: the model artefacts are fixed at May 2024, and anything in the repository since then is not reflected in a version you can download by name.
The page is candid about its own numbers in the same way, dating the arena figures and calling them for reference.
The dependency file pins one old library and leaves three open
The requirements file is six lines and one of them is worth attention.
There is a floor on the deep learning framework, a floor on the transformers library, and three packages with no version constraint at all. The sixth line is an exact pin on the parameter-efficient fine-tuning library, at a version that predates the transformers floor by a noticeable margin.
An exact pin is the right call for a training script you want to reproduce, and a floor is the right call for a library you want to keep current. The odd combination is having the most important training dependency frozen while the inference stack floats. If a newer version of the fine-tuning library is required by a newer transformers, this file will not resolve.
The intended use is visible in the feature list. The project ships a tutorial for quantising the model and running it locally on a personal machine's processor or graphics card, and it lists support for several local inference engines and for the mainstream transformers ecosystem. That is the audience: someone running it on their own hardware, not a training cluster.
Alongside the models, the repository also ships the pretraining and fine-tuning scripts and three named instruction datasets, which is what makes it useful as a starting point rather than only as a download.
Editorial conclusion
This is a well documented model release whose main virtue is that it shows its work: the scripts, the datasets and the per-version benchmark table are all public, and the vocabulary decision comes with the measurement behind it. Two things to weigh before you pick a checkpoint. The version the page recommends is a merge plus a small fine-tune rather than a fresh training run, so if your use case leans on long documents the table argues for the earlier version instead. And the later instruct models descend from the upstream instruct checkpoint rather than from this project's own Chinese base model, so the large Chinese pretraining run is not necessarily in the weights you would download.
Frequently asked questions
What is Chinese-LLaMA-Alpaca-3?
It is the third project in a Chinese language adaptation series, built on Meta's Llama 3. It open-sources an 8B Chinese base model and an 8B Chinese instruct model, both with an 8K context and the original upstream vocabulary, together with the pretraining and instruction fine-tuning scripts and three named instruction datasets.
Which version of the Chinese-LLaMA-Alpaca-3 instruct model should I use?
The page says to use an instruct model for chat and to prefer the third version unless you have a specific preference. On its own table the third version leads on Chinese ability, English ability and arena rating, while the second version leads on long-text ability by roughly six points, so long-document work argues for the earlier release.
Did Chinese-LLaMA-Alpaca-3 add Chinese tokens to the vocabulary?
No, deliberately. The project reports that the upstream model's expanded byte-pair vocabulary encoded Chinese at about 95% of the efficiency of its own extended vocabulary from the previous generation, measured on Wikipedia data, and chose to keep the original vocabulary unchanged, citing related work on Chinese mixture-of-experts adaptation.
Is the Chinese-LLaMA-Alpaca-3 instruct model built from this project's own base model?
Only the first version is. That one continued from this project's Chinese base model. The second was fine-tuned directly on the upstream instruct checkpoint with five million instruction items and no continued pretraining, and the third is a merge of both earlier instruct models plus the upstream instruct model, refined on roughly five thousand items.
What do I need to train or fine-tune Chinese-LLaMA-Alpaca-3?
A deep learning framework at version 2.0.1 or newer, the transformers library at 4.40 or newer, and an exact pin on the parameter-efficient fine-tuning library, plus three unpinned packages. The repository also ships the pretraining and fine-tuning scripts and lists support for several local inference engines.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/ymcui-chinese-llama-alpaca-3)Star history chart for your README
[](https://hysenlabs.com/projects/ymcui-chinese-llama-alpaca-3)Was this useful?