SearChat ships seven search backends, an alpha Docker image a year behind its newest tag, and three features still marked TODO
Search + Chat = SearChat (AI chat with search). Supports OpenAI/Anthropic/VertexAI/Gemini, DeepResearch, the SearXNG aggregated search engine, and one-click Docker deployment.
At a glance
- What is it?
- SearChat is a self-hosted conversational search engine built as a Turborepo monorepo with a Koa backend and a Vue 3 frontend, where a LangChain and LangGraph research loop runs follow-up searches and emits numbered citations. The deployment instructions are where it gets interesting: the compose file pulls an alpha image from a regional container registry under a different product name, while the manifest sits one version behind the newest release.
- Who is it for?
- This is a reasonable self-hosted starting point if you want to see a research agent wired to real search backends, and the extraction of that loop into a standalone package is the part worth stealing. Three checks before you rely on it.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 75 days ago.
- What is it written in?
- Mainly TypeScript, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
Star history
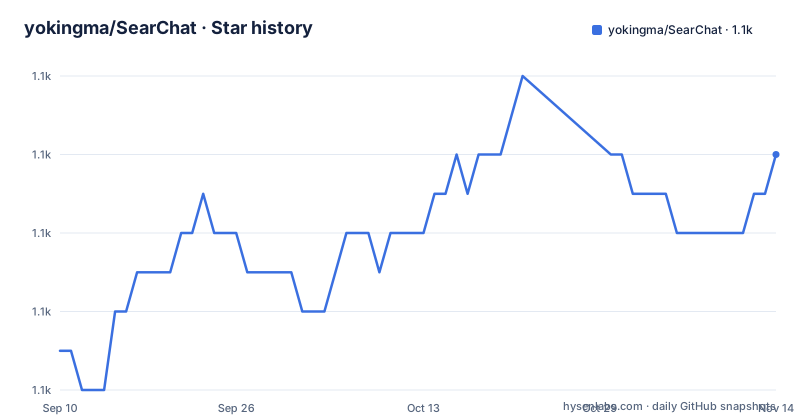
- yokingma/SearChat1,064 ★ · +5
| Repository | 2026-09-10 | 2026-11-14 |
|---|---|---|
| yokingma/SearChat | 1.1k | 1.1k |
5 Stars in the last 65 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The documented image is an alpha build on a regional registry
The deployment section tells you to copy a compose file and edit it, and the image line in that file is the first thing to check. The service is called search_chat, the image is named after a different product and tagged alpha at version 1.2.0, and it is pulled from a regional container registry rather than a public one. The newest tagged release of the source is 1.2.3, so the image everyone is told to run is an older alpha of a differently named artefact. The rest of the environment block is a list of search keys, one each for Bing, Google, a Google custom search identifier, Tavily, Zhipu, Exa and Bocha, plus an optional key for content extraction. Prerequisites also state that SearXNG needs outbound access to Google, so a deployment behind a restrictive egress policy will fail quietly at search time rather than at start time.
Model keys live in a JSON file, search keys live in the compose file
Secrets are split across two files that sit next to each other, and neither is a secret store. Search engine keys go into the compose file as plain environment variables, with placeholder values you are expected to replace. Model credentials go into a separate JSON file created by hand, holding an array of provider blocks. Each block carries a provider name, an API type, a base URL and an API key, and the OpenAI example also sets an API mode that chooses between the chat completions style and the newer responses style. Inside each provider sits a list of models with a name, an alias, a description, a token limit, and one flag worth understanding: a model marked for intent analysis is used for search intent analysis and query rewriting, and the guidance is to put a small model there because it runs on every single query before the main model does.
A separate fast model runs before every query
That flag is the most operationally interesting setting in the configuration and it is easy to skim past. The recommended shape is a small model marked for intent analysis sitting beside the larger model that writes the answer. Intent analysis and query rewriting happen before retrieval, so a slow or expensive model in that slot adds latency and cost to every turn rather than only to the turns that need deep research. The note recommends a smaller model there explicitly, to improve response speed. The rest of the configuration surface is thin: a provider name, an API type that covers the OpenAI, Anthropic and Google shapes, a base URL for anyone running a compatible endpoint, a key, and the optional API mode. Compatibility is claimed for OpenAI, Gemini, Anthropic and Vertex AI, with one hard requirement stated in a callout: the model has to support tool calling, or the results will not be good.
Citations are a rendering contract, not a link
The research mode produces citations in one of two shapes and you choose with a single option. Left at its default, the output emits a superscript containing a numbered reference with the link inline, so the answer text carries markup. Switched off, it emits a bare citation marker with an index and no address, which reads as a footnote reference and leaves the URL out entirely. That default is worth thinking about before you point this at anything that renders untrusted model output, since a model asked to emit inline link markup is a model asked to emit links, and the surrounding application is what decides whether they are safe. The two formats also mean a downstream renderer has to handle both, so switching the flag changes your frontend, not just your output.
The research loop is published separately from the app
The most reusable thing here is not the search interface. The deep research capability is available as its own package on the public registry:
npm install deepsearcherIts constructor takes a search callback you supply, which is the extension point: you return results and the library handles the iteration, the gap detection and the report. Alongside the callback you pass a provider type, an API key and the citation flag. Then the object is compiled once into an agent and invoked with a message list, which reads like a compiled graph rather than a per-request call, consistent with the orchestration library named elsewhere in the readme. Note the naming drift across the whole project: the application is SearChat, the registry package is search_with_ai, the compose service is search_chat, and the published image is a third name entirely. Anyone grepping a log line will need all four.
Three headline features are still open checkboxes
The feature list is written as a checklist, and the last three entries are unticked and labelled as to do: support for external MCP services, image and video search, and document upload with content extraction. That is worth weighing against the pitch, because all three are things a search product is assumed to have. One earlier entry is subtler: deep research mode is checked off but annotated as being refactored, which is a smaller claim than the rest of that section makes about iterative exploration and structured reports. The parts that are done are solid and unglamorous: multi-turn conversational search, history cached in the browser rather than on the server, streaming answers with a typewriter effect, automatic dark and light theme switching, and an internationalised interface. The history point has a consequence, since a conversation kept in browser storage is a conversation that does not follow the user to another machine.
The manifest is one version behind the newest release
The root manifest names the workspace search_with_ai, describes it as ai search chat with node.js, and declares version 1.2.2. The newest tagged release is 1.2.3. So the version in the repository is one behind the newest tag, which is ordinary for a repository that forgets to bump after a release and a real trap for anyone pinning from the manifest. The release dates themselves are uneven: 1.2.1 in early December 2025, 1.2.2 later that month, then 1.2.3 in May 2026, while the most recent commit to the repository is dated 1 September 2026. There is a changelog and a continuous integration directory at the root, along with three readme languages, a configuration file for the container registry that hosts the image, a contributor file whose name is spelled without the middle n, and a chat app QR code image committed alongside the source.
Editorial conclusion
This is a reasonable self-hosted starting point if you want to see a research agent wired to real search backends, and the extraction of that loop into a standalone package is the part worth stealing. Three checks before you rely on it. Pin your image deliberately, because the documented tag is an alpha build on a regional registry while the newest tagged release is newer, and the two do not match. Decide which model does intent analysis, since the configuration has a dedicated slot for it and a slow model there slows every query before the real one starts. And treat the citation format as a rendering contract rather than a feature, because the default emits markup the frontend has to post-process and the alternative loses the link entirely.
Frequently asked questions
What is SearChat and how is it built?
A self-hosted AI conversational search engine on a Turborepo monorepo, with a Node.js and Koa backend and a Vue 3 with TypeScript frontend. It offers multi-turn conversational search over several engines, browser-cached history, streaming answers, and a deep research mode that orchestrates iterative follow-up searches.
Which search engines can SearChat use?
Seven are named: an open source aggregated engine that needs no API key, plus Bing, Google, Tavily, Exa, BochaAI and a free search plugin from Zhipu AI. Prerequisites also note that the aggregated engine needs outbound access to Google, so deployments with restricted egress will fail at search time.
What does the model configuration file control in SearChat?
A hand-written JSON file holding an array of provider blocks, each with a provider name, an API type, a base URL, an API key and a list of models. Each model carries a name, an alias, a token limit and an intent analysis flag; a model with that flag set handles search intent analysis and query rewriting, and the guidance is to use a small one there for speed.
Can I use the SearChat deep research loop without the app?
Yes. It is published separately on the public registry as its own package with a standalone install command. You supply a search callback that returns results, pass a provider type, an API key and a citation flag, compile the object into an agent once, and then invoke it with a message list.
What does SearChat require from the model provider?
The model has to support tool calling, which the readme calls out as required for good results. Compatibility is claimed for the OpenAI, Gemini, Anthropic and Vertex AI API shapes, and for OpenAI-compatible endpoints you can pick between the chat completions style and the newer responses style through an API mode setting.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/yokingma-searchat)Star history chart for your README
[](https://hysenlabs.com/projects/yokingma-searchat)Was this useful?