Follow Builders turns 26 AI builders into one digest your agent writes for you
AI builders digest — monitors top AI builders on X and YouTube podcasts, remixes their content into digestible summaries. Follow builders, not influencers.
At a glance
- What is it?
- An agent skill that pulls a centrally refreshed feed of X posts, podcast transcripts and blog articles, then remixes it into a daily or weekly digest. No content sources to configure, and no way to change them either.
- Who is it for?
- Follow Builders earns its place if you want one scheduled read of the AI scene and do not mind that a fixed list of 26 accounts, 6 podcasts and 2 company blogs is the whole world view, refreshed daily by a server you do not run. Skip it if your interest is a specific person outside that list, if you need the source selection under your own control, or if a skill with no release history and no homepage gives you pause.
- Can I use it commercially?
- Not without permission. GitHub finds no licence file in the repository, and without a licence all rights are reserved by default: you may read the code but not reuse it. Check the README, or ask the authors, before using it.
- Is it still maintained?
- Yes. The repository received new commits within the last day.
- What is it written in?
- Mainly JavaScript, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
Star history
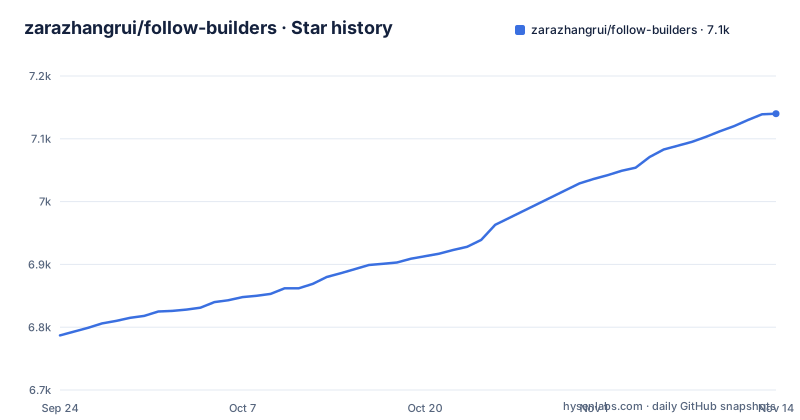
- zarazhangrui/follow-builders7,140 ★ · +353
| Repository | 2026-09-24 | 2026-11-14 |
|---|---|---|
| zarazhangrui/follow-builders | 6.8k | 7.1k |
353 Stars in the last 51 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Setup is a sentence to your agent, not a file you edit
Installation puts a skill directory into your agent and then hands control to a conversation. Once the skill is in place you say set up follow builders, or invoke `/follow-builders`, and the agent runs setup by asking questions. It asks how often you want the digest, daily or weekly, and at what time. It asks what language you prefer. It asks how you want it delivered: Telegram, email, or shown in chat. That is the entire configuration surface, and it is reached by talking rather than by opening an editor.
Changing settings later uses the same channel. You can say switch to weekly digests on Monday mornings, change language to Chinese, make the summaries shorter, or show me my current settings, and the agent updates what it stored. The README is explicit that this is what the conversational route is for.
One promise shapes the first five minutes: your first digest arrives immediately after setup. Read that carefully, because the content behind it can only be as fresh as the last central feed update, which the same document says happens once a day.
The digest reads three JSON feeds your agent pulls once
Follow Builders is a client, and the interesting part runs on somebody else's machine. A central feed is updated daily with content from every source: blog articles collected by web scraping, YouTube transcripts pulled through Supadata, and X posts retrieved with the official API. Your agent then makes one HTTP request against that feed and gets the raw text.
The repository layout shows what that means locally. Four JSON files sit at the root: `feed-blogs.json`, `feed-podcasts.json`, `feed-x.json`, and `state-feed.json`. The first three mirror the three source categories, and the fourth is the cursor or state for the feed. The rest of the tree is small and mostly text: `prompts/` holds the summary instructions, `scripts/` holds the code that npm installs, `config/` is also present, `examples/` holds a sample digest, and `SKILL.md` is the manifest your agent reads.
Two consequences follow, and neither is stated outright. Freshness is bounded by a daily refresh you do not control, so a Tuesday run can hand you Monday's posts. And the endpoint URL for that one HTTP request appears nowhere in the documentation, which means you cannot point the client at your own copy of the feed from what is written down.
Five plain-English prompt files decide the shape of every summary
Where most digest tools hide behaviour in code, this one puts it in Markdown you can read. Five files in `prompts/` control the output, and each one owns a distinct job. `summarize-podcast.md` handles podcast episodes, `summarize-tweets.md` handles X posts, `summarize-blogs.md` handles blog articles, `digest-intro.md` sets the overall format and tone of the digest, and `translate.md` governs how English content becomes Chinese.
That last file is what makes the language setting more than a label: producing English, Chinese, or bilingual output is a prompt change, not a translation service. The files are described as plain English instructions rather than code, and edits take effect on the next digest, with no rebuild step in between.
There are two ways in. The recommended one is conversational: ask for more concise summaries, ask for a focus on actionable insights, or ask for a more casual tone, and the agent rewrites the prompt files for you. The second is direct editing for people who would rather not delegate it. Since the first route lets the agent overwrite the same files the second route edits, keep a copy if you care which version is live.
Delivery credentials sit in a .env file, which the no-keys promise glosses over
The privacy section makes a strong claim and then immediately qualifies it. No API keys are sent anywhere, because all content is fetched centrally and your agent never talks to Supadata or the X API. True, and the useful part of the design: your agent's outbound surface is one feed request.
The qualification is the next line. If you choose Telegram or email delivery, those keys are stored locally in `~/.follow-builders/.env`. So the no-keys statement covers content fetching, not delivery. A Telegram bot token or a mail credential ends up on disk in plaintext, which means the file's permissions are your responsibility, and a mistake during setup leaves a credential sitting in your home directory indefinitely.
The rest of the section is narrower and mostly reassuring: the skill reads only public content, meaning public blog posts, public YouTube videos, and public X posts, and your configuration, preferences, and reading history stay on your machine. Note that last claim covers your side only. The upstream side sees whatever your agent requests from the feed, and nothing in the documentation describes that request.
A fixed roster of 26 accounts, 6 podcasts and 2 blogs, curated elsewhere
The default sources are a closed set, and being in it is the entire selection mechanism. The podcasts number six: Latent Space, Training Data, No Priors, Unsupervised Learning from Redpoint, The MAD Podcast with Matt Turck, and AI & I by Every. The official company blogs number two, Anthropic Engineering for technical deep-dives and the Claude Blog for product announcements.
The X roster is the large half, 26 accounts, running from researchers such as Amanda Askell and Andrej Karpathy through builders such as Peter Steinberger, Dan Shipper, Madhu Guru, and Zara Zhang, plus company accounts like Google Labs and Claude. The stated philosophy is that the list tracks people who build products and hold original opinions rather than accounts that repeat information.
Here is the constraint that matters in practice: the source list is curated centrally and updates on its own, so you get the latest sources without doing anything, and equally you cannot add anyone. If the person whose work you actually follow is absent from those 26, this skill will never mention them, and there is no documented override, allowlist, or per-user source config. Treat the roster as the product's real scope, not as a starting set.
The one-line installer is marked coming soon, so plan on git clone
Two agents are documented, OpenClaw and Claude Code, and both currently install the same way: clone the repository into a skills directory, then install the dependencies in `scripts/`.
For Claude Code:
git clone https://github.com/zarazhangrui/follow-builders.git ~/.claude/skills/follow-builders
cd ~/.claude/skills/follow-builders/scripts && npm install
For OpenClaw:
git clone https://github.com/zarazhangrui/follow-builders.git ~/skills/follow-builders
cd ~/skills/follow-builders/scripts && npm install
The short form exists but is not usable yet. A single command is shown for it:
# From ClawhHub (coming soon)
clawhub install follow-builders
The comment is the author's own, and it matters: treat that path as unavailable. The requirements list is otherwise minimal, an AI agent such as OpenClaw, Claude Code, or something similar, plus an internet connection to reach the central feed. No API keys. Note that npm install is scoped to `scripts/`.
No releases, no homepage, and a repository that is mostly prose
Maintenance signals here are thin, so weigh them before depending on it. The last push to the default branch is dated 2026-11-02, so the work is current. But the repository has no GitHub releases at all, which means there is no version to pin, no upgrade note to read, and no changelog. There is no homepage set on the repository either, and no issue tracker is mentioned anywhere in the documentation.
What you get instead is documentation in two languages, with `README.md` and `README.zh-CN.md` side by side, which is more care than most skill projects show. The licence is stated as MIT in the README, though the repository metadata does not carry a licence field, so if relicensing matters to you that gap is worth raising with the author rather than assuming.
The shape of the tree deserves one last note. The primary language is JavaScript, but the JavaScript lives in `scripts/`, which is where `npm install` is run. Everything else that shapes what you read is Markdown. A pull request that changes a prompt file and a pull request that changes code have very different blast radii, and only one of them is exercised by the install step you just ran.
Editorial conclusion
Follow Builders earns its place if you want one scheduled read of the AI scene and do not mind that a fixed list of 26 accounts, 6 podcasts and 2 company blogs is the whole world view, refreshed daily by a server you do not run. Skip it if your interest is a specific person outside that list, if you need the source selection under your own control, or if a skill with no release history and no homepage gives you pause. Before installing, check which agent you actually run against the two documented paths, read the five files in `prompts/` to see how opinionated the summaries are by default, and decide whether storing Telegram or email credentials in `~/.follow-builders/.env` fits your machine.
Frequently asked questions
How do I set up follow-builders, and do I need API keys?
You install the skill into an agent such as OpenClaw or Claude Code, then say set up follow builders or run /follow-builders, and the agent asks for frequency, time, language and delivery. No API keys are needed for content, but Telegram or email delivery credentials are stored locally in ~/.follow-builders/.env.
Can I add my own X accounts or podcasts to follow-builders?
Not from the client side. The source list is curated centrally and updates on its own, so the roster stays at 26 builders on X, 6 podcasts and 2 official company blogs. What you can change is summary style, either by asking the agent or by editing the plain-English files in the prompts folder.
How fresh is a follow-builders digest when it arrives?
As fresh as the last central feed update, which happens daily. Blog articles arrive by web scraping, YouTube transcripts through Supadata, and X posts through the official API, and your agent then pulls that feed with one HTTP request. Your first digest arrives immediately after setup.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/zarazhangrui-follow-builders)Star history chart for your README
[](https://hysenlabs.com/projects/zarazhangrui-follow-builders)Was this useful?