Apache Druid 38.0: A Real-Time Analytics Database for High-Concurrency Query Workloads
Apache Druid: a high performance real-time analytics database. Consider Druid as an open source alternative to data warehouses for a variety of use cases.
At a glance
- What is it?
- Apache Druid is an open source, Java-based analytics database built for fast ingestion and low-latency queries. This review covers its architecture, setup paths, and the trade-offs you should check before adopting it.
- Who is it for?
- Apache Druid is a strong fit for teams that need fast queries over streaming and batch data behind a UI or for operational ad-hoc analysis, and who can manage a multi-service cluster. It is not a good fit for simple transactional workloads or for teams that want a single-node database with minimal operational overhead.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository received new commits within the last day.
- What is it written in?
- Mainly Java, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 13, 2026, and from our analysis. They are not legal advice.
Star history
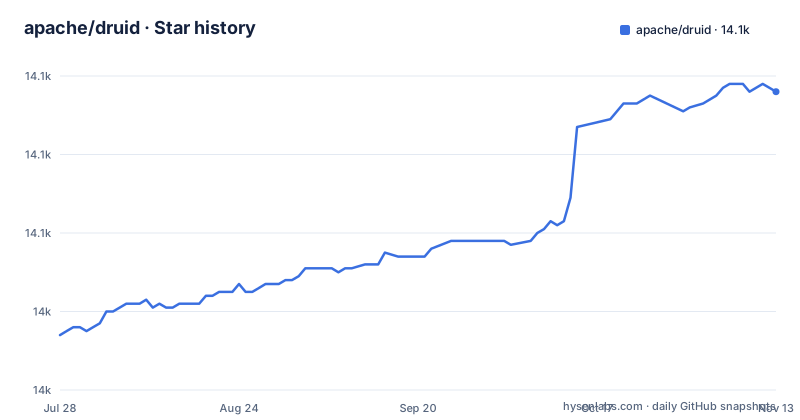
- apache/druid14,096 ★ · +62
| Repository | 2026-07-28 | 2026-11-13 |
|---|---|---|
| apache/druid | 14k | 14.1k |
62 Stars in the last 108 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
What Druid Actually Solves
Apache Druid targets a specific pain point: the gap between a traditional data warehouse and a real-time query engine. The README states that Druid's main value add is to reduce time to insight and action. It is designed for workflows where fast queries and ingest really matter, such as powering UIs, running operational ad-hoc queries, or handling high concurrency. This is not a general-purpose OLTP database. It is an analytics store that trades transactional flexibility for query speed on large, event-driven datasets. The intended user is an engineer building a product that needs to answer analytical questions over fresh data, often with many concurrent users hitting the same dashboards or endpoints.
Architecture: Segments, Services, and the DruidSQL Layer
The repository points to design documentation for the key concepts, but the README itself gives a few concrete architectural markers. The README links segments as one of the things the console shows. The cluster is composed of multiple process types, which the README refers to as services. Ingestion is split between streaming and batch paths, and each is managed by supervisors or one-off tasks. Queries can be issued in two ways: DruidSQL, which is a SQL dialect, and native queries. The web console provides a query workbench to prototype both. The architecture is built around separating ingestion, storage, and query serving, which is typical of distributed analytics systems but adds operational weight compared to a monolithic database.
Getting Started: Local, Docker, and Kubernetes Paths
The README offers three distinct ways to run Druid. For a single-machine evaluation, there is a local quickstart. For containerized setups, a Docker quickstart is available. For production on Kubernetes, the druid-operator is maintained in a separate repository, which implies that the core project does not bundle a native Kubernetes deployment. The README also notes that Druid provides a rich set of APIs via HTTP and JDBC, and the built-in web console is the primary interactive interface. The quickstart tutorials are the entry points, and the documentation is versioned, with the latest official release at druid.apache.org. If you want to build the docs site locally, you need Node 22 or higher and Docusaurus 3, but that is for contributing to docs, not for running Druid.
Ingestion and Query Mechanics
The README describes a point-and-click wizard in the web console that guides you through ingestion setup, for both streaming and batch data. Once data is loaded, you monitor ingestion through supervisors and one-off tasks. The console also gives a view of datasources, segments, and services, all powered by SQL system tables. This means the management UI is not a separate tool; it queries the same metadata that is exposed via SQL. For querying, the workbench lets you prototype DruidSQL and native queries side by side. The existence of DruidSQL is important because it lowers the barrier for teams that already know SQL, but you should verify the exact SQL coverage in the docs.
A Real Limitation: Operational Complexity and Tooling Gaps
Druid is not a single binary. The README references multiple services, segments, ingestion tasks, and supervisors, which implies a distributed system that requires planning. The documentation for architecture and processes is external, but the repository layout confirms that this is a multi-process system. For a small team or a simple use case, the operational overhead of running and tuning these services could outweigh the query performance benefits. Another limitation is that the Kubernetes deployment path is not in the main repository; you must adopt the separate druid-operator, which adds a dependency on a project outside the core release cycle. The README also has a badge disabled until it can be fixed, which is a minor sign that some CI or reporting infrastructure is not fully stable. None of these are fatal, but they are real friction points.
Alternative Approaches: Data Warehouses and Other Real-Time Stores
The README explicitly positions Druid as an open source alternative to data warehouses for a variety of use cases. The difference in approach is that a traditional data warehouse, such as Apache Hive or a cloud warehouse, typically stores data in a columnar format optimized for large scans and complex joins, but it may not offer the same low-latency, high-concurrency serving capabilities that Druid targets. Another alternative is a time-series database like InfluxDB or TimescaleDB, but those are often more specialized for time-series data and may not handle arbitrary analytics or high concurrency as broadly. The key difference is that Druid is built for serving analytical queries to many users, whereas a data warehouse is often designed for batch-oriented reporting. You should evaluate your workload's query latency and concurrency requirements against each system's architecture.
Maintenance, Licensing, and Release Cadence
Druid is licensed under Apache-2.0, which is permissive and allows commercial use without copyleft obligations. The repository is actively maintained, with recent releases including 38.0.0 in October 2026, 37.0.0 in May 2026, and 36.0.0 in February 2026. This three-release cadence over roughly eight months indicates a steady release train. The README mentions that documentation and tutorials are maintained in the /docs directory, and contributions are welcome via pull requests. For upgrades, you should expect to follow the release notes and migration guides in the documentation, as Druid has multiple services that may need coordinated upgrades. The project also has a community page and mailing lists, which are the primary support channels.
Editorial conclusion
Apache Druid is a strong fit for teams that need fast queries over streaming and batch data behind a UI or for operational ad-hoc analysis, and who can manage a multi-service cluster. It is not a good fit for simple transactional workloads or for teams that want a single-node database with minimal operational overhead. Before adopting, verify your query patterns against Druid's segment-based storage and its SQL coverage, and confirm that your data volumes justify the operational complexity. The release cadence (38.0.0 in October 2026) shows active maintenance, but you must plan for the cost of running and tuning multiple services.
Frequently asked questions
how to install apache druid
The README sends you to a local quickstart or a Docker quickstart tutorial instead of printing commands. For Kubernetes it points to the druid-operator, which is maintained in a separate repository.
Which Apache Druid release is current, and when was master last changed?
The most recent release is 38.0.0, published 2026-10-01, after 37.0.0 on 2026-05-08 and 36.0.0 on 2026-02-09. The last push is dated 2026-11-02.
How does Apache Druid let you see what is inside a cluster?
The web console shows datasources, segments, ingestion tasks, and services from one location. Those views are powered by SQL systems tables, and the README says you can see the underlying query for each view.
Does running Apache Druid on Kubernetes require a separate project?
Yes. The README points Kubernetes users to the druid-operator, which is maintained in a separate repository, so the operator release and its Druid pairing have to be checked there.
What does Apache Druid use to load streaming and batch data?
Both kinds of data go through a point-and-click wizard for ingestion setup, and you can monitor one-off tasks and ingestion supervisors afterwards.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/apache-druid)Star history chart for your README
[](https://hysenlabs.com/projects/apache-druid)Was this useful?