Apache Superset: The Open Source BI Platform That Scales From SQL Editor to Dashboard
Apache Superset is a Data Visualization and Data Exploration Platform.
At a glance
- What is it?
- Apache Superset is a Python-based, Apache-2.0 licensed business intelligence platform for data exploration and visualization. This review covers its architecture, setup, limitations, and alternatives, with a focus on whether it fits your engineering team.
- Who is it for?
- Adopt Apache Superset if you need a self-hosted, SQL-first BI platform that integrates with nearly any SQL database and offers a no-code chart builder plus a powerful SQL editor. Skip it if you need fully governed semantic modeling or if your team lacks Python/DevOps capacity to manage upgrades and driver dependencies.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 1 day ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 12, 2026, and from our analysis. They are not legal advice.
Star history
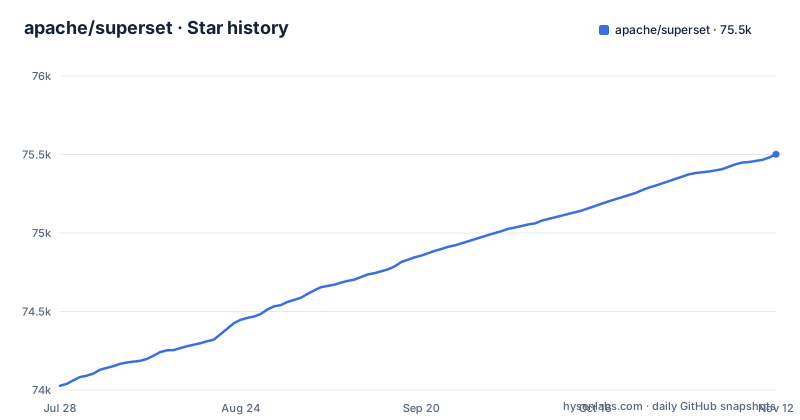
- apache/superset75,501 ★ · +1,474
| Repository | 2026-07-28 | 2026-11-12 |
|---|---|---|
| apache/superset | 74k | 75.5k |
1,474 Stars in the last 107 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
What Superset Actually Solves
Superset targets a specific gap: teams that want business intelligence without paying for proprietary tools or locking themselves into a closed ecosystem. The README states it is a modern data exploration and data visualization platform that can replace or augment proprietary BI tools. It is for analysts who need to build charts quickly without code, and for engineers who want to run advanced SQL queries through a web interface. The platform also provides a lightweight semantic layer for defining custom dimensions and metrics, which is a middle ground between raw SQL and a full semantic modeling tool. If your organization already stores data in a SQL-speaking datastore, Superset gives you a way to turn that into dashboards with minimal setup. The core value is not in the charts themselves, but in the breadth of database support and the ability to iterate from a query to a published dashboard in one tool.
Architecture: Python Backend, SQLAlchemy Everywhere
Superset's architecture is built around Python and SQLAlchemy. The README explains that it can query any SQL-speaking datastore that has a Python DB-API driver and a SQLAlchemy dialect. That means the backend is not tied to a specific database engine. Instead, it relies on the Python ecosystem to provide connectivity. The README also lists an API for programmatic customization. The platform includes a caching layer to reduce database load, and it supports configurable security roles and authentication. The design is cloud-native, which the README describes as designed from the ground up for scale. A web service with supporting components such as a metadata database and cache is more to operate than a desktop tool. The SQL Editor is a first-class feature, not an afterthought, which distinguishes it from tools that only offer drag-and-drop chart builders.
Getting It Running: From PyPI to Helm
The README points to an Administrator Guide for installation, but the repository itself shows the primary distribution is via PyPI as apache_superset. The README directs installation to the Administrator Guide, and the package can be installed with pip. For production, the project also publishes a Helm chart, with recent releases like superset-helm-chart-0.22.8. The Administrator Guide covers installation, configuration, security, scaling and database drivers. The key point is that Superset is not a single binary; it is a service that requires a database and a cache to function.
Database Support: The Long Tail Is the Point
One of Superset's strongest claims is support for nearly any SQL database. The README lists a long series of supported databases, including Amazon Athena, Redshift, ClickHouse, Druid, Hive, Impala, Pinot, Spark SQL, and many others. This is not just marketing: the mechanism is that each database needs a Python DB-API driver and a SQLAlchemy dialect. For an engineer, this means you can point Superset at your existing data warehouse or lakehouse without writing custom connectors. The trade-off is that each database connection requires a Python driver to be installed in the Superset environment. If you need to connect to an exotic database, you may have to install a driver that is not bundled by default. The README also mentions that Superset can query any SQL-speaking datastore, but that assumes the driver exists. In practice, the quality of each dialect varies, and some databases may not support all Superset features, such as time-series functions or geospatial queries. Before committing, you should verify that your specific database version is covered by a maintained dialect.
The Semantic Layer: Lightweight by Design
Superset includes what the README calls a lightweight semantic layer for quickly defining custom dimensions and metrics. The README describes it only as a way to quickly define custom dimensions and metrics. Because it is described as lightweight, it is reasonable to expect it to be thinner than a dedicated semantic modeling tool, so check it against your governance needs. For teams that already have a well-modeled warehouse, this is fine. For teams that expect the BI tool to enforce metric definitions, this is a limitation.
Caching and Performance: A Double-Edged Sword
Superset ships with a lightweight, configurable caching layer to ease database load. The README lists this as a feature, and it is important for production use. This is a real benefit for dashboards that hit expensive queries on large data warehouses. However, caching introduces its own complexity. You must configure the cache backend, decide on invalidation strategies, and handle the case where cached data becomes stale. For a small team, this is manageable. For a large deployment with many dashboards, cache management can become a significant operational task. Plan to load-test your specific queries and dashboard load before scaling out.
Security and Extensibility: Roles, API, and Customization
Superset provides highly extensible security roles and authentication options. The README mentions this as a feature, and it is a key reason why enterprises consider it. The platform also lists an API for programmatic customization, and the repository includes an embedded SDK. This extensibility is a double-edged sword: it gives you power, but it also means you need to understand the underlying security model to configure it correctly. The Administrator Guide covers security. For a team that needs to embed BI into an existing application, the API is a strong draw. For a team that just wants a simple internal dashboard tool, the security configuration may be overkill.
The Wrong Tool and a Real Alternative
Superset is not the right tool for every BI need. If you require a fully governed semantic layer with versioned metric definitions, or if you need a product that offers hosted, zero-ops deployment, Superset will be a burden. It is also not ideal for teams that want a desktop application or a tool that does not require maintaining a Python environment. A real alternative is Metabase, which is also open source and self-hosted. Compare its interface, setup and SQL support against your own needs. If your team is SQL-literate and wants to build custom visualizations, Superset is the better fit. If you need to onboard business users quickly without much training, Metabase is worth evaluating.
Editorial conclusion
Adopt Apache Superset if you need a self-hosted, SQL-first BI platform that integrates with nearly any SQL database and offers a no-code chart builder plus a powerful SQL editor. Skip it if you need fully governed semantic modeling or if your team lacks Python/DevOps capacity to manage upgrades and driver dependencies. Before adopting, verify that your target database has a maintained SQLAlchemy dialect and that your team can handle the operational overhead of a web service with a metadata database and caching layer. Check the current release notes for any breaking changes in the API or security model.
Frequently asked questions
How do I install Superset?
The readme points to INSTALL.md at the repository root and to the Administrator Guide, which covers installation, configuration, security, scaling and database drivers. For containers there are four compose files and two Dockerfiles, and the compose file states that it is not supported for production environments.
How do I use Superset dashboards?
The User Guide is the document for analysts and business users, covering exploring data, building charts, creating dashboards and connecting databases. The readme describes a no-code interface for building charts, a web based SQL editor, and a semantic layer for defining custom dimensions and metrics.
How do I use the Superset API?
The Developer Guide covers building on the REST API and the extension framework, and the feature list includes an API for programmatic customization. The tree also holds an embedded SDK and an extensions CLI, which are the intended seams for building on top of Superset rather than forking it.
Is Superset available as a desktop or mobile app?
Nothing in the readme describes a separate application. Superset is described as a web based business intelligence application, reached through a browser, and the distribution routes it documents are the Python package, the container images and the Helm chart.
How do I install Superset on Ubuntu?
It directs installation to INSTALL.md and the Administrator Guide, and for a container deployment the compose route starts from the repository's docker folder with its own environment file, while pip installs the `apache_superset` distribution, which requires Python 3.11 or newer.
Official sources
Where this project is recommended
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/apache-superset)Star history chart for your README
[](https://hysenlabs.com/projects/apache-superset)Community discussions
Was this useful?