xy: a flat 0.081 seconds at 100 million points, and the control row that explains how
Project brief: Ultra-fast and customizable Python charts. Customize every layer Use Python to control the chart, from marks and axes to interactions and layout.
At a glance
- What is it?
- XY is a Python charting library that renders in a Rust core reached through a plain C ABI, and it publishes one of the more carefully qualified benchmark tables in Python plotting. The headline is a curve that does not move between ten thousand and a hundred million points, and the interesting part is why: above 200k rows it stops drawing markers and draws a density surface instead. The page also ships its own costed control row, which is rarer than the headline.
- Who is it for?
- Read the benchmark table before the marketing line, because the two tell you different things and the table is the more useful one. XY draws a screen bounded density surface above 200k rows and goes back to exact rows when you zoom, which is what produces the flat curve; if you need one marker per row everywhere, this is not the tool that flattens, and the page tells you what that costs, 1.34 seconds and 5.26 GiB at a hundred million points.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 9 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
Star history
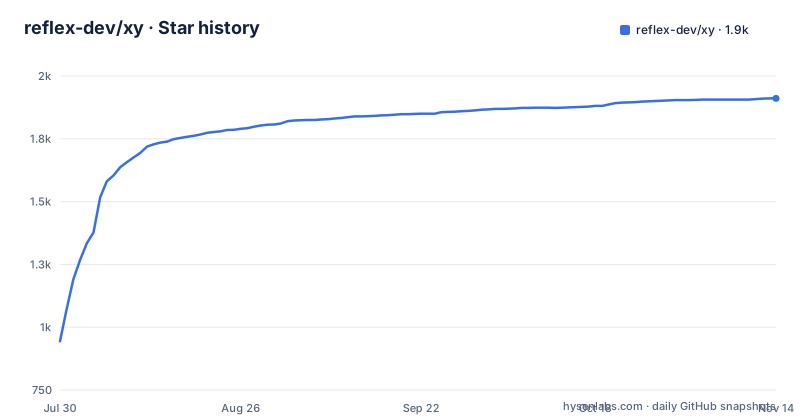
- reflex-dev/xy1,911 ★ · +967
| Repository | 2026-07-30 | 2026-11-14 |
|---|---|---|
| reflex-dev/xy | 944 | 1.9k |
967 Stars in the last 107 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Alpha, a version derived from git tags, and a Rust crate on a different number
The page opens with an important notice in bold: XY is in alpha and is receiving frequent enhancements. Everything else in the repository is consistent with that framing, starting with how you install it. There are two commands on the page and one distribution name, which is short enough to collide with other packages:
pip install xy

# or, with uv
uv add xy
The published releases are v0.0.7, and before it v0.0.7a2 and v0.0.7a1, three tags published on the same day in August 2026. That is an alpha numbering scheme doing what alpha numbering schemes do, and it means there is no stable release to point a dependency at.
The Python package takes its version from somewhere other than the manifest. The project metadata declares the version dynamic, and the build requires a dynamic versioning plugin pinned to a minimum version, which is the mechanism that derives a number from git tags at build time. Two other version numbers exist alongside it and they do not agree with each other. The native Rust crate is at 0.1.0 while the Python package is at 0.0.7. And the release tooling in the build file is pinned to a third number, an alpha of 0.1.0, with a comment explaining that the same version has to appear in two places or a local changelog command and the release workflows would run different pipelines.
That comment is worth reading for what it reveals about the release process: the tool is invoked through a throwaway environment on purpose, so it never becomes a dependency of the development environment. The default branch was last pushed on 2026-10-01, so this is a project with recent commits and an explicitly unstable surface.
The flagship is ten billion points, and the measurements stop at a hundred million
The opening claim is the largest one in the page: with XY, the entirety of OpenStreetMap was rendered, described as a ten billion point data set, with a link to the example that does it. Everything after that is measured against a table whose largest column is a hundred million.
So there is a factor of one hundred between the example the project leads with and the largest size it publishes numbers for. That is not necessarily a problem, since a map at national scale is a different workload from a scatter plot of random points, and the page never claims the table covers the map case. It does mean that the ten billion figure is a demonstration rather than a measurement, and that the flat curve you will read about is established over four orders of magnitude, from ten thousand to a hundred million, not over the five the headline implies.
The table has ten size columns and five rows, and two of those rows are not competitors. One is XY itself, one is XY with aggregation switched off, one is Matplotlib through its web aggregation path, one is Plotly through its scattergl renderer, and the first row is a speedup figure that divides XY by the faster of the two competitors at each size. That speedup row ends at one hundred and seventy seven times at fifty million and then stops, because at the next size there is no competitor number left to divide by.
Above 200k rows it stops drawing markers and draws a density surface
The flat curve has one cause, and the page names it: above two hundred thousand rows XY draws a screen bounded density surface instead of one marker per row, and zooming drills back to exact rows. That is the whole trick, and it is a rendering strategy rather than an optimisation of marker drawing.
The object model underneath it is small, which is worth noting for anyone porting code. A chart is a container plus the marks inside it, any sequence works, and NumPy is optional:
import xy

chart = xy.line_chart(xy.line([1, 2, 3, 4, 5], [120, 180, 165, 240, 310]))
# chart.to_html("chart.html")
# chart.to_png("chart.png")
# chart.to_svg("chart.svg")
chart  # notebooks render it
So the same call renders in a notebook or writes out HTML, PNG or SVG, and the four export paths on the page are three commented calls plus returning the object.
The mechanism is described in the same terms twice. For small charts every point is sent to the browser. For large charts the Rust core computes only what the screen needs to display, based on its resolution. Then, when you pan, zoom, hover or select, full detail appears by running the same process again for the new range, and a selection returns the original rows.
Two consequences follow, and both matter more than the timing. First, the cost is tied to the screen rather than to the data, which is why ten thousand and a hundred million land within a hundredth of a second of each other. Second, the aggregation is not the final answer: a selection hands back the original rows, so a density surface is a display layer over data you can still interrogate point by point.
The interactive parameters make the drill down explicit. In the hundred million point example the scatter call carries a density flag, a colormap, a marker size, a zoom size factor and a zoom opacity, and the comment on those last three says they grow and solidify the markers once a view drills through to real rows. The base view is an aggregate; the moment you zoom past it, markers take over.
The clock stops only when the canvas is correct and stable
Most chart benchmarks stop the clock when the library says it is done. This one does not, and the page is explicit about the stopping condition. The clock stops only when the canvas is both correct and stable: correctness means planted sentinel points were verified as actually lit, and stability means ten byte identical frames in a row. The stated reason is that progressive renderers are charged until their last chunk lands.
That single methodological choice explains most of the results in the table. Each library is given every row and driven through its own input path in a real browser, so Plotly is not fed a cheaper path than XY. And the consequence for the competitors is that their timeouts are not timeouts, they are unfinished work. The page says Plotly never finishes constructing the figure at fifty million, and Matplotlib draws at a hundred million but never resolves the zoom that follows. In the table those cells are marked with a cross rather than a number, and the crossing points are where each library stops: Matplotlib crosses one second at roughly three million and reaches 13.4 seconds at fifty million, Plotly crosses at roughly two and a half million and reaches 9.8 seconds at twenty five million.
The same discipline applies to memory, with a stated boundary. The memory table measures peak resident memory on the Python side and excludes browser memory, on the grounds that a headless Chrome already resides about a gigabyte before drawing anything. So the comparison is between what each library holds in the process you are already running, not between total machine footprint.
The control row is the one worth reading: one marker per row costs 5.26 GiB
The benchmark table includes a row for XY with density switched off, and the page labels it the pale line and explains that it is the same engine drawing one marker per row with no aggregation credit. This is the row most published benchmarks would leave out.
What it shows is that the exact marker path still scales with the data, exactly as the page says. XY with aggregation holds 0.071 seconds at ten thousand points and 0.081 at a hundred million, a range of a hundredth of a second across four orders of magnitude. The same engine without aggregation runs 0.085 seconds at ten thousand and 1.343 seconds at a hundred million, which is a curve in the same shape as everyone else's, just lower. It renders a hundred million exact markers in 1.34 seconds on 5.26 GiB.
So the honest summary of the performance claim is two claims, not one. As an aggregate renderer XY is flat. As an exact marker renderer it is fast but linear, and at the largest measured size it uses more memory than Matplotlib does at fifty million. The memory table shows the same split: XY runs 0.05 to 2.58 GiB across the range, the no aggregation row runs 0.05 to 5.26, Matplotlib runs 0.09 to 3.85 at fifty million, and Plotly 0.21 to 4.70 at twenty five million.
Read together, the two tables say the choice is between a flat curve with drill down, and a linear curve with no aggregation. Both are legitimate, and only one of them is the headline.
Two runtime dependencies, and four libraries deliberately kept out of them
The runtime dependency list is short enough to state in full: numpy and anywidget. That is it, for a library whose description mentions a native Rust core, a binary columnar transport and a GPU render client.
The optional dependency is more interesting than its size. The Reflex extra pins a minimum version of that framework and nothing else, and the comment above it explains why the adapter source still ships in every wheel: so the framework integration and the render client can never drift apart. Importing plain xy stays framework free, and the extra only selects a supported floor. So you get the integration code whether or not you use it, and the extra is a version constraint rather than a feature switch.
The development group then shows the same discipline applied to test-only libraries, with a reason attached to each. Arrow ingest is there because the ingest tests skip themselves when it is missing. Pillow is there as a decode oracle for the native JPEG and WebP encoders, skipped when absent. Starlette is there because the FastAPI drill down example imports it at load time for its callback endpoint, and aiohttp is there because the adapter tests exercise the real socket data plane. Four libraries, four explanations, all of them saying this is not something a user of the package should have to install.
Two version styles appear in that list too. Most entries use floors, and one pins an exact linter version, while another dependency group carries an exact playwright version in the JavaScript manifest.
The core is a cdylib bound through ctypes, which is why the symbol table must survive
The Rust manifest is where the reason for the performance curve becomes structural. The compute core is a single crate that builds as both a shared library and a Rust library, and the comment above that line gives the rationale: the core stays exposed through a plain C ABI, so one shared library per platform covers every version of the interpreter. There is no compiled extension module to rebuild per interpreter version.
That choice has consequences the project writes down in the release profile. Whole program optimisation is on, the code generation unit count is set to one, and symbols are stripped, with a comment explaining that the strip setting is chosen because it keeps the dynamic symbol table, which is what ctypes binds against. So the loader is ctypes, the symbol table is load bearing, and the build is configured with that in mind.
The other profile comment is about failure. Panics must stay unwinding, because the library catches them at the C ABI boundary. That is the right constraint to be aware of when you read the crate: a panic does not cross into the interpreter as a crash, it is caught on the Rust side of the boundary, which means a fault can arrive as an error rather than as a traceback.
The crate also declares exactly one dependency, a png library, and the comment explains the shape of that choice: static chart export uses that crate's fast deflate path, and compression lives next to rasterisation so the hot path never round trips a full framebuffer through Python. The manifest also describes the crate's job in its own words, as zone maps, offset encoded single precision floats, and decimation.
Thirty three make targets, including browser conformance and HTML safety
The build file declares thirty three phony targets for a library that calls itself alpha, and the names describe a verification programme rather than a set of conveniences. There is a fast local gate and a fuller one that adds the JavaScript, Rust and ABI gates. There are browser smokes, and a separate target that runs accessibility and conformance checks across Chromium, Firefox and WebKit. There is a documentation examples target, a canonical API examples target, and one that runs Reflex asset registry checks.
Then the ones that tell you what the project thinks goes wrong. A security target runs standalone HTML safety and client text sink checks. An errors target runs public error, level of detail and mutation safety tests. There is a public API target, a python floor target that implies testing the oldest supported interpreter, an ABI smoke target for the native boundary, and separate distribution and wheel and artifact checks with overridable paths for the built files.
A matplotlib compatibility layer has its own pair of targets, one for the shim and one for its speed, which tells you the pyplot path is a tested feature rather than a convenience import. That shim is the migration story for existing code: you change the import to the pyplot module and keep your plotting calls, including subplots, a formatted plot call, a legend and a show. The page is candid that not all charts and functionality are supported yet, and points at a compatibility guide.
The examples directory gives the range honestly, with entries for a dashboard, a notebook pair, a FastAPI drill down, an OpenStreetMap case, a Reflex integration, a matplotlib shim notebook and a log scale axis notebook, alongside two whose names are worth a second look, a directory called bad apple and an image called exploitbench. Neither is explained on the page. Given the standalone HTML safety checks and the client text sink checks in the same build file, they are the kind of example that exists because something broke.
Editorial conclusion
Read the benchmark table before the marketing line, because the two tell you different things and the table is the more useful one. XY draws a screen bounded density surface above 200k rows and goes back to exact rows when you zoom, which is what produces the flat curve; if you need one marker per row everywhere, this is not the tool that flattens, and the page tells you what that costs, 1.34 seconds and 5.26 GiB at a hundred million points. Four things to settle first. It is alpha, the newest release is v0.0.7 from 2026-08-27, and the branch moved on 2026-10-01, so treat the API as unsettled and pin a version. The matplotlib story is a shim with a compatibility guide and a note that not everything is supported, so migrating an existing figure is plausible and complete coverage is not. The claimed flagship, the whole of OpenStreetMap at ten billion points, sits a hundred times above the largest measured size in the table, so nothing published here measures that case. And the native core is a compiled artifact bound through ctypes, which is worth knowing before you plan a deployment across platforms. If you are plotting in a notebook, moving from matplotlib, or rendering a dataset far past what a browser can hold as individual points, the engineering here is worth reading. If you need a stable plotting library with a fixed API contract and published long term support, this page does not claim to be that.
Frequently asked questions
What does xy stand for in Python and what is it used for?
It is a Python charting library for the web, notebooks and static exports, with a native Rust core that does the drawing and a GPU render client. Charts are composed through Python, and can be customised with Python, CSS or Tailwind, then exported as HTML, PNG, SVG or PDF.
How do I create an XY plot in Python?
Import xy and pass marks to a chart container, for example a line chart wrapping a line with your two sequences. NumPy is optional, and the chart object renders directly in notebooks or exports to HTML, PNG or SVG.
Is xy ready to depend on in production?
The page marks it as alpha and says it is receiving frequent enhancements. The newest published release is v0.0.7 from 2026-08-27, with two earlier alpha tags the same day, and the default branch was last pushed on 2026-10-01.
Can I keep my matplotlib code when moving to xy?
There is a pyplot shim: you change the import and keep the plotting code, including subplots, formatted plot calls, legends and show. The page says not all charts and functionality are supported yet and points to a compatibility guide, and the build file runs dedicated checks for the shim.
What packages does xy require?
Two runtime dependencies, numpy and anywidget. The optional Reflex extra only pins a supported framework floor, because the adapter source ships in every wheel so the framework integration and the render client cannot drift.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/reflex-dev-xy)Star history chart for your README
[](https://hysenlabs.com/projects/reflex-dev-xy)Was this useful?