light-ocr: PP-OCRv6 OCR for Node.js and C++ with Core ML and WebGPU Acceleration
Fast, offline OCR for Node.js & C++. PP-OCRv6 with Core ML / WebGPU hardware acceleration, recognize text in images with confidence scores & coordinates. npm: @arcships/light-ocr.
At a glance
- What is it?
- light-ocr is a fast, offline OCR library for Node.js and C++ that bundles PP-OCRv6 Small, PDFium, and a Chinese fallback font into a single npm package. It runs locally with hardware acceleration on macOS, Linux, and Windows, and returns text with confidence scores and coordinates.
- Who is it for?
- Adopt light-ocr if you need offline OCR in a Node.js application or CLI and want a single install that includes the model, PDF renderer, and fonts. Avoid it if you require Japanese language support, need a C++ API beyond the Node.js bindings, or want to control every dependency.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 36 days ago.
- What is it written in?
- Mainly C++, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 13, 2026, and from our analysis. They are not legal advice.
Star history
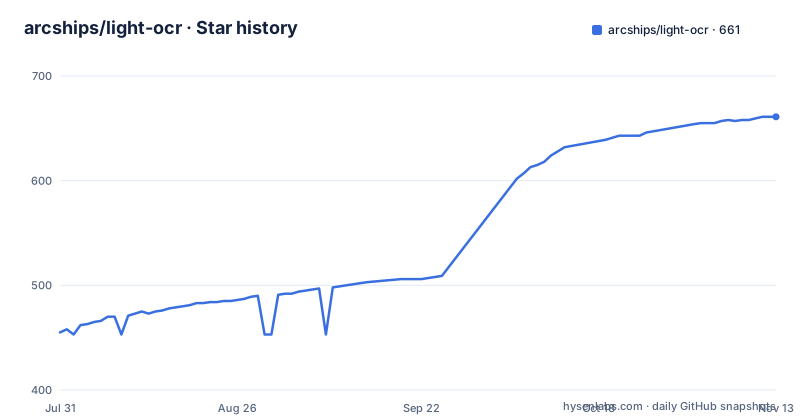
- arcships/light-ocr661 ★ · +206
| Repository | 2026-07-31 | 2026-11-13 |
|---|---|---|
| arcships/light-ocr | 455 | 661 |
206 Stars in the last 105 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
What light-ocr Solves and Who It Is For
light-ocr targets developers who need text recognition inside a Node.js process without sending images to a cloud service. The README positions it for local OCR in Node.js apps, CLIs, desktop software, and native C++ integrations. It handles JPEG, PNG, PDF, encoded bytes, and decoded pixel buffers, returning lines in reading order with confidence scores and quadrilateral coordinates. The project bundles PP-OCRv6 Small, PDFium, and a Chinese fallback font into the npm package, so there are no postinstall downloads or runtime fetches. This makes it attractive for offline environments, air-gapped systems, or applications that must keep documents on the machine. The primary audience is JavaScript developers who want a single dependency rather than a pipeline of separate OCR, rendering, and font packages.
The Core Mechanism: PP-OCRv6 with Auto Hardware Selection
The recognition pipeline is built around PP-OCRv6 Small, a model that the README describes as the stable default. The library exposes an engine object created via createEngine(), which automatically selects an execution mode based on the host platform. On macOS 15+ Apple Silicon, it tries Core ML first, then falls back to CPU. On Linux x64 with glibc, it uses WebGPU through Vulkan, then CPU. Windows x64 uses WebGPU through D3D12. Intel macOS and ARM64 Linux and Windows builds stay on CPU. The execution option lets applications force auto, cpu, apple, or webgpu modes. This design separates the model from the compute backend, which means the same API works across very different hardware stacks. The recognition runs off the JavaScript main thread, supporting queues, cancellation, and explicit cleanup via engine.close().
Getting It Running: Commands and Configuration
Installation is a standard npm install. The README shows npm install @arcships/light-ocr for Node.js 22 and 24. The TypeScript example imports createEngine and recognizeEncoded, reads an image file, and iterates over result.lines to print text, confidence, and box. For decoded pixel data, recognize() accepts GRAY8, RGB8, BGR8, and RGBA8 buffers. PDF handling uses recognizeDocument, which takes a file path or an array of buffers and streams pages with index, lines, and source kind. The CLI is available after install, with commands like light-ocr image.png --format json, light-ocr report.pdf --pages 1-10 --format jsonl, and light-ocr detect image.png for boxes only. A --region option restricts recognition to a rectangle. The doctor command outputs system diagnostics, and info --version prints engine details. Output uses a versioned schemaVersion: 1 contract, and EXIF orientation is corrected automatically.
PDF and Multi-Page Documents: Built-In, Not Bolt-On
PDF support is a notable differentiator. The npm package carries a matching PDFium binary and a checksum-pinned Noto Sans SC fallback font. This means a PDF that references common non-embedded Chinese fonts can be rendered before OCR without a separate install, a system font requirement, or a runtime download. The README emphasizes that there is no postinstall script, compiler, or model download. The document API streams pages, which is useful for large files because you can process pages incrementally. The CLI supports page ranges and JSONL output for streaming. A limitation is that the fallback font only covers common Chinese characters, so PDFs with obscure or non-CJK fonts may not render correctly. Also, the PDF renderer is tied to the platform package, so any mismatch between the PDFium binary and the host OS could break rendering, though the project ships prebuilt binaries for the six supported platforms.
Hardware Acceleration: Core ML and WebGPU, with Caveats
The acceleration story is platform-dependent. On macOS 15+ Apple Silicon, Core ML is the first choice. On Linux and Windows x64, WebGPU is attempted, with CPU as fallback. The README does not provide benchmark numbers, so it is unclear how much faster these backends are compared to CPU. The WebGPU path depends on Vulkan on Linux and D3D12 on Windows, which means the host must have working GPU drivers. On systems without Vulkan or D3D12 support, the library falls back to CPU, so there is no failure, but the acceleration benefit disappears. The macOS re-signing note adds another caveat: if you re-sign the native binaries with your own Developer ID, the loader accepts them only if the code signature verifies and the signing identity matches the host application (same TeamIdentifier or both ad-hoc). This is a security gate that protects against tampering but could complicate distribution for macOS app developers.
Model Tiers: Small, Tiny, and Medium
The default model is Small, which the README calls stable. Two preview tiers exist under the next tag: Tiny, at about 6.3 MB, and Medium, at about 139 MB. All three expose the same API, types, result schema, and error model, so switching tiers only changes the package name and the model payload. Tiny supports 49 languages but not Japanese. Medium is larger and likely more accurate, but the README does not specify its language coverage. The preview status means these tiers may change or have bugs. For production, Small is the safe choice. The size difference is significant: Tiny is 6.3 MB, Small is 30 MB, and Medium is 139 MB. This matters for installation size and memory footprint, especially in serverless or containerized environments. The trade-off is accuracy versus size, but the README does not provide accuracy metrics, so you cannot compare tiers objectively.
Limitations and When It Is the Wrong Tool
The most obvious limitation is the absence of Japanese in the Tiny model. If your documents contain Japanese text, you must use Small or Medium, or another OCR engine. The README also does not mention support for other scripts like Arabic or Devanagari, so language coverage beyond the stated 49 languages in Tiny is unclear. Another limitation is the reliance on prebuilt binaries. The six platform builds cover macOS (Apple Silicon and Intel), Linux x64 and arm64 with glibc, and Windows x64 and arm64. If you need a musl-based Linux distribution like Alpine, or a BSD system, there is no prebuilt package, and the README does not describe a source build process. The C++ integration is mentioned in the description, but the README focuses on the Node.js API, so C++ users may find sparse documentation. Finally, the project is young, with recent releases in July and August 2026, so the API may still change, especially for the preview model tiers.
Alternatives and How They Differ
The main alternative for Node.js OCR is Tesseract.js, which compiles Tesseract to WebAssembly and runs in the browser or Node without native binaries. Tesseract.js uses a different architecture: it does not rely on PP-OCR or hardware acceleration, and it downloads language data files at runtime unless you bundle them. light-ocr's advantage is that it includes everything in the npm package, with no runtime downloads. However, Tesseract.js supports a wider range of languages out of the box, including Japanese, and it runs in the browser, which light-ocr does not claim to do. Another alternative is the native PaddleOCR, which is the Python/C++ origin of PP-OCR. PaddleOCR offers more model options and training capabilities, but it requires a Python environment and a more complex setup. light-ocr's Node.js binding is simpler for JavaScript developers, but it is not a training framework. If you need to fine-tune a model, PaddleOCR is the better choice, not light-ocr.
Editorial conclusion
Adopt light-ocr if you need offline OCR in a Node.js application or CLI and want a single install that includes the model, PDF renderer, and fonts. Avoid it if you require Japanese language support, need a C++ API beyond the Node.js bindings, or want to control every dependency. Verify first that your target platform is in the six prebuilt builds, that your Node.js version is 22 or 24, and that the preview Tiny or Medium model tiers meet your accuracy needs before relying on them in production.
Frequently asked questions
What is light-ocr and what does it return?
light-ocr is an offline OCR engine for Node.js and C++ that recognises text in PDF, JPEG, PNG, or raw image data on your own machine. It returns lines in reading order, and every line carries the recognised text, a confidence score, and quadrilateral coordinates for its position in the original image, plus page metadata and timing.
Does light-ocr download anything after installation?
No. The platform npm package carries the recognition model, the OCR runtime, a PDF renderer, and a checksum-pinned Chinese fallback font, so there is no postinstall fetch, no runtime download, no compiler, no model download, no PDF engine download, and no font download.
Which platforms does light-ocr accelerate on?
Three of the eight prebuilt builds. Apple Silicon macOS on macOS 15 or newer uses Core ML, Linux x86_64 with glibc uses WebGPU through Vulkan, and Windows x86_64 uses WebGPU through D3D12, each falling back to the CPU. macOS on Intel, both Linux arm64 builds, both musl builds, and Windows on arm64 are CPU only.
What Node.js version does light-ocr need?
Node 22 or newer, with the 22 and 24 long term support lines fully tested. Newer versions can load the same prebuilt binaries without a library release, because the project relies on the stable Node addon ABI rather than the version-specific interface.
How do I run light-ocr from the command line?
The command is available after install with no extra setup. The default verb recognises text, detect returns boxes only without recognition, info prints version diagnostics, and doctor prints system diagnostics as JSON. A PDF path routes straight to document handling, and EXIF orientation is corrected automatically.
Which light-ocr model tiers are stable?
The small model is the stable default. The tiny and medium models are opt-in preview packages published under a preview tag. All three expose the same API, types, result schema, and error model, and each install carries only its selected model, and output includes a versioned schema identifier.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/arcships-light-ocr)Star history chart for your README
[](https://hysenlabs.com/projects/arcships-light-ocr)Was this useful?