Synthadoc: A Local-First Wiki Engine That Compiles Knowledge at Ingest Time
Synthadoc: An open-source LLM knowledge compilation engine that turns raw documents into structured, local-first wikis. A transparent, human-readable alternative to traditional RAG, which can be self-managed and self-improved without the use of any tools.
At a glance
- What is it?
- Synthadoc is an open-source Python engine that turns raw documents into a structured, local Markdown wiki using LLMs. It inverts the usual RAG flow by compiling knowledge at ingest time, which makes the wiki itself the browsable artifact.
- Who is it for?
- Adopt Synthadoc if you need a local-first, human-readable knowledge base that does not depend on query-time retrieval and you are comfortable with the AGPL-3.0 license. Skip it if you require real-time updates on every ingest or if your team cannot manage the LLM cost and the occasional contradiction that the engine itself flags.
- Can I use it commercially?
- Yes, with strict conditions. AGPL-3.0 is a network copyleft licence: if people use a modified version over a network, for example as a hosted service, you must offer them its source code under the same licence.
- Is it still maintained?
- Yes. The repository received new commits within the last day.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
Star history
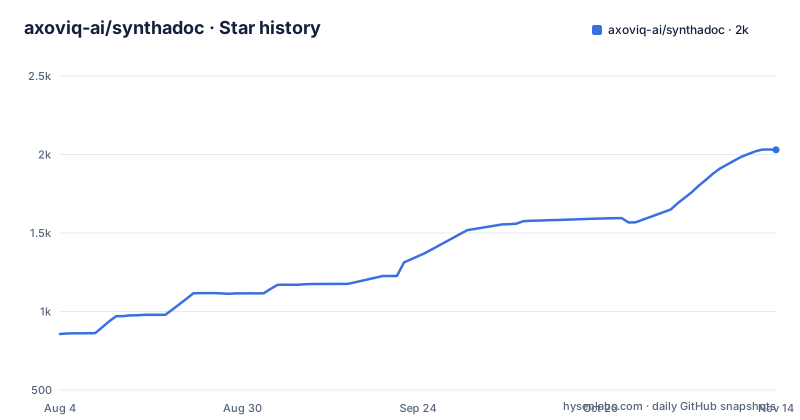
- axoviq-ai/synthadoc2,030 ★ · +1,173
| Repository | 2026-08-04 | 2026-11-14 |
|---|---|---|
| axoviq-ai/synthadoc | 857 | 2k |
1,173 Stars in the last 102 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
What Synthadoc Actually Does
Synthadoc is a Python-based engine that reads raw source documents and uses an LLM to synthesize them into a persistent, structured wiki. The input formats listed in the README are broad: PDFs, spreadsheets, PPTs, web pages, images, videos, Word files, TXTs, and AI session transcripts in .jsonl. The output is plain Markdown files stored locally. The key phrase in the README is that it 'compiles knowledge at ingest time,' which means every new source enriches and cross-links the entire corpus, rather than just appending a chunk to a vector store. The wiki is the artifact: you can browse it, edit it, and back it up with git. No cloud account is required, and there is no vendor lock-in because the output is just Markdown. This is aimed at solo researchers, small teams, and enterprises that need a knowledge base that stays accurate as documents accumulate, with an emphasis on local control and auditability.
How It Differs from Traditional RAG
The README positions Synthadoc as 'a transparent, human-readable alternative to traditional RAG.' Traditional RAG retrieves and summarizes at query time: you store chunks, embed them, and at query time you fetch relevant chunks and pass them to an LLM. Synthadoc inverts that flow. It compiles knowledge at ingest time, so the wiki is the end product, not a retrieval index. This has a couple of implications. First, the wiki is readable and browsable without any tool running. Second, the engine can build cross-references automatically, detect and surface contradictions, flag orphan pages, and ensure every answer cites its sources. That is a fundamentally different trade-off: you pay the LLM cost upfront during ingest, but you get a static, inspectable artifact that does not require a live retrieval pipeline at query time. The README explicitly says this is for 'solo users and enterprises alike,' and the design suggests it is for people who want to audit what the LLM produced, not just trust a black-box retrieval response.
Architecture and Components
The repository layout shows a clear separation of concerns. There is a synthadoc directory with agents and skills subdirectories, a hooks directory, and an obsidian-plugin directory. The README mentions four interfaces: CLI, Obsidian, Web UI, and MCP. The agentic workflows are documented in the user quick-start guide, and there is a hook system for CI/CD integration. The presence of an audit trail for every ingest and cost event is notable for compliance-sensitive environments. The OpenTelemetry integration for ops dashboards suggests it is designed to be monitored in production. The architecture appears to be modular: agents handle the synthesis tasks, skills provide specific capabilities, and hooks allow external automation. The Obsidian plugin indicates that the Markdown output is meant to be consumed in Obsidian, which is a popular local knowledge management tool. The MCP interface suggests it can be connected to Claude via the Model Context Protocol, as mentioned in the quick-start guide's appendix. This is a multi-interface design, but the core is the ingestion engine that produces the wiki.
Getting It Running
The README provides installation and quick-start instructions, but the exact commands are not in the provided excerpt. The table of contents lists 'Installation' and 'Quick-Start Guide' sections, and there is a 'Command Reference by Use Case' section. From the badges, it is clear that the project is on PyPI, so installation is likely via pip install synthadoc. The README mentions running it 'free on Gemini Flash or a local Ollama model with zero ongoing cost,' which implies you need to configure an LLM provider. The configuration section likely covers model selection, API keys, and path settings. The quick-start guide is referenced for creating your own wiki, and there is an end-to-end example using AquaFlow Capital M&A due diligence. That example is probably the best way to see the full flow. The README also mentions an administrative reference and a section on understanding logs and the audit trail. Without the full guide, the safest statement is that the tool is pip-installable, requires an LLM provider, and has a CLI. The presence of a Web UI and MCP suggests there are other ways to interact, but the CLI is the primary entry point.
Limitations and Failure Modes
The most obvious limitation is cost and latency at ingest time. Since every source is processed by an LLM and the entire corpus is enriched and cross-linked, the token usage can be significant. The README acknowledges this by offering a free tier with Gemini Flash or a local Ollama model, but that is not a guarantee of speed. For large corpora, the ingest process could be slow and expensive. Another limitation is the dependence on the LLM's accuracy. The engine detects contradictions and surfaces them, but it does not resolve them automatically. That means a human must review flagged contradictions, which adds operational overhead. The README mentions 'autonomous self-optimization,' but the exact mechanism is not detailed in the excerpt. The AGPL-3.0 license is a real constraint: if you integrate Synthadoc into a proprietary service, you may need to release your modifications under the same license. That is a legal consideration, not a technical one, but it matters for enterprises. Finally, the output is Markdown, which is great for transparency, but it is not a database. If you need complex queries or real-time updates, this is the wrong tool.
Alternatives and How They Differ
The obvious alternative is a traditional RAG pipeline, such as building your own with LangChain or LlamaIndex. The difference in approach is fundamental: RAG retrieves at query time, while Synthadoc compiles at ingest time. With RAG, you can update the index incrementally and query immediately, but the answers are generated on the fly and are not stored as a permanent artifact. With Synthadoc, you get a static wiki that is always up to date with the last ingest, but you have to re-run the ingest to incorporate new documents. Another alternative is a manual wiki like Obsidian itself, where you write and link notes by hand. That gives you full control but no automation. Synthadoc sits in between: it automates the synthesis but leaves the final artifact human-editable. If you need a queryable knowledge base with low latency, a vector database with RAG is likely a better fit. If you need a browsable, auditable knowledge base that does not require a live system, Synthadoc is the more direct match.
Maintenance and Upgrade Cost
The project has a recent release history: v1.3.1 on 2026-08-26, v1.3.0 on 2026-08-19, and v1.2.1 on 2026-08-13. That is a rapid release cadence, which suggests active maintenance. The README mentions a 'document version: v1.3.1,' so the docs are kept in sync with releases. The presence of a CI workflow (visible in the badges) indicates automated testing. The upgrade cost is likely low if you follow the releases, but you should check the changelog for breaking changes. The audit trail and cost events suggest that the tool tracks its own usage, which helps with budgeting. The hooks system allows CI/CD integration, so you can automate the ingest process as part of your pipeline. However, the LLM cost is a recurring operational expense, not a one-time upgrade cost. The license is AGPL-3.0, which means if you modify the code and distribute it, you must share your changes. That is a maintenance consideration for teams that want to fork or extend the project.
Editorial conclusion
Adopt Synthadoc if you need a local-first, human-readable knowledge base that does not depend on query-time retrieval and you are comfortable with the AGPL-3.0 license. Skip it if you require real-time updates on every ingest or if your team cannot manage the LLM cost and the occasional contradiction that the engine itself flags. Before committing, verify that your source formats (PDFs, spreadsheets, PPTs, web pages, images, videos, Word, TXT, and .jsonl transcripts) match the documented ingest list, and test a small corpus to measure the latency and token usage on your chosen model, whether that is a local Ollama instance or a cloud API like Gemini Flash.
Frequently asked questions
Where does Synthadoc store its output?
As local Markdown files that can be opened in Obsidian or any wiki-compliant editor. The page states there is no cloud account involved, that the wiki is plain Markdown you can back up with git, and that a compiled wiki directory ships at the top level of the repository itself.
Which document formats can Synthadoc read?
PDFs, spreadsheets, PPTs, web pages, images, videos, Word files, TXT files and AI session transcripts in .jsonl form. The dependency list covers PDFs with pypdf and pdfminer.six, spreadsheets with openpyxl, presentations with python-pptx, Word with python-docx, pages with beautifulsoup4 and video through youtube-transcript-api.
Which interfaces does Synthadoc provide?
Four, according to the project's own video link: a CLI, an Obsidian plugin, a web UI and an MCP server. The repository carries web-ui/ and obsidian-plugin/ at the top level, and the manifest depends on typer, rich, fastapi, uvicorn and mcp.
What license and Python version does Synthadoc require?
Metadata attached to the repository records AGPL-3.0, while the manifest sets AGPL-3.0-or-later and classifies it as AGPLv3+. The package requires Python 3.11 or newer, builds with hatchling, and is marked with a Development Status 4 - Beta classifier.
Which LLM providers does Synthadoc support?
The declared dependencies include the Anthropic and OpenAI SDKs, and tavily-python for web research. The team table additionally describes running the solo tier on Gemini Flash or a local Ollama model, though neither has a client in the dependency list.
Official sources
Where developers are discussing it
Posts on Hacker News, dev.to and Lobsters that link to this repository, found by our scan of those communities. 2 in the last 30 days; newest first.
- Should our LLM wiki use vector search? We benchmarked it before decidingdev.to · Oct 28, 2026 · 15 points · 16 comments
- Harnessing the Nondeterministic Machine: Practical Lessons in Agentic AI Hardeningdev.to · Oct 16, 2026 · 11 points · 2 comments
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/axoviq-ai-synthadoc)Star history chart for your README
[](https://hysenlabs.com/projects/axoviq-ai-synthadoc)Was this useful?