CnSTD: A Detection-Only Toolkit for Chinese Text, Math Formulas and Page Layout
CnSTD: a Python3 package for Chinese/English scene text detection, mathematical formula detection (MFD) and layout analysis, based on PyTorch/MXNet.
At a glance
- What is it?
- CnSTD wraps DBNet text detection, YOLOv7 math formula detection and a ten-class layout model behind one Python package, with ONNX and PyTorch backends. It detects boxes; it does not read them.
- Who is it for?
- Adopt CnSTD if your pipeline needs bounding boxes for Chinese or English text, inline and isolated math formulas, or the ten layout element classes, and you already have an OCR step such as cnocr for recognition. Do not adopt it if you expect end-to-end text extraction from an image, or if you need a model family the repository does not ship.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 140 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 21, 2026, and from our analysis. They are not legal advice.
Star history
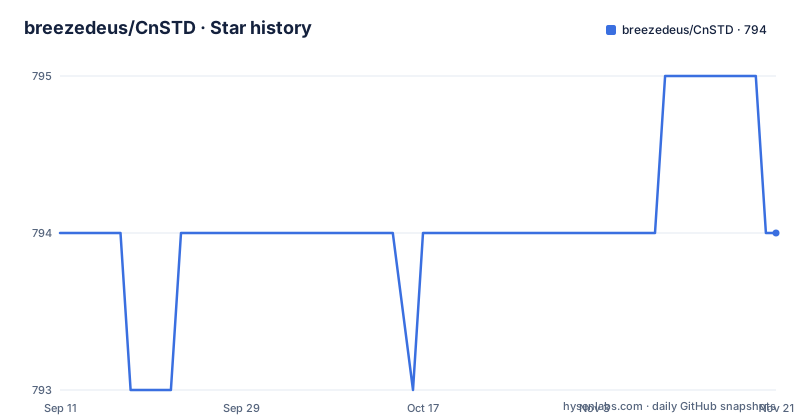
- breezedeus/CnSTD794 ★ · +0
| Repository | 2026-09-11 | 2026-11-21 |
|---|---|---|
| breezedeus/CnSTD | 794 | 794 |
0 Stars in the last 71 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
What CnSTD Detects, and What It Deliberately Leaves Out
CnSTD is a Python 3 package for scene text detection, abbreviated STD in the project's own vocabulary. It takes an image and returns boxes. The README is explicit that text recognition is a separate job: to read the characters inside a detected box you combine CnSTD with the OCR toolkit cnocr, by the same author. That split is the first thing to understand, because it determines whether the package fits your pipeline at all. If your input is a photograph of a sign and your output needs to be a string, CnSTD is one half of the system.
The scope is broader than plain text detection. Since V1.2.1 the package ships a mathematical formula detection model, referred to as MFD, which separates inline formulas (class embedding) from display formulas on their own line (class isolated). A layout analysis model is also included, trained on the CDLA dataset, and it labels ten page elements: Text, Title, Figure, Figure caption, Table, Table caption, Header, Footer, Reference and Equation. The audience is therefore narrower than "anyone doing OCR". It is people building document understanding pipelines for Chinese and English material, where formulas and page structure matter as much as the words.
The Detection Stack: DBNet, YOLOv7 and Two Backends
Current text detection models use DBNet. The README notes that the earlier V0.1 line used PSENet, and that switching to DBNet cut detection time by nearly an order of magnitude while also improving accuracy. Six pretrained DBNet variants are listed, differing mainly in backbone: db_resnet34, db_resnet18, db_mobilenet_v3, db_mobilenet_v3_small, db_shufflenet_v2 and db_shufflenet_v2_small. Parameter counts run from 22.5 M down to 2.0 M, and file sizes from 86 M down to 7.9 M. The README's own timing table gives 3.11 seconds per image for db_resnet34 and 1.24 seconds for db_mobilenet_v3_small, but the note beneath the table warns that the numbers were measured on a local Mac and that only relative values are meaningful. The IoU column carries the same caveat: the calculation method was adjusted, so treat those figures as relative too. The README recommends the MobileNet and ShuffleNet variants for lightweight scenarios.
Formula detection runs on a YOLOv7 model, retrained in V1.2.3 on newly annotated data. The README states that the training code for the MFD model lives in a separate repository, breezedeus/yolov7 on the dev branch, not inside CnSTD itself. Layout analysis is trained on CDLA. So three different architectures sit behind one import.
External Models and the ONNX Path
CnSTD does not only serve its own weights. The README divides available models into two groups: models trained by the CnSTD project, usually shipped in both PyTorch and ONNX form, and models ported from other OCR engines, converted to ONNX and used inside CnSTD. The ported family comes from PaddleOCR. V1.2.6 added PP-OCRv5 detection models, ch_PP-OCRv5_det and ch_PP-OCRv5_det_server, described as faster at inference. V1.2.8 went further with PP-OCRv6 multilingual detection through RapidOCR, adding multi_PP-OCRv6_det_tiny, multi_PP-OCRv6_det_small and multi_PP-OCRv6_det_medium, plus a new --lang-type CLI flag for specifying the language of a RapidOCR v6 model. An earlier release, V1.2.5, had already integrated PP-OCRv4 detection.
This matters for two reasons. First, it means the model you pick may not be a CnSTD-native model, and the maintenance of that weight file belongs to another project. Second, ONNX is a first-class backend, selected with model_backend=onnx according to the README. The package supports it on both CPU and GPU through separate extras.
Installation, Extras and the OpenCV Dependency
The base install is a single command:
pip install cnstd
For ONNX inference on CPU or GPU, the README directs you to install an extra instead:
pip install cnstd[ort-cpu] pip install cnstd[ort-gpu]
There is a trap here that the README calls out directly: if onnxruntime is already installed in the environment, uninstall it first with pip uninstall onnxruntime before running the extra install command. If PyPI is slow, the README suggests a mirror, for example pip install cnstd -i https://mirrors.aliyun.com/pypi/simple.
Two requirements are stated plainly. Python 3.8 or higher. And opencv, which is a dependency but may need to be installed separately depending on your environment. The README's own tone about the install is worth quoting in spirit rather than at length: it says things go smoothly if you are lucky. That is an honest signal that the dependency chain, particularly opencv and the ONNX runtime, is where most setup friction will land.
Where CnSTD Is the Wrong Tool
The clearest failure mode is built into the package's purpose. CnSTD returns boxes, not text. A team that installs it expecting to feed in a scanned page and get back a transcript will find they have half a pipeline and no recognition stage. The README points to cnocr for that, which means a second dependency, a second model download and a second set of failure modes.
The second limitation is model provenance. The README states that the MFD training code is not in this repository; it lives in a fork of yolov7 on a dev branch. If you want to fine-tune formula detection on your own annotated pages, you are leaving CnSTD to do it. The V1.2.3 release notes describe Label Studio scripts in the scripts directory that detect formulas in a folder of images and emit JSON importable into Label Studio, and a reverse script that converts exported Label Studio JSON into the training format. Those scripts bridge annotation and training, but the training itself happens elsewhere.
The third issue is that the performance table is explicitly not trustworthy as an absolute benchmark. The README says the timings come from a local Mac and that only relative values are useful, and that the IoU figures were computed with an adjusted method. Anyone sizing hardware from that table is reading numbers the project itself declines to stand behind.
How It Compares to Using PaddleOCR Directly
The obvious alternative is PaddleOCR itself, and the comparison is not abstract. Several CnSTD models are PaddleOCR models: the PP-OCRv4, PP-OCRv5 and PP-OCRv6 detection weights are ported and converted to ONNX for use inside CnSTD. So for those specific models, CnSTD is a wrapper, and going straight to PaddleOCR gives you the original weights plus that project's own training and export tooling.
What CnSTD adds on top is the parts PaddleOCR does not cover in the same package. The MFD model is CnSTD's own, trained on the English IBEM dataset and the Chinese CnMFD_Dataset, with the two-class embedding and isolated output. The layout model, trained on CDLA, produces the ten element classes. And the DBNet family, with its six backbone variants and the small db_mobilenet_v3_small weight at 7.9 M, is CnSTD-native. The practical difference is this: if you want a single text detection model, PaddleOCR is the source and CnSTD is a convenience layer. If you want text boxes, formula boxes and layout regions from one Python import with one consistent result format, that combination is what CnSTD exists to provide. Note also that the README says detection results were unified to four-point box coordinates from V1.0.0 onward, which is the kind of detail that matters when you are writing downstream code.
Maintenance, Licensing and Upgrade Cost
The repository is active and not archived. Recent releases arrive at a steady cadence: V1.2.8 in July 2026, V1.2.7.3 in May 2026, V1.2.7.2 in April 2026. The changelog shows a mix of new model integrations and small fixes, including a patch to make subprocess calls in the YOLOv7 modules more reliable and a fix for the rapidocr model_root_dir setting. That pattern suggests the project tracks upstream PaddleOCR releases rather than freezing a model set, which is good for freshness and a cost for stability: a model name that works today may be joined by a successor that changes results.
The licence is Apache-2.0, which is permissive and generally compatible with commercial use, but the model weights are a separate question from the code. The README says the directly usable models are hosted on HuggingFace under cnstd-cnocr-models and the breezedeus/cnstd-ppocr-* repositories and are free to download. It also mentions that an earlier MFD YOLOv7 model was released to members of the author's paid community, and that the knowledge community distributes private materials including unpublished models. That is a two-tier arrangement worth understanding before you plan around a specific weight file. Whether a given model's licence and provenance suit your deployment is something to check against the model repository itself; this review is not legal advice.
The upgrade cost is mostly re-validation. When detection weights change, your downstream thresholds and post-processing may need adjustment, and the README's own warning about relative-only benchmark numbers means you should measure on your own images rather than trusting the table.
Editorial conclusion
Adopt CnSTD if your pipeline needs bounding boxes for Chinese or English text, inline and isolated math formulas, or the ten layout element classes, and you already have an OCR step such as cnocr for recognition. Do not adopt it if you expect end-to-end text extraction from an image, or if you need a model family the repository does not ship. Before committing, verify that your Python is 3.8 or higher, that opencv is present, and that the model you intend to use is actually listed in the current model table rather than only in a release note.
Frequently asked questions
What does CnSTD detect?
Three things. Scene text detection, its original task, locating text boxes in images. Mathematical formula detection, which splits formulas inside a line of text into an embedding class and formulas on their own line into an isolated class, trained on one English and one Chinese formula dataset. And layout analysis, which labels ten document element types from body text and headings through figures, table captions, headers, footers, references and equations, trained on a public layout dataset.
How do I install CnSTD?
`pip install cnstd` for the default install. To use the ONNX models, install the matching extra: `pip install cnstd[ort-cpu]` on CPU or `pip install cnstd[ort-gpu]` on GPU, after uninstalling any existing onnxruntime package, since the two cannot coexist. Python 3.8 or higher is required, and the package depends on OpenCV.
Can I fine-tune the PP-OCR models that ship with CnSTD?
No. Those ten models are the ONNX versions of PaddleOCR detectors, so they need no PaddlePaddle packages and cannot be fine-tuned on your own domain data. They do support detection of vertically set text. The package's own DBNet models do have PyTorch versions and are the ones to start from for custom work.
Which CnSTD models are intended for lightweight use?
The MobileNet and ShuffleNet based detectors, which the document recommends for lightweight scenarios. The highlighted small pick is db_shufflenet_v2_small at 3.0M parameters, a 12 MB file, IoU 0.7190 and 1.29 seconds per image. db_mobilenet_v3_small is smaller and faster at 2.0M parameters, 7.9 MB and 1.24 seconds, with IoU 0.7054.
Where do I get the CnSTD models?
They are hosted for free download in the cnstd-cnocr-models repository on Hugging Face and in the corresponding breezedeus/cnstd-ppocr repositories. Since V1.2 the set has two kinds: models trained by the CnSTD authors, normally available in both PyTorch and ONNX, and external models borrowed from other OCR engines and converted to ONNX.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/breezedeus-cnstd)Star history chart for your README
[](https://hysenlabs.com/projects/breezedeus-cnstd)Was this useful?