kotaemon: A Gradio RAG UI You Can Also Import as a Library
An open-source RAG-based tool for chatting with your documents.
At a glance
- What is it?
- kotaemon is an Apache-2.0 RAG application that ships both an end-user chat interface and a Python pipeline developers can import. The interesting part is the split between those two audiences, and the retrieval defaults that sit underneath both.
- Who is it for?
- Adopt kotaemon if you want a self-hosted document QA interface that a non-developer can operate, and you are willing to run the Docker image or a Python 3.10+ environment yourself. Skip it if you need a managed service with a support contract, or if your corpus is mostly .doc and .docx files and you want to avoid the larger full image.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 122 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 13, 2026, and from our analysis. They are not legal advice.
Star history
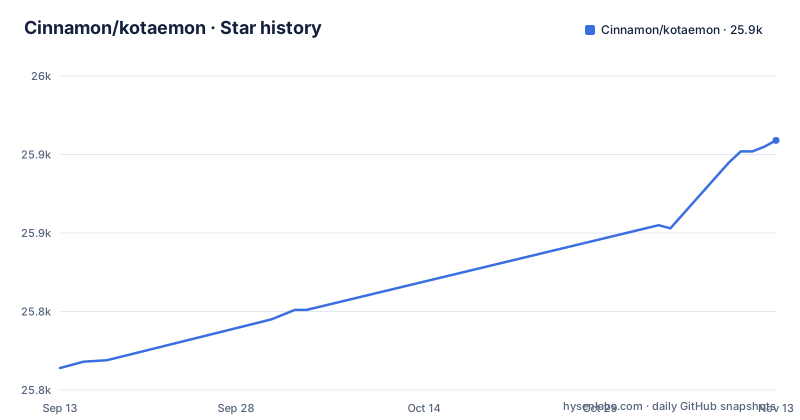
- Cinnamon/kotaemon25,909 ★ · +145
| Repository | 2026-09-13 | 2026-11-13 |
|---|---|---|
| Cinnamon/kotaemon | 25.8k | 25.9k |
145 Stars in the last 61 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The gap between a demo notebook and something a colleague can log into
Most RAG examples end at a script that answers one question about one PDF. The step that gets skipped is everything after that: where do the files live, who can see them, how does a second person use the thing, and how do you check whether the answer was grounded. kotaemon targets that gap. The README describes it as an open-source RAG UI for chatting with your documents, built for both end users and developers, and the repository's own diagram makes the layering explicit: end users use apps built with kotaemon, developers import kotaemon, contributors send pull requests. That three-layer framing is the clearest statement of intent in the README. If you are the person who has been asked to stand up an internal document assistant and you would rather not write the retrieval layer from scratch, this is aimed at you. If you only need a library and have no interest in a UI, you are in the middle layer and should read the developer guide rather than the installation section.
Hybrid retrieval, re-ranking, and why the citations matter more than the chat window
The README states that kotaemon ships a default RAG pipeline using a hybrid retriever that combines full-text and vector search, followed by re-ranking. That is the mechanism to understand, because it determines the quality ceiling of everything above it. Full-text search catches exact terms, identifiers and rare strings that embeddings tend to blur; vector search catches paraphrase. Running both and then re-ranking the merged candidate set is a standard way to avoid the failure mode where a keyword query returns nothing useful. On top of retrieval sits the citation layer: the README says the system provides detailed citations by default, that you can view them with a relevance score in an in-browser PDF viewer with highlights, and that it warns when the retrieval pipeline returns low-relevance articles. That warning is the most consequential feature in the list. A chat interface that confidently answers from weak context is worse than no interface, and surfacing a low-relevance signal at least gives the reader a reason to check. Beyond plain QA, the README lists question decomposition for multi-hop questions and agent-based reasoning with ReAct and ReWOO. Treat those as available strategies rather than defaults.
Running it: Docker tags, Gradio environment variables, and the Unstructured dependency
The README recommends Docker. It publishes both lite and full images, and the README's own guidance is that the lite image works well for most users, while the full image adds the extra unstructured packages needed for file types such as .doc and .docx at the cost of a larger image. The example command sets GRADIO_SERVER_NAME to 0.0.0.0, GRADIO_SERVER_PORT to 7860, mounts ./ktem_app_data into /app/ktem_app_data, and publishes port 7860, pulling from ghcr.io/cinnamon/kotaemon. Those two Gradio variables and the single data volume are the configuration shown in the Docker example, which is worth noting: application state and uploaded files live under ktem_app_data, so that path is what you back up and what you mount from persistent storage. Outside Docker, the system requirements are Python 3.10 or newer and, optionally, Unstructured if you want to process files other than .pdf, .html, .mhtml and .xlsx. The README points to Unstructured's own installation instructions and notes that the steps differ by operating system, which is a real friction point rather than a formality. For non-developers the README directs you to download a .zip from the latest release and follow the user guide, and it also links an online install page and a Colab notebook for local RAG.
Multi-user collections, model providers, and the settings surface
Two features shape what kind of deployment this is. The first is multi-user login with private and public file collections, plus the ability to share a chat. That moves kotaemon out of the single-operator category and into the small-team category, and the .env.example file has an AUTHENTICATION_METHOD setting (Google by default, or KEYCLOAK) with Keycloak server, client and realm settings, alongside sso_app.py at the top level. The second is model flexibility: the README lists API providers including OpenAI, Azure OpenAI, Cohere and Groq, and local execution through ollama and llama-cpp-python. Embedding models are configurable in the same place. There is also a settings UI that the README says exposes most important retrieval and generation parameters, including prompts. For a team testing whether a retrieval change helps, editing the prompt and retriever settings in the interface instead of redeploying is the practical difference between a two-minute experiment and an afternoon. Multi-modal parsing is selectable in the UI, and the README notes QA support for documents containing figures and tables. The README does not quantify how well any of this performs on scanned or poorly structured PDFs, and that is the kind of claim you would need to test on your own files.
Where kotaemon is the wrong tool
The README's own file-type list is the first boundary. If your corpus is dominated by.doc and.docx, you are pushed toward the full Docker image or a manual Unstructured installation whose steps vary by operating system, and that is a heavier setup than the lite path. The second boundary is scale and operations. The Docker example persists a single application data directory. For a department of a few dozen people that may be entirely adequate; for a corpus of millions of chunks with continuous ingestion, verify how indexing and storage scale before committing. Third, kotaemon is an application, not a hosted service. There is no vendor to call, and the project is Apache-2.0 licensed open source maintained by Cinnamon, with releases visible at v0.12.0, v0.11.3 and v0.11.2. If your requirement is a signed SLA, this is the wrong shape of product. Finally, if your real problem is document parsing quality rather than retrieval orchestration, kotaemon sits on top of Unstructured and will not fix parsing upstream of it.
How this differs from wiring LangChain or LlamaIndex into your own front end
The closest alternative is not another RAG UI but the general-purpose framework route: LangChain or LlamaIndex for the pipeline, plus something like Streamlit or Gradio for the interface. The difference in approach is where the work sits. With those frameworks you assemble retrievers, re-rankers and prompt templates yourself, and you get exactly the pipeline you specified, including whatever citation and low-relevance handling you choose to write. kotaemon inverts that. It hands you a working hybrid retriever plus re-ranker and a citation viewer, and the customisation happens at the settings layer and in the Gradio components, with the README noting that the UI is built on Gradio and that you can add or change UI elements, and pointing to a separate kotaemon-gradio-theme repository for theming. The trade is control for time. If your retrieval design is genuinely unusual, a framework gives you the freedom and no ceiling; if it is close to the standard hybrid-plus-rerank shape, kotaemon starts you much further along. A second, narrower alternative worth naming is a pure library RAG toolkit with no UI at all, which is the right pick when the deliverable is an API rather than a page people log into.
Licence, upgrades and what maintenance actually costs
kotaemon is Apache-2.0. That permits commercial use and modification, and it includes a patent grant and a requirement to preserve notices, but this is not legal advice and you should have your own counsel review the terms if you redistribute it or embed it in a product. Practically, Apache-2.0 means the maintenance burden is yours: you run the container, you hold the ktem_app_data volume, and you decide when to move between releases. The visible release history shows v0.11.2, v0.11.3 and v0.12.0 across roughly three months, which suggests active development but also means the settings UI and pipeline defaults can shift under you. Pin a specific image tag rather than tracking latest if you need reproducibility. The upgrade cost is dominated by two things: whether your stored index format is compatible across versions, and whether prompt or retriever defaults changed in a way that alters answer quality. Before upgrading, check the release notes for the version you are moving to and keep a copy of the ktem_app_data directory from before the upgrade.
Editorial conclusion
Adopt kotaemon if you want a self-hosted document QA interface that a non-developer can operate, and you are willing to run the Docker image or a Python 3.10+ environment yourself. Skip it if you need a managed service with a support contract, or if your corpus is mostly .doc and .docx files and you want to avoid the larger full image. Before committing, verify two things from the repository: which Docker tag you are actually pulling, and whether the default hybrid retriever plus re-ranker returns acceptable citations on your own documents, because that combination is the part the README promises and the part you cannot judge from screenshots.
Frequently asked questions
What is kotaemon?
kotaemon is an open-source RAG-based tool for chatting with your documents, described as a clean and customizable RAG interface built with both end users and developers in mind. End users get a web interface for question answering over their files, and developers get a framework for building their own retrieval-augmented generation pipeline plus a customizable UI built with Gradio. The system requirements are Python 3.10 or higher, with Docker optional.
How do I run kotaemon with Docker?
Pull one of three images from GHCR, the lite one, the full one, or the one with Ollama bundled, then run it mapping port 7860 and mounting a volume for application data. The documentation recommends the lite image for most users, and the full image adds unstructured packages for Word documents at a larger image size. After starting, the web interface is at `http://localhost:7860/`, and you select linux/arm64 with a platform flag if you are on a newer Mac.
Which LLMs and embedding models does kotaemon support?
It is compatible with API providers including OpenAI, Azure OpenAI and Cohere, and with local models through Ollama and a local Python binding. The feature list names OpenAI, Azure, Ollama and Groq, and the environment example file adds settings for Mistral and Voyage as well as a local model and a local embeddings model, both of which are given concrete defaults.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/cinnamon-kotaemon)Star history chart for your README
[](https://hysenlabs.com/projects/cinnamon-kotaemon)Was this useful?