trurl: A libcurl-Powered URL Manipulation Tool for Scripts and Pipelines
GitHub describes it as a command line tool for URL parsing and manipulation.. The repository metadata lists Perl as its primary language. The metadata lists the NOASSERTION license. This article stays within the project description and details documented in the GitHub repository README.
At a glance
- What is it?
- trurl is a command line utility from the curl project that parses, edits, and extracts parts of URLs. It is a thin wrapper around libcurl's URL API, aimed at scripting and automation where precision and repeatability matter.
- Who is it for?
- Adopt trurl if you need a scriptable, libcurl-backed way to normalize, transform, or inspect URLs in shell pipelines, especially when you already rely on curl's URL semantics. Avoid it if you need a full browser-grade URL parser with extensive Unicode or WHATWG compliance, or if you cannot meet the libcurl 7.62.0 baseline and the feature-specific version gates.
- Can I use it commercially?
- Check first. The repository uses a licence we do not classify automatically, so read its LICENSE file before any commercial use.
- Is it still maintained?
- Yes. The repository last received commits 14 days ago.
- What is it written in?
- Mainly Perl, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
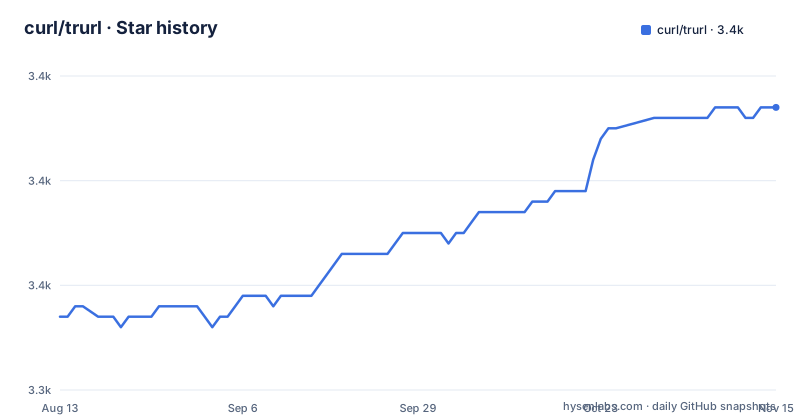
- curl/trurl3,367 ★ · +20
| Repository | 2026-08-13 | 2026-11-15 |
|---|---|---|
| curl/trurl | 3.3k | 3.4k |
20 Stars in the last 94 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
What trurl Solves and Who It Is For
trurl is a command line tool for URL parsing and manipulation. It solves a narrow but recurring problem: turning a URL into a structured object that you can read, modify, and reassemble without writing custom parsing code. Shell scripts, cron jobs, and CI pipelines often need to rewrite a host, strip tracking parameters, or extract a port. Doing that with sed or awk is brittle because URLs contain percent-encoding, default ports, and path normalization. trurl gives you a deterministic interface backed by libcurl's URL parser. It is for developers and operators who work in Unix-like environments and who prefer small, composable tools over pulling in a scripting language dependency. The README's examples show operations like replacing a hostname with `--set host=example.com` and extracting a path with `--get '{path}'`, which are exactly the kind of tasks that appear in automation. It is not a GUI, not a library, and not a server; it is a single-purpose binary that fits into a pipeline.
The Mechanism: libcurl's URL API Under the Hood
trurl is written in C and compiles into a standalone executable that links against libcurl. It does not implement its own URL parser; it delegates to libcurl's URL API, which was introduced in libcurl 7.62.0. That means every URL trurl processes is parsed and serialized using the same code that curl uses for its network operations. The README explicitly lists the minimum libcurl version as 7.62.0, and it notes that newer features require newer libcurls. For example, punycode support needs libcurl 7.88.0, and punycode2idn needs 8.3.0. The tool's behavior is therefore a direct function of the libcurl it is built against. When you run `--set host=example.com`, trurl calls the libcurl URL setter for the host component, then re-serializes the URL. When you run `--get '{port}'`, it asks libcurl for the port component, which returns the default port (443 for HTTPS) if none is explicitly present. This design means trurl inherits libcurl's quirks and its normalization rules, which is both a strength and a constraint. The README points to a URL-QUIRKS.md file for details on how missing features affect behavior. For instance, with an older libcurl, the `--zone-id` feature will not work, and trurl will not fail loudly; it will simply not perform the intended operation.
Getting trurl Running: Build, Install, and Dependencies
Compiling trurl on Linux is straightforward if you have a C compiler and libcurl development files. The README shows the build process with make. The output of the build command is a binary named `trurl` that you can place anywhere in your PATH. The prerequisites are the development headers for libcurl, such as `libcurl4-openssl-dev` or `libcurl4-gnutls-dev`. You need libcurl 7.62.0 or newer to get the URL parsing API. The README notes that trurl also uses `CURLUPART_ZONEID` from libcurl 7.81.0 and `curl_url_strerror()` from 7.80.0, so for full functionality you need a libcurl newer than 7.81.0. The compatibility table lists the minimum libcurl version for each feature: `imap-options` needs 7.30.0, `normalize-ipv` needs 7.77.0, `white-space` needs 7.78.0, `url-strerror` needs 7.80.0, `zone-id` needs 7.81.0, `punycode` needs 7.88.0, `punycode2idn` needs 8.3.0, and `no-guess-scheme` needs 8.9.0. The README also says that trurl can build with older libcurl versions, but it will not work as well. To check what your build supports, run `trurl --version`, which prints both the trurl version and the libcurl version it was built with. On Windows, the README suggests using Cygwin, installing curl, libcurl-devel, libcurl4, make, and gcc-core, then running make the same way as on Linux.
Core Operations: Set, Append, Get, and Query Trimming
trurl's command line interface is built around a small set of verbs. `--set` assigns a value to a URL component, like `--set host=example.com` or `--set port=8080`. `--append` adds a path segment or a query parameter, as in `--append path=you` which turns `https://curl.se/hello` into `https://curl.se/hello/you`. `--get` extracts a component using a template syntax like `{path}` or `{port}`, and it can also fetch a specific query key with `{query:a}`. The README shows that `--get '{port}'` on `https://curl.se/we/are.html` returns `443`, which is the implicit default port for HTTPS, not a literal port in the URL. That is a useful behavior for scripts that need to know the effective port. `--sort-query` reorders query key/value pairs alphabetically, which is handy for generating canonical URLs. `--qtrim` removes query tuples that match a pattern, such as `--qtrim "utm_*"` to strip tracking parameters. The tool also supports `--redirect` to resolve a relative URL against the base, and `--query-separator` to handle semicolon-separated queries, as shown in the example that trims a search key from a URL using a semicolon separator. These operations are the bread and butter of URL manipulation, and trurl makes them composable on a single command line.
Input Handling and JSON Output
trurl accepts a URL directly as a positional argument, or it can read from a file with `--url-file`. The README shows piping a list of URLs from stdin with `cat urllist.txt | trurl --url-file -`. That makes trurl suitable for batch processing. For each URL, trurl can output the result as plain text or as JSON. The `--json` flag produces an array of objects, each containing the resulting URL and a `parts` object with the parsed components. The example in the README shows how a URL with a userinfo component is serialized: `--set user=::moo::` results in `https://%3a%3amoo%3a%[email protected]/hello#frag`, and the JSON `parts` object lists `scheme`, `user`, `host`, `path`, and `fragment`. Note that the `user` field in JSON contains the raw value `::moo::`, while the URL itself percent-encodes the colons. That is a subtle but important detail: trurl preserves the decoded component in the JSON output, which is useful for further processing. The JSON output is an array, which suggests that when multiple URLs are processed, you get a single JSON array containing all results. This is convenient for feeding into jq or other JSON tools. The README does not show an example of multiple URLs with JSON, but the array structure implies it.
Limitations and Failure Modes
The most significant limitation is that trurl is only as good as the libcurl it is linked against. If you build against an older libcurl, features silently degrade. The README says that trurl builds with libcurl older than 7.81.0 but will not work as well, and it directs you to URL-QUIRKS.md for details. That means a feature like `--punycode` might be a no-op on a system with libcurl 7.80.0, and you would not get an error unless you check the version. Another limitation is that trurl does not implement a full URL standard on its own. It follows libcurl's parsing rules, which may differ from the WHATWG URL specification. For example, libcurl's handling of spaces in URLs requires an explicit `--accept-space` flag, as shown in the README. That is a deliberate choice, but it means trurl will reject or misparse URLs that other tools might accept. The README also shows that `--query-separator` is needed for semicolon-separated queries, which are not standard but appear in some legacy systems. If you feed trurl a URL with a malformed component, it will likely fail or produce unexpected output, but the README does not document specific error messages. Finally, trurl is a command line tool, not a library, so you cannot call it from within a program without spawning a process. For high-volume URL processing, that overhead might be a problem.
Alternatives and How They Differ
The obvious alternative is to use Python's `urllib.parse` module, which is built into the standard library and offers functions like `urlparse`, `urlunparse`, and `urlencode`. The difference in approach is that Python's parser is a separate implementation with its own rules, not tied to libcurl. For example, Python's `urlparse` does not normalize default ports or percent-encode userinfo the same way that libcurl does. If you need consistency with curl's behavior, trurl is the better match. Another alternative is `jq` for JSON manipulation, but jq is not a URL parser; you would need to combine it with another tool. There is also the `url` command from the `url-python` package, but that is a different ecosystem. The key difference with trurl is that it reuses libcurl's battle-tested parser, which means the output is predictable for anyone who already understands curl's URL handling. If you are in a shell environment and do not want to write a Python script, trurl is a lightweight option. However, if you need to do complex URL transformations that involve multiple steps, a scripting language might be more expressive. The trade-off is between a single-purpose binary and a general-purpose language.
Maintenance, Upgrade Cost, and Licensing
trurl is maintained as part of the curl project, and the repository shows regular releases, with version 0.16.1 pushed in May 2025. The README does not specify a release cadence, but the version numbers indicate active development. The upgrade cost is low because the tool is a single C file that compiles with make, and the only external dependency is libcurl. However, upgrading libcurl on your system can change trurl's behavior, because new libcurl versions may add features or alter parsing quirks. The README warns about this with the URL-QUIRKS.md file. The license is listed as NOASSERTION in the repository metadata, which is unusual. The README itself contains an SPDX-License-Identifier: curl, but that is not a standard OSI license identifier. The project's homepage is on curl.se, and the curl project typically uses a MIT-like license, but you should verify the exact license terms in the repository before using it in a commercial product. The README does not provide a COPYING file or a license section, so the licensing situation is not fully documented. That is a point to check before adoption.
Editorial conclusion
Adopt trurl if you need a scriptable, libcurl-backed way to normalize, transform, or inspect URLs in shell pipelines, especially when you already rely on curl's URL semantics. Avoid it if you need a full browser-grade URL parser with extensive Unicode or WHATWG compliance, or if you cannot meet the libcurl 7.62.0 baseline and the feature-specific version gates. Before deploying, verify your libcurl version with `trurl --version` and test edge cases like spaces, semicolon queries, and punycode, because trurl's behavior depends directly on your libcurl build.
Frequently asked questions
what is trurl exe
trurl is the curl project's command line tool for parsing and manipulating URLs, a single C file built against libcurl. The README documents building it with make on Linux and through Cygwin on Windows, and the tree also carries a CMakeLists.txt and a winbuild directory that the install section never mentions.
How do I build trurl from source?
Run `make`, which compiles trurl.c and links it against libcurl; you need the libcurl development files and 7.62.0 or newer, the first release with the URL parsing API. On Windows the README walks through installing Cygwin with the curl, libcurl-devel, libcurl4, make and gcc-core packages, then the same make command.
Why does my trurl build fail on a warning?
Because the Makefile adds `-Werror` whenever NDEBUG is not defined, so a plain make treats warnings as errors. The transcript in the README shows only `-W -Wall -pedantic -g`, while the Makefile adds conversion, shadow, cast-qual, declaration-after-statement, write-strings, missing-prototypes and missing-noreturn on top.
Which libcurl version does trurl need?
7.62.0 or newer to compile, and the compatibility table maps eight features to minimum versions from imap-options at 7.30.0 up to no-guess-scheme at 8.9.0. URL-QUIRKS.md covers the behaviour when a feature is missing, and `trurl --version` reports what a given build supports.
Does trurl work natively on Windows?
The README documents Cygwin rather than a native build: install the Cygwin packages, optionally add its bin directory to PATH, and run make as on Linux. A `winbuild/` directory and a CMakeLists.txt both exist in the tree without being mentioned in the install section.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/curl-trurl)Star history chart for your README
[](https://hysenlabs.com/projects/curl-trurl)Was this useful?