The doc search starter keeps its knowledge base in the Next.js router directory and re-embeds on every build
Template for building your own custom ChatGPT style doc search powered by Next.js, OpenAI, and Supabase.
At a glance
- What is it?
- A Supabase template that chunks .mdx files from the pages folder, stores 1536-dimension embeddings in pgvector behind a checksum table, and answers from the text completion endpoint, with dependencies pinned to a 2023 era and no releases at all.
- Who is it for?
- This template is still the shortest honest path from a folder of markdown to a working retrieval-augmented search, and its incremental design is sound: a checksum per file means unchanged docs cost nothing. Two things to check before building on it.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Activity is slowing. The repository last received commits 6 months ago.
- What is it written in?
- Mainly TypeScript, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
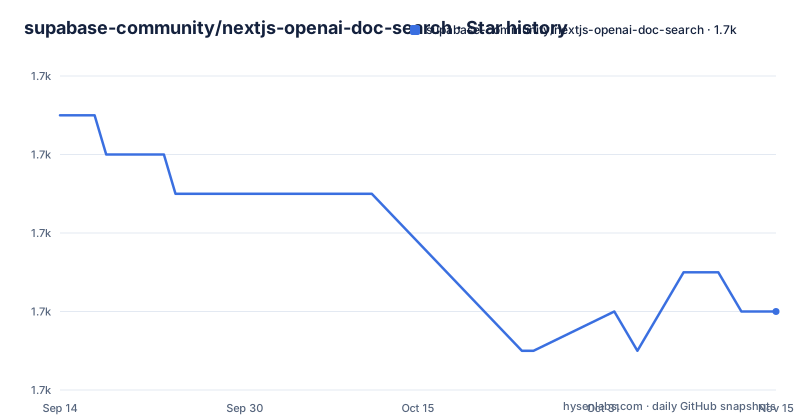
Star history
- supabase-community/nextjs-openai-doc-search1,726 ★ · -5
| Repository | 2026-09-14 | 2026-11-15 |
|---|---|---|
| supabase-community/nextjs-openai-doc-search | 1.7k | 1.7k |
-5 Stars in the last 62 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The knowledge base is the router directory
The starter takes every `.mdx` file in the `pages` directory and uses it as context. That directory is not a separate content folder; it is the one Next.js routes from. The files that become your documentation are simultaneously the files that become pages, and the instruction for adopting an existing site is to rename compatible `.md` files to `.mdx`.
The runtime half lives in the same tree. The search endpoint is `pages/api/vector-search.ts`, an edge function, and the client that calls it is a `SearchDialog` component. The dialog is built from a Radix dialog primitive and the cmdk command palette library, so the interface a user meets is a command palette rather than a chat window, which is a deliberate difference from the ChatGPT styling the repository name suggests.
The database side is initialised from SQL migrations under `supabase/migrations`, and those are applied automatically to a local Postgres instance when you run the Supabase CLI. The extension setup for pgvector lives in that same migration set, so the vector column and its index exist before the first embedding is written.
Every production build re-checks every file against the embedding API
The build script is two commands joined: it regenerates embeddings and then runs the Next.js build. The regeneration is incremental, and the mechanism is a second database table. The build-time script computes a checksum for each `.mdx` file and stores it, so embeddings are only produced again when the file's content has actually changed.
Two consequences follow. First, a production deploy is not free of OpenAI usage: any file whose checksum is new gets embedded during the build, and the vector size is fixed by the contract the diagrams state, a 1536-dimension vector returned for each section. Second, the cache lives in the database, not on disk, so a project pointed at a fresh Supabase instance has an empty checksum table and pays for the whole corpus on its first build. The same applies after wiping a local database.
There is a forced path as well. A second script passes a refresh flag to the generator, which regenerates regardless of the checksums, and the documentation tells you to run the ordinary script and then start the development server again, because the dev server does not generate embeddings on its own.
The query is embedded by one endpoint and answered by another
The runtime sequence has two distinct calls into the OpenAI API, and they use different endpoints. On the way in, the edge function asks for an embedding of the user's question, receives a 1536-dimension vector, and uses it for a similarity search against pgvector. On the way out, it sends the retrieved content as context in a completion request and streams the answer to the client.
So the retrieval side and the generation side are not the same model family, and the generation side is a text completion rather than a chat call. The documentation links that step to the platform's text completion guide and the build-time description labels the target as GPT-3. The pinned dependencies match that era: the main SDK and an edge-specific build of it, plus a tokenizer package named for GPT-3, alongside Vercel's own AI SDK at version 2.
One detail of the diagram is worth recording, because the reader has to infer it. The runtime sequence diagram ends on its final arrow with the label for the completion request cut off partway through the word. Everything up to that point is drawn, and the last step is not.
The chunker is an mdast pipeline rather than a text splitter
The build-time step is described as chunking the `.mdx` pages into sections, and the dependency list shows how that is done. The parser side brings in mdast utilities for reading markdown, for handling MDX nodes specifically, a micromark extension for MDX JSX syntax, and the unist builder and filter utilities for walking the resulting tree. On the output side there are utilities for serialising back to markdown and for flattening a node to a plain string, plus a slugger for generating heading anchors.
What that buys is that the embedding unit is a structural section of a document, defined by its place in the parse tree, rather than a fixed character window. Headings produce identifiers, code blocks and lists stay intact inside their section, and the flattened string that gets embedded is the text of one node. For a documentation site that is the difference between retrieving a coherent section and retrieving half a sentence.
It also means the input format is a hard requirement rather than a preference. A `.md` file has to become `.mdx` before it can be chunked this way, which is exactly the renaming step the setup instructions ask for.
The deploy button is an empty link and one configuration bullet is broken
The Deploy section is one paragraph followed by a link with nothing in it. The paragraph is the useful part: deploying to Vercel triggers the Supabase integration, which sets the required environment variables and applies the database schema from the migration file, leaving you to supply one key and nothing else.
The configuration list below has a mangled third bullet. It reads as an instruction to set the anon key and the service role key and then trails off into the word run before the note about needing to run Supabase to retrieve them. The intent is recoverable from the commands around it. Copy the example environment file to `.env`, put your OpenAI key in it, and get the two Supabase values from the CLI.
The example environment file is more informative than the README here. It ships the Supabase URL already filled in as the local development default, `http://localhost:54321`, and leaves both keys blank, with a comment pointing at the CLI for local values and at the project's API settings page for hosted ones. Local development needs the Supabase CLI running with Docker available, and the two commands that matter are:
supabase startto bring the stack up, and
supabase statusto print the keys it generated. The development server itself is then started with a third command in its own terminal window, `pnpm dev`.
A public key and a full-privilege key share one template file
Four variables are required. One is the Supabase URL. Two are keys: an anon key that carries a `NEXT_PUBLIC_` prefix and a service role key that does not. The fourth is the OpenAI key.
That naming convention is the only thing standing between the two keys. A `NEXT_PUBLIC_` variable is inlined into the JavaScript bundle and is visible to anyone who loads the page, which is what makes the anon key safe to ship. The service role key is the one that must never reach the browser, and in this template its consumer is the search edge function, which is where the vector similarity query actually runs. The example file lists them on adjacent lines with no comment distinguishing them, and the README's configuration note does not repeat the distinction.
The OpenAI key is described as the only thing you have to set before a Vercel deploy, because the Supabase integration handles the rest. That is convenient, and it also means the embedding and completion calls for a production deployment are billed to whoever supplied that single key, on every build that changes a document.
No releases, a private package, and one era of dependencies
The repository has no published releases at all, and the package manifest marks itself private at version 0.1.0 with no changelog to speak of. That is what a template looks like rather than a library, and it means there is no upgrade path other than editing the dependencies yourself.
The pinned set is worth reading before you start. Next.js and its ESLint configuration are both at 13.2.4, React and React DOM at 18.2.0, TypeScript at 4.9, ESLint at 8.36.0, and the Node type definitions pinned to an exact 18.15.10 rather than a range. Supabase's JavaScript client and Radix are on caret ranges, so those move with a fresh install while the framework does not.
The last push to the default branch is dated 2026-05-12. Whatever state the tree is in, it is the state as of that date, and nothing in the repository records which versions it was tested against beyond what the manifest pins.
Editorial conclusion
This template is still the shortest honest path from a folder of markdown to a working retrieval-augmented search, and its incremental design is sound: a checksum per file means unchanged docs cost nothing. Two things to check before building on it. The whole toolchain is pinned to Next.js 13.2.4 with React 18.2.0 and TypeScript 4.9, and the last push is dated 2026-05-12 with no published releases, so you own the upgrade path. The embedding pipeline also assumes a fixed 1536-dimension vector, which is a database column width as much as an API contract.
Frequently asked questions
What does the nextjs-openai-doc-search starter build?
A ChatGPT-style search over the .mdx files in the pages directory. At build time those pages are chunked into sections and embedded into Postgres through pgvector; at query time an edge function embeds the question, runs a similarity search, injects the matching content into an OpenAI text completion prompt and streams the answer.
Where are the embeddings stored and how are they kept up to date?
In Postgres using pgvector, with the schema created by the SQL migrations under supabase/migrations that run when you execute supabase start. A second table holds a checksum per .mdx file, so embeddings are regenerated only for files whose content changed, and a refresh flag forces a full regeneration.
How do I search my own documentation with it?
Put the files in the pages directory as .mdx, renaming compatible .md files. With Supabase running, run pnpm run embeddings, then run pnpm dev again to refresh the page on localhost:3000. The dev server on its own does not generate embeddings.
Which environment variables does the starter need?
NEXT_PUBLIC_SUPABASE_URL, NEXT_PUBLIC_SUPABASE_ANON_KEY, SUPABASE_SERVICE_ROLE_KEY and OPENAI_KEY. The example file ships the URL already set to http://localhost:54321 and leaves the keys empty; local values come from supabase status, and hosted keys from the project's API settings page.
Can I run it locally without a hosted Supabase project?
Yes, with Docker installed and running. supabase start brings up the local stack and applies the migrations including the pgvector setup, and supabase status prints the anon and service role keys you need. The README links the design to a Supabase blog post on building ChatGPT for their docs.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/supabase-community-nextjs-openai-doc-search)Star history chart for your README
[](https://hysenlabs.com/projects/supabase-community-nextjs-openai-doc-search)Was this useful?