facebookresearch/sam3: Text-Prompted Segmentation for Images and Video
The repository provides code for running inference and finetuning with the Meta Segment Anything Model 3 (SAM 3), links for downloading the trained model checkpoints, and example notebooks that show how to use the model.
At a glance
- What is it?
- SAM 3 extends the Segment Anything line from point and box prompts to open-vocabulary text concepts, and adds joint detection and tracking in video. The repository ships inference and finetuning code, but the checkpoints sit behind a gated Hugging Face request.
- Who is it for?
- Adopt SAM 3 if you need to segment every instance of a short text concept across images or video and you can work inside the stated Python 3.12, PyTorch 2.7 and CUDA 12.6 requirements. Do not adopt it if you have no CUDA GPU, no accepted Hugging Face access request, or only a point-prompt image workflow that SAM 2 already covers.
- Can I use it commercially?
- Check first. The repository uses a licence we do not classify automatically, so read its LICENSE file before any commercial use.
- Is it still maintained?
- Yes. The repository received new commits within the last day.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 13, 2026, and from our analysis. They are not legal advice.
Star history
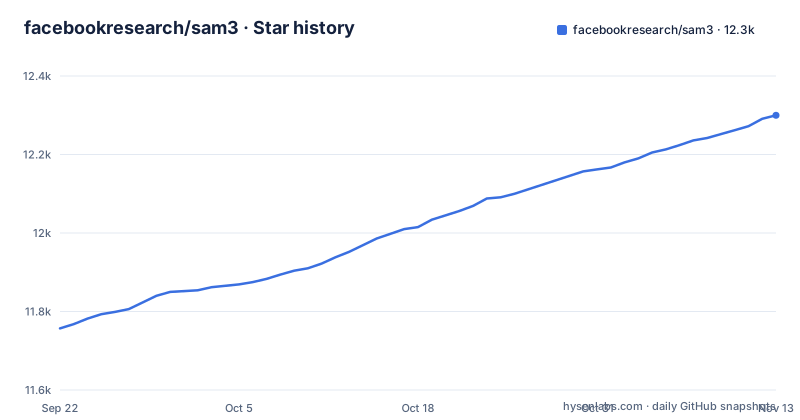
- facebookresearch/sam312,300 ★ · +543
| Repository | 2026-09-22 | 2026-11-13 |
|---|---|---|
| facebookresearch/sam3 | 11.8k | 12.3k |
543 Stars in the last 52 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
What SAM 3 adds over a point-prompt segmenter
SAM 2 and the original SAM respond to geometry: a point, a box, a mask. You have to know where the object is before you can ask for it. SAM 3 changes the input type. The README describes it as "a unified foundation model for promptable segmentation in images and videos" that can "detect, segment, and track objects using text or visual prompts such as points, boxes, and masks." The new capability is exhaustive segmentation of every instance of an open-vocabulary concept named by a short phrase or by exemplars.
The word exhaustive is the part that matters in practice. A text-conditioned detector that returns the single best match is a different tool from one that returns all matches for "a player in red" across a frame or a clip. The README states that SAM 3 reaches 75 to 80 percent of human performance on the SA-CO benchmark, which it says contains 270K unique concepts, over 50 times more than existing benchmarks. That is a self-reported figure from the project, not an independent measurement, and the benchmark is the project's own.
Two architectural claims are worth separating from the marketing. First, a presence token, described as improving discrimination between closely related prompts such as "a player in white" versus "a player in red." Second, a decoupled detector and tracker design that the README says minimizes task interference and scales efficiently with data. Both are design choices aimed at the same failure mode: a model that segments a person correctly but cannot tell you which team they play for.
The image and video inference path in the repository
The code is organized around builders and processors rather than a single entry point. For images, build_sam3_image_model returns the model and Sam3Processor wraps it. You call set_image to get an inference state, then set_text_prompt with the phrase you want segmented. The output carries the masks, bounding boxes and scores.
That split explains the file layout. The sam3/ package holds the model code, examples/ holds twelve notebooks covering image prediction, batched inference, interactive image work, video prediction, the SAM 1 and SAM 2 task compatibility notebooks, agent use and SA-CO evaluation, and scripts/ plus test/ sit alongside them.
The pyproject.toml lists the hard runtime dependencies as timm, numpy pinned below 2.0, tqdm, ftfy pinned at 6.1.1, regex, iopath, typing_extensions and huggingface_hub. Everything else is an extra. That is a narrow core, which is a point in the repository's favor for anyone who only wants inference.
Installing SAM 3 and running a first text prompt
The README's prerequisites are stricter than the packaging metadata. It asks for Python 3.12 or higher, PyTorch 2.7 or higher, and a CUDA-compatible GPU with CUDA 12.6 or higher. The pyproject.toml, by contrast, declares requires-python as >=3.8 and classifies the project against Python 3.8 through 3.12. Trust the README here: the install commands below pin Python 3.12 and a CUDA 12.8 PyTorch build, which is what the project actually documents.
The environment setup is three commands. The README deactivates the base environment before activating the new one, which is easy to skip and easy to regret.
conda create -n sam3 python=3.12
conda deactivate
conda activate sam3
PyTorch comes from the CUDA 12.8 index, not from the default PyPI index, so the index URL is not optional.
pip install torch==2.10.0 torchvision --index-url https://download.pytorch.org/whl/cu128Then clone and install the package in editable mode. The notebooks extra is what the examples/ directory needs.
pip install -e ".[notebooks]"Optional dependencies exist for faster inference: einops, ninja, flash-attn-3 installed with --no-deps from the same CUDA 12.8 index, and cc_torch from a GitHub URL. Measure the speedup yourself before relying on it.
Checkpoint access is gated. The README says to request access on the SAM 3 Hugging Face repo and to authenticate once accepted, for example with hf auth login after generating an access token. Without that, the download fails regardless of how clean the install was.
The first inference run is short. Build the model and processor, load an image, set the image state, then pass a text prompt and read the three output arrays.
from PIL import Image
from sam3.model_builder import build_sam3_image_model
from sam3.model.sam3_image_processor import Sam3Processor

model = build_sam3_image_model()
processor = Sam3Processor(model)
image = Image.open("<YOUR_IMAGE_PATH.jpg>")
inference_state = processor.set_image(image)
output = processor.set_text_prompt(state=inference_state, prompt="<YOUR_TEXT_PROMPT>")
# Get the masks, bounding boxes, and scores
What you should see are the masks, bounding boxes and scores for the prompted concept.
Where SAM 3 is the wrong tool
The hardware bar is the first filter. A CUDA-compatible GPU with CUDA 12.6 or higher is a prerequisite, not a recommendation,. If your deployment target is a laptop, a CPU-only CI runner, or an edge device without a supported CUDA stack, this repository will not run as documented.
The gated checkpoints are the second filter, and they are a workflow problem rather than a technical one. Access has to be requested and approved before any download works, and the machine that runs inference has to be authenticated. That is awkward for reproducible builds: a container image built in CI needs a token.
There is also a scope mismatch to watch for. If your task is interactive segmentation of one object at a time from clicks, SAM 3's headline capability, exhaustive open-vocabulary concept segmentation, is not what you need, and the extra machinery buys you nothing. The repository even ships examples/sam3_for_sam1_task_example.ipynb and examples/sam3_for_sam2_video_task_example.ipynb, which suggests the authors expect people to arrive with SAM 1 and SAM 2 workloads.
Finally, the pyproject.toml still carries the classifier "Development Status :: 4 - Beta." The README also warns that using the SAM 3.1 checkpoints requires pulling the latest code and reinstalling. Interfaces can move.
SAM 3.1 and the upgrade cost
The latest update in the README, dated 03/27/2026, announces SAM 3.1 Object Multiplex, described as a shared-memory approach for joint multi-object tracking that is "significantly faster without sacrificing accuracy." New checkpoints are published at huggingface.co/facebook/sam3.1, and RELEASE_SAM3p1.md holds the full details. There is a dedicated example at examples/sam3.1_video_predictor_example.ipynb.
The upgrade instruction is blunt: to use the SAM 3.1 checkpoints you need the latest model code from the repository, so pull with git pull and reinstall following the installation section.
For a team pinning versions in production, the cost is that the SAM 3.1 checkpoints need the latest code from the repository, and the repository has no GitHub releases to pin.
On licensing, the repository carries a LICENSE file and pyproject.toml points to it, while the classifiers claim "License :: OSI Approved :: MIT License." The repository metadata reports the license as NOASSERTION, meaning the platform could not classify it automatically. Those two signals disagree. Read the LICENSE file and the checkpoint terms on the Hugging Face repo before you ship anything; this is not a point where a classifier string is good enough.
Editorial conclusion
Adopt SAM 3 if you need to segment every instance of a short text concept across images or video and you can work inside the stated Python 3.12, PyTorch 2.7 and CUDA 12.6 requirements. Do not adopt it if you have no CUDA GPU, no accepted Hugging Face access request, or only a point-prompt image workflow that SAM 2 already covers. Verify three things before you commit: that your access request to the facebook/sam3 Hugging Face repo has been accepted, that hf auth login succeeds on the machine that will run inference, and that your Python and CUDA versions match the prerequisites rather than the looser requires-python value in pyproject.toml.
Frequently asked questions
What is Meta SAM 3?
SAM 3 is a unified foundation model for promptable segmentation in images and videos, released by Meta Superintelligence Labs. It can detect, segment and track objects from text or visual prompts, and it adds exhaustive segmentation of all instances of an open-vocabulary concept given as a short phrase or exemplars.
What are the key differences between SAM 2 and SAM 3?
The README states that compared to SAM 2, SAM 3 introduces the ability to exhaustively segment all instances of an open-vocabulary concept specified by a short text phrase or exemplars. It also describes a presence token for telling closely related prompts apart and a decoupled detector and tracker design.
Is Meta SAM 3 free?
The repository is public and pyproject.toml points to a LICENSE file, with classifiers claiming an OSI-approved MIT license, but the repository metadata reports the license as NOASSERTION, so the platform could not classify it. The checkpoints are separate: access must be requested on the SAM 3 Hugging Face repo and approved before you can download them. Read the LICENSE file and the checkpoint terms yourself.
Is SAM 3 real time?
The README's overview does not claim real-time performance. It says SAM 3.1 Object Multiplex is significantly faster for joint multi-object tracking without sacrificing accuracy, and it lists optional dependencies for faster inference.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/facebookresearch-sam3)Star history chart for your README
[](https://hysenlabs.com/projects/facebookresearch-sam3)Was this useful?