HeavyDB: A GPU-First SQL Engine You Build From Source
HeavyDB (formerly MapD/OmniSciDB)
At a glance
- What is it?
- HeavyDB is an Apache-2.0 columnar SQL database that executes queries with JIT-compiled code across CPUs and Nvidia GPUs. This article covers what the repository actually documents, what building it demands, and where the approach stops being the right fit.
- Who is it for?
- Adopt HeavyDB if you have Nvidia GPUs, multi-billion row analytical workloads, and engineers who can compile from source and stay current with a fast-moving engine. Do not adopt it if you need a one-line install, a managed service, or if your data fits comfortably in a single-node CPU column store.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 2 days ago.
- What is it written in?
- Mainly C++, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
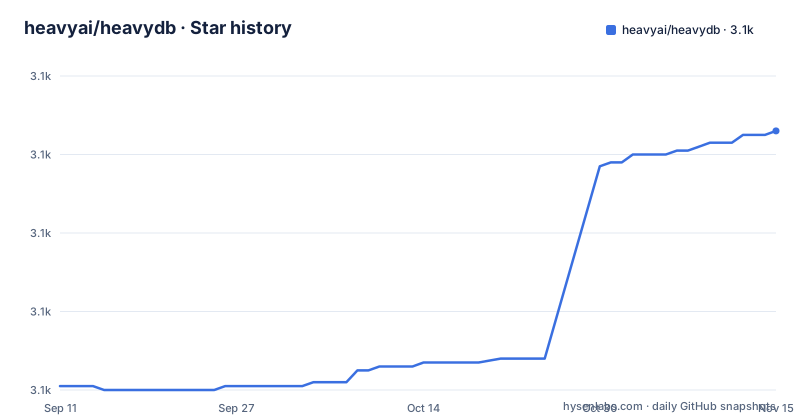
- heavyai/heavydb3,126 ★ · +65
| Repository | 2026-09-11 | 2026-11-15 |
|---|---|---|
| heavyai/heavydb | 3.1k | 3.1k |
65 Stars in the last 65 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The Problem HeavyDB Targets: Querying Billions of Rows Without Pre-Aggregation
The README states the goal directly: query multi-billion row datasets in milliseconds without indexing, pre-aggregation, or downsampling. That is a specific claim about a specific pain point. Traditional analytical databases handle large scans either by building indexes ahead of time, by materializing aggregate tables, or by sampling the data down. Each of those moves work from query time to load time, and each makes the system less useful when the question changes. HeavyDB instead pushes the scan itself onto hardware built for parallel arithmetic, and compiles the query into machine code rather than interpreting it. The intended user is an analyst or data engineer running interactive exploration over event-scale data: telemetry, ad impressions, geospatial traces. The repository topics list real-time, OLAP, and visualization alongside cuda and llvm, which matches that positioning. It is not a transactional store.
How HeavyDB Executes a Query: JIT Compilation and Tiered Memory
Two mechanisms carry the design. The first is a Just-In-Time query compilation framework, described in the README as innovative, which turns a SQL plan into compiled code rather than walking an interpreted plan tree. The second is multi-tiered caching of data between storage, CPU memory, and GPU memory. The data flow implied by that description is: columnar data sits in storage, is pulled into host memory, and is promoted to GPU memory where the compiled kernel runs. On a hybrid CPU/GPU machine the engine can use both. The build flags confirm the split. ENABLE_CUDA defaults to on, and setting it to off produces a CPU-only build. That matters because it means the same SQL surface and the same storage layer serve both configurations. The README also notes CPU-only operation on X86, Power, and ARM, with ARM marked experimental. So the GPU path is the primary one and the CPU path is a supported fallback, not a separate product.
Building HeavyDB From Source: CMake Flags That Change Behaviour
There is no documented one-line install in this material. The README points to HEAVY.AI Downloads for binaries, but the repository itself is a source build driven by CMake. The documented sequence is: create a build directory, run cmake with a build type, then make. A debug build is shown as cmake -DCMAKE_BUILD_TYPE=debug .. followed by make -j 4. The build type options listed are Debug, Release, RelWithDebInfo, MinSizeRel, and unset. Several flags change what you get. ENABLE_CUDA defaults to on, so a machine without Nvidia hardware needs -DENABLE_CUDA=off explicitly. ENABLE_AWS_S3 defaults to on if available. ENABLE_ONLY_ONE_ARCH compiles GPU code only for the host architecture and speeds up compilation, which is the flag to reach for when build times become the bottleneck. ENABLE_CUDA_KERNEL_DEBUG adds debugging symbols to CUDA kernels and, per the README, will dramatically reduce kernel performance, so it is a diagnostic-only setting. ENABLE_JIT_DEBUG does the same for the JIT layer. ENABLE_TESTS defaults to on. Packaging uses CPack, and the README notes that packages built on CentOS with static linking enabled (via -DPREFER_STATIC_LIBS=on) can be used on most other recent Linux distributions, though that flag is documented as only working on CentOS.
Testing and Sanitizers: What the Repository Actually Provides
HeavyDB uses Google Test, with tests under the Tests directory. The README names a sanity_tests target as the run of the most common tests, invoked as make sanity_tests. Two sanitizer configurations are documented, and both come with a constraint worth noting: AddressSanitizer and ThreadSanitizer each require CUDA to be disabled in the build. For ASan the documented commands are cmake -DENABLE_ASAN=on -DENABLE_CUDA=off .. followed by make -j 4, then exporting ASAN_OPTIONS=alloc_dealloc_mismatch=0:handle_segv=0 before running the tests. For TSan it is cmake -DENABLE_TSAN=on -DENABLE_CUDA=off .., and the README instructs setting TSAN_OPTIONS to point at config/tsan.suppressions so warnings from third party libraries are ignored. The practical consequence is that memory and race checking happen on the CPU code path only. If you are chasing a bug that only appears in a GPU kernel, these sanitizer builds will not reproduce it. That is a real gap in the tooling, and the README does not claim otherwise.
Where HeavyDB Is the Wrong Tool
The build story is the first limitation. Everything documented here assumes a C++ toolchain, CMake, and a dependency set large enough that the README keeps it in a separate section and points to ThirdParty/licenses/index.md for the bundled packages. That is a meaningful operational cost before you run a single query. The second limitation is hardware. GPU acceleration depends on Nvidia GPUs, and the README says so plainly. If your deployment target is an ARM server without Nvidia hardware, you are on the experimental CPU path. The third is workload shape. A JIT compiler earns its keep on repeated, complex, compute-heavy queries over large columnar scans. If your queries are small, highly concurrent, and dominated by point lookups, the compilation step and the GPU transfer overhead have nothing to amortize against, and a conventional row or column store will be simpler to operate. Finally, the README announces HeavyAI 10.0 with an ETA of September 2026 and a performance branch previewed at VLDB 2026 that will be merged into master after release. Anyone building from master today should expect the tree to move under them.
How HeavyDB Differs From DuckDB and ClickHouse
The closest CPU-only comparison is DuckDB, which is also a columnar SQL engine but executes through a vectorized interpreted pipeline on CPU cores alone, and ships as a single library or binary you can embed in a process. HeavyDB instead compiles queries to machine code and can dispatch them to GPU memory, which is a different bet: more build and hardware complexity in exchange for parallelism that CPU-only engines cannot reach on a single node. ClickHouse takes a third route, a distributed columnar store with its own MergeTree storage engine and a server model, scaling across many CPU machines rather than one GPU-equipped one. The difference in approach is where the parallelism comes from. ClickHouse adds nodes. DuckDB adds cores on one machine. HeavyDB adds GPU cores on one machine. Which of those fits depends on whether your bottleneck is aggregate compute or data volume across a fleet. None of the three is a drop-in for the others, and there is no basis here for claiming HeavyDB wins on any particular query.
Licence, Contributions, and What Maintenance Involves
HeavyDB is licensed under Apache License 2.0, and the README notes that the repository bundles third party packages under separate licences, with details in ThirdParty/licenses/index.md. If you redistribute a build, that file is the one to read, since Apache-2.0 covers the project's own code and not necessarily everything linked into the binary. Contributions require a signed Contributor License Agreement, and the README states that a bot will flag pull requests where a CLA is missing. On maintenance: there is no LTS branch described in this material. The latest release listed is v9.0.0, and the README already advertises HeavyAI 10.0 with a September 2026 ETA plus a separate performance branch that will be merged into master after that release. Upgrading therefore means tracking master or waiting on release branches, and rebuilding, because this is a compiled engine with a dependency tree rather than a package you update in place. Budget for that rebuild cycle. Verify the upgrade path between major versions yourself before depending on one.
Editorial conclusion
Adopt HeavyDB if you have Nvidia GPUs, multi-billion row analytical workloads, and engineers who can compile from source and stay current with a fast-moving engine. Do not adopt it if you need a one-line install, a managed service, or if your data fits comfortably in a single-node CPU column store. Before committing, verify three things: that your GPU model and driver combination is supported by the CUDA version the v9.0.0 tree expects, that your build machine has the dependencies listed under ThirdParty, and that your workload actually benefits from JIT compilation rather than being dominated by I/O or result transfer. If those checks pass, run the sanity_tests target and then benchmark your own queries before moving any production data.
Frequently asked questions
What is HeavyDB?
It is an in-memory, column store, SQL relational database designed from the ground up to run on GPUs, formerly known as MapD Core or OmniSciDB. It is Apache licensed, and the repository's dependency scripts and sample configuration file still carry the older brand names in their paths.
What did NVIDIA open source in the HeavyDB repository?
The page says that as of October 2026 the repository includes the whole platform rather than only the database core, adding the dashboard user interface, a GPU-accelerated renderer for point, symbol, line, polygon, heatmap and raster images composited over a map background, a radio-frequency propagation simulator for wireless network planning, and a connector layer exposing external data as foreign tables with adapters for delimited files, Parquet, pattern-parsed logs, database connectivity and raster sources.
How do I build HeavyDB?
Follow the build-from-source documentation, which is hosted on the current owner's documentation domain and builds the entire platform, including the interface, the web server, the geospatial extension modules and the database, into a usable container image. Dependency installation is handled by scripts that support Ubuntu 22.04 and Rocky Linux 8.x and require sourcing a generated shell file before configuring the build.
What code style does the HeavyDB project require?
Code should compile without warnings on recent compilers across most Linux distributions and follow the C++ core guidelines, with a Chromium-based formatter configuration and a linter configuration at the top level and stated minimum versions for both tools. The page advises committing your work before running the linter, then reviewing and amending, because it can make invalid or overly verbose changes.
Does every HeavyDB source file need a licence header?
Yes, a standard header with the current owner's copyright line and the Apache identifier, and a pre-commit hook adds and refreshes the copyright year range automatically, fixing files in place. Enforcement is forward-looking, so only files you add or modify are checked, the existing tree is not rewritten, and vendored third-party code is exempt in named directories.
Official sources
Where developers are discussing it
Posts on Hacker News, dev.to and Lobsters that link to this repository, found by our scan of those communities. 1 in the last 30 days; newest first.
- HeavyAI (formerly MapD) is now open sourceHacker News · Oct 29, 2026 · 2 points · 2 comments
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/heavyai-heavydb)Star history chart for your README
[](https://hysenlabs.com/projects/heavyai-heavydb)Was this useful?