PaddlePaddle: a C++ framework whose README describes release 3.2 while v3.4.0 ships
PArallel Distributed Deep LEarning: a machine learning framework from industrial practice. The PaddlePaddle core framework for high-performance single-machine and distributed training, and cross-platform deployment, in deep learning and machine learning.
At a glance
- What is it?
- PaddlePaddle is an Apache-2.0 deep learning framework built in C++, open sourced in China since 2016, with automatic parallelism and one code path for training and inference. Its repository enforces a Python 3.10 floor in code, routes every install step to an external page, and documents its version numbers a release behind.
- Who is it for?
- PaddlePaddle fits a team that wants training and inference in one framework and can reach paddlepaddle.org.cn for the install steps the repository does not carry. Read the v3.4.0 release notes rather than the README feature list, since the prose still describes 3.2.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 1 day ago.
- What is it written in?
- Mainly C++, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 13, 2026, and from our analysis. They are not legal advice.
Star history
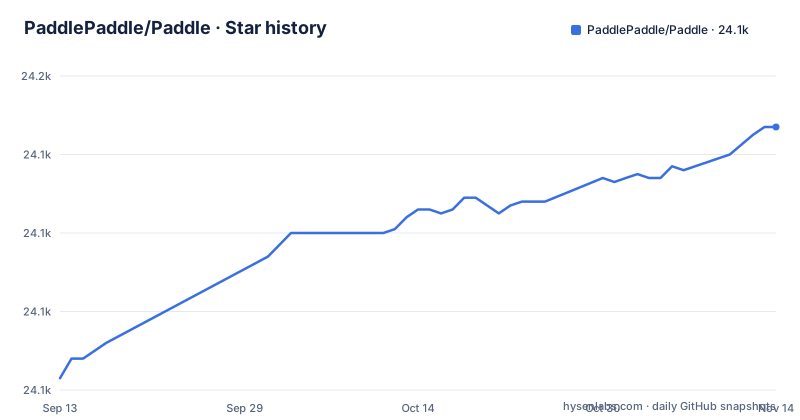
- PaddlePaddle/Paddle24,147 ★ · +64
| Repository | 2026-09-13 | 2026-11-13 |
|---|---|---|
| PaddlePaddle/Paddle | 24.1k | 24.1k |
64 Stars in the last 61 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The README still says 3.3 while v3.4.0 shipped in September
The version numbers in the README and the version numbers in the release feed disagree, and the mismatch is visible from the repository alone. Under Installation the README heads its own section "Latest PaddlePaddle Release: 3.3" and points readers at the releases page to track what is new. The next feature heading is titled "PaddlePaddle New Generation Framework 3.2". The most recent GitHub releases are v3.4.0 published on 2026-09-11, v3.3.0 on 2026-01-31 and v3.2.2 on 2025-12-08.
Nothing is broken by this, but it changes where a reader should look first. The five capability claims in the README describe 3.2, and the release notes for 3.3 and 3.4 are the only place the newer work is described. The README links the releases page in general terms. An adoption note written from the README alone will understate what the framework currently claims to do.
setup.py stops the install before anything else on Python 3.9
The version floor is enforced in Python code rather than stated in prose. The first checks in setup.py read the running interpreter and compare it against 3.10, raising before any compilation step begins.
python_version = platform.python_version()
version_detail = sys.version_info
version = str(version_detail[0]) + '.' + str(version_detail[1])
env_version = os.getenv("PY_VERSION", None)

if version_detail < (3, 10):
    raise RuntimeError(
        f"Paddle only supports Python version >= 3.10 now,"
        f"you are using Python {python_version}"
    )
Two details matter for whoever hits it. First, the comparison is against sys.version_info of the interpreter running setup.py, so a mismatch surfaces as a hard build failure rather than a warning. Second, the script reads PY_VERSION from the environment and, when it is unset, prints and sets the value itself. If PY_VERSION is already set to something different, the next branch raises ValueError instead. The error text names both the required floor and the version actually found, so the message does tell you what to change.
Tensor partitioning written on one card, parallelism discovered across the cluster
Automatic parallelism is presented as a reduction in annotation work, not as a scheduler you configure by hand. The claim is that a developer annotates tensor partitioning based on a single-card configuration and the framework then discovers the most efficient distributed strategy by itself.
That design changes the failure mode. In a manually parallel setup, a wrong device count or a wrong layer mapping shows up as a configuration error you can read. Here the strategy is chosen after the annotations are written, so the first sign of trouble is a distributed run that diverges from the single-card run you already validated. The README does not say how the discovered strategy is reported, whether it can be pinned, or what happens when an annotation is under-specified, and that debugging step is left open.
The same bullet also names unified dynamic and static graphs, so the partitioning annotation is expected to hold in either graph form rather than only in the static one.
Training and inference share one framework, so the split happens elsewhere
The second capability is integrated training and inference, described as the same framework covering both phases so that code carries over between them. A third, the neural network compiler, is presented as an integrated design supporting efficient training and flexible inference for generative and scientific computing models.
For an adopter the interesting part is where the split is not. If training and inference share the framework, the usual separation between a training-only graph and a trimmed export artifact is not a PaddlePaddle boundary, and the README documents no export-only mode to look for.
High-order differentiation is listed alongside them, with complex number operations, Fourier transforms and compilation optimization, aimed at mathematics, mechanics, materials science, meteorology and biology. Those five fields are the README's own framing of who the scientific computing half is for, not a statement about what has been validated.
Multi-chip support is a promise about interfaces, not a list of vendors
Heterogeneous multi-chip adaptation is described in terms of abstraction: a unified adaptation solution across multiple hardware types, standardized interfaces that hide differences between chip software stacks, and a pluggable architecture. No vendor, accelerator or board is named in that paragraph, and the top-level tree has no per-hardware directory that would reveal the supported set.
For a team choosing hardware, that gap is the decision itself. The claim as written says PaddlePaddle can adapt to several chip types. It does not say which hardware has an adaptation, at which release, or whether an adaptation is contributed by a vendor or maintained in tree. Anyone who needs a specific accelerator verified has to settle it against the Quick Install page and the release notes, because the repository does not.
The nightly build has the same shape. The README offers "Install Latest Stable Release or Nightly Release" as a heading and then links out for details, so pinning a nightly for a reproducible environment gets you no documented version string from the repository.
A clone lands on develop, not on a tagged release
The default branch is develop. That single fact changes what a contributor reads and what a user builds. Cloning without arguments gives you the branch where new work lands, not the source that produced the v3.4.0 tag published on 2026-09-11, along with the README whose install section still reads 3.3.
The repository is arranged for gate-heavy C++ work. Root-level configuration includes .clang-format, .clang-tidy, .cmake-format.py, .editorconfig, _typos.toml, sgconfig.yml and a .pre-commit-config.yaml, next to CMakeLists.txt and directories for ci/, cmake/, tools/, patches/, test/ and third_party/. There is also an r/ directory sitting next to python/, the one place in the tree that suggests an interface outside Python.
The upshot for a user rather than a contributor is that a tagged release is the only reproducible starting point named here, and the README does not record which branch a given tag was cut from.
Installation is a link to a quick install page, not a command
There is no install command in this README. The Installation section names the latest release, points at the releases page for features, and then sends you to Quick Install at www.paddlepaddle.org.cn/install/quick for the actual steps.
That split has consequences wherever a link is not enough. The README gives no wheel name, no index URL, no accelerator or driver version, no Python range for a particular wheel, and no verification step for what landed. The single hard constraint visible in the repository is the 3.10 floor enforced by setup.py, and that surfaces only once you already have the source.
The documentation is split across hosts too. The repository homepage is www.paddlepaddle.org, while the installation, guides and API links inside the README all point at www.paddlepaddle.org.cn, and the Practice link is the only one that stays inside the Chinese documentation tree. Anything scripted against those URLs should not assume the two hosts are interchangeable.
Ruff stops at the boundary of the vendored gast tree
The Python side carries an explicit lint configuration, and the exclusion list is narrow enough to read as intent.
[tool.ruff]
exclude = [
    "./build",
    "third_party",
    "./python/paddle/utils/gast/**",
]
line-length = 80
target-version = "py310"
Three paths are excluded: build output, the third_party tree, and one vendored subtree under python/paddle/utils/gast. Everything else under python/ is linted, and the selected rule set is long, covering pycodestyle, pyflakes, isort, bugbear, pylint, refurb and flake8-quotes among others, with NPY001 marked unfixable so numpy deprecation fixes are never applied automatically.
line-length is 80 while docstring code is formatted separately at 120, and E501 sits in the ignore list, so length is enforced by the formatter rather than by the linter. For a contributor that makes the effective style rule the formatter's own output rather than a separately written convention.
Editorial conclusion
PaddlePaddle fits a team that wants training and inference in one framework and can reach paddlepaddle.org.cn for the install steps the repository does not carry. Read the v3.4.0 release notes rather than the README feature list, since the prose still describes 3.2. Before committing, confirm the Python 3.10 floor against your build image, check that your accelerator is actually covered by the multi-chip adaptation the README promises in general terms, and pin a tag rather than the develop branch, which is where new work lands.
Frequently asked questions
How do you install PaddlePaddle?
The README carries no install command. It names the latest release and points to Quick Install at www.paddlepaddle.org.cn/install/quick for the steps, and offers a heading covering both the latest stable release and a nightly release without naming a version string for either.
Which Python versions does PaddlePaddle support?
Python 3.10 or newer. setup.py compares sys.version_info against 3.10 at the top of the file and raises a RuntimeError naming the version in use when the check fails, and the ruff configuration in pyproject.toml sets target-version to py310.
Does PaddlePaddle support hardware other than Nvidia GPUs?
The README claims heterogeneous multi-chip adaptation through standardized interfaces that abstract the differences between chip software stacks, with a pluggable architecture. It names no specific vendor, accelerator or board, so a particular card has to be confirmed elsewhere.
How does PaddlePaddle set up distributed training?
The framework claims you annotate tensor partitioning based on a single-card configuration and it then finds the most efficient distributed parallel strategy itself. The README does not document how that strategy is reported or whether it can be pinned.
Which version of PaddlePaddle should I read about?
The newest GitHub release is v3.4.0, published on 2026-09-11, ahead of v3.3.0 from 2026-01-31 and v3.2.2 from 2025-12-08. The README is behind both: its install heading says 3.3 and its feature section is titled 3.2.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/paddlepaddle-paddle)Star history chart for your README
[](https://hysenlabs.com/projects/paddlepaddle-paddle)Was this useful?