Infinity: a single-binary search engine for vectors, tensors and text
The AI-native database built for LLM applications, providing incredibly fast hybrid search of dense vector, sparse vector, tensor (multi-vector), and full-text.
At a glance
- What is it?
- Infinity combines dense vectors, sparse vectors, multi-vector tensors and full-text search behind one table API, shipped as a C++ binary with a Python client. It is aimed at retrieval pipelines rather than general application storage.
- Who is it for?
- Adopt Infinity if your retrieval layer needs dense vectors, sparse vectors, tensors and full-text search in one query, and you can run a server process on x86_64 with AVX2. For dense-only workloads, compare its cost and operational requirements with other vector databases; if you need a managed service or tenant isolation, verify those requirements against the available offering and documentation.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository received new commits within the last day.
- What is it written in?
- Mainly C++, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
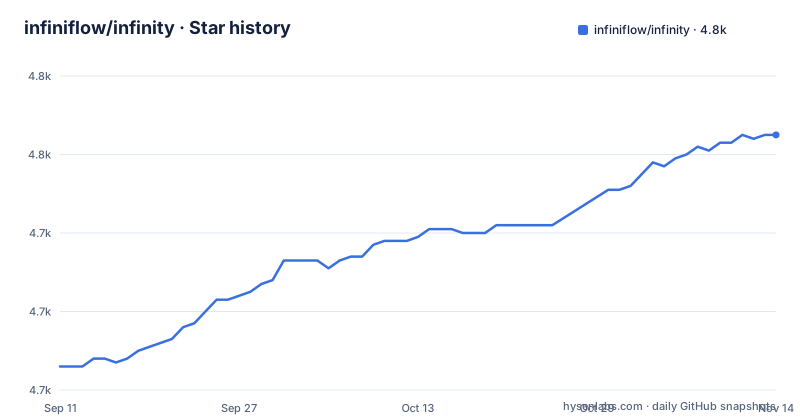
Star history
- infiniflow/infinity4,765 ★ · +59
| Repository | 2026-09-11 | 2026-11-14 |
|---|---|---|
| infiniflow/infinity | 4.7k | 4.8k |
59 Stars in the last 64 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
What problem Infinity is aimed at
A retrieval-augmented generation pipeline usually needs more than one index. Dense embeddings handle semantic similarity, BM25 handles exact terms and rare tokens, and a multi-vector representation such as ColBERT keeps token-level detail that a single pooled vector throws away. Running those as three services means three schemas, three write paths and a merge step in application code. Infinity's pitch is that all of them live in one table: the README describes support for dense vector, sparse vector, tensor, full-text and structured data, and states that hybrid search across those types is supported in addition to filtering. The audience is engineers building search, question answering or recommender features who are willing to run their own search process rather than call a hosted API. The README frames the target as LLM applications and RAG specifically,.
The mechanism: one table, several index types, a reranking stage
The data model is a table with typed columns. In the README's example, create_table takes a mapping of column names to type descriptors: {"num": {"type": "integer"}, "body": {"type": "varchar"}, "vec": {"type": "vector, 4, float"}}. The vector type string carries dimensionality and element type. Queries are built by chaining, starting from output(["*"]).match_dense("vec", ...) with the column name and a query vector. Hybrid search is the part that differs from a plain vector store. The README lists rerankers including RRF (reciprocal rank fusion), weighted sum and ColBERT, so the intended flow is to score candidates from more than one matcher and then combine those scores in a final stage inside the engine. What the README does not specify is how the fusion stage is configured at the API level, which arguments select RRF versus weighted sum, or how per-matcher weights are expressed. That detail sits in the linked Python and HTTP API references, not in the README, so treat the README as a map of capabilities rather than a configuration guide.
Getting a server and a client running
The README's primary path is Docker with client and server as separate processes. It first creates a data directory and hands ownership to the current user, then pulls and runs the image with a raised file descriptor limit and host networking: sudo mkdir -p /var/infinity && sudo chown -R $USER /var/infinity, then docker pull infiniflow/infinity:nightly, then docker run -d --name infinity -v /var/infinity/:/var/infinity --ulimit nofile=500000:500000 --network=host infiniflow/infinity:nightly. The nofile bump to 500000 is not incidental for a search server holding many open index segments, and --network=host means the client reaches the server on the host network rather than a mapped port. On Windows the README requires WSL or WSL2, with systemd enabled inside WSL2, docker-ce installed per Docker's Ubuntu instructions, and, for Docker Desktop 4.29 or newer, the Enable host networking option switched on before the same run command is used. The client is installed separately: pip install infinity-sdk==0.7.4. Note the version split. The client is pinned to 0.7.4, which matches the v0.7.4 release listed in the repository, while the server image tag in the README is nightly. Prerequisites are stated plainly: x86_64 with AVX2 support, Linux with glibc 2.17 or newer, Windows 10 or newer through WSL, macOS, and Python 3.11 or newer. The README also points to a binary deployment guide and a build-from-source guide for people who do not want Docker, and notes that Infinity can be embedded in Python as a module.
The AVX2 floor and the single-binary trade-off
The hard constraint is the CPU. Infinity requires x86_64 with AVX2 support. That is a reasonable assumption on server hardware from the last decade, but it is a real boundary: ARM hosts, older Xeons without AVX2, and some virtualized or emulated environments will not run it. The README does not describe a fallback path for those machines, so this is a gate rather than a tuning parameter. The second trade-off is architectural. A single-binary design with no external dependencies is genuinely easier to deploy than a system that expects a coordination service and object storage, and the README calls this out as a deployment advantage. The cost is that scaling out is not described in the README at all. There is no discussion of replication, sharding, or how multiple server processes would coordinate over the same data directory. Mounting /var/infinity from more than one container is not something the README addresses. If your requirement is horizontal scale with a documented replication story, this README gives you nothing to evaluate, and you would need the references section to answer it.
Comparing vector and hybrid search options
If your workload only needs dense-vector search and metadata filters, compare the operational and performance costs of Infinity with alternatives on your own data. Qdrant and Milvus also support hybrid full-text and vector search, so hybrid retrieval is not unique to Infinity. Their data models, query APIs, indexing and deployment options differ; test the specific features and versions you intend to use. The other axis is operations. A hosted or managed vector service removes the server process, the data directory, the file descriptor limit and the AVX2 requirement from your plate. Infinity's README presents a self-hosted binary and nothing about a managed offering, so choosing it means owning that process.
Performance claims and what to check before trusting them
The README states 0.1 millisecond query latency and 15K+ QPS on million-scale vector datasets, and 1 millisecond latency and 12K+ QPS for full-text search on 33M documents. It also links a benchmark report on infiniflow.org. Those are the project's own numbers under its own conditions, and the README does not state the hardware, the dataset, the recall target, or the concurrency level behind them. Latency figures for approximate nearest neighbor search are only meaningful alongside a recall number, because a lower recall target is cheaper to hit. Before you plan capacity around 0.1 milliseconds, read the linked benchmark page for the configuration and then reproduce it on your own data and hardware. The same caution applies to the hybrid path: the README lists RRF, weighted sum and ColBERT rerankers but does not publish latency for a fused query, which is the shape most RAG pipelines actually issue.
Versioning, licence and upgrade cost
The release list shows v0.7.3 and v0.7.4 as dated releases plus a nightly tag, and the README's Docker instructions pull nightly while the client is pinned to 0.7.4. That mismatch is the main upgrade cost to plan for. A nightly server image moves under you, and the Python client is version-locked, so a deployment that follows the README literally is running a moving server against a fixed client. Pinning the server to a released tag and tracking the client version alongside it is the more predictable arrangement, and the README's own install line for the client shows the project does tag releases. The project has not been archived, and the last push date on the repository is recent, so the codebase is active. On licensing, Infinity is Apache-2.0. That is a permissive licence that generally allows commercial use and modification, but it also carries notice and attribution obligations, and it is not legal advice. If you embed the binary in a product you ship, have counsel review the notice requirements rather than assuming the licence grants more than it does.
Editorial conclusion
Adopt Infinity if your retrieval layer needs dense vectors, sparse vectors, tensors and full-text search in one query, and you can run a server process on x86_64 with AVX2. For dense-only workloads, compare its cost and operational requirements with other vector databases; if you need a managed service or tenant isolation, verify those requirements against the available offering and documentation. Verify first that your CPU reports AVX2, that the pinned client version matches the server version you pull, and that the nightly image tag is acceptable for your deployment, since the README's Docker examples pull infiniflow/infinity:nightly while the client is pinned to 0.7.4.
Frequently asked questions
How do I run Infinity as separate server and client processes?
Pull the `infiniflow/infinity:nightly` image and start it with host networking, then install the client with `pip install infinity-sdk==0.7.4` and connect to port 23817 through `infinity.connect(infinity.NetworkAddress("<SERVER_IP_ADDRESS>", 23817))`.
Does Infinity run on ARM or Apple Silicon?
The documented prerequisites name x86_64 with AVX2 and list Linux, Windows through WSL/WSL2 and MacOS, with no ARM option given.
Which rerankers does Infinity offer for hybrid search?
RRF, weighted sum and ColBERT. The repository includes `example/ColBERT_reranker_example/`, and filtering can be applied alongside the merged retrieval paths.
Which Python versions work with the infinity-sdk client?
`pyproject.toml` sets `requires-python = ">=3.11,<3.14"`, while the quickstart states Python 3.11+. The packaged version is 0.7.4.
Does Infinity document authentication on its server port?
The quickstart run command sets `--network=host` and raises the file descriptor limit, and says nothing about authentication on 23817. The HTTP API reference is the place the project points for request level detail.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/infiniflow-infinity)Star history chart for your README
[](https://hysenlabs.com/projects/infiniflow-infinity)Was this useful?