xiaozhi-esp32-server-java: a Java control plane for ESP32 voice hardware
A Java enterprise management platform for XiaoZhi ESP32, providing an integrated frontend, backend and server solution for device monitoring, voice customization, role switching and conversation log management.
At a glance
- What is it?
- This repository is the Java rewrite of the xiaozhi ESP32 server, split into a management process and a dialogue process that share MySQL and Redis. It fits teams that already own the hardware and want a web console, but the deployment path is heavier than a single Python service and part of the feature set is not open source.
- Who is it for?
- Adopt it if you already have xiaozhi ESP32 hardware and want a Java stack with a built-in web console for devices, voices, roles and conversation logs. Skip it if you only need a minimal WebSocket voice loop, or if you refuse to run MySQL 8.0 and Redis 7 alongside a first-run model download.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository received new commits within the last day.
- What is it written in?
- Mainly Java, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
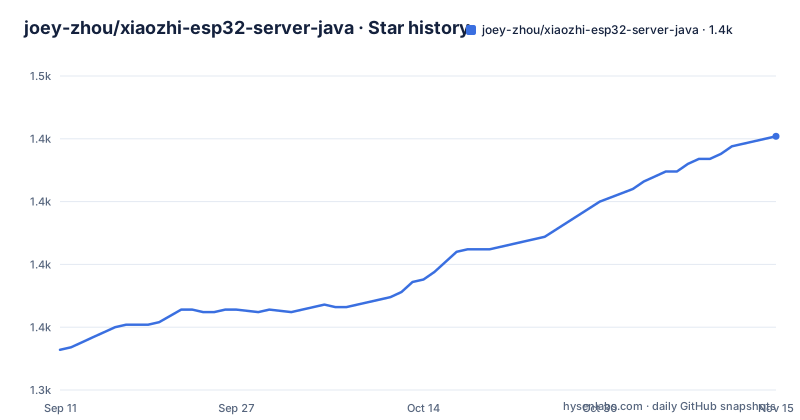
- joey-zhou/xiaozhi-esp32-server-java1,426 ★ · +85
| Repository | 2026-09-11 | 2026-11-15 |
|---|---|---|
| joey-zhou/xiaozhi-esp32-server-java | 1.3k | 1.4k |
85 Stars in the last 65 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The gap this fills for people who already own the hardware
The upstream xiaozhi-esp32 project gives you firmware. What it does not give you is a place to look at a fleet of devices, swap a voice, change a character prompt, or read back what was said last Tuesday. That operational layer is what this repository claims to add: the README describes it as a Java enterprise-grade server with a full front-end and back-end management platform, covering device monitoring, voice customization, role switching and conversation record management. The intended audience is stated plainly in a section titled 适用人群: people who have already bought ESP32 hardware and need a management platform, developers who want to stand something up quickly, and deployments that expect many concurrent device connections. So the unit of value here is not the audio pipeline alone. It is the audio pipeline plus the console that makes a fleet of small devices administrable. If you are running one board on a desk, most of this repository is overhead you will never open.
Two processes, one database, and how a device reaches them
The architecture section describes a multi-module, dual-process design. Two independent processes share MySQL and Redis and can be deployed and scaled separately. The first is xiaozhi-server on port 8091, the management back end: REST API, user, device and role management, and OTA upgrades. The second is xiaozhi-dialogue on port 8092, which handles WebSocket and MQTT real-time audio streams and the AI conversation pipeline. The scaling story is the interesting part. The README states that dialogue supports horizontal scaling, that new instances register themselves with the server automatically, and that load balancing is achieved through device OTA. In other words, the management process is the registry, and devices are pointed at a dialogue instance through the same OTA channel used for firmware updates. That is a real mechanism rather than a claim, and it also tells you where the coupling lives: MySQL and Redis are shared state between the two processes, so neither can be replaced casually. Behind the dialogue process sits a pipeline assembled from pluggable parts. Speech recognition options listed are Vosk, FunASR, Aliyun, Tencent Cloud and iFlytek. Speech synthesis options are sherpa-onnx locally, plus Volcano Engine, Aliyun and Edge TTS. Language models listed are OpenAI, Zhipu, iFlytek Spark, Ollama, Dify and Coze. The README also lists MCP tool protocol, Function Call, a RAG knowledge base and voice cloning as extension capabilities, and mentions real-time interruption and bidirectional streaming as part of the voice chain.
Getting it running: the model download is not optional
The quick start in the README is four commands. Clone the repository, change into it, run ./scripts/download_models.sh, then run bin/all.sh start to compile and launch both processes. bin/all.sh status reports state. The README is explicit that models/ and lib/ are not in the Git repository and must be fetched by script on first deployment. There is a lighter path: if you intend to use third-party STT and TTS services rather than local inference, ./scripts/download_base.sh downloads only the VAD model and the native libraries. Deployment routes are documented separately for CentOS (recommended for production), Windows (development and testing), Docker, and firmware compilation, the last of which is what you use to flash the ESP32 itself. After a successful start, the README says xiaozhi-server prints the OTA address and xiaozhi-dialogue prints the WebSocket connection address, and those are what you feed into the firmware build so the device registers with your server. Schema creation is handled by Flyway migrations, which the README lists among the one-click deployment features. The concrete constraint to plan around is the data layer: MySQL 8.0 and Redis 7 are both required, and both processes depend on them.
The published benchmark, and what it does not cover
The repository ships a companion load tool, Xiaozhi Concurrent, and publishes results from it. The stated environment is a Tencent Cloud instance with 8 cores, 8 GB of RAM and metered 100 Mbps bandwidth, driving 100 devices with 100 concurrent connections across 5 rounds of conversation. Reported figures include 100 percent success on WebSocket connection setup at 0.090s average, 100 percent on the Hello handshake at 0.073s, and 100 percent wake-word response at 0.333s. Speech recognition latency is given as 0.988s average, with the note that the measurement includes 800ms of silence. Server-side processing (LLM plus TTS) averages 0.849s with a maximum of 3.759s, and the end-to-end figure a user would feel averages 1.837s. Resource numbers are 1.8 GB idle rising to 1.96 GB at peak, CPU from 0 to 80 percent across 8 cores, and roughly 2200 KB/s up and 3300 KB/s down at peak. One number stands out and deserves attention rather than celebration: the frame delay rate is reported as 8.47 percent, defined as frames arriving more than 65ms apart, against an average frame interval of 58.07ms. That is a measurement of jitter under a specific cloud network, not a property of the code, and the README does not break it down by STT or TTS provider. Treat the whole table as one configuration on one machine.
Where the open version stops
The README contains a section titled 功能对比, a feature comparison between the open source and commercial versions, presented as an image at docs/images/featture-comparison.png with the note that some features are not open source and that interested parties should make contact. That is the single most important limitation for anyone evaluating this for production, and it is also the least legible part of the repository: the boundary between what the MIT-licensed code does and what requires a commercial arrangement is only visible inside an image. The licence badge and LICENSE link point to MIT, and the README's own disclaimer states that the project provides technical implementation code only, no media content, and that users are responsible for holding the rights to anything they play through it. Read together, those two facts mean the MIT grant covers the code in this repository, not the closed portion, and not the content you route through the voice pipeline. Nothing here is legal advice; if you plan to ship a product, have someone read the comparison image and the licence file rather than trusting a summary. The other structural limit is the dependency floor. MySQL 8.0 plus Redis 7 plus a first-run model download plus native libraries means this is not a drop-in binary. Teams that want a single container with no external database will find the architecture working against them.
What the Python lineage does differently
The obvious comparison is the upstream xiaozhi-esp32-server ecosystem this project is derived from, which is Python. The difference is not language preference, it is packaging. A Python server of this kind is typically a single process you start with a Python entry point, and the operational surface around it is whatever you build yourself. This repository inverts that: it splits management and dialogue into two processes on 8091 and 8092, adds a Vue and Ant Design front end, and puts Flyway migrations, OTA distribution and instance self-registration into the management process. The trade is explicit. You get an admin console and a documented scaling path where new dialogue instances register themselves and devices are rebalanced by OTA. You take on MySQL, Redis, a Java build and a model download before the first device connects. If your team already runs Java services and wants the console, that trade is favourable. If you are prototyping a voice loop on one board and want to iterate on prompts and audio handling, the Python lineage will get you to a working loop with fewer moving parts, and you can move here once you actually need the fleet view.
Upgrade cost and what the release cadence implies
The repository is not archived, the last push is recent, and the release list shows v5.1.0, v5.0.0 and v4.1.0 spaced across 2026, with a major version bump between 5.0.0 and 5.1.0 arriving about a week after the 5.0.0 tag. Major-version tags at that interval suggest the schema and API surface are still moving. For an operator that matters in two places. First, Flyway runs migrations on startup, so a version jump can alter your MySQL schema, and a rollback is not a script the README documents. Second, the dialogue process registers itself with the management process, so a partial upgrade that leaves the two processes on different versions is a state the documentation does not describe. A defensible upgrade procedure is to read CHANGELOG.md before tagging a new version, take a MySQL dump first, and upgrade both processes together rather than one at a time.
Editorial conclusion
Adopt it if you already have xiaozhi ESP32 hardware and want a Java stack with a built-in web console for devices, voices, roles and conversation logs. Skip it if you only need a minimal WebSocket voice loop, or if you refuse to run MySQL 8.0 and Redis 7 alongside a first-run model download. Before committing, read docs/images/featture-comparison.png to see which features are closed, and confirm the ESP32 firmware in docs/FIRMWARE-BUILD.md matches the OTA address your device expects.
Frequently asked questions
What are the two ports in xiaozhi-esp32-server-java?
The management backend xiaozhi-server runs on 8091 and serves the REST API, user, device and role management and OTA upgrades, while the dialogue service xiaozhi-dialogue runs on 8092 and handles the WebSocket and MQTT audio streams. They share MySQL and Redis and scale separately.
What is the default login for xiaozhi-esp32-server-java?
After the containers report healthy, open port 8084 and sign in as admin with the password 123456. The compose file also defaults the application database password to 123456 and the MySQL root password to abc123456, so all three should be changed before the service faces a network.
Is device authentication enabled by default?
No. The compose file comments say an empty XIAOZHI_DEVICE_AUTH_SECRET is the same as having no protection, and the environment example tells you to generate one with openssl rand -hex 16 before deploying externally.
Do I need to download models before xiaozhi-esp32-server-java will start?
Yes, when running from source. The models and lib directories are not in the Git repository, so the download script must run first. If you use third-party APIs for both recognition and synthesis, the lighter download script that fetches only the voice activity detection model and native libraries is enough.
Why does my device still get the old port after I change the server port?
The server and dialogue port properties have to be changed as well. If they are not, the addresses pushed down to the device are still the old ports, and nothing fails loudly because the device simply keeps contacting a port that is no longer listening.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/joey-zhou-xiaozhi-esp32-server-java)Star history chart for your README
[](https://hysenlabs.com/projects/joey-zhou-xiaozhi-esp32-server-java)Was this useful?