nanochat: A $48 GPT-2 trainer that fits on one GPU node
GitHub describes it as The best ChatGPT that $100 can buy.. The repository metadata lists Python as its primary language. The metadata lists the MIT license. This article stays within the project description and details documented in the GitHub repository README.
At a glance
- What is it?
- karpathy/nanochat is a minimal PyTorch harness that trains a GPT-2 capability model in about two hours on an 8xH100 node, with a single depth dial controlling the whole run. It is a research tool, not a production framework, and its trade-offs are clear.
- Who is it for?
- Adopt nanochat if you are a researcher or hobbyist who wants to reproduce GPT-2 grade training on a single node, with a clean, hackable codebase and a community leaderboard for speed. Avoid it if you need a production serving system, multi-node scaling, or support for exotic hardware.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 68 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
Star history
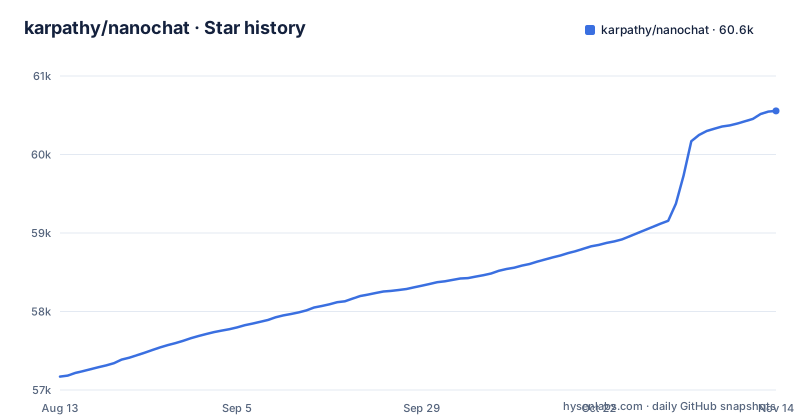
- karpathy/nanochat60,555 ★ · +3,384
| Repository | 2026-08-13 | 2026-11-14 |
|---|---|---|
| karpathy/nanochat | 57.2k | 60.6k |
3,384 Stars in the last 93 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The problem: GPT-2 training cost is still a barrier
In 2019, training GPT-2 cost about $43,000. That figure is from the README, and it is the baseline that nanochat targets. The project's stated goal is to bring that cost down to under $100, and the current speedrun leaderboard shows times around 1.65 hours on an 8xH100 node. At roughly $24 per hour for that node, the cost is about $48, or closer to $15 on a spot instance. This is not a toy. The trained model reaches a DCLM CORE score above the original GPT-2 checkpoint, which the README lists as 0.2565. The audience is clear: researchers who want to experiment with pretraining without a large cluster, and engineers who want to understand the full LLM pipeline. nanochat is not for serving models at scale or for fine-tuning on proprietary data with a polished UI. It is a harness for training from scratch and for studying how compute, data, and hyperparameters interact.
The depth dial: one knob for the whole model family
The core design choice is a single complexity dial: --depth, the number of transformer layers. The README states that all other hyperparameters, including width, number of heads, learning rate, training horizon, and weight decay, are calculated automatically in an optimal way. This is a radical simplification compared to typical training scripts where you juggle a dozen flags. The claim is that GPT-2 capability corresponds to approximately depth 26. For quick experiments, the README suggests a 12-layer model, which it calls GPT-1 sized. This design makes scaling laws experiments tractable: you can run a miniseries of models with different depths and compare their compute-optimal behavior. The trade-off is that you lose fine-grained control. If you want to tweak the learning rate schedule independently of depth, you cannot, at least not without modifying the code. The README says these hyperparameters are calculated automatically; to deviate from them you would need to read or modify the code.
How the pipeline fits together: from tokenization to chat
nanochat covers all major LLM stages: tokenization, pretraining, finetuning, evaluation, and inference. The speedrun.sh script is the entry point: the README says the entire pipeline to train your own GPT-2 and talk to it is contained in that single file. The training loop uses torchrun for multi-GPU, and it automatically falls back to gradient accumulation if you omit torchrun on a single GPU. The evaluation metric is DCLM CORE, which is computed periodically during training. The chat CLI is a simple Python module, scripts.chat_cli, that lets you chat with the trained model. The README shows an example conversation where the model produces a plausible but incorrect explanation of Rayleigh scattering, which is a nice illustration of the capability level: it is GPT-2 grade, not ChatGPT grade. The code is described as minimal and hackable, and it is vanilla PyTorch, so it should run on any backend that supports PyTorch, though the README admits that XPU and MPS paths may have sharp edges.
Getting it running: uv, a speedrun script, and a chat CLI
Setup is straightforward if you use uv. The README gives two commands: uv sync --extra gpu for CUDA, or uv sync --extra cpu for CPU-only or MPS. Then you activate the virtual environment. For development, you add --group dev to include pytest, matplotlib, and other tools. To reproduce the GPT-2 speedrun, you boot an 8xH100 node and run bash runs/speedrun.sh. The README suggests running it in a screen session because it takes about 1.5 hours. After training, you chat with python -m scripts.chat_cli. The script is designed for 80GB GPUs; if you have less, you must reduce --device-batch-size from the default of 32 down to 16, 8, 4, 2, or 1. Below that, the README warns you need to know what you are doing. This is a concrete constraint: the default configuration will OOM on a 40GB or 48GB GPU. The README also notes that the code runs on a single GPU without torchrun, but you wait eight times longer.
The speedrun leaderboard: a moving target
The project's main development focus is the pretraining stage, and it maintains a leaderboard for time to GPT-2. The table shows six entries, with the latest at 1.65 hours, achieved on March 14, 2026. The improvements come from changes like switching to the NVIDIA ClimbMix dataset, bumping the total batch size to 1M tokens, and using fp8. The leaderboard is a community effort, with contributors listed. This is a real mechanism for tracking progress, but it also means the recipe is not stable. The runs/speedrun.sh script is described as the reference, but it changes frequently. If you want to reproduce a specific result, you must check the commit hash associated with that leaderboard entry.The leaderboard lists a commit for each entry, so you may need to check out that commit to get comparable numbers. This is a double-edged sword: it is good for research, but bad for reproducibility in the strict sense. The leaderboard also only measures pretraining time, not the full pipeline including finetuning or evaluation, so it is a narrow metric.
Limitations: memory, single-node, and thin documentation
The most obvious limitation is memory. The default configuration assumes 80GB GPUs. The README explicitly says you will OOM on smaller GPUs unless you reduce --device-batch-size, and below a batch size of 1 you are on your own. This excludes a large class of users who have 24GB or 48GB cards. A second limitation is that it is designed for a single GPU node. The README describes it as designed to run on a single GPU node. The README also notes that the code is vanilla PyTorch and should run on XPU or MPS, but the author has not exercised those paths, so you may encounter sharp edges. The README points to dev/LEADERBOARD.md for leaderboard details and to DeepWiki, Discussions and Discord for questions about the repo.
Alternatives: modded-nanogpt and the full training stack
The README explicitly credits modded-nanogpt as inspiration for the leaderboard. That project takes a different approach: it focuses on a single well-tuned GPT-2 training run, with a fixed model size and manual hyperparameter tuning. nanochat abstracts away the hyperparameters behind the depth dial, while modded-nanogpt exposes them for direct manipulation. If you want to understand the effect of a specific learning rate or weight decay, modded-nanogpt gives you that control. nanochat gives you a faster path to a trained model but less insight into the individual choices. Another alternative is to assemble your own stack with Hugging Face Transformers and a training library like PyTorch Lightning. That gives you full flexibility but requires you to write the tokenization, data loading, and evaluation yourself. nanochat bundles all of that, which is its main value. The trade-off is that you are locked into the author's choices for data, optimizer, and schedule, unless you modify the code.
Maintenance and license: MIT with active development
The repository is not archived, and the leaderboard shows commits from January through March 2026, so it is under active development. The README mentions a Discord channel and a DeepWiki page for questions, which suggests a community around it. The license is MIT, which means you can use, modify, and distribute the code with minimal restrictions. For a research harness, this is ideal. The main maintenance cost is keeping up with the changing speedrun script and dataset choices. If you fork it for your own experiments, you will need to track upstream changes if you want to stay on the leaderboard. There are no formal releases, so you cannot rely on semantic versioning. You must pin a commit hash for reproducible work.
Editorial conclusion
Adopt nanochat if you are a researcher or hobbyist who wants to reproduce GPT-2 grade training on a single node, with a clean, hackable codebase and a community leaderboard for speed. Avoid it if you need a production serving system, multi-node scaling, or support for exotic hardware. Before you commit, verify your GPU memory: the defaults assume 80GB, and you will need to lower --device-batch-size if you have less. Also confirm that your provider's spot pricing makes the $15 to $48 cost realistic, and check the current speedrun.sh for the latest dataset and hyperparameters, as the leaderboard shows frequent changes.
Frequently asked questions
How do I use nanochat?
Install with uv by picking one extra, gpu for CUDA hardware or cpu for CPU-only and MPS, then activate the environment with source .venv/bin/activate. The whole pipeline is in runs/speedrun.sh, which the file says is designed for an 8XH100 GPU node and takes about an hour and a half, after which you chat with python -m scripts.chat_cli.
What is nanochat?
It describes itself as the simplest experimental harness for training LLMs, running on a single GPU node with minimal, hackable code, and covering tokenization, pretraining, finetuning, evaluation and inference. The full run to chat loop is contained in one script, runs/speedrun.sh.
What is karpathy nanochat?
A Python training harness published under karpathy/nanochat, MIT licensed, with version 0.1.0 in pyproject.toml and no GitHub releases. The default branch is master, and the last push was on 2026-09-07.
How big is nanochat?
GPT-2 capability corresponds to a depth of about 26 layers, and a speedrun model is a 4e19 FLOPs model, described as a bit like talking to a kindergartener. For quick experiments the file suggests a 12-layer, GPT-1 sized model, and the leaderboard measures whether a model beats the GPT-2 (1.6B) CORE score of 0.256525.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/karpathy-nanochat)Star history chart for your README
[](https://hysenlabs.com/projects/karpathy-nanochat)Was this useful?