LitGPT: From-Scratch LLM Training and Inference Without the Abstraction Tax
20+ high-performance LLMs with recipes to pretrain, finetune and deploy at scale.
At a glance
- What is it?
- LitGPT is a PyTorch-based toolkit for pretraining, finetuning, and deploying 20+ LLMs with single-file implementations and no abstraction layers. It targets engineers who want control over the full stack, but its reliance on Lightning AI's ecosystem and YAML recipes demands careful evaluation.
- Who is it for?
- Adopt LitGPT if you need a transparent, from-scratch training and finetuning stack for Llama, Qwen, Gemma, or Phi models, and you are comfortable with PyTorch and YAML-driven recipes. Skip it if you want a high-level API with built-in experiment tracking or if your models are outside the supported list.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 5 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
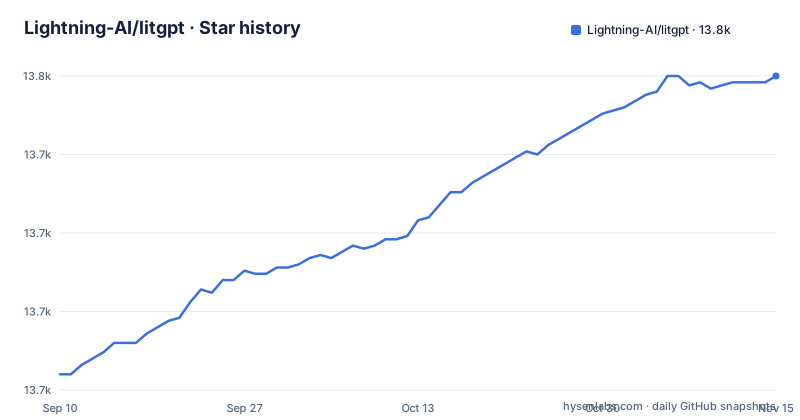
- Lightning-AI/litgpt13,750 ★ · +95
| Repository | 2026-09-10 | 2026-11-15 |
|---|---|---|
| Lightning-AI/litgpt | 13.7k | 13.8k |
95 Stars in the last 66 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The Problem: Opaque LLM Stacks
Most LLM frameworks wrap training and inference in layers of high-level abstractions. That makes quick experiments easy but debugging hard, because you must trace errors through inherited classes and hidden hooks. LitGPT takes the opposite route. Every supported model is implemented from scratch, with single-file implementations and no abstraction layers. The README promises full control and easy debugging. This targets engineers who need to understand exactly what happens inside the forward pass, whether they are modifying attention, adding a new loss term, or profiling memory. It is not for someone who wants a black-box API that hides the model architecture.
From-Scratch Implementations: A Trade-Off
The core design choice is writing each model architecture from scratch rather than reusing a shared transformer base. The benefit is that you can read the entire Llama 3 implementation in one file, without chasing parent classes. The cost is maintenance. Every new model release requires a new implementation, and the project must keep pace with architectural variations across Llama, Qwen, Gemma, and Phi. The README lists over 20 models, including Code Llama, Falcon, and R1 Distill Llama, so the breadth is real. But this breadth comes with a risk: older models like FreeWilly2 may not receive the same optimization attention as newer ones. The project's release cadence, with versions in June 2026 and December 2025, suggests active upkeep, but you should verify that your specific model version is still supported before relying on it.
How It Works: Single-File Models and YAML Recipes
The repository layout, as described in the README, organizes each model as a self-contained module. Training and finetuning workflows are driven by YAML recipes, which the README highlights as 'Proven recipes' tested at enterprise scale. The Python API is minimal. The quick start shows loading a model with `LLM.load("microsoft/phi-2")` and generating text with a single call. This separation means you can treat recipes as versioned configuration files, which is practical for reproducing experiments across teams. The absence of abstraction layers implies that the training loop, optimizer, and scheduler are explicit in the code. For an engineer, that is a double-edged sword: you can modify anything, but you also own everything.
Getting Running: Install and First Inference
Installation is straightforward. The README gives `pip install 'litgpt[extra]'` as the primary command. For source installs, you can clone the repository and run `uv sync --all-extras` or `pip install -e ".[extra,compiler,test]"`. The extra index includes compiler and test dependencies, which suggests optional optimization paths. After install, the Python API is the entry point. The example loads a Microsoft Phi-2 model and runs a spelling correction prompt. That single API call hides the orchestration of downloading weights, setting up the device, and managing inference. The documentation also mentions a full Python API guide in `tutorials/python-api.md`, which is where you would find details on custom generation parameters. The README has its own Finetune an LLM and Recipes (YAML) sections, and the tutorials/ directory holds further guides; consult those for exact finetuning commands.
Scaling and Optimization: FSDP, Flash Attention, and Quantization
LitGPT claims support for Fully Sharded Data Parallel (FSDP), flash attention, and mixed precision from fp4 to fp32. These are concrete mechanisms for scaling from 1 to 1000+ GPUs or TPUs. The README also lists LoRA, QLoRA, and Adapter methods for parameter-efficient finetuning. This is not a toy framework. The presence of fp4 and fp8 quantization indicates a focus on reducing GPU memory for large models, which is useful for inference on low-memory hardware. You cannot assume that a 70B model will run in fp4 on a single consumer GPU without checking the specific recipe. The claim of 'no abstractions' also means you are responsible for understanding FSDP configuration, which is a nontrivial skill.
Where It Hurts: Vendor Lock-In and Documentation Gaps
The README heavily promotes Lightning AI's commercial cloud, including GPU pricing and 'vibe train' workspaces. That is a red flag for teams that want a vendor-neutral toolchain. While LitGPT is Apache-2.0 licensed, which permits unrestricted use, the surrounding ecosystem nudges you toward Lightning Cloud. Check the README's Recipes (YAML) section and the config_hub/ directory before relying on the recipes, and look for benchmark numbers before accepting the 'blazing fast' claim. The project's beginner-friendly claim is also questionable, given the need to understand FSDP, quantization, and model internals.
Alternatives: Hugging Face Transformers and Axolotl
The most direct alternative is Hugging Face Transformers, which provides a unified API for thousands of models, including most of those in LitGPT's list. Transformers uses a shared architecture with model-specific configuration classes, which is the opposite of LitGPT's from-scratch approach. That means easier model swapping and a larger community, but also more abstraction layers and less transparency. For finetuning specifically, Axolotl is a popular YAML-driven tool that wraps Hugging Face and supports LoRA and QLoRA. Axolotl hides even more of the implementation, making it faster to start but harder to debug. If your priority is maximum control over the model code, LitGPT wins. If your priority is broad model support and community documentation, Transformers is the safer default. The choice hinges on whether you value single-file implementations over a mature ecosystem.
Maintenance and License Implications
LitGPT is licensed under Apache-2.0, which permits commercial use, modification, and distribution without royalties. That is a permissive license, and the README explicitly markets it as 'enterprise ready.' However, permissive licensing does not guarantee long-term maintenance. The project's last push was on 2026-11-01, and the latest release is v0.5.13 from June 2026. The version number below 1.0 signals that APIs may change. Upgrading between minor versions could break your recipes or Python scripts. You should pin your dependencies and test upgrades in a staging environment. The reliance on Lightning AI's cloud also means that some features, like 'vibe deploy,' are likely tied to their platform, not the open-source code. For a production deployment, you must separate the core library from the commercial services.
Editorial conclusion
Adopt LitGPT if you need a transparent, from-scratch training and finetuning stack for Llama, Qwen, Gemma, or Phi models, and you are comfortable with PyTorch and YAML-driven recipes. Skip it if you want a high-level API with built-in experiment tracking or if your models are outside the supported list. Before committing, verify that your target model and hardware configuration are covered by the provided recipes, and test the Python API on a small model to confirm the no-abstraction design fits your debugging style. The project is under active development with recent releases, but its README heavily promotes Lightning AI's commercial cloud, so keep the Apache-2.0 library separate from those services if you need vendor-neutral tooling.
Frequently asked questions
How do I install LitGPT and run a model?
Install with `pip install 'litgpt[extra]'`, then load a model by its Hugging Face id and generate: `llm = LLM.load("microsoft/phi-2")` followed by `llm.generate(...)`. From a clone, the README documents `uv sync --all-extras` or `pip install -e ".[extra,compiler,test]"`.
Which Python and torch versions does LitGPT require?
pyproject.toml sets requires-python to >=3.10 with classifiers for Python 3.10 through 3.14, and the base dependency is torch>=2.7 with lightning>=2.6.1. The compiler extra narrows that on Linux with torch<2.13.
Why does the LitGPT compiler extra hold torch back on Linux?
The extra adds lightning-thunder>=0.2.dev20250119 and torch<2.13 for Python 3.10 and up on Linux. pyproject.toml notes that thunder references torch's named-tensor APIs at import time, that those were removed in torch 2.13, and that no thunder release supports 2.13 yet.
What does the extra extra in LitGPT install?
It adds datasets for litgpt.evaluate, litdata==0.2.59 for downloads, litlogger>=0.1.7 for logging, litserve>0.2 for litgpt.deploy, huggingface-hub[hf-transfer] and bitsandbytes. The bitsandbytes pin is >=0.42,<0.43 on darwin and >=0.45.2,<0.50 on linux or win32.
How often does LitGPT release, and is main ahead of the package?
The tagged versions are v0.5.11 from 2025-09-09, v0.5.12 from 2025-12-18 and v0.5.13 from 2026-06-29, and the last push to the repository was 2026-11-01. Code merged after a tag reaches an installed package only at the next version bump.
Does LitGPT depend on Hugging Face transformers?
The dependency list has huggingface-hub, tokenizers and safetensors alongside torch and lightning, and does not include transformers. pyproject.toml describes the project as a hackable implementation of state-of-the-art open-source LLMs, written per model.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/lightning-ai-litgpt)Star history chart for your README
[](https://hysenlabs.com/projects/lightning-ai-litgpt)Was this useful?