FastChat: A Serving and Training Platform That Powers Chatbot Arena
An open platform for training, serving, and evaluating large language models. Release repo for Vicuna and Chatbot Arena.
At a glance
- What is it?
- FastChat is an open platform for training, serving, and evaluating LLM chatbots, best known as the engine behind Chatbot Arena. This review covers its CLI, web serving, API, and evaluation tools, with a focus on practical adoption.
- Who is it for?
- Adopt FastChat if you need a self-hosted, OpenAI-compatible serving layer for multiple open models, or if you want to reproduce Chatbot Arena-style evaluation. Skip it if you need a production-grade, actively maintained serving engine with advanced features like continuous batching and PagedAttention; in that case look at vLLM.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Activity is slowing. The repository last received commits 6 months ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
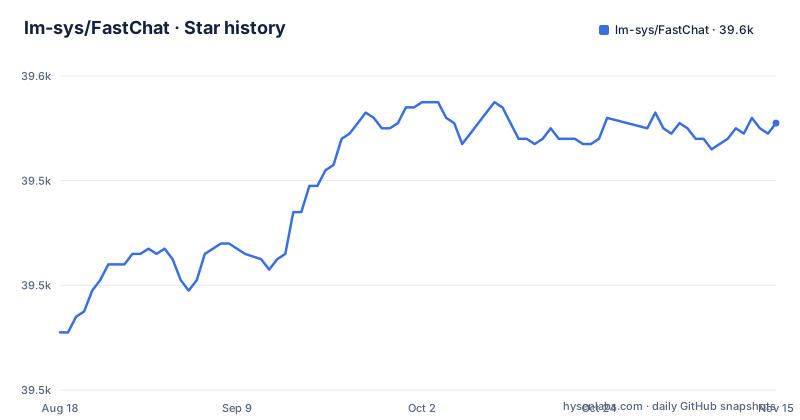
- lm-sys/FastChat39,551 ★ · +40
| Repository | 2026-08-18 | 2026-11-15 |
|---|---|---|
| lm-sys/FastChat | 39.5k | 39.6k |
40 Stars in the last 89 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
What FastChat Actually Solves
FastChat solves a coordination problem: running multiple LLM chatbots in one place, with a consistent interface for training, serving, and evaluating them. It is the release repository for Vicuna and the platform behind Chatbot Arena, which the README says has served over 10 million chat requests for 70+ LLMs. For an engineer, the value is not the models themselves but the glue: a CLI for local inference, a web UI for demos, and an OpenAI-compatible REST API so existing clients can switch backends without rewriting. The project targets researchers and developers who want to stand up a multi-model chat service quickly, or who want to replicate the Arena's side-by-side evaluation workflow. It is less useful if you only need to serve one model in production, because the serving stack is simpler than dedicated inference engines.
The Architecture: Workers, Controllers, and the Web UI
The README describes a distributed multi-model serving system. The install extras are named model_worker and webui, which points to model workers that are separate from the web UI.
Getting Started: Installation and the CLI
Installation is straightforward. The README offers two methods. With pip, run `pip3 install "fschat[model_worker,webui]"`. From source, clone the repo, install Rust and CMake on Mac with `brew install rust cmake`, then run `pip3 install -e ".[model_worker,webui]"`. The extra flags pull in dependencies for model workers and the web UI. After installation, you can chat with a model using the CLI. For example, `python3 -m fastchat.serve.cli --model-path lmsys/vicuna-7b-v1.5` downloads the weights from Hugging Face and starts an interactive session. The command accepts `--num-gpus` for model parallelism and `--max-gpu-memory` to control memory allocation. The README warns that Vicuna-7B needs about 14GB of GPU memory and Vicuna-13B about 28GB. For CPU-only use, it needs roughly 30GB of RAM for the 7B model. These numbers matter for planning hardware. The CLI also supports a `--style rich` option for better text streaming, but the README notes it may not work on all terminals.
Serving with the Web UI and OpenAI-Compatible API
FastChat's core features include a distributed multi-model serving system with a web UI and OpenAI-compatible RESTful APIs, and the README's table of contents has separate Serving with Web GUI and API sections. The API is OpenAI-compatible, which is a major adoption point. If you already have code that calls OpenAI's API, you can point it at a FastChat server, which lowers the barrier to swapping in open models. That compatibility is a concrete reason to choose FastChat over a custom serving script, because it saves client-side work.
Evaluation with MT-Bench and the Arena Methodology
FastChat includes evaluation code, most notably for MT-Bench, a multi-turn question set introduced in June 2023. The README describes MT-Bench as a challenging multi-turn question set for evaluating chatbots. The evaluation workflow is central to the project's identity, since Chatbot Arena collects human votes from side-by-side battles to compile an Elo leaderboard. For a team that wants to benchmark their own model against others, FastChat provides the scripts to run MT-Bench and compute scores. This is a differentiator: most serving platforms do not include an evaluation harness. The LMSYS-Chat-1M dataset, released in September 2023, is also available for real-world conversation analysis, which can be useful for fine-tuning or benchmarking.
Limitations and When It Is the Wrong Tool
FastChat's biggest limitation is its maintenance status. The last release, v0.2.36, was on 2024-02-11, and the last push to the default branch was on 2026-05-01. The README still claims Arena serves over 10 million requests, but that is a product statistic, not evidence of active development. For a production deployment, the lack of updates means you inherit any bugs in the serving stack without patches. The serving system is also simpler than dedicated inference engines. If you need high throughput for many concurrent users, FastChat may not be the best fit. Another limitation is memory. The README's numbers are around 14GB of GPU memory for Vicuna-7B and 28GB for Vicuna-13B. On CPU, 30GB for a 7B model is impractical for many setups. For a quick demo or a research project, these constraints are fine. For a production API serving thousands of requests per second, you should look elsewhere.
Alternatives: vLLM and TGI
The main alternative is vLLM, which is a high-throughput serving engine that uses PagedAttention to manage KV cache memory. FastChat and vLLM solve different problems. FastChat is a platform that includes training, evaluation, and a web UI. vLLM is a pure serving engine, optimized for throughput and latency. If you only need to serve a single model at scale, vLLM is the better choice because it has continuous batching and a more active development cycle. Another option is Hugging Face's Text Generation Inference (TGI), which also focuses on production serving with features like tensor parallelism and quantization. TGI is more geared toward deployment in a cluster. FastChat's advantage is its breadth: you get the CLI, the web UI, and the evaluation tools in one package. But for a serving-only use case, vLLM or TGI will likely give you better performance and more frequent updates.
Maintenance, Licensing, and Upgrade Cost
FastChat is licensed under Apache-2.0, which is permissive for commercial use. The README identifies the listed Vicuna v1.5 weights as Llama 2-based; older Vicuna versions use earlier LLaMA weights. Check the model-specific provenance and applicable license before deployment. The maintenance cost is a concern. Since the last release was in February 2024 and the last push was on 2026-05-01, expect to manage any security or compatibility issues yourself. The upgrade path is also unclear. If you start with v0.2.36 and a new release appears, you will need to read the release notes and test the changes. For a project that is essentially stable but not evolving, the upgrade cost is low in the short term, but the long-term risk is that dependencies like transformers or torch will move on, and FastChat may fall behind. You should pin your dependencies and budget time for periodic testing.
Editorial conclusion
Adopt FastChat if you need a self-hosted, OpenAI-compatible serving layer for multiple open models, or if you want to reproduce Chatbot Arena-style evaluation. Skip it if you need a production-grade, actively maintained serving engine with advanced features like continuous batching and PagedAttention; in that case look at vLLM. Before adopting, verify that your target models are in the supported list, check the memory requirements for your GPUs, and plan for the fact that the project's last release was in early 2024 and the last push to the repository was on 2026-05-01.
Frequently asked questions
how to install fastchat
Either pip3 install "fschat[model_worker,webui]" for the published package, or clone the repository and run pip3 install -e ".[model_worker,webui]" after upgrading pip, with brew install rust cmake first on Mac. Both commands add only the model_worker and webui extras.
what is fast chat
FastChat is an open platform for training, serving, and evaluating large language model based chatbots. It powers Chatbot Arena, which the README says has served over 10 million chat requests for 70+ LLMs and collected over 1.5M human votes.
Does the FastChat pip install bring in the evaluation dependencies?
No. The two documented install commands name only the model_worker and webui extras. The llm_judge extra, which carries openai<1, anthropic>=0.3, and ray, and the train extra, which carries einops, flash-attn>=2.0, and wandb, are defined in pyproject.toml and installed by neither command.
Where does FastChat put the model weights it downloads?
Downloaded weights are stored in a .cache folder in the user's home folder, in the shape ~/.cache/huggingface/hub/<model_name>. The first chat command triggers the download from the Hugging Face repo named in --model-path, which accepts either a repo name or a local folder.
Official sources
Where this project is recommended
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/lm-sys-fastchat)Star history chart for your README
[](https://hysenlabs.com/projects/lm-sys-fastchat)Was this useful?