FunClip: LLM-Assisted Video Clipping on Top of FunASR
FunASR-powered video transcription, subtitle generation, and LLM-assisted clipping tool with a local Gradio UI.
At a glance
- What is it?
- FunClip is a locally deployed Gradio app that transcribes video with FunASR Paraformer models, lets you pick text segments or speakers, and exports clips plus SRT files. The design is coherent for Chinese-language editing, but the model dependencies are where adoption decisions actually get made.
- Who is it for?
- Adopt FunClip if you are cutting Chinese-language interview, podcast, or lecture footage on a machine that can host the recognizer and you want clips and SRT files without uploading media anywhere. Do not adopt it if you need English-first transcription quality, if you cannot install and manage ModelScope model weights.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 13 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
Star history
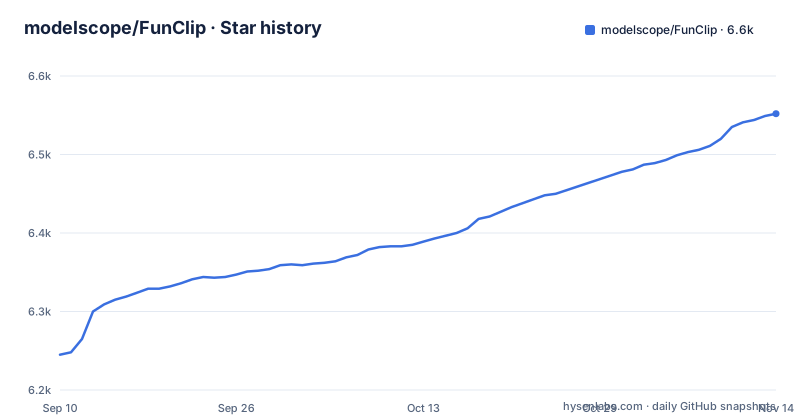
- modelscope/FunClip6,552 ★ · +307
| Repository | 2026-09-10 | 2026-11-14 |
|---|---|---|
| modelscope/FunClip | 6.2k | 6.6k |
307 Stars in the last 65 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The editing step FunClip removes
Cutting a clip out of a recorded talk usually means scrubbing a timeline until you find the sentence you remember, then marking in and out points by ear. FunClip replaces the scrubbing with a transcript. The README describes the flow plainly: FunASR Paraformer models run speech recognition on the video, then the user chooses text segments or speakers from the recognition results and clicks the clip button to get the matching video segment. That is the whole product idea, and it is a good one because the transcript is a better index than a waveform for anything spoken. The target user is someone editing Chinese-language video who is willing to run a local service. The README points at interview and speaker-segmented material through its CAM++ integration, and at entity-heavy speech through SeACo-Paraformer hotwords. It is not aimed at someone who wants a hosted editor with a timeline, effects, and collaborative review. It is aimed at the person who already knows which sentence they want and does not want to hunt for it.
How the ASR, speaker, and clipping layers connect
The mechanism is a pipeline, not a monolith. FunASR performs recognition and, per the README, Paraformer-Large can "accurately predict timestamps in an integrated manner," which is what makes text-to-video mapping possible at all. Those timestamps become the bridge: a selected text span corresponds to a time range, and the clip is cut from that range. On top of the base recognizer sit two optional models. SeACo-Paraformer adds hotword customization so that names and entity words can be supplied before recognition to improve results. CAM++ adds speaker recognition, and the README states that the auto-recognized speaker ID can be used as the trimming target, so you can extract every segment belonging to one speaker rather than every segment containing one phrase. Release v2.2.0 adds a third path: MOSS-Transcribe-Diarize for long-form ASR, timestamps, and anonymous speaker labels without external VAD or speaker models. The output side is equally concrete. FunClip returns full-video SRT subtitles and target-segment SRT subtitles, and v2.2.1 renders built-in subtitles with Pillow specifically so that a selected foreground color survives video encoding. That last detail is a real engineering fix, not a cosmetic one: the README says built-in subtitles are rendered with Pillow so the selected foreground color survives video encoding.
Running the Gradio service and choosing a model
Installation is a clone plus a requirements install. The README gives `git clone https://github.com/modelscope/FunClip.git`, `cd FunClip`, then create a Python 3.12 virtual environment and run `python -m pip install -r requirements.txt`. The service starts with `python funclip/launch.py`. Model selection is passed as flags on that same command. The README lists `-m fun-asr-nano` for the flagship Fun-ASR-Nano model covering Mandarin, English, Japanese, seven Chinese dialect groups, and 26 regional accents; `-m sensevoice` for multilingual ASR plus emotion and audio event detection; `--model moss` for OpenMOSS long-form ASR with anonymous speaker labels and timestamps; `-l en` for English audio; `-p xxx` for the port. There is a versioned snapshot path too: download FunClip-2.2.1.tar.gz or the zip from the release, then verify against the published SHA256SUMS. Model weights are not in those archives; the README says they are downloaded separately when FunClip starts. Two upgrade commands matter. Existing installations should run `pip install -U -r requirements.txt` before restarting, and because the current model and subtitle compatibility paths require it, run `pip install -U "funasr>=1.4.9"` if FunClip was installed before that requirement changed. ImageMagick is now optional: the v2.2.1 Pillow renderer covers standard subtitle clipping, and ImageMagick is only needed for the legacy `funclip/test/imagemagick_test.py` example or your own MoviePy TextClip workflow.
Where the dependency chain becomes the real cost
The heaviest constraint is not FunClip's own code, it is what sits underneath. The README notes that ASR with Whisper timestamps requires massive GPU memory, and that the project supports timestamp prediction for vanilla Paraformer in FunASR to work around this. That sentence tells you the maintainers hit a memory wall and routed around it rather than solving it. The practical consequence: your hardware budget is set by the recognizer, and if you want the long-form MOSS path you are adding a third-party model with its own vLLM adapter requirement. The README states that the MOSS vLLM adapter is part of what `funasr>=1.4.9` brings in, which means the FunASR version pin is not incidental. Pin it wrong and the model path or the normalized `sentence_info` speaker segments will not behave as documented. A second limitation is language. The project's center of gravity is Chinese. English is reachable through `-l en` and through Fun-ASR-Nano's multilingual coverage, but the README's own framing puts Paraformer-Large forward as "one of the best-performing open-source Chinese ASR models," and the ongoing list's Whisper item relies on Paraformer timestamp prediction rather than Whisper timestamps. If your library is English-first, you are on the secondary path. A third issue is the roadmap itself. Reverse-period selection while clipping and silence removal are both still unchecked boxes, so cutting around pauses is manual work today.
FunClip against Whisper-based clipping tools
The obvious comparison is a Whisper-based transcription-and-cut pipeline. The difference is not accuracy claims, it is architecture. FunClip delegates recognition to Paraformer-family models served through FunASR and gets timestamps from the recognizer itself, which is why it can run the whole thing locally without a separate forced-alignment step. A typical Whisper clipping setup either accepts Whisper's segment-level timestamps, which are coarse, or adds an alignment model to sharpen them, and the README's own note about Whisper timestamping needing massive GPU memory describes exactly that pressure. Where Whisper-based tools usually win is language breadth and the size of the surrounding ecosystem, particularly for non-Chinese audio. Where FunClip wins is the Chinese-specific stack: SeACo-Paraformer hotwords, CAM++ speaker targeting, and MOSS anonymous speaker labels are all wired into the same Gradio surface, so a Chinese interview workflow gets speaker-aware clipping without assembling three separate tools. No accuracy numbers, speed numbers or head-to-head evaluation are given here, so treat the model descriptions as the project's characterization rather than measured results.
Licence, upgrades, and what maintenance actually involves
FunClip is MIT-licensed, which is permissive and places few obligations on how you use or redistribute the application code. That licence does not automatically extend to the model weights, which are downloaded separately from ModelScope and carry their own terms, so check each model you launch with before shipping anything commercial. Do not read the MIT label as covering the full stack. Upgrade cost is modest but not zero. The recent release cadence is three releases in about a month (v2.1.1 in early August, v2.2.0 in late August, v2.2.1 on September 1), which means the install instructions and the funasr pin move. The concrete maintenance actions are the two upgrade commands above plus a restart, and the SHA256SUMS verification if you deploy from a release archive rather than a clone. A version bump is something you test rather than assume.
A narrow tool that knows its audience
FunClip is a focused utility with a clear boundary. It transcribes, it maps text and speakers to time ranges, it cuts, and it writes SRT. It does not edit beyond that, and the two unchecked roadmap items (reverse-period selection, silence removal) are the features most likely to send you back to a full editor for finishing work. The v2.1.1 to v2.2.1 releases show active maintenance on the parts that break in practice: subtitle color fidelity, fresh Gradio installs, private-by-default container startup, case-insensitive matching, and MiniMax routing. That is a maintenance pattern aimed at people running the tool, not at people reading about it. The judgement is straightforward. If your source material is Chinese and your machine can host the recognizer, FunClip collapses a tedious manual step into a text selection, and the local deployment means the footage never leaves your hardware. If any of those conditions fails, the dependency chain will cost you more than the clipping saves.
Editorial conclusion
Adopt FunClip if you are cutting Chinese-language interview, podcast, or lecture footage on a machine that can host the recognizer and you want clips and SRT files without uploading media anywhere. Do not adopt it if you need English-first transcription quality, if you cannot install and manage ModelScope model weights. Before committing, verify three things: that funasr>=1.4.9 resolves in your environment, that the Pillow subtitle renderer produces the foreground color you selected after encoding, and that your target language is actually covered by the model you launch with.
Frequently asked questions
How do I install FunClip and start the local interface?
Clone the repository, create a Python 3.12 virtual environment, install with python -m pip install -r requirements.txt, then start the service with python funclip/launch.py.
Which speech models can FunClip use for transcription?
The default is the FunASR Paraformer series. Launch flags cover -m fun-asr-nano for the flagship Nano model, -m sensevoice for multilingual ASR with emotion and audio event detection, --model moss for OpenMOSS long-form ASR with anonymous speaker labels and timestamps, and -l en for English audio recognition.
Does FunClip still require ImageMagick for subtitle clipping?
No. Version v2.2.1 renders built-in subtitles with Pillow and the bundled font, so standard subtitle clipping no longer needs ImageMagick. It remains needed only for the legacy funclip/test/imagemagick_test.py example or your own MoviePy TextClip workflow.
What files does FunClip produce after a clip?
It supports multi-segment free clipping and automatically returns full video SRT subtitles along with SRT subtitles for the target segments. Selection is made in the Gradio page by choosing transcript text or a recognized speaker.
Can FunClip transcribe English audio with Whisper yet?
The README's On Going list has a checked item saying FunClip will support Whisper for English users, with the note that timestamped Whisper ASR requires a lot of GPU memory, so FunClip supports timestamp prediction for vanilla Paraformer instead. Removing silence periods is also still unchecked.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/modelscope-funclip)Star history chart for your README
[](https://hysenlabs.com/projects/modelscope-funclip)Was this useful?