ms-swift: A ModelScope Toolkit for Fine-Tuning and RL on 600+ LLMs and 400+ MLLMs
Use PEFT or Full-parameter to CPT/SFT/DPO/GRPO 600+ LLMs (Qwen3.6, DeepSeek-V4, GLM-5.1, InternLM3, Llama4, ...) and 300+ MLLMs (Qwen3-VL, Qwen3-Omni, InternVL3.5, Ovis2.5, GLM4.5v, Gemma4, Llava, Phi4, ...) (AAAI 2025).
At a glance
- What is it?
- ms-swift is a Python framework from ModelScope that covers pre-training, SFT, preference learning, GRPO-family RL, evaluation, and deployment for a broad catalog of text and multimodal models. It stands out for its breadth of supported algorithms and hardware, but its documentation and release cadence demand careful verification before adoption.
- Who is it for?
- Adopt ms-swift if you need a single toolkit to fine-tune or run reinforcement learning across many Qwen, Llama, GLM, and multimodal models, especially if you are already in the ModelScope ecosystem or require Megatron parallelism for MoE training. Do not adopt it if you need stable, deeply documented production support for a narrow set of models, or if you cannot tolerate frequent releases (v4.5.2, v4.5.3 and v4.6.0 between August and October 2026).
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository received new commits within the last day.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 13, 2026, and from our analysis. They are not legal advice.
Star history
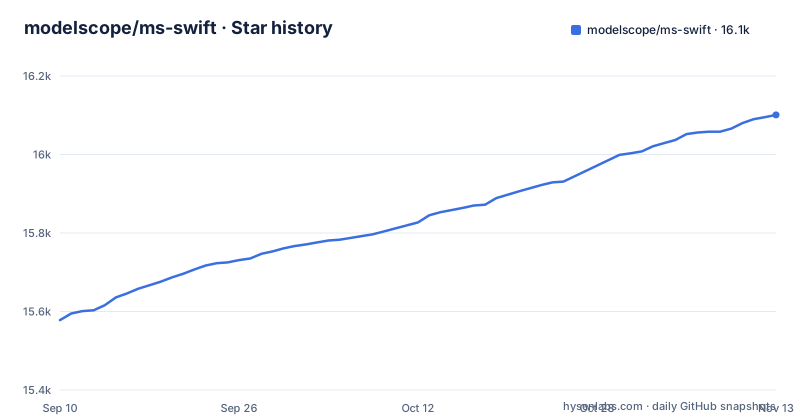
- modelscope/ms-swift16,101 ★ · +523
| Repository | 2026-09-10 | 2026-11-13 |
|---|---|---|
| modelscope/ms-swift | 15.6k | 16.1k |
523 Stars in the last 64 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
What ms-swift actually covers
ms-swift is a training and deployment framework for large language models and multimodal large models. The README claims support for 600+ text-only models and 400+ multimodal models, including Qwen3, Qwen3.5, InternLM3, GLM4.5, DeepSeek-R1, Llama4, Qwen3-VL, Qwen3-Omni, InternVL3.5, Ovis2.5, GLM4.5-V, and others. It is not a single-purpose trainer. It covers pre-training (CPT), supervised fine-tuning (SFT), human alignment via DPO, KTO, RM, CPO, SimPO, ORPO, and reinforcement learning with a broad GRPO family: GRPO, DAPO, GSPO, SAPO, CISPO, CHORD, RLOO, and Reinforce++. It also handles embedding, reranker, and sequence classification tasks. The intended user is an engineer or researcher who needs to fine-tune or align a model from a wide catalog without switching between many separate tools. The project is from the ModelScope community.
The architecture: from data to deployment in one pipeline
The framework is built as a full pipeline. It accepts custom datasets or 150+ built-in datasets for pre-training, fine-tuning, and alignment. The training core supports lightweight methods like LoRA, QLoRA, DoRA, LoRA+, LLaMAPro, LongLoRA, LoRA-GA, ReFT, RS-LoRA, Adapter, and LISA. It also supports full-parameter training. For memory reduction, it integrates GaLore, Q-Galore, UnSloth, Liger-Kernel, Flash-Attention 2/3, and sequence parallelism techniques like Ulysses and Ring-Attention. For distributed training, it offers DDP, device_map, DeepSpeed ZeRO2/ZeRO3, FSDP/FSDP2, and Megatron with TP, PP, SP, CP, ETP, EP, and VPP strategies. That Megatron support is notable because it explicitly targets MoE model training speed. The pipeline does not stop at training. It includes inference acceleration via Transformers, vLLM, SGLang, and LMDeploy, an OpenAI-compatible interface, evaluation through EvalScope with 100+ datasets, and quantization export to AWQ, GPTQ, FP8, and BNB. The README also mentions a Web-UI for training, inference, evaluation, and quantization. That is a wide surface.
How to get it running: commands and config keys
The README links the package on PyPI as ms-swift, so it installs with pip install ms-swift. The documentation link is https://swift.readthedocs.io/en/latest/ for English and the Chinese version is at https://swift.readthedocs.io/zh-cn/latest/. The README says users only need to prepare datasets for one-click training, and it mentions a Web-UI interface for training. For concrete CLI examples and config files, consult the documentation and the repository's examples/ directory (train/, infer/, deploy/, megatron/ and others). The latest releases are v4.6.0 (2026-10-13), v4.5.3 (2026-09-08) and v4.5.2 (2026-08-16), so the project is actively maintained.
Reinforcement learning: a rich but complex menu
One of ms-swift's strongest claims is its support for many GRPO-family algorithms. The README lists GRPO, DAPO, GSPO, SAPO, CISPO, CHORD, RLOO, and Reinforce++. It also says the framework supports synchronous and asynchronous vLLM engine inference acceleration, extensible reward functions, multi-turn inference schedulers, and environments through plugins. That is a substantial RL toolkit. The framework also supports agent training with templates that allow one dataset to be used across different models. That is useful for RL environments. The complexity is real: running RL with a vLLM engine, custom reward functions, and multi-turn schedulers requires a deeper understanding than a feature list provides. The project's value in RL is high, but the learning curve is steep.
Multimodal and hardware support: broad but with caveats
ms-swift claims support for multimodal packing to improve training speed by over 100%, and mixed modality training with text, images, video, and audio. It also allows independent control of the vision encoder (vit), aligner, and LLM parts. That level of control is uncommon and valuable for multimodal research. On hardware, the README lists NVIDIA GPUs (A100/H100/RTX series via CUDA), AMD GPUs (MI300 series via ROCm), Ascend NPU, MetaX GPU, Moore Threads GPU (via MUSA), Apple MPS and CPU. It also claims quantized training on BNB, AWQ, GPTQ, AQLM, HQQ, and EETQ, requiring only 9GB for 7B models. Those are concrete numbers, but they are claims from the README, not from independent benchmarks. The breadth of hardware support is a differentiator, especially the inclusion of domestic hardware like Ascend NPU, MetaX and Moore Threads GPUs. The caveat is that supporting many hardware backends often means that not every feature works on every backend. Verify method and hardware combinations against the documentation.
Limitations and wrong-tool cases
The most obvious limitation is documentation depth. The README is a feature list, not a guide. It points to external docs, with both English and Chinese documentation linked. The project is also moving: v4.5.2 was released on August 16, 2026, v4.5.3 on September 8 and v4.6.0 on October 13. That release cadence suggests steady iteration, which can mean breaking changes. If you need a stable, long-term supported training stack, this may be the wrong tool. Another limitation is the sheer scope. The framework tries to cover training, inference, evaluation, quantization, and deployment across hundreds of models. That ambition can lead to shallow support in any single area. For example, if you only need to fine-tune Llama 3.1 8B with QLoRA, you might be better served by a simpler, more focused tool like Hugging Face TRL. ms-swift is the wrong choice if you need a minimal dependency footprint.
Alternatives: TRL and Axolotl take different paths
A direct alternative is Hugging Face TRL. TRL focuses on SFT, DPO, and PPO, and it is tightly integrated with the Transformers ecosystem. It does not claim support for hundreds of models or multimodal packing. Its approach is modular: you bring your own model and dataset, and it provides trainer classes. ms-swift, by contrast, is a monolithic pipeline with its own dataset handling, inference engines, and quantization. Another alternative is Axolotl, which is a configuration-driven fine-tuning framework that supports SFT and DPO on a range of open models. Axolotl uses YAML config files and is known for reproducibility. It does not cover RL as broadly as ms-swift. The key difference is that ms-swift aims to be an end-to-end platform with a Web-UI and RL algorithms, while TRL and Axolotl are more focused on training loops. If you need GRPO variants or Megatron parallelism, ms-swift's approach is more integrated. If you need a simple, well-documented training run, TRL or Axolotl may be easier to start with.
Maintenance, license, and upgrade cost
The project is licensed under Apache-2.0, which is permissive and allows commercial use and modification. That is a positive for adoption. The repository is not archived, and the last push was November 2, 2026, with the latest release, v4.6.0, on October 13. That indicates active maintenance. The upgrade cost is non-trivial. With releases roughly monthly, you will need to track changes regularly; GitHub releases and the documentation are where to look. The maintenance burden is not just on the project but on you: you must verify that your training scripts and configs remain compatible with each new version. The README mentions 'Day-0 support for popular models', which means the project prioritizes being current with new model releases, but that also means it may break backward compatibility. For a production environment, you should pin a specific version and test upgrades in a staging environment.
Editorial conclusion
Adopt ms-swift if you need a single toolkit to fine-tune or run reinforcement learning across many Qwen, Llama, GLM, and multimodal models, especially if you are already in the ModelScope ecosystem or require Megatron parallelism for MoE training. Do not adopt it if you need stable, deeply documented production support for a narrow set of models, or if you cannot tolerate frequent releases (v4.5.2, v4.5.3 and v4.6.0 between August and October 2026). Before committing, verify that your exact model and training task appear in the supported list, check the documentation for the specific algorithm you plan to use (e.g., DAPO vs. GRPO), and test on a small run with your own dataset to confirm the data format and the Web-UI workflow match your expectations. The framework's value is real but conditional on your ability to navigate its rapid evolution.
Frequently asked questions
What is MS Swift?
SWIFT, which stands for Scalable lightWeight Infrastructure for Fine-Tuning, is the ModelScope community's Apache-2.0 framework for fine-tuning and deploying large and multimodal models. It covers pre-training, instruction fine-tuning, preference learning such as DPO, KTO, CPO, SimPO and ORPO, GRPO family reinforcement learning, evaluation, quantization and deployment.
ms swift vs llamafactory
The repository makes no comparison with LLaMA-Factory. What it describes about itself is breadth: over 150 built-in datasets, lightweight methods including LoRA, QLoRA, DoRA, LoRA+ and LongLoRA, quantized training on BNB, AWQ, GPTQ, AQLM, HQQ and EETQ models needing 9GB for 7B, and inference through vLLM, SGLang and LmDeploy.
ms swift vs unsloth
No comparison with Unsloth appears in the documentation. Unsloth is named only as one of several memory optimization techniques ms-swift supports, alongside GaLore, Q-Galore, Liger-Kernel, Flash-Attention 2 and 3, and Ulysses and Ring-Attention sequence parallelism.
ms swift vs verl
The repository states no comparison with verl. On reinforcement learning it describes its own support: the GRPO family including GRPO, DAPO, GSPO, SAPO, CISPO, CHORD, RLOO and Reinforce++, synchronous and asynchronous vLLM engine acceleration, extensible reward functions, multi-turn inference schedulers, and environments through plugins.
ms-swift vscode debug
The repository does not ship a VS Code configuration. Its top level contains a Makefile with linter, test, whl and docs targets backed by a .dev_scripts directory, plus a .pre-commit-config.yaml, CONTRIBUTING.md and a tests folder. Debugging is therefore handled by whatever setup you configure yourself.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/modelscope-ms-swift)Star history chart for your README
[](https://hysenlabs.com/projects/modelscope-ms-swift)Was this useful?