TinyDB: a pure-Python document store for small apps
TinyDB is a lightweight document oriented database optimized for your happiness :)
At a glance
- What is it?
- TinyDB keeps documents in a JSON file and gives you a Mongo-style query API with no server and no dependencies. It is a good fit for small tools and tests, and the wrong fit once several processes or threads write at once.
- Who is it for?
- Adopt TinyDB when the dataset fits comfortably in memory, one process owns the file, and you want a document API without running a server. Do not adopt it when several processes or threads write concurrently, when you need indexes or transactions, or when the file will grow past what a single JSON load can handle.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 20 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
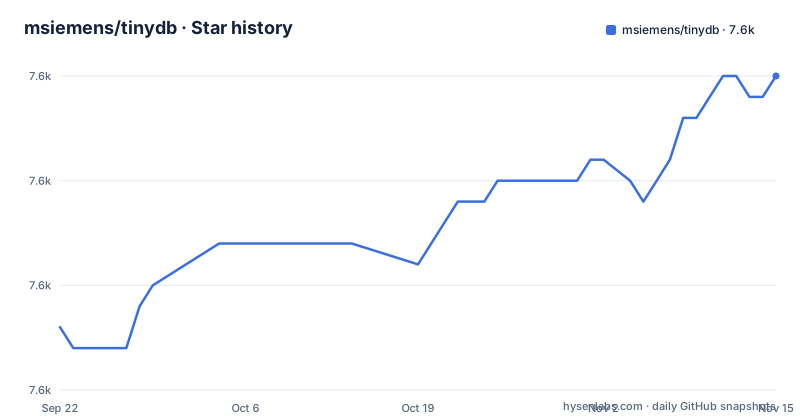
- msiemens/tinydb7,580 ★ · +12
| Repository | 2026-09-22 | 2026-11-15 |
|---|---|---|
| msiemens/tinydb | 7.6k | 7.6k |
12 Stars in the last 54 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
What TinyDB solves, and who it is written for
The README puts it plainly: the target is small apps that would be blown away by a SQL-DB or an external database server. That sentence is the whole positioning. If your program needs to keep a few thousand records between runs and you do not want to run Postgres, SQLite with a schema, or a MongoDB instance, TinyDB gives you a dict-shaped store with no setup step.
The audience follows from that. Command-line tools that keep a cache, desktop utilities, prototypes, test fixtures, and teaching examples. The project describes itself as document oriented like MongoDB: you store any document represented as a dict. There is no schema, no migration step, and no server process. The README also notes it is written in pure Python with no external dependencies, which matters for packaging: a tool that depends on TinyDB has no compiled extension to build.
It is not a general-purpose database, and the README does not pretend otherwise. The size claim is part of the design: the current source is described as 1800 lines of code with about 40 percent documentation, plus 1600 lines of tests. A store that small has a small feature surface by construction.
How the JSON storage and Query layer work together
The architecture is two layers. A storage class owns reading and writing the data, and the TinyDB object sits on top of it, exposing insert, search, update and table operations. The default storage is JSONStorage, which serialises the whole database to a single JSON file. The README shows the constructor taking a path: TinyDB('/path/to/db.json').
Because the default storage is JSON, the file is human-readable: the README's own example code shows a path ending in db.json, so you can open the file with any JSON tool.
Queries are built with the Query class rather than SQL strings. You create a Query object, then compare fields with Python operators. The README shows equality (User.name == 'John'), logical and and or with the & and | operators, negation with ~, and the comparison operators !=, <, >, <= and >=. It also documents map for transforming a field before comparison, and where(...).matches(regex) and where(...).test(your_test_func) for regex and predicate checks. Tables are separate namespaces inside one database: db.table('name') returns a table object with its own insert and all methods.
Storage behaviour can be changed without touching the query layer. The README shows passing a storage explicitly, and shows CachingMiddleware wrapping JSONStorage so that writes are buffered instead of flushing on every operation. That is the documented extension point: new storages, or middlewares that modify how an existing storage behaves.
Install TinyDB and run a first query
The package is published under the name tinydb, which is the name declared in pyproject.toml and the name the README's version badge points at on PyPI. The README's compatibility section says the project has been tested with Python 3.8 to 3.13 and PyPy3, while pyproject.toml declares requires-python as >=3.10,<4. Those two statements disagree; if you are on Python 3.8 or 3.9, check the installed package metadata rather than relying on the README line.
pip install tinydbAfter installing, the smallest useful program creates a database, inserts a document, and reads it back. The README's example uses a path under /path/to/, which you should replace with a real location.
from tinydb import TinyDB, Query

db = TinyDB('/path/to/db.json')
db.insert({'int': 1, 'char': 'a'})
db.insert({'int': 1, 'char': 'b'})
Running that leaves a db.json file at the path you gave, containing the two inserted documents. The README's next example searches it, and the search call returns a list of matching documents.
User = Query()
db.search(User.name == 'John')
Logical combinations use Python's bitwise operators, which is the part that surprises people coming from SQL. Parentheses are required because of operator precedence.
db.search((User.name == 'John') & (User.age <= 30))
db.search((User.name == 'John') | (User.name == 'Bob'))
db.search(~(User.name == 'John'))
To keep the file in a separate namespace, use a table instead of the root store.
table = db.table('name')
table.insert({'value': True})
table.all()
Where TinyDB stops being the right tool
Concurrency is the sharper limitation. The README does not document locking, transactions, or multi-process safety for the JSON storage, and it does not claim thread safety. The documentation is silent on rollback, so a failed write mid-serialisation is not something you can reason about from the README alone.
The README documents no indexes. There is no query planner to inspect and no index to add through the documented API. If your access pattern needs indexed lookups, a different store is the honest answer.
Finally, the project states it is in maintenance mode: it has reached a mature, stable state where significant new features or architectural changes are not planned, though releases for bugfixes and community-contributed features continue. Plan around the current API rather than a roadmap.
TinyDB against SQLite and MongoDB
The closest comparison is SQLite, because both are embedded, file-based and dependency-free for the user. The difference is the model and the guarantees. SQLite is a relational engine with a schema, SQL, indexes, transactions and a C implementation that handles concurrent readers and a single writer safely. TinyDB is a Python library that serialises dicts to JSON with no schema and no transaction layer. Choosing TinyDB over SQLite buys you the dict API and the readable file; it costs you indexes, transactional guarantees, and the ability to query with SQL tooling. If your data is naturally tabular and you want to ask ad hoc questions with sqlite3, SQLite is the better default.
Against MongoDB the difference is operational. MongoDB is a server: it runs as a process, speaks over a network, and brings indexes, replication and a query language of its own. TinyDB is a file. The README's own example code mirrors Mongo's document model, which is why the comparison comes up, but the two do not substitute for each other at any scale where MongoDB is warranted. TinyDB is what you reach for when running a server is the thing you are trying to avoid.
Maintenance status, licence and upgrade cost
The last push to the repository was on 2026-10-26, and the most recent release listed is v4.9.0 from 2026-08-06. The repository is not archived. The project nevertheless describes itself as being in maintenance mode, so the activity you should expect is bugfixes and community-contributed features rather than architectural change. The gap between v4.8.2 in October 2024 and v4.9.0 in August 2026 is a reasonable illustration of that cadence.
Upgrade cost is low in practice. The public surface is small: TinyDB, Query, the storage classes and the middlewares. The one thing to watch when moving between versions is the supported Python range. The README says Python 3.8 to 3.13 and PyPy3, while pyproject.toml requires >=3.10,<4 and lists classifiers up to 3.14. Pin the version you test against and read the changelog before a major bump.
The licence is MIT, declared both in pyproject.toml and in the LICENSE file at the repository root. MIT is permissive: it allows use, modification and redistribution, including in closed-source products, provided the copyright notice and permission notice are retained. That is a description of the licence text, not legal advice; if your organisation has a policy on third-party licences, run it past whoever owns that policy. There is no copyleft obligation here, so TinyDB does not force you to publish the code that uses it.
Editorial conclusion
Adopt TinyDB when the dataset fits comfortably in memory, one process owns the file, and you want a document API without running a server. Do not adopt it when several processes or threads write concurrently, when you need indexes or transactions, or when the file will grow past what a single JSON load can handle. Before committing, install it, write and read a record, then open the JSON file and confirm the on-disk shape matches what you expect. The project states it is in maintenance mode, so treat new features as unlikely and pin the version you test with.
Frequently asked questions
What is TinyDB?
TinyDB is a lightweight document-oriented database written in pure Python with no external dependencies. It stores dicts in a file, and the README describes the target as small apps that would be blown away by a SQL database or an external database server.
How do I install TinyDB?
Install it from PyPI with pip install tinydb. The pyproject.toml declares a Python requirement of >=3.10,<4, while the README says the project has been tested with Python 3.8 to 3.13 and PyPy3.
How do I use TinyDB?
Create a database with TinyDB('/path/to/db.json'), insert a dict, then search with a Query object. The README shows combining conditions with the & and | operators and negating with ~, and shows db.table('name') for a separate namespace.
Is TinyDB thread safe?
The README does not claim thread safety, and it does not document locking or transactions for the JSON storage.
Is TinyDB a NoSQL database?
Yes. The README describes it as document oriented like MongoDB, and you store any document represented as a dict, with queries built from Python comparisons rather than SQL.
How does TinyDB compare with MongoDB?
Both use a document model, but MongoDB is a server process with its own query language, indexes and replication, while TinyDB is a Python library that writes to a file. TinyDB exists to avoid running that server, not to replace it at scale.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/msiemens-tinydb)Star history chart for your README
[](https://hysenlabs.com/projects/msiemens-tinydb)Was this useful?