SQLGlot rewrites SQL through an expression tree, which is where your formatting goes
Python SQL Parser and Transpiler
At a glance
- What is it?
- SQLGlot parses SQL into an AST and regenerates it for over 30 dialects, in pure Python with an optional mypyc build. The parser is lenient on purpose, so a clean parse is not proof your query runs, and the compiled speed path quietly disappears on Python 3.9.
- Who is it for?
- SQLGlot fits teams that need one SQL string rewritten for several engines, or a query parsed into a tree for linting and metadata, and who accept output that is regenerated rather than preserved. It does not fit anyone who needs a validator, since the parser accepts what a real engine would reject.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository received new commits within the last day.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
Star history
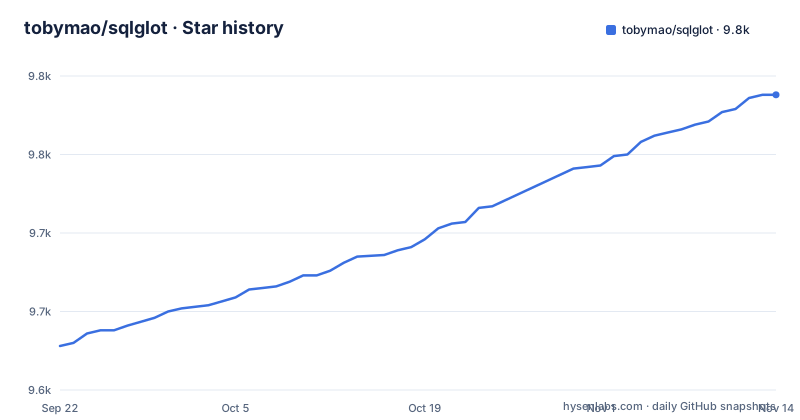
- tobymao/sqlglot9,788 ★ · +160
| Repository | 2026-09-22 | 2026-11-14 |
|---|---|---|
| tobymao/sqlglot | 9.6k | 9.8k |
160 Stars in the last 53 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
parse_one quietly assumes a superset dialect when you leave the source out
The first question in the README's FAQ is about valid SQL that refuses to parse, and the likely cause is a missing source dialect. Call parse_one without one and SQLGlot assumes what it calls the 'SQLGlot dialect', a deliberate superset of every supported dialect, so a construct that only makes sense inside one engine can be read as something else and then rejected further along. The fix the project gives is a single argument: parse_one(sql, dialect="spark"). If parsing still fails after naming the dialect, the instruction is to file an issue. The design choice is intentional: a superset default means you can paste a query from any engine and get a tree back. The cost is that a successful parse tells you nothing about which engine wrote the query, so pass the dialect at every call site instead of hiding it in a helper.
Output is regenerated from the tree, so casing, quoting and comments do not survive
Every output path runs the same two steps: parse into an expression tree, then generate SQL back out of it. What comes back is the meaning of the query rather than its text, so spacing, letter case and identifier quoting can all change in the process. Two flags cover the cosmetic cases: pretty=True for formatted output and identify=True to quote all identifiers, which is what you want when the target engine is strict about reserved words. Comments survive on a best-effort basis only, and a MySQL style `#` comment is rewritten into standard comment syntax rather than left as `#`. The consequence for tooling is concrete: if your pipeline diffs generated SQL against a checked-in expectation file, expect every run to differ on layout unless you normalize it yourself before comparing.
The parser flags some syntax errors and stays quiet on everything else
SQLGlot does detect real syntax problems, and the README names the classes it highlights: unbalanced parentheses and incorrect usage of reserved keywords. Dialect incompatibilities are tracked too, and whether those warn or raise depends on configuration rather than on one fixed default. Past that line, the stance is stated plainly and is the part worth repeating to anyone planning to use this as a lint step. The parser is intentionally lenient so it can accept queries that a real engine would reject, because SQLGlot is a transpiler and not a validator, and a query that parses successfully may still fail at execution time. In other words, you can get a well-formed tree back for SQL that never had a chance on your database. Do not read a clean parse as a pass.
Reading and writing are separate arguments and both fall back to the same default
The same caution applies on the way out. If the generated SQL lands in a dialect you did not expect, the target was never named and the generator used the default too. Naming both ends looks redundant but is the documented path: parse_one(sql, dialect="spark").sql(dialect="duckdb"), or the one-shot form transpile(sql, read="spark", write="duckdb"). What the two arguments control is not just syntax. A DuckDB call to EPOCH_MS becomes a Hive FROM_UNIXTIME wrapping a POW division:
sqlglot.transpile("SELECT EPOCH_MS(1618088028295)", read="duckdb", write="hive")[0]which returns 'SELECT FROM_UNIXTIME(1618088028295 / POW(10, 3))'. Custom format strings move as well, so STRFTIME(x, '%y-%-m-%S') comes out as DATE_FORMAT(x, 'yy-M-ss'). That %- form is dialect-specific syntax, exactly the kind of detail the read argument exists to pin down.
The sqlglot[c] extra is a silent no-op on Python 3.9
There are two install paths and they are not interchangeable. The base one is pure Python with no dependencies. The compiled path adds C extensions built with mypyc, and the project states it is roughly 3 to 5 times faster than the pure Python version, which is why that extra is the recommendation when parsing speed matters. The catch is a version gate: on Python 3.9, installing the compiled extra gives you the pure Python version anyway, and the package metadata expresses that as a marker, c = sqlglotc=={version}; python_version >= '3.10', so the requirement resolves to nothing rather than raising. On 3.10 and newer the install is not even guaranteed to be fast, because a prebuilt wheel is used only when one exists for your platform and the extension builds from source otherwise.
# Pure python version
pip3 install sqlglot

# C extensions compiled with mypyc (Python 3.10+)
# prebuilt wheel if available for your platform, otherwise builds from source
pip3 install "sqlglot[c]"
Subclassing a dialect and the mypyc build do not mix, and the rs extra is deprecated
Adding a dialect SQLGlot does not ship has two routes: subclass an existing one, or publish it as a separate package. The first carries a catch the project names directly, that subclassing may not work properly when the compiled extra is installed, so a custom dialect can force the whole environment back to pure Python and cost you the parsing speedup everywhere else in the process. A packaged dialect avoids inheriting that constraint but adds a dependency and a release you maintain yourself. There is also a deprecated route still visible in the metadata: the rs extra pins sqlglotrs==0.13.0 and states that the Rust tokenizer has been replaced by sqlglotc. Older tutorials that tell you to install the rs extra are pulling a component the project has already moved past, and the hard pin means it will not follow current releases.
Versions come from git tags, and a checkout with no tags reports 0.0.0
The repository publishes no GitHub releases, so the version number is not something you read off a download page. It is derived: the build backend is setuptools with setuptools_scm, which writes the computed value into sqlglot/_version.py, falls back to 0.0.0 when no version can be determined, and uses local_scheme no-local-version so a dirty working tree does not append a local segment. That fallback is where people get caught, since 0.0.0 in a log line is easy to mistake for a real version. The numbering rules are strict about compatibility: PATCH for backwards-compatible changes, MINOR for backwards-incompatible ones, MAJOR for significant backwards-incompatible ones. A MINOR bump can therefore change behavior while the API surface looks untouched, which is the argument for pinning exactly and running your tests on every upgrade.
make install-dev stops mid-run to offer you a Homebrew install of the GitHub CLI
The local checkout path is two Makefile targets. make install runs a pip editable install, optionally switched to uv pip by prefixing the command with UV=1:
# Optionally prefix with UV=1 to use uv for the installation
make install-dev
make install-dev does more. It initializes the git submodule holding the integration tests, installs that submodule, installs the dev extras, and then checks whether gh is on the machine. If it is not there, the target prints a message, reads from standard input, and offers to run brew install gh for you. The reason it wants gh is specific: it is needed to auto-create pull requests for integration tests. On macOS that offer saves a step. On Linux, in a container, or in any non-interactive session there is nobody to answer the prompt, the branch does not apply, and the target prints Skipping and carries on without the pull request automation.
Editorial conclusion
SQLGlot fits teams that need one SQL string rewritten for several engines, or a query parsed into a tree for linting and metadata, and who accept output that is regenerated rather than preserved. It does not fit anyone who needs a validator, since the parser accepts what a real engine would reject. Before you adopt it, pin a version, confirm your Python is 3.10 or newer if the compiled path matters to you, and check whether a custom dialect forces you back to pure Python. The last push landed on 2026-11-02, and under the project's versioning rules a MINOR bump can be backwards-incompatible.
Frequently asked questions
How do I install SQLGlot?
From PyPI, pip3 install sqlglot gives you the pure Python version with no dependencies. For the mypyc compiled extensions use pip3 install "sqlglot[c]", which needs Python 3.10 or newer; on Python 3.9 that extra resolves to the pure Python version.
How do I use SQLGlot to convert a query between dialects?
Pass both ends explicitly, either as transpile(sql, read="spark", write="duckdb") or as parse_one(sql, dialect="spark").sql(dialect="duckdb"). Omitting the read dialect makes the parser assume the SQLGlot dialect, a superset of all supported dialects, which is the usual cause of valid SQL failing to parse.
Is SQLGlot open source?
Yes. The project metadata declares the MIT license and lists Toby Mao as the author, and the base install pulls in no dependencies. Contributions are handled through the contribution guide and the onboarding document in the repository.
What does SQLGlot actually do?
It parses SQL into an expression tree and can format it, transpile it between over 30 dialects such as DuckDB, Presto and Trino, Spark and Databricks, Snowflake and BigQuery, analyze metadata, traverse trees, build SQL programmatically, and run an optimizer. It also detects syntax errors such as unbalanced parentheses and reserved keyword misuse.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/tobymao-sqlglot)Star history chart for your README
[](https://hysenlabs.com/projects/tobymao-sqlglot)Was this useful?