GR00T WBC: three checkpoints and two lookahead budgets
Welcome to GR00T Whole-Body Control (WBC)! This is a unified platform for developing and deploying advanced humanoid controllers. This includes: Decoupled WBC models used in NVIDIA Isaac-Gr00t, Gr00t N1.5 and N1.6 and GEAR-SONIC
At a glance
- What is it?
- The GR00T Whole-Body Control repository is a collection of humanoid controllers rather than one project, and it is honest about being a hub: a decoupled controller for two model generations, a behaviour foundation model with three released checkpoints, and a motion generation model with its own preview release. The model card is the most useful part, because choosing between its checkpoints is a latency decision with two different answers.
- Who is it for?
- This repository fits a team working on humanoid control who wants published checkpoints and the training code behind them rather than a paper alone, since both the deployment framework and the teleoperation stack are here. Three things to plan around.
- Can I use it commercially?
- Check first. The repository uses a licence we do not classify automatically, so read its LICENSE file before any commercial use.
- Is it still maintained?
- Yes. The repository last received commits 11 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
Star history
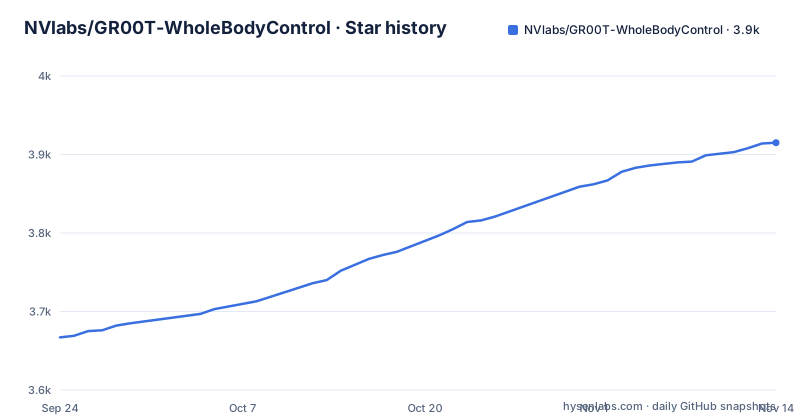
- NVlabs/GR00T-WholeBodyControl3,915 ★ · +248
| Repository | 2026-09-24 | 2026-11-14 |
|---|---|---|
| NVlabs/GR00T-WholeBodyControl | 3.7k | 3.9k |
248 Stars in the last 51 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The checkpoint choice is a lookahead budget, not a preference
The model card is the section to read, and it makes a decision you would otherwise guess at.
Three checkpoints are released, all for one robot platform, and the card says to choose on two axes: the reference representation and the intended deployment.
The original release is the general-purpose one. Its reference input is ten future frames of a body model at twenty millisecond spacing, which the card converts to roughly two hundred milliseconds of lookahead. Its observations are decimated by a factor of five. It lives at the top level of the model repository as an encoder, a decoder and an observation configuration, with the training checkpoint in a release subdirectory.
The low-latency one takes four future frames at the same spacing, so about eighty milliseconds of lookahead, with observations decimated by one. The card says to use its encoder, decoder and observation configuration together, which is the constraint that matters: the three files are a matched set, not three independent downloads.
So the trade is two hundred milliseconds of planning against eighty, and the answer depends on how much you care about response latency against how much you care about how far ahead the controller can see. A teleoperation loop that has to feel immediate wants the short one, and everything else should start with the default.
The wire protocol to the C++ stack changed size in March 2026
One news entry is worth isolating, because it is the kind of change that breaks integrations without breaking anything inside the repository.
The March 2026 entry is a C++ inference stack update, and it lists four things: motor error monitoring, spoken alerts through a text-to-speech path, a version four of the ZeroMQ protocol, and readaptation during idle mode. The last line of the entry is the one to note. The header size for that protocol changed, and it gives the new number.
So any external component speaking to the inference process over that protocol, whether that is a teleoperation front end, a data collection client or your own tooling, needs to be rebuilt against the new header size. Nothing in this repository would fail, because both ends are here.
The other three items are useful signals about the state of the system rather than breaking changes. Motor error monitoring and spoken alerts are the kind of feature you add when a robot is running unsupervised and nobody is watching it. Idle-mode readaptation is what you add when the hardware drifts while the policy is idle.
The root is tooling only, and there are two packages to install
The project manifest opens with a comment that answers the first question anyone has, which is how to install this.
It says the file at the root is tooling configuration only, and then gives the install commands: one for the decoupled package, with optional extras for a full set and a development set, and one for the SONIC package, with extras for teleoperation and for simulation.
So this is a monorepo of two separately installable distributions, each with its own extras, and the root exists to hold the formatting, linting, typing and test configuration they share.
The manifest then holds five tool configurations, and one of them is worth reading for what it excludes rather than what it selects. Both the import sorter and the linter are told to skip a vendored dependencies directory, and the sorter says so three times with three different patterns to make sure the exclusion matches every path spelling.
That vendoring is itself a decision. A project that ships its third-party sources in-tree is choosing reproducibility over a clean dependency tree, and it is why the exclusion lists are defensive.
Four checking tools, two line lengths, and a type checker that is switched off
The tooling configuration is more thorough than most, and the make target that runs it is less thorough than the configuration suggests.
Four tools are configured. One formatter at a line length of one hundred. An import sorter configured to match that formatter's profile. A linter at a line length of one hundred and fifteen. And two type checkers, one of them configured to report no complaint about importing private names, the other configured to ignore missing imports and to check the bodies of unannotated functions.
So there are two different line lengths in one repository, one enforced by the formatter and one by the linter, and the linter will not complain about the formatter's length.
The make target is where the gap shows. It runs the import sorter in check mode, the formatter in check mode and the linter. The type checker line is present and commented out.
That means the type checker is configured, has a per-module override for tests, and is not run by the standard check target. Whether that is deliberate or a leftover is not something the file says, and it is the sort of thing worth asking about before you assume a clean target means a fully checked tree.
The default test run collects one package's tests and logs everything at debug
The test configuration has three settings that describe how the project is actually tested.
First, the test paths point at one package's tests directory, not at a top-level tests directory. So a run with no arguments collects that package's suite and nothing else, even though the repository contains two installable packages.
Second, the class discovery patterns accept two naming conventions at once, which is what you get when a codebase grew by merging two sources.
Third, and this one will surprise you in a CI log, the log level is set to debug and the format includes the logger name. A suite that logs every message at debug produces a lot of output for something you probably wanted to be a quick pass.
None of these is wrong. They are the accumulated settings of a repository where one package arrived later than the other, and together they mean that a green default test run tells you less than you would assume: one package's tests, one class naming convention, and a log volume sized for debugging rather than for CI.
Checkpoints arrive through LFS and a download script, and the repo ships services
The top level explains how a repository with model checkpoints and a robot in it is laid out, and several entries exist for that reason alone.
There is a configuration file for Git's large file storage, which is how the weights are stored rather than committed as ordinary blobs. There is a script whose name says it downloads from the model hub, which is the supported way to fetch the released checkpoints rather than cloning them. And there is a script whose name says it checks the environment, which is what you run before discovering a missing dependency at inference time.
Then the directories that are not code. One for the robot hardware. One for install scripts. One for legal files, and a citation file at the root, which together are the paperwork a research release needs. One for a vendored dependencies tree. One for a deployment variant of the SONIC package. One for a service manager unit directory, which means at least one component here is meant to run as a background service on a robot rather than as a command you start by hand.
And a media directory plus a shell script for linting, which is the same four-tool checking story from the previous sections, reachable from a terminal.
Eleven dated entries in ten months, and one date written three ways
The news list is the best available record of how this project moves, and it is dense.
It opens with an initial release in November 2025 carrying only the decoupled controller for two model generations. Then a foundation-model release in February 2026 with checkpoints, a C++ inference stack, virtual-reality teleoperation and documentation. Then, in March, the inference protocol update described earlier and the open-sourcing of a human motion dataset, which the entry sizes at over a hundred and forty thousand motions, roughly two hundred and eighty-eight hours, with simulated trajectories for the same robot.
April brings a browser demo you can try without hardware and a preview release of the motion generation model with three kinds of pretrained checkpoint. May brings an end-to-end workflow on the robot covering data collection, fine-tuning a model generation and deployment through the controller. June brings the low-latency checkpoint and, separately, teleoperation setup documentation for a cloud and device path that now runs in process with no separate publisher container. July brings the version one point one checkpoint. August brings a per-motor gain fix for a controller that was stumbling.
One entry breaks the pattern: the teleoperation setup entry is dated with a two-digit month and no year, while the entry right after it carries the full date. Which means the list is maintained by hand, and the last thing in it is a bug fix rather than a capability.
Editorial conclusion
This repository fits a team working on humanoid control who wants published checkpoints and the training code behind them rather than a paper alone, since both the deployment framework and the teleoperation stack are here. Three things to plan around. The checkpoint choice is a real engineering decision rather than a preference, because the default and the low-latency model expect different observation settings and cannot be mixed. The wire protocol to the C++ inference stack changed size in March 2026, so anything you built against an earlier release needs checking. And the root of the repository is tooling configuration rather than an installable package, with two separate packages to install and a test configuration that only collects one of them.
Frequently asked questions
What is in the GR00T Whole-Body Control repository?
Model checkpoints and scripts for training, evaluating and deploying whole-body controllers for humanoid robots: a decoupled controller using reinforcement learning for the lower body and inverse kinematics for the upper body, used in two model generations; the SONIC behaviour foundation model with its training code, deployment framework and teleoperation stack; and MotionBricks, a real-time latent generative motion model.
How do I choose between the GR00T SONIC checkpoints?
On reference lookahead and deployment. The original release takes ten future frames at twenty millisecond spacing, about two hundred milliseconds, with observations decimated by five. The low-latency one takes four frames, about eighty milliseconds, decimated by one, and its encoder, decoder and observation configuration must be used together.
How do I install the GR00T Whole-Body Control packages?
The root project file is tooling configuration only. You install the two distributions separately with an editable install, choosing extras such as a full or development set for the decoupled package, and teleoperation or simulation for the SONIC package.
What does GR00T SONIC learn from?
The model card describes motion tracking used as a scalable training task, so that one unified policy produces whole-body movement across behaviours from walking and crawling to teleoperation and multi-modal control, rather than a separate controller per predefined motion. It is trained from large-scale human motion data.
Do GR00T SONIC releases stay wire-compatible?
Not always. A March 2026 entry records a C++ inference stack update that moved the ZeroMQ protocol to version four and changed the header size to 1280 bytes, so external clients built against an earlier release need updating.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/nvlabs-gr00t-wholebodycontrol)Star history chart for your README
[](https://hysenlabs.com/projects/nvlabs-gr00t-wholebodycontrol)Was this useful?