QeRL uses quantization noise as an exploration mechanism
[ICLR 2026]QeRL enables RL for 32B LLMs on a single H100 GPU.
At a glance
- What is it?
- An NVlabs framework that pairs NVFP4 quantization with LoRA so a 32B model can take reinforcement learning on a single H100 with 80 GB, and whose more interesting claim is that quantization noise raises policy entropy and therefore helps exploration. Built on the open-r1 training stack, with a quantize-then-train workflow across two separate conda environments.
- Who is it for?
- Adopt QeRL if you are running reinforcement learning on a model too large for the hardware you have, or if you have observed that your policy stops exploring and you want a knob that addresses entropy directly rather than through a learning rate schedule. The adaptive quantization noise mechanism is the part with an idea behind it, and the single-GPU 32B claim is the part with consequences for your cluster bill.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Activity is slowing. The repository last received commits 7 months ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 13, 2026, and from our analysis. They are not legal advice.
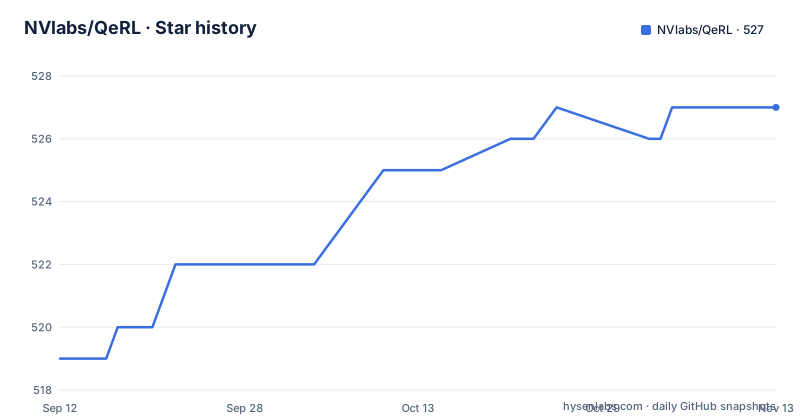
Star history
- NVlabs/QeRL527 ★ · +8
| Repository | 2026-09-12 | 2026-11-13 |
|---|---|---|
| NVlabs/QeRL | 519 | 527 |
8 Stars in the last 62 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The noise is the feature, not the cost
Most quantization work is framed as a loss you accept for a memory saving. This project argues the opposite, and that argument is the paper. The stated finding is that quantization noise increases policy entropy, which enhances exploration and enables the discovery of better strategies during reinforcement learning. Entropy in a policy is the quantity that says how much probability mass is spread across actions, and an RL run that collapses early stops trying alternatives. So if adding noise at initialization raises entropy and reward then grows faster, the noise has done something a learning rate schedule usually gets credit for. The framework follows that finding rather than merely tolerating it: an adaptive quantization noise mechanism dynamically adjusts the noise during training rather than leaving it at a fixed level. Reinforcement learning for large models is described as resource-intensive in two ways, requiring substantial GPU memory and long rollout durations, and the framework targets both, with the rollout phase named as the one it accelerates.
One H100 with 80 GB is the claim that changes the bill
The headline is a capacity claim rather than a speed claim: this is described as the first framework to enable reinforcement learning training of a 32B model on a single H100 80GB GPU. Everything else follows from that. Supporting the model at that size without it would mean a multi-GPU node, and the difference between one card and a node is the difference between a workstation experiment and a shared cluster job. The reported speed result is separate and smaller: over 1.5 times speedup in the rollout phase, with the note that the gain is larger for longer reasoning traces. That qualifier matters, because rollout dominates the wall clock when a model generates long chains of thought, so the benefit scales with the task rather than being a fixed percentage. The accuracy claims are stated as comparisons: faster reward growth and higher final accuracy than 16-bit LoRA and QLoRA, and performance matching full-parameter fine-tuning on mathematical benchmarks, with GSM8K at 90.8 percent and MATH 500 at 77.4 percent in the 7B model. All of these are claims from the project's own write-up rather than independent measurements.
You quantize your own checkpoint first, in a second environment
The training workflow has a prerequisite that is easy to miss, and it runs in a different Python version from the training environment. To bring your own model you first build the quantization tool, following an instruction document inside the repository, then create a separate conda environment on Python 3.12, install the tool in editable mode along with a management library, and run the quantization script once per model:
cd llm-compressor
conda create -n llmcompressor python=3.12 -y
conda activate llmcompressor

pip install -e .
pip install nvidia-ml-py

python quantize_nvfp4.py --model Qwen/Qwen2.5-3B-Instruct
python quantize_nvfp4.py --model Qwen/Qwen2.5-7B-Instruct
python quantize_nvfp4.py --model Qwen/Qwen2.5-14B-Instruct
python quantize_nvfp4.py --model Qwen/Qwen2.5-32B-Instruct
Four lines, one per model size, is a fair summary of the cost: quantizing a model is a batch job you run before training exists. The main training environment is a different one, created on Python 3.10 with a CUDA toolkit from a labelled channel, followed by a setup script in the repository that installs the rest. Two environments on two Python versions for one pipeline is not elegant, and it is the direct consequence of the quantization tool having its own dependency requirements.
Two training scripts, one of them the baseline you are meant to beat
Training itself is two shell invocations, and the pairing is the point:
bash training/dapo_qwen2.5-7b_nvfp4_single_gpu.shbash training/dapo_qwen2.5-7b_bf16_single_gpu.shThe first is QeRL with the quantized format, the second is vanilla 16-bit LoRA, and both are named for a 7B model on a single GPU. Publishing the baseline script next to the method is the part of this repository worth copying: it means the comparison in the write-up is one command away rather than something you have to reconstruct. The name also tells you the algorithm family, since the file prefix is the GRPO-style recipe used elsewhere in the open-r1 ecosystem, and the same page describes the GRPO result separately, noting that the quantized model reaches a better converged reward score and grows reward faster. The figures on the page cover rollout throughput for Qwen2.5 14B and 32B instruct models across different LoRA ranks, so rank is treated as a variable rather than fixed.
Set the memory utilization lower than usual, because the model is already small
The hints section contains the practical advice, and the first one is unusual enough to be worth quoting in full. GPU memory usage is controlled by a parameter in the training script that configures how much of the card the inference server may take, and for this framework the README recommends setting that value smaller than usual, because the model uses the quantized format which is already optimized for reduced memory consumption, and lowering it helps use memory resources better without compromising training stability, especially on cards with limited memory. The logic is that the usual calibration assumes a full-precision model that needs the headroom, so carrying that value over to a quantized one leaves the reserve unused. The second hint is more conventional: tune the per-device training batch size and the gradient accumulation steps to match your hardware and your target effective batch size, and reduce the per-device batch size when memory is tight. Both are the kind of guidance that saves a day of out-of-memory failures and that no framework can apply for you.
The packaging is open-r1's, down to the HuggingFace copyright header
The repository structure explains what this project is built on. There are directories for training scripts, evaluation, recipes, a replacement layer, a trainer, shared utilities, the quantization tool, an open-r1 tool directory and a single entry module. The packaging file makes the lineage explicit: its header is the Apache 2.0 notice from the HuggingFace team, it says in a comment that it was adapted from the transformers setup file, and it still cleans up a stale egg-info directory named after open-r1. Its dependency list is open-r1's, with fast-moving packages pinned exactly, which the file explains is deliberate for things like the trainer library, alongside acceleration, bitsandbytes, datasets, a pinned DeepSpeed release and a data-labeling library. The Makefile is more revealing still. The development environment is built with a Python 3.11 virtual environment, a pinned vLLM release, flash attention installed without build isolation, and the project installed in editable mode with Git LFS smudging disabled. Style and quality targets run a formatter, an import sorter and two linters at a line length of 119, and evaluation runs through a harness that shells out to a specific evaluation package with a chat template and fixed generation settings.
The README installs Python 3.10, the Makefile uses 3.11
Two documented setup paths disagree, and that is the last thing worth checking before you start. The README path is conda based: create an environment on Python 3.10, activate it, install CUDA from a labelled channel, install the toolkit from the same channel, and run the setup script in the repository. The Makefile path is a Python virtual environment built by a different tool on Python 3.11, with vLLM pinned to a specific patch release and flash attention built without isolation. Neither is labelled wrong, but they are not interchangeable, and the README does not mention the Makefile targets at all. Two smaller signals in the same direction. The news section has a single entry, recording that the paper and the repository with all training and inference code were released in October 2025, and there are no GitHub releases, so nothing to pin. And the default branch was last pushed on 30 March 2026, which is the date to plan around if you are depending on fixes.
Editorial conclusion
Adopt QeRL if you are running reinforcement learning on a model too large for the hardware you have, or if you have observed that your policy stops exploring and you want a knob that addresses entropy directly rather than through a learning rate schedule. The adaptive quantization noise mechanism is the part with an idea behind it, and the single-GPU 32B claim is the part with consequences for your cluster bill. Do not adopt it as a general quantization toolkit, because the NVFP4 path is specific, the requirement is hardware that supports the format, and the reported benchmark numbers are on mathematical tasks. Four things to check first. Whether your GPU supports the NVFP4 weight format, since the tested list names specific architectures and other setups are described as untested. Whether you already have a quantized checkpoint or will build one, because that step is a separate tool in a separate environment. Which Python you are on, since the README and the Makefile disagree. And whether the evaluation path works for you, since it is built around a specific harness and specific generation settings.
Frequently asked questions
What is QeRL?
A quantization-enhanced reinforcement learning framework for large language models from NVlabs, combining NVFP4 quantization with Low-Rank Adaptation. It is described as the first framework to enable reinforcement learning training of a 32B model on a single H100 with 80 GB, while delivering over 1.5 times speedup in the rollout phase.
Why does QeRL add quantization noise on purpose?
Because the project's stated finding is that quantization noise increases policy entropy, which enhances exploration and helps the discovery of better strategies during reinforcement learning. The framework follows that finding with an adaptive quantization noise mechanism that dynamically adjusts the noise during training rather than leaving it fixed.
What hardware does QeRL need?
An Nvidia GPU that supports the NVFP4 weight format with triton, with the tested examples given as an RTX 5090, an H100 and a B100, running on Linux with 64 GB of RAM. The README says other hardware setups could work but have not been tested.
How do I quantize a model for QeRL?
In a separate environment: build the quantization tool following the instruction document in the repository, create a conda environment on Python 3.12, install the tool in editable mode along with a management library, then run the quantization script once per model, for example against Qwen instruct models at 3B, 7B, 14B and 32B.
How does QeRL compare with 16-bit LoRA and QLoRA?
The project's write-up reports faster reward growth and higher final accuracy than both, and performance matching full-parameter fine-tuning on mathematical benchmarks, with GSM8K at 90.8 percent and MATH 500 at 77.4 percent for the 7B model. Both a QeRL script and a 16-bit LoRA baseline script are included in the training directory.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/nvlabs-qerl)Star history chart for your README
[](https://hysenlabs.com/projects/nvlabs-qerl)Was this useful?