ToolOrchestra ships Orchestrator-8B and three conda environments, and the last commit is dated 2026-03-25
ToolOrchestra is an end-to-end RL training framework for orchestrating tools and agentic workflows.
At a glance
- What is it?
- An end-to-end RL training framework from NVIDIA for training small models that call tools and specialist models in turns. The results are published and the checkpoints are on Hugging Face, while the run instructions assume an internal Slurm account and three separate Python environments.
- Who is it for?
- ToolOrchestra is a research artifact rather than a library. The paper, the dataset and the checkpoints are public, the training entry point is a single script named after the GPU it was written for, and the tau2-bench setup assumes an internal Slurm account and a Lustre filesystem that no outside user has.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Activity is slowing. The repository last received commits 7 months ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 13, 2026, and from our analysis. They are not legal advice.
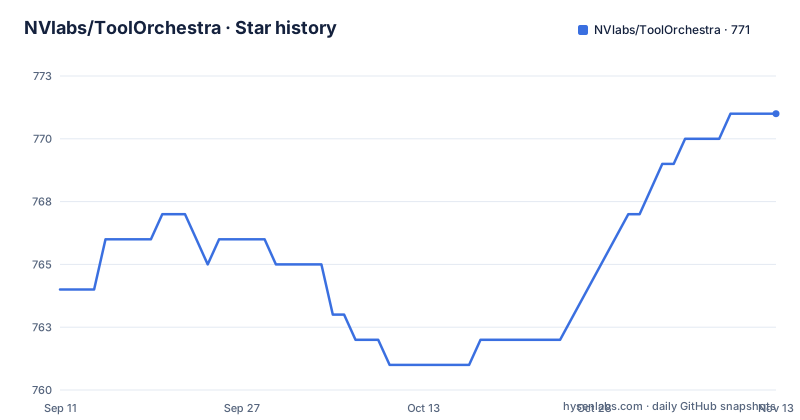
Star history
- NVlabs/ToolOrchestra771 ★ · +7
| Repository | 2026-09-11 | 2026-11-13 |
|---|---|---|
| NVlabs/ToolOrchestra | 764 | 771 |
7 Stars in the last 63 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The news block is dated, and the last commit is dated too
Three dated lines record the publication sequence. On 2025/11/27 the code, training data and model checkpoints of ToolOrchestra were released. On 2025/12/2 the project was reported at number one on the GAIA benchmark. On 2025/12/5 the generated dataset ToolScale became the most downloaded dataset on Hugging Face, and Nemotron-Orchestrator-8B ranked third among all models.
Those three lines are the whole release history in the project file, and there is nothing after them. The repository has no GitHub releases at all, so the dated list and the repository's own history are the only record available.
The last commit is dated 2026-03-25, and no commits have landed since. The paper is on arXiv under 2511.21689, authored by Hongjin Su and Shizhe Diao as equal contributors with fourteen further names from NVIDIA and the University of Hong Kong. What you get from a clone today is the state of the project as it stood in late March, not a moving target, and the release announcements in the file are seven months older than that commit.
That gap matters for anyone planning to build on it. The checkpoints and the paper are fixed artifacts you can evaluate. Anything that depended on later fixes to the training or evaluation code will not be in what you download.
The headline numbers are two scores and a cost ratio
Three benchmarks carry the results, and they are stated in a compact form. On HLE, Orchestrator-8B scores 37.1%, ahead of GPT-5 at 35.1%, and is described as 2.5 times more efficient. On τ²-Bench and FRAMES, the claim is wider: Orchestrator-8B surpasses GPT-5 by a wide margin while using roughly 30% of the cost.
The mechanism behind those numbers is the reason the model is small. Given a task, the Orchestrator alternates between reasoning and tool calling across multiple turns, and the tool set has three tiers: basic tools such as web search and a code interpreter, specialised models such as coding and math models, and generalist models named as GPT-5, Llama-Nemotron-Ultra-253B and Claude Opus 4.1. The 8B model is not answering; it is deciding who answers.
Training is where the efficiency comes from. The Orchestrator is jointly optimised by outcome, efficiency and preference rewards through end-to-end reinforcement learning, so spending less is part of the objective rather than a lucky side effect. Alongside that, an automatic pipeline synthesises both the environment and the tool-call tasks at scale, which is what makes the RL loop possible without hand-building thousands of tasks.
Each benchmark also runs in its own environment. HLE and FRAMES both need the vllm1 and retriever environments, while τ²-Bench needs vllm1 alone.
Three conda environments, three different torch lines
The setup is split into three named environments, and they do not share a dependency line.
The training environment is python=3.12, then pip install -r requirements.txt, then flash-attn installed with --no-build-isolation, then flashinfer-python from a wheel index built for cu124 and torch2.6, then the rollout package installed from training/rollout in editable mode. The retriever environment pins the older stack explicitly:
conda install pytorch==2.4.0 torchvision==0.19.0 torchaudio==2.4.0 pytorch-cuda=12.4 -c pytorch -c nvidiaThat is torch 2.4 with CUDA 12.4, against the flashinfer index built for torch 2.6. The vLLM environment then goes the other way: torch with no version at all, transformers held below 4.54.0, and vllm==0.9.2 with a comment saying it is for gemma-2-9b-it.
So a reproduction involves three interpreters, and the transformers ceiling and the torch pins are the constraints that decide whether the pieces fit together. Nothing in the file resolves that for you; the evaluation section only says which pair of environments each script needs.
The tau2-bench setup is an srun job on an internal account
Evaluating on τ²-Bench needs a rebuilt container image, and the recipe for that rebuild is a Slurm job specification rather than a docker command. It requests the interactive partition for four hours on one node with 128 CPUs per task and 8 GPUs, names the accounting group nvr_lpr_agentic, points at a container image stored under /lustre/fsw/portfolios/nvr/users/$USER/docker/s1.sqsh, saves the rebuilt image back to that path, and mounts $HOME and /lustre into the container.
Only the last part of that block is portable:
pip uninstall -y tau2
cd toolorchestra/evaluation/tau2-bench
pip install -e .
The reason given for rebuilding is that the evaluation requires a local installation of tau2, and the fix is to remove the existing tau2 and install the local copy inside the new image. That part any user can follow. The srun line above it cannot be followed outside that cluster: the partition name, the accounting group and the Lustre image path all belong to one internal filesystem.
Worth knowing before you plan around it: the one evaluation among the three whose setup is not self-contained is also the one whose environment list is the shortest, since it needs vllm1 and not the retriever.
Customization means editing fixed line numbers
The extension points are named precisely, and the precision is the problem. To change the model call you modify the get_llm_response function in LLM_CALL.py, which is the route to services beyond vLLM and OpenAI. To change prompts you edit lines 455-458 in eval_hle.py and lines 506-509 in eval_frames.py. To use a different tool set you substitute the tool_config variable at line 27 in both files. Tools and models are changed in tools.json and in the call_tool function in eval_hle.py. To run experiments in parallel you edit variables named {EXPERIMENT_NAME1}, {EXPERIMENT_NAME2} and {EXPERIMENT_NAME3} in training/resume_h100.py, and those names are supposed to match file names in the directory.
Line 455 and line 27 are the kind of instruction that survives exactly until someone reformats a file or adds an import. There is no configuration file for prompts and no flag for the tool set, so a change to the prompt means finding the right four lines again after every pull.
The connection-error workaround has the same shape. To stop errors reaching host models during HLE, you are told to comment one line in run_hle.py, then run run_hle.py and eval_hle.py in separate processes so the driver and the evaluator do not share a connection.
requirements.txt is a frozen environment with the optional GPU blocks commented out
The requirements file is a freeze dump rather than a curated list. It runs for hundreds of lines with exact pins on packages that have nothing to do with the project logic, including argon2-cffi, docker-pycreds, blake3, asciitree and cmake, which is the signature of one machine's environment captured in full.
Inside it, optional pieces are present as comments. A whole RAPIDS block is commented out, covering cudf, cugraph, cuml and the related packages at 24.6.0, with a note to install them separately through pip with an extra index URL pointing at pypi.nvidia.com. dask-cuda and dask-cudf are commented out next to a live dask pin. dbus-python is commented out with a note that it is a system package to install through apt, and distributed-ucxx is commented out too.
What stays enabled is the CUDA-adjacent core: cupy-cuda12x, cuda-python, and the transformers and datasets stack. So the file is a working environment with the graph and vector-library branches switched off, and a reader who wants the RAPIDS path has to turn those lines back on against a different index.
The repository root has no Dockerfile and no packaging metadata. The top level holds LLM_CALL.py, prepare_sft_data.py, requirements.txt, THIRD_PARTY_NOTICES.md, and the data/, data_synthesis/, evaluation/ and training/ directories.
Two API keys and two cloned repositories before training starts
The environment setup asks for two external services and two Hugging Face clones.
git clone https://huggingface.co/datasets/multi-train/index
export INDEX_DIR='/path/to/index'
git clone https://huggingface.co/nvidia/Nemotron-Orchestrator-8B
export CKPT_DIR='/path/to/checkpoint'
The search key is separate: TAVILY_KEY, obtained by applying for an API key at app.tavily.com, plus WANDB_API for experiment tracking. HF_HOME and REPO_PATH complete the set. The retriever environment installs tavily-python alongside pyserini, faiss-gpu, uvicorn and fastapi, which means retrieval is served as its own process rather than called as a library, and that process is the one the retriever environment exists for.
Training itself is one command, and the script name carries a hardware assumption:
cd training
python resume_h100.py
resume_h100.py is the entry point for resuming training, and the parallel experiment variables are edited inside that same file. There is no configuration file for the training run and no documented flags, so changing anything about training means reading the script.
Every benchmark has its own entry script and its own environment pair
Evaluation is three scripts in one directory, each with its environment requirements written next to it.
cd evaluation

# Evaluate on HLE (requires env: vllm1 and retriever)
python run_hle.py
FRAMES runs from the same directory with the same pair of environments, and τ²-Bench has its own run.py inside the tau2-bench subdirectory, needing vllm1 only. The asymmetry is not explained. Either the benchmark's retrieval needs differ, or the environment list is simply inherited from whichever script was written first.
The data synthesis side of the project lives in data_synthesis/, and prepare_sft_data.py sits at the root to prepare supervised fine-tuning data from it. The training directory is where the RL rollout package lives, since the training environment installs it with pip install -e from training/rollout rather than from the root.
Putting the pieces together, the repository is a research codebase rather than a distributed package: frozen environment files, one training script named for an H100, three evaluation scripts with different environment needs, an internal cluster recipe for one of them, and fixed line numbers as the extension mechanism.
Editorial conclusion
ToolOrchestra is a research artifact rather than a library. The paper, the dataset and the checkpoints are public, the training entry point is a single script named after the GPU it was written for, and the tau2-bench setup assumes an internal Slurm account and a Lustre filesystem that no outside user has. Use it to reproduce the Orchestrator-8B numbers or to study how outcome, efficiency and preference rewards are combined. Skip it if you want something you can install and call, because customization means editing fixed line numbers in the evaluation scripts. Note the publication state: code, data and checkpoints were released in November 2025, and the last commit to this repository is dated 2026-03-25.
Frequently asked questions
What is ToolOrchestra and who built it?
An end-to-end RL training framework for orchestrating tools and agentic workflows, from NVIDIA and the University of Hong Kong under the Apache 2 license. It trains small orchestrators that alternate between reasoning and tool calling across multiple turns.
What is Orchestrator-8B and how does it score?
The 8B model the project produces, published as nvidia/Orchestrator-8B on Hugging Face. It scores 37.1% on HLE against GPT-5 at 35.1% and is described as 2.5 times more efficient, and on τ²-Bench and FRAMES it surpasses GPT-5 using roughly 30% of the cost.
Which environments does ToolOrchestra need?
Three conda environments. toolorchestra runs python 3.12 with requirements.txt, flash-attn and flashinfer for training; retriever pins pytorch 2.4.0 with pyserini, faiss-gpu and tavily-python for search; vllm1 installs torch, transformers below 4.54.0 and vllm 0.9.2 for serving models.
Which API keys does ToolOrchestra require before it runs?
TAVILY_KEY for the search API, applied for at app.tavily.com, and WANDB_API for experiment tracking. HF_HOME, REPO_PATH, INDEX_DIR and CKPT_DIR are set as paths, with INDEX_DIR and CKPT_DIR pointing at two Hugging Face repositories you clone.
How is ToolOrchestra customized for a different setup?
By editing source files: the get_llm_response function in LLM_CALL.py for model calls, lines 455-458 of eval_hle.py and 506-509 of eval_frames.py for prompts, the tool_config variable at line 27 for the tool set, and tools.json plus the call_tool function for tools and models.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/nvlabs-toolorchestra)Star history chart for your README
[](https://hysenlabs.com/projects/nvlabs-toolorchestra)Was this useful?